Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsSome links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
There is no single best replacement for NVIDIA across every AI workload. AMD Instinct is the closest like-for-like data-center accelerator option when you need deployable hardware, large on-package memory, and the ROCm software stack. Google TPU is a different choice: a cloud-provisioned accelerator whose performance depends on XLA compilation, supported frameworks, and a workload that maps well to TPU execution. AWS Trainium and Inferentia belong in the evaluation, but current generations, specifications, availability, and software guidance are not verified in the available official material, so they should not be ranked against AMD or Google yet.
The practical decision is therefore workload-specific. Compare training, fine-tuning, online or batch inference, recommendation and embedding jobs, and HPC by software fit, memory and interconnect, measured latency or throughput, access, and total operating cost—not by a peak specification or a universal “best” label.

As an Amazon Associate I earn from qualifying purchases.
What are the best alternatives to NVIDIA GPUs for AI?
Choose AMD Instinct when you need accelerator hardware in your own servers or an enterprise system and can validate ROCm support for your models. Choose Google TPU when a Google Cloud deployment, XLA-compatible graph, and the provider’s supported frameworks fit your operating model. Treat AWS Trainium and Inferentia as options requiring a fresh primary-source check rather than as a proven third choice: the current evidence does not establish their generations, specifications, service availability, or workload guidance.
These products are not interchangeable categories. AMD sells data-center accelerator hardware and a software stack; Google exposes custom accelerators through Google Cloud; AWS’s named chips cannot be fairly assessed here without verified current documentation. A defensible choice comes from a representative benchmark on the exact model, precision, batch size, sequence length, serving topology, and framework you intend to run.
#1 Best Overall
| Option | What it is | Documented strengths | Important qualification |
|---|---|---|---|
| AMD Instinct | Data-center accelerator hardware with ROCm | MI350-series products are positioned for generative-AI training, inference, and HPC; MI355X is listed with 288 GB HBM3E and 8 TB/s peak theoretical bandwidth. | Those are AMD specifications, not an independent workload benchmark. Framework, kernel, server, and deployment support must be checked for the target model. |
| Google Cloud TPU | Custom accelerator accessed as a Google Cloud service | Google documents TPU v6e for transformer, text-to-image, and convolutional-network training, fine-tuning, and serving; TPU7x is recommended for large-scale training and high-bandwidth inference. | TPU programs must be compiled by XLA, and Google identifies limitations for branching-heavy, custom-operator, CPU-dependent, and FP64 workloads. |
| AWS Trainium and Inferentia | AWS accelerator families named in the comparison | Current official details were not verified in the available material. | Do not infer current chip generations, prices, software support, regions, or relative performance until current AWS documentation is checked. |
For context, this article uses current official product and documentation claims available on October 25, 2026. Vendor figures describe their own products and should not be read as a matched comparison with NVIDIA or another vendor.
How does AMD Instinct compare with NVIDIA for AI workloads?
AMD Instinct is the most direct hardware alternative in this set. AMD’s portfolio covers accelerator families for AI training, inference, HPC, and sovereign-AI deployments, with ROCm providing the associated software environment. The comparison becomes meaningful only after you establish that your framework, libraries, model kernels, and server configuration work on ROCm at the required performance and reliability.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →What are the current MI350-series memory and bandwidth figures?
AMD’s MI350 product material lists the MI355X with 288 GB of HBM3E memory and 8 TB/s of peak theoretical memory bandwidth. These figures can be important for large models, long context windows, large batches, and workloads that otherwise require sharding, but they are manufacturer specifications. They do not prove that MI355X will deliver higher tokens per second, lower latency, or better utilization than a competing accelerator on your model.
The MI350 family is described for generative-AI training, inference, and HPC. AMD also discusses enterprise deployment through PCIe cards and rack-scale accelerator platforms, so the buying decision can include complete server design, networking, cooling, and operations rather than an isolated chip.
How do MI300X and MI325X compare with MI355X?
| Accelerator | Memory | Peak theoretical bandwidth | Attribution and scope |
|---|---|---|---|
| MI355X | 288 GB HBM3E | 8 TB/s | AMD MI350 product page; manufacturer specification, not a matched workload result. |
| MI325X | 256 GB HBM3E | 6 TB/s | AMD MI300 product page; manufacturer specification, not a matched workload result. |
| MI300X | 192 GB HBM | 5.3 TB/s | AMD MI300 product page; manufacturer specification, not a matched workload result. |
The generations are not directly comparable by memory alone. Real capacity depends on model weights, optimizer states, activations, precision, tensor and pipeline parallelism, runtime overhead, and the number of devices. Bandwidth matters only in relation to the workload’s arithmetic intensity and communication pattern.
What does ROCm change in an AMD migration?
ROCm is an open software stack, but “open” does not mean every CUDA-oriented project runs without engineering work. Audit the complete path: framework version, distributed-training library, attention and convolution kernels, quantization implementation, communication layer, profiler, container image, and any custom C++ or GPU code. A model may load successfully while a missing optimized kernel causes a large throughput loss or forces an unsupported fallback.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →- Framework: confirm the exact PyTorch or other framework release and its ROCm support status.
- Operators: inventory custom operations, fused attention, quantization, sparse kernels, and preprocessing code that may run outside the main framework.
- Distributed execution: test collective communication and failure recovery on the intended PCIe or rack-scale topology.
- Production tooling: validate containers, monitoring, profiling, checkpoint restart, and orchestration on the actual server image.
- Capacity planning: model memory overhead and inter-device traffic instead of treating HBM capacity as usable model size.
When is AMD Instinct a sensible choice?
AMD is a sensible candidate when you want owned or hosted accelerator servers, your target model has a tested ROCm path, and memory capacity or system integration is more important than assuming compatibility with a CUDA-first toolchain. It is especially worth a pilot for organizations that can control the server software stack and measure the complete training or serving system.
It is a weaker choice when the project depends on unported custom operators, undocumented vendor-specific kernels, or a rapidly changing model stack that has only been validated on another platform. In those cases, migration labor and debugging time can outweigh a favorable hardware specification.
Rank #2

- Hpe AMD WX4100 Graphics module
Can AMD GPUs replace NVIDIA GPUs for AI training and inference?
They can replace NVIDIA in particular deployments, but not by default. Replacement is demonstrated by a workload test that meets your quality, throughput, latency, reliability, and cost targets with the production software stack. A larger HBM number or a theoretical bandwidth advantage is only a reason to test, not the result of the test.
What should an AMD replacement benchmark measure?
- Freeze the workload: record model revision, tokenizer, sequence length, input distribution, precision, batch or concurrency, decoding settings, and evaluation set.
- Match the system: use comparable host CPUs, storage, networking, device count, power limits, and software optimization levels.
- Measure useful output: report training samples or tokens per second, time to a target loss, inference latency percentiles, throughput at a stated concurrency, and quality metrics.
- Capture utilization: log accelerator utilization, memory use, communication time, data-loader stalls, and host-side overhead.
- Repeat under failure conditions: test checkpointing, node loss, restart time, long-running stability, and behavior during capacity or thermal constraints.
- Price the whole service: include server amortization or cloud rental, power, cooling, networking, storage, engineering time, and unused capacity.
Use the same acceptance thresholds for both platforms. If one system reaches the target quality with fewer devices or less operational effort, that is more informative than a peak specification taken from a product page.
What are Google Cloud TPU v6e and TPU7x?
Google TPU is a cloud deployment choice rather than a card you install in a general-purpose server. Google documents TPU v6e, also called Trillium, for transformer, text-to-image, and convolutional-neural-network training, fine-tuning, and serving. Its current guidance also identifies TPU7x, known as Ironwood, and TPU v5p as supported Compute Engine generations.
Which TPU generation fits which workload?
Google’s workload guidance recommends TPU v6e for cost-efficient fine-tuning and serving and TPU7x for large-scale training and high-bandwidth inference. Those recommendations are workload guidance, not a universal speed or price ranking. Model architecture, parallelism, sequence length, input pipeline, and the chosen serving framework still determine the result.
| Workload or requirement | Documented TPU direction | What to verify before committing |
|---|---|---|
| Fine-tuning with an emphasis on cost efficiency | Google points to TPU v6e. | Framework support, compilation time, batch shape stability, quota, and end-to-end cost. |
| Serving supported models | Google documents TPU v6e and later for inference. | Latency at production concurrency, model loading, autoscaling, and serving backend support. |
| Large-scale training | Google points to TPU7x. | Topology, distributed checkpointing, input pipeline, and reservation or capacity availability. |
| High-bandwidth inference | Google points to TPU7x. | Actual tokens per second, tail latency, and the cost of keeping the allocation warm. |
Why is XLA compilation central to TPU use?
Google’s official introduction states: Code that runs on TPUs must be compiled by the accelerated linear algebra (XLA) compiler.
XLA compiles the graph’s linear algebra, loss, and gradient components into TPU machine code. In practice, this means compilation behavior, graph shape, supported operations, and recompilation triggers are part of application design rather than an afterthought.
A workload with stable tensor shapes and operations that map cleanly to XLA can be a strong TPU candidate. A workload that changes control flow frequently, calls custom CPU-running operators, or relies on FP64 arithmetic may require substantial changes or may not be a good fit. Google explicitly identifies frequent logical branching, custom operators that run on the CPU, and FP64-dependent workloads as suitability concerns.
Which frameworks and serving paths are documented?
Google’s TPU v6e training documentation discusses JAX and PyTorch/XLA. Its inference documentation describes vLLM and SGLang options with JAX or PyTorch backends for TPU v5e and later. Support depends on the exact TPU generation, model, backend version, and topology, so confirm the combination in current documentation before promising a production launch.
How do you provision a TPU now?
Google’s current guidance recommends using Compute Engine or Google Kubernetes Engine (GKE) for TPU resource management instead of the legacy Cloud TPU API. The practical path is to choose a supported generation, verify regional capacity and quota, create the Compute Engine or GKE resources, install the documented framework and backend versions, compile a representative model, and then measure serving or training performance.
Rank #3

- Supported Technologies: AMD Software: Adrenalin Edition, AMD FidelityFX Super Resolution, AMD Link, AMD Noise Suppression, AMD Radeon Super Resolution, AMD Smart Access Memory, VSR(4K), AMD Privacy View, AMD Radeon Boost, AMD Radeon Anti-Lag, AMD Radeon Image Sharpening, AMD Enhanced Sync Technology, AMD FreeSync Technology, AMD Radeon Chill, TrueAudio Next, The Vulkan API, AMD Mantle API
- Core and Clocks: Boost Clock up to 2310 MHz, Memory Size 16GB, Memory Type GDDR6, Memory Bus 256-bit, Memory Speed up to 18 Gbps
- Supported Rendering Format: HDMI 4K Support, 4K H264 Decode, 4K H264 Encode, H265/HEVC Decode, H265/HEVC Encode, AV1 Decode
- Minimum PSU Recommendation: 850W
Cloud access introduces constraints that do not appear in a chip specification: project permissions, quota approval, regional inventory, reservation strategy, networking, persistent storage, image maintenance, and teardown of idle resources. A TPU design that is technically fast but frequently unavailable or difficult to schedule may be unsuitable for a latency-sensitive service.
Can a Google TPU replace NVIDIA for AI workloads?
A TPU can replace NVIDIA for a workload that compiles cleanly with XLA, uses supported JAX or PyTorch/XLA paths, and meets production targets on Google Cloud. It is less suitable when the application depends on frequent branching, CPU-side custom operators, FP64 arithmetic, or a CUDA-specific extension that has no supported equivalent.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchEvaluate TPU as a platform migration, not merely a hardware swap. Port the training or serving graph, reproduce model quality, account for compilation and warm-up, and test the cloud operations around quota and scaling. A successful notebook run is not evidence of production readiness.
What should a TPU pilot include?
- Select a fixed model slice: use the real architecture, representative sequence or image sizes, and production preprocessing.
- Compile early: identify unsupported operations, dynamic-shape behavior, recompilation, and compile-time impact before tuning throughput.
- Validate numerical behavior: compare loss curves, evaluation quality, convergence, and generated output against the current reference.
- Test serving modes: measure cold start, warm latency, tail latency, batching, concurrency, and model update time with the intended vLLM, SGLang, JAX, or PyTorch backend.
- Test cloud operations: request quota, confirm regional capacity, exercise autoscaling or node replacement, and calculate idle-resource exposure.
What is known about AWS Trainium and Inferentia?
The current material available for this comparison does not adequately verify AWS Trainium or Inferentia generations, specifications, Neuron software support, service availability, or workload recommendations. That is an evidence limitation, not a claim that the products are unavailable or unsuitable.
Because those details are unverified here, a responsible comparison cannot rank AWS against AMD Instinct or Google TPU, quote current memory or bandwidth, promise framework compatibility, or state a price advantage. Before selecting either AWS family, obtain current AWS primary documentation for the exact chip generation and service, then run the same workload test used for the other candidates.
What should an AWS due-diligence check cover?
- Exact accelerator generation and the AWS service or instance type that exposes it.
- Supported framework, compiler, runtime, model libraries, custom-operator path, and quantization support.
- Device memory, host memory, interconnect, scaling limits, and regional availability.
- Training and inference guidance for the specific model class, precision, and serving framework.
- Quota process, reservation or on-demand behavior, storage and networking charges, and operational tooling.
- Migration effort from the current implementation, including debugging and observability.
Do not substitute an old product page, a third-party benchmark, or a generic cloud estimate for current AWS documentation. Accelerator generations and service names change quickly enough that stale specifications can produce an invalid architecture decision.
How should you compare AMD, Google TPU, AWS, and NVIDIA alternatives?
Use a workload scorecard with the same definitions for every platform. The six dimensions below prevent a single attractive number from deciding the purchase.
| Dimension | Questions to answer | Evidence to collect |
|---|---|---|
| Workload fit | Is the target training, fine-tuning, online inference, batch inference, recommendation, embedding, or HPC? | Representative model runs and quality results at production shapes. |
| Software fit | Do the framework, compiler, kernels, custom operators, and serving tools support the platform? | Compatibility matrix, compile logs, fallback counts, and engineering hours. |
| Memory and scaling | Can the model and runtime fit, and how does performance change across devices or hosts? | Usable memory, communication time, topology tests, and scale-out efficiency. |
| Measured outcome | Does the system meet throughput, latency, utilization, convergence, and quality targets? | Repeated benchmark runs with stated precision, batch, concurrency, and model version. |
| Access | Can you obtain capacity where and when the service needs it? | Quota, region, reservation, lead time, failure recovery, and replacement options. |
| Economics and operations | What is the total cost to deliver one training run or one unit of inference? | Compute, power, cooling, networking, storage, software, labor, and idle-capacity costs. |
No matched independent benchmark covering AMD, Google, AWS, and NVIDIA is established here, and no comparable total-cost figures are available. Treat any cross-vendor ranking that ignores those gaps as provisional until you reproduce it on your own workload.
Rank #4
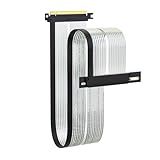
- FULL PCIE 5.0 X16 BANDWIDTH: Delivers up to 64GB/s in a CPU-direct PCIe 5.0 x16 slot – double a PCIe 4.0 x16 link – and negotiates down cleanly to PCIe 4.0 and 3.0 slots and GPUs.
- BUILT FOR PCIE 5.0 GPUS: Works with RTX 5090/5080/5070 Ti/5070/5060 Ti incl. Super, RTX PRO Blackwell, Radeon RX 9070 XT/9070/9060 XT/9060, AI Pro R9700, Arc Pro B60/B50 and Instinct MI300X/MI350.
- RIGHT-ANGLE CARD-SIDE CONNECTOR: Turns 90 degrees so the cable hugs the card and exits flush – the natural pick for vertical and side GPU mounts, multi-GPU spacing and routing tight against the chassis wall.
- 600MM REACH, LARGE TOWERS: Sized for large towers and chassis with distant GPU mounting positions; beyond one meter, cascade two cables (maximum two; three or more not supported).
- SI TESTED, SHIPS PROTECTED: Passed signal integrity testing (reports on request); packed in anti-static bags. Never touch the gold fingers – skin oils degrade signal quality. Seat both ends fully before power-on.
Which alternative fits each AI workload?
The matrix below is a starting point for testing, not a performance ranking.
| Workload | First platform to investigate | Why | Primary risk to validate |
|---|---|---|---|
| On-premises or hosted training | AMD Instinct | It is deployable accelerator hardware with a ROCm stack and a portfolio aimed at training and HPC. | Kernel and distributed-training compatibility, plus complete server economics. |
| Fine-tuning with stable, supported graphs | Google TPU v6e | Google specifically positions v6e for cost-efficient fine-tuning. | XLA compilation, shape stability, quota, and quality parity. |
| Large-scale training | Google TPU7x or AMD Instinct pilot | Google points to TPU7x for large-scale training; AMD offers rack-scale accelerator systems. | Scale-out efficiency, capacity access, and distributed checkpointing. |
| Online inference | AMD Instinct or Google TPU v6e | Both have documented inference roles, but they represent hardware deployment versus cloud provisioning. | Tail latency, batching, model loading, and serving backend support. |
| Batch inference and embeddings | Run a cost-per-output pilot on both candidates | Batch shape, memory pressure, and utilization can dominate theoretical specifications. | Actual throughput at the required concurrency and total cloud or system cost. |
| Branch-heavy or FP64-dependent HPC | Do not assume TPU suitability | Google identifies frequent branching, CPU-side custom operators, and FP64 workloads as TPU limitations. | Algorithm mapping and numerical requirements on the selected accelerator. |
What are the biggest migration pitfalls?
Most failed accelerator evaluations are integration failures rather than arithmetic failures. Plan for the following issues before ordering hardware or requesting a large cloud quota.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
- Confusing peak bandwidth with application bandwidth: a memory-bound kernel, communication bottleneck, or input pipeline may prevent the model from approaching the published number.
- Testing only a toy model: small examples can hide compilation, memory fragmentation, synchronization, and long-context behavior.
- Ignoring quality drift: a faster inference path is not acceptable if quantization, precision, or kernel differences change model quality beyond your threshold.
- Counting only accelerator rental: include host nodes, persistent storage, network traffic, orchestration, monitoring, engineering, and idle time.
- Assuming framework compatibility equals optimization: a model may execute while using slow fallbacks or missing fused kernels.
- Skipping capacity tests: cloud quota and regional inventory can determine whether a design is operable at peak demand.
- Porting without rollback: keep the current production path, checkpoints, model artifacts, and traffic-routing plan until the alternative passes reliability tests.
What is the practical decision process?
- Define the target: write down model quality, throughput, latency percentiles, training deadline, availability objective, and cost ceiling.
- Classify the workload: separate training, fine-tuning, online inference, batch inference, recommendation or embedding, and HPC rather than using one blended benchmark.
- Shortlist by deployment model: compare AMD hardware with Google Cloud TPU as distinct operating choices; add AWS only after current AWS facts are verified.
- Audit software: list framework versions, compilers, kernels, operators, backends, containers, and monitoring requirements.
- Run a representative pilot: use production-like data shapes, precision, concurrency, and distributed topology.
- Measure end to end: include compilation, warm-up, data loading, communication, checkpointing, serving, and failure recovery.
- Calculate total cost and access risk: price the complete system or cloud service and document quota, region, lead time, and operational staffing.
- Decide with a rollback: select the platform that meets the acceptance criteria with an operationally credible fallback, not merely the platform with the largest headline specification.
What should you conclude before choosing?
AMD Instinct is the strongest directly documented hardware alternative in this comparison, with a broad AI and HPC positioning and large published HBM figures. Google TPU is compelling when your workload fits XLA and you want a managed cloud accelerator path; Google’s own guidance differentiates v6e and TPU7x by workload rather than naming one universal winner. AWS Trainium and Inferentia require current primary-source verification before they can be compared responsibly. For every option, your model’s measured throughput, latency, quality, availability, and total cost are more decisive than peak vendor specifications.
Frequently Asked Questions
Do TPUs run unmodified CUDA programs?
No. TPU programs follow Google’s TPU software path and must be compiled by XLA, so CUDA-specific kernels and extensions generally require an equivalent supported implementation or a port. Confirm every custom operator and serving dependency during the pilot.
Does 288 GB of HBM mean an MI355X can hold any 288 GB model?
No. Weights are only one part of the footprint. Runtime buffers, activations, optimizer states, fragmentation, parallelism metadata, and communication space reduce usable capacity, so calculate memory with the exact precision and workload configuration.
Can I buy a Google TPU as an ordinary workstation card?
The documented TPU path is Google Cloud provisioning through services such as Compute Engine or GKE, not a general retail workstation purchase. Availability, quota, region, and service configuration are part of the deployment decision.
Recommended Free Tools
How often should accelerator compatibility be rechecked?
Recheck immediately before committing a production design and again when upgrading a framework or model. Generations, supported backends, cloud services, and regional capacity can change, and a previously working combination may require a new validation run.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

