What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Neither local nor cloud AI wins on every measure. A local LLM runs inference on hardware you control, which can keep prompts on that machine and work without a network connection, but you assume responsibility for security, updates, power and capacity. Cloud AI sends requests to a provider’s infrastructure, where larger models and elastic capacity may deliver better quality or concurrency, while introducing network dependence, provider terms and usage charges.
The practical choice depends on four things: the workload and quality it needs, the sensitivity and location rules for its data, the device or budget available, and how steadily the system will be used. The comparison below shows how to evaluate those factors, when a hybrid route makes sense, and how to avoid treating “local” as an automatic guarantee of privacy, low cost or speed.
As an Amazon Associate I earn from qualifying purchases.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Clear out junk files and repair common Windows errorsFree Scan →What is the difference between local and cloud AI?
Local inference executes the model on an endpoint, server or other infrastructure that you or your organization control. A prompt can stay on that hardware, but the operator must secure the device, restrict access, protect logs and backups, install updates and keep the runtime functioning.
Cloud inference sends prompts, files or other inputs to a provider-operated service. The provider runs the model and underlying infrastructure; you remain responsible for choosing an appropriate service, reviewing its data-handling terms, checking the processing region and applying the rules that govern your data.
#1 Best Overall

- Boosts System Performance: 32GB DDR5 RAM laptop memory kit (2x16GB) that operates at 5600MHz, 5200MHz, or 4800MHz to improve multitasking and system responsiveness for smoother performance
- Accelerated gaming performance: Every millisecond gained in fast-paced gameplay counts—power through heavy workloads and benefit from versatile downclocking and higher frame rates
- Optimized DDR5 compatibility: Best for 12th Gen Intel Core and AMD Ryzen 7000 Series processors — Intel XMP 3.0 and AMD EXPO also supported on the same RAM module
- Trusted Micron Quality: Backed by 42 years of memory expertise, this DDR5 RAM is rigorously tested at both component and module levels, ensuring top performance and reliability
- ECC Type = Non-ECC, Form Factor = SODIMM, Pin Count = 262-Pin, PC Speed = PC5-44800, Voltage = 1.1V, Rank And Configuration = 1Rx8
Hybrid inference uses both routes. A policy can keep short or sensitive jobs on a local model and send complex work to a cloud endpoint when local capacity or quality is insufficient, provided the user and organization permit that transfer and can see when it occurs.
“Local,” “on-premises,” private cloud and public cloud are not interchangeable labels. This comparison concerns local or on-device execution versus provider-hosted cloud AI; a private cloud may still be remote from the user, and an on-premises deployment still needs disciplined security.
| Question | Local inference | Cloud inference |
|---|---|---|
| Where does a prompt go? | It can remain on controlled hardware; access, logs, backups and malware protection are your responsibility. | It is processed on provider infrastructure under the provider’s service and data terms. |
| Who supplies compute? | You buy, rent or operate the CPU, GPU, NPU, memory and storage. | The provider supplies shared or dedicated capacity, subject to limits and availability. |
| What happens when demand rises? | Throughput is bounded by the installed device or servers; scaling generally means adding hardware. | Capacity can be expanded by the service, although price, quotas and congestion still apply. |
| Is a network required? | Not for inference after the runtime and model are available, if the software supports offline operation. | Yes, for access to the endpoint and for sending and receiving each request. |
| Who operates the stack? | Your team maintains the runtime, model files, hardware, accounts and security updates. | The provider maintains core infrastructure; you maintain integrations, credentials and data governance. |
Is a local LLM more private?
It can reduce data exposure, but “local” is not a privacy guarantee. Keeping inference on a controlled machine removes the provider from that particular prompt path. The same machine can still leak data through malware, an exposed local API, excessive user permissions, diagnostic logs, cloud-synced folders, backups or an untrusted model download.
Follow the entire local data path
- Input: identify whether prompts, attached files, clipboard contents or application context are copied into the model.
- Runtime: check which process listens for requests, which users can reach it and whether it binds only to the local device or to a wider network.
- Storage: locate chat histories, prompt logs, model caches, crash reports and temporary files; encrypt storage and limit retention.
- Backups and synchronization: verify that sensitive conversations are not automatically copied to another computer or online backup.
- Updates: obtain runtimes and model files from trustworthy sources, validate permissions and keep the operating system and drivers patched.
- People: use separate accounts, least-privilege access and clear rules for shared workstations.
Microsoft’s guidance assigns these controls to the user or operator of a local deployment. A local model can therefore improve data residency while increasing the amount of security work your team must perform.
What Microsoft says about Foundry Local
Microsoft’s Windows AI FAQ gives a concrete, product-specific example: after setup, Foundry Local runs inference on the device, so inference input and output do not leave that machine. The same FAQ notes that the initial model download and optional catalog-metadata refreshes use network traffic. That behavior should not be generalized to every local-model application; inspect the software you select.
What changes with cloud AI?
A cloud request leaves your device and is handled under the provider’s terms. Before sending regulated, confidential or proprietary material, confirm the provider’s retention, logging, training-use, deletion, access-control and regional-processing statements, plus any contractual commitments your organization requires. The fact that a service is popular does not answer those questions, and the fact that it is cloud-hosted does not by itself prove that it is unsafe.
Privacy decision checklist
- Classify the data: public, internal, confidential, personal or regulated.
- Record the permitted processing regions and retention period.
- Decide whether a provider may receive the raw prompt, a redacted version or only derived features.
- For local use, secure the host, local endpoint, logs, backups and model-download channel.
- For cloud use, review the provider’s current terms and configure the narrowest available data-sharing and retention settings.
- Tell users when a hybrid workflow can send content off-device and obtain the required consent.
Is running an LLM locally cheaper?
Only when the workload uses the hardware enough to justify its full cost. Local inference avoids a per-request service bill, but it requires capable hardware, electricity, cooling, storage, maintenance and staff time. Cloud billing varies with requests, tokens, model choice and other service dimensions, so a light or irregular workload may cost less in the cloud while a steady, predictable workload can favor owned infrastructure.
Rank #2
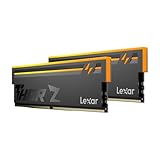
- Unleash Next-Gen Dominance: Experience Lexar DDR5 RAM performance with the Lexar THOR Z Series RGB DDR5 RAM 32GB Kit (2x16GB). Clocking at a blistering 6000MHz with low CL38 latency, this DDR5 desktop memory delivers up to 6000 MT/s for a full-throttle advantage. Whether you're building a high-end gaming rig or a professional workstation, this Lexar 32GB RAM kit ensures your system keeps pace with next-gen titles
- Sleek & Robust Thermal Design: Engineered for both aesthetics and endurance, this Lexar DDR5 RAM 6000MHz features an all-new streamlined design. The solid, sandblasted aluminum heatsink fuses a minimalist, razor-sharp aesthetic with uncompromising thermal control. This Lexar THOR Z Series armor ensures your DDR5 memory stays cool under pressure, delivering sustained peak performance during intense gaming sessions
- Game in Style with Brighter RGB Lighting: Elevate your build's aesthetics with the enhanced customizable RGB lighting on this Lexar RGB DDR5 RAM. Brighter and more vibrant than previous generations, the Lexar THOR Z Series RGB DDR5 RAM allows you to synchronize lighting effects with your components, creating a truly immersive gaming atmosphere that stands out from the crowd
- On-die ECC & PMIC for Rock-Solid Stability: Go beyond speed with reliability. This Lexar DDR5 RAM kit integrates On-die Error Correction Code (ECC) to automatically correct data errors, vastly improving stability and reliability for your critical tasks. The onboard Power Management Integrated Circuit (PMIC) ensures efficient power delivery, boosting the overall power efficiency of your DDR5 desktop memory for a longer-lasting, more stable system
- Seamless Compatibility with Intel & AMD: Worry-free upgrade guaranteed. The Lexar THOR Z Series DDR5 RAM is built for broad compatibility with the latest platforms. It fully supports Intel XMP 3.0 and AMD EXPO one-click overclocking, making it effortless to achieve the rated speeds. Trust Lexar DDR5 RAM to deliver seamless performance with mainstream DDR5 motherboards
| Cost element | Local | Cloud |
|---|---|---|
| Initial investment | Computer or server, memory, accelerator, storage and compatible software. | Usually little or no dedicated hardware purchase; configuration and integration still take time. |
| Variable operating cost | Power, cooling, replacement parts, storage growth and support. | Usage charges that rise or fall with request volume and selected capacity. |
| Capacity changes | Buying or leasing additional hardware; deployment and testing are your tasks. | Changing service tier or quota, subject to provider pricing and availability. |
| Lifecycle | Plan for refreshes, decommissioning and secure disposal. Lenovo Press uses a three-to-five-year on-premises refresh cycle as a planning assumption in its 2025 paper. | Provider refreshes core infrastructure; you remain exposed to price, product and quota changes. |
| Often overlooked | Administration, monitoring, failed components, model storage, security work and downtime. | Data-transfer charges where applicable, integration work, vendor dependency and the cost of idle reserved capacity. |
How to make a fair cost comparison
- Define the workload: estimate requests per day or month, average input and output size, peak concurrency, context length and the model quality required.
- Measure utilization: note how many hours the local machine will be busy instead of spreading its purchase price across an unrealistic 100% duty cycle.
- Annualize ownership: divide hardware and installation costs over the planned life, then add power, cooling, storage, maintenance, monitoring and operator time.
- Price the same workload in the cloud: use the provider’s current rates, model, region, quotas and expected volume rather than a generic headline price.
- Include failure and growth: budget for a spare, capacity peaks, model upgrades and the cost of migrating if the provider or hardware no longer fits.
Lenovo Press’s On-Premise vs Cloud: Generative AI Total Cost of Ownership (2025 Edition), published May 23, 2025, concludes that cloud can suit short-term or bursty workloads while on-premises infrastructure can be more cost-efficient at consistent utilization. Its analysis focuses on core infrastructure and excludes networking, facility overhead and routine IT operations, so it is not a universal break-even study for an individual, small office or every model. The page indicates a 2026 edition, but the 2025 figures should not be presented as current savings guarantees.
Is local AI faster than cloud AI?
It depends on the model, hardware, request and network. Local inference removes the round trip to a service, which can make short requests feel responsive on a capable device. The same request may be slower if the model is too large for available memory, if the runtime falls back to a CPU, if a long context is being processed or if several users share the machine. Cloud services add network variability but may run a larger or better-optimized model on powerful accelerators.
| Performance factor | Local effect | Cloud effect |
|---|---|---|
| Transport latency | No network trip for inference when the application and model are on the same device. | Upload, queueing and response travel add variability. |
| Model capability | Limited by what the device can load and what the chosen runtime supports. | Provider infrastructure may expose larger models, longer contexts or more features. |
| Concurrency | Multiple users compete for local memory and accelerator time unless you add hardware. | Service capacity can handle more simultaneous requests, subject to quotas and throttling. |
| Offline operation | Possible after installation when the application supports it. | Unavailable during a connection outage or when the endpoint cannot be reached. |
Google’s Android Studio documentation warns that local models in that context may have lower accuracy, higher latency and fewer features than cloud Gemini models. That is guidance for Android Studio, not a universal benchmark. Microsoft likewise describes local speed as device-dependent and cloud speed as connection- and service-dependent; no general percentage advantage or universal response-time winner is established.
Free tools Windows power users keep installed
One-click scans. No signup required.
Match the route to the task
- Short, constrained transformations: a small local model may be adequate when the format and vocabulary are narrow.
- Offline or policy-constrained work: local execution avoids sending content to an endpoint, provided the host is secured.
- Complex reasoning or long context: cloud models may be preferable when the local device cannot load a sufficiently capable model.
- Current information: a cloud workflow may be easier when the service includes retrieval or other connected features; a disconnected local model cannot know events after its training data without an approved data source.
- High concurrency: compare queueing and reliability under the actual number of users, not a single-user demonstration.
What hardware does a local LLM need?
There is no single minimum specification. Model size, runtime, quantization, context length, concurrency and operating system all matter. Microsoft lists the CPU, GPU, NPU, memory and storage as constraints. Check the selected model’s current documentation rather than treating a specification for one model as a rule for all local AI.
| Example in Google’s Android Studio guidance | Total RAM | Storage for the model | Scope |
|---|---|---|---|
| Gemma E4B | 12 GB | 4 GB | Requirement listed for that Android Studio local-model setup. |
| Gemma 26B MoE | 24 GB | 17 GB | Requirement listed for that setup; not a universal requirement for every deployment. |
Those figures, published in Google’s Android Developers documentation and accessed in 2026, illustrate how quickly capacity changes with model choice. Leave additional headroom for the operating system, application, context, multiple models and temporary files. A machine that technically meets a model’s stated minimum can still provide an unsatisfactory experience under sustained load.
When a memory upgrade is relevant
If a compatible computer lacks the capacity required by the model you selected, adding memory may help. Treat a 32 GB DDR5 kit as only an example of a possible upgrade path: verify the motherboard or laptop’s memory type, maximum supported capacity, slot availability and warranty before buying. The model requirements do not establish that every local-LLM computer uses DDR5 or needs 32 GB.
Capacity checks before installation
- Confirm free storage for the model, runtime, updates and logs.
- Check total system RAM, not only graphics-memory marketing numbers.
- Identify whether the runtime can use your CPU, GPU or NPU and which drivers it requires.
- Estimate the context length and number of simultaneous users you expect.
- Verify that the operating system and chosen provider, such as a local runtime integrated with Android Studio, support the model format.
How do I choose between local, cloud and hybrid AI?
Use the following sequence before selecting a model or buying hardware. It prevents privacy, cost and performance assumptions from being made in isolation.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minutePC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Rank #3

- Requires overclocking/BIOS adjustments. Maximum speed and performance depends on system components, including motherboard and CPU.
- G.SKILL Flare X5 Series DDR5 U-DIMM Memory Kit, Model: F5-6000J3636F16GX2-FX5
- Non-ECC, DDR5 U-DIMM, 288-pin, for Desktop PC & Gaming
- Includes JEDEC default profile, and AMD EXPO & Intel XMP 3.0 memory overclock profile
- Do not mix memory kits. Memory kits are sold in matched kits that are designed to run together as a set. Mixing memory kits will result in stability issues or system failure.
- Describe the job and quality bar. Write down the input types, output format, acceptable error rate, context length, response-time target and number of users. Test whether a smaller local model can meet that bar before planning for a larger one.
- Classify the data. Determine whether prompts contain personal, regulated, confidential or proprietary information. Record which regions and processors are allowed to handle it.
- Check local readiness. Compare the chosen model’s RAM, storage, accelerator, context and runtime requirements with the actual device. Include headroom and offline-update procedures.
- Calculate total cost. Annualize hardware over its expected life and add utilization, energy, support and administration. Price an equivalent cloud workload for the same period and expected peaks.
- Decide what connectivity and scale matter. Offline sites, remote access, collaboration, burst capacity and service reliability can outweigh a small latency difference.
- Set a fallback policy. If local quality or availability is insufficient, define which tasks may use cloud AI, what redaction is required, who approves the transfer and how users are notified.
A practical decision matrix
| Your priority | Likely starting point | Question to validate |
|---|---|---|
| Data must stay on a controlled device | Local, or a hybrid route with strict local-first rules | Can the device deliver acceptable quality and can you secure its logs and backups? |
| Demand is unpredictable or seasonal | Cloud or hybrid | Do usage charges and quotas remain acceptable during peaks? |
| Work is steady and hardware is already available | Local may be economical | What is the measured utilization after power, maintenance and staffing? |
| Complex reasoning and long context are central | Cloud, or hybrid fallback | Is the required model too large or feature-rich for the local device? |
| Internet access is unreliable or prohibited | Local | Can you install, update and support the runtime without connectivity? |
| Many concurrent users need a consistent service | Cloud or dedicated local servers | What are the queueing, capacity and failover results under peak load? |
How does a hybrid local-and-cloud design work?
A hybrid design is not simply “use whichever is faster.” It is a routing policy with an explicit data boundary. Microsoft recommends checking local readiness, matching the route to task complexity and obtaining consent for model downloads or cloud fallback.
Define routing rules
- Route approved, short or offline tasks to a local model.
- Require a user or policy decision before sending sensitive content to a provider.
- Use cloud capacity for tasks that exceed local memory, context or quality limits.
- Display the active route in the interface so users know when data leaves the device.
- Log the route and decision without storing raw sensitive prompts unless retention is justified.
Plan failure behavior
When the cloud endpoint is unavailable, decide whether the application should queue the request, use a smaller local model, redact and retry, or return an error. When the local model is unavailable, do not silently upload content unless the user and policy permit that fallback. Test these branches with representative data before deployment.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How do I set up a local model safely?
The exact controls differ by operating system and runtime, but the deployment sequence is consistent. Google’s Android Studio documentation uses a locally installed model with an inference provider such as Ollama or LM Studio; the names and supported versions can change, so verify the current documentation for your chosen setup.
- Select the model and provider. Confirm the model’s license, supported format, RAM and storage requirements, context limits and whether it supports your CPU, GPU or NPU.
- Prepare the machine. Apply operating-system and driver updates, enable full-disk encryption where available, create a dedicated user or service account and reserve storage for model files and logs.
- Install the runtime from its official distribution. Review the installer’s permissions and disable network exposure you do not need.
- Download the model. Use the provider’s documented model source, record the version and verify checksums or signatures when offered. Remember that this initial download is network traffic even if later inference is offline.
- Connect the application. In Android Studio or another supported client, select the local inference provider and installed model according to its current setup instructions.
- Restrict access. Bind the local service to the minimum interface, require authentication when supported, and block unsolicited inbound connections at the host firewall.
- Test with non-sensitive prompts. Measure latency, output quality, memory use, error handling and behavior after a restart before permitting confidential data.
- Operate it. Patch the runtime, rotate credentials, monitor storage and resource use, review logs, back up only what policy allows and document how to remove the model securely.
What are the common failure modes?
The model will not load
Check free storage, total RAM, model format, runtime compatibility and driver support. A model can fail even when the headline RAM number appears sufficient because the operating system and context also consume memory. Try a smaller model or shorter context only after confirming that the resulting quality meets the job’s requirement.
Responses are too slow
Measure first-token latency and total generation time separately. Check whether the runtime is using the intended accelerator, whether another user is consuming memory, and whether the context is unnecessarily long. If the device remains inadequate, route that task to a permitted cloud model instead of promising that a software tweak will create more compute.
Output quality is inadequate
Compare the local model with a cloud model on a fixed, representative test set and the same instructions. A smaller local model may be suitable for classification or constrained formatting but not for complex reasoning. Improve the routing decision or select a model that fits the device rather than judging the entire local approach from one task.
Data appears in unexpected places
Inspect application histories, runtime logs, crash dumps, temporary directories, synchronization tools and backups. Remove unnecessary retention, tighten permissions and document who can access the machine. For a hybrid setup, trace outbound requests so a fallback cannot silently bypass policy.
Rank #4

- Faster than ever with 5600MHz frequency, new structural composition for better performance.
- Conserve energy with energy-efficient 1.1V working voltage.
- Supports on-die ECC for more stable systems.
- Upgraded capacity for powerful multitasking.
- Lifetime warranty. ※Refer to the latest version on the official website. In case of discrepancies, the official website prevails.
Offline mode stops working
Verify that the model and runtime are fully downloaded and that the application does not require a catalog refresh or license check at launch. Microsoft’s Foundry Local FAQ distinguishes offline inference from network activity used for initial downloads and optional catalog metadata, so check which behavior your software implements.
Recommended Free Tools
What should you measure in a pilot?
A short, controlled pilot is more useful than a generic speed or price claim. Use the same prompts, model task and acceptance criteria on the local and cloud routes.
- Quality: factual accuracy, formatting compliance, refusal behavior and human-review time.
- Latency: time to first token, time to complete and queueing at expected concurrency.
- Reliability: failure rate, recovery after restart and behavior during network loss.
- Privacy: destinations contacted, data retained, user permissions and backup exposure.
- Cost: hardware allocation, utilization, energy, administration and equivalent cloud usage charges.
- Operations: update effort, monitoring burden, incident response and model replacement procedure.
Keep the pilot’s scope visible. No universal benchmark establishes that local inference is always cheaper, faster or more accurate; the result belongs to your model, device, workload and policy.
Frequently Asked Questions
Can a local LLM work without an internet connection?
Often, yes, once the runtime and model files are installed and the application supports offline execution. Initial downloads, optional model-catalog refreshes or license checks may still require a connection, so verify those dependencies for the specific software rather than assuming every local tool is fully disconnected.
Does keeping prompts local make me compliant with privacy law?
No. Local processing can simplify data residency, but compliance also depends on access controls, retention, auditability, lawful purpose, backups and the people who can use the device. Document the complete data path and apply the requirements that govern your particular data and jurisdiction.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Can I let employees use a local model on a shared computer?
Only with separate accounts, least-privilege permissions and protected conversation history. Encrypt the disk, prevent the local service from accepting untrusted network connections, and decide whether chat logs and model files belong in backups before enabling shared use.
How often should a local model be updated?
Set an update schedule based on security advisories, runtime compatibility and the value of newer model versions. Test each update on non-sensitive workloads, record the version used in production and keep a rollback copy so an upgrade does not interrupt critical offline work.
What happens if a hybrid system sends data to the cloud unexpectedly?
Treat routing as a security control: display the active route, require explicit permission for fallback where policy demands it, and log the decision without retaining raw sensitive content unnecessarily. Test outages and capacity failures so the system fails closed or follows the documented redaction path instead of silently uploading prompts.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitches
