Some links on this page are affiliate links: if you buy through them we may earn a commission, at no extra cost to you.
Yes, you can use several kinds of AI without Wi-Fi or mobile data—but only after preparing them while you are connected. Download an on-device feature or local model, let it finish caching, then disable connectivity and test the exact job you need. Built-in phone features are usually simplest; local runtimes on Windows and other computers offer more model choice. Offline systems generally trade some cloud-level accuracy, speed, or features for availability and, in supported implementations, local processing.
The safest workflow is: choose the task, verify device eligibility, download the model or feature, reserve enough storage and memory, save any files it will need, and run a real airplane-mode test before travel, an outage, or field work.
As an Amazon Associate I earn from qualifying purchases.
What does it mean to use AI offline?
Offline AI performs inference on your device instead of sending each prompt to a remote service. The model weights, supporting files, and the app that runs them must already be present locally. A first-time download normally requires internet access; after that, only features implemented for local execution can continue without a connection.
Offline is not an all-or-nothing label for an app. A writing assistant may summarize a document locally while its web search, account sync, cloud history, or large-model option still needs a network. Treat every feature as a separate capability and test the exact workflow you plan to depend on.
#1 Best Overall

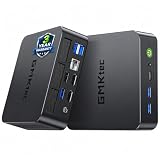
- EVOLUTION RYZEN AI MAX+ 395 MINI PC - GMKtec EVO-X2 is the next evolution in AI mini PC Ryzen Strix Halo series. Thanks to AMD Simultaneous Multithreading (SMT) the core-count is effectively doubled, to 32 threads. Ryzen AI Max+ 395 has 64 MB of L3 cache and can boost up to 5.1 GHz, depending on the workload. The Ryzen AI Max+ 395 is currently rated as the "most powerful x86 APU" on the market for AI computing.
- AI NPU with XDNA 2 ARCHITECTURE - Powered by 16 “Zen 5” CPU cores, 50+ peak AI TOPS XDNA 2 NPU and a truly massive integrated GPU driven by 40 AMD RDNA 3.5 CUs, the Ryzen AI MAX+ 395 is a transformative upgrade and delivers a significant performance boost over the competition. The Ryzen AI Max+ 395 excels in consumer AI workloads like the llama.cpp-powered application: LM Studio. Shaping up to be the must-have app for client LLM workloads, LM Studio allows users to locally run the latest language model without any technical knowledge required and unleash their creativity and productivity.
- AMD RADEON 8090S iGPU GAMING PC - The AMD Radeon RX 8060S offers all 40 CUs with up to 2.9 GHz graphics clock and uses the new RDNA 3.5 architecture. The powerful iGPU is positioned between an RTX 4060 and 4070 laptop GPU and therefore enables gaming in FHD at maximum details in most demanding games. The 8060S can also utilize the full 128GB pool, which is perfect for running LLMs such as Deepseek 70B Q8, which runs comfortably on this machine.
- EIGHT CHANNEL LPDDR5X - LPDDR5X is a new ground breaking memory small form factor installed on-board. With blazing speeds up to to 8000MT/s, it runs 1.5x faster than the DDR5 SODIMMs; 90% better performance over DDR5 SODIMMs in video conferencing and photo editing; 30% better performance in productivity apps; 12% better performance in digital content workloads.
- QUAD SCREEN 8K DISPLAY SUPPORT - EVO-X2 AI Mini PC support 4-screen 4K/8K output via HDMI 2.1 (8K@60Hz), DisplayPort 1.4 (4K@60Hz), and dual USB 4 40Gbps Transfer speed (supporting PD3.0/DP1.4/DATA). Ideal for gaming, video editing, and multitasking, it provides expansive and crisp multi-display support.
How can I prepare AI for use without an internet connection?
Preparation is the part people skip, and it is why an apparently offline-capable app fails at the airport or in a dead zone. Follow this sequence while you still have a reliable connection.
- Define the task. Decide whether you need summarization, rewriting, translation, image analysis, coding help, transcription, or another job. A small model may be adequate for summaries but not for complex code reasoning.
- Check platform and model eligibility. Confirm the operating-system version, supported hardware, language, memory, and storage requirements on the model or feature’s official page.
- Install the runtime or feature. Update the operating system and app first. Local runtimes, phone system components, and IDE integrations can have different installers and permissions.
- Download the model while online. Wait for the download to finish and verify that the model is marked available or cached. Microsoft explains that Foundry Local performs inference after a model has been downloaded and cached; its initial download needs internet access (Microsoft’s Foundry Local FAQ).
- Prepare local inputs. Copy documents, reference notes, project files, dictionaries, and any images or audio you will use onto the device. A local model cannot retrieve a file that remains on a cloud drive when that drive is unreachable.
- Disconnect deliberately. Turn on airplane mode, then disable Wi-Fi and Bluetooth if you want a stricter test. Open the app, load the downloaded model, and run a representative task rather than a trivial prompt.
- Record the result. Note startup time, response speed, battery drain, memory pressure, and which buttons are disabled. Keep this information with your travel or outage plan so you know the limits before you need the tool.
Which offline AI option fits my device?
The best choice depends on whether you value simplicity, model flexibility, or coding integration. Use the following as a starting point, then verify the exact feature on your hardware.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitches| Platform or workflow | What can work locally | Important requirements or limits |
|---|---|---|
| Windows computer | Windows local models, including Phi Silica on eligible Copilot+ PCs and more than 20 open-source models listed by Microsoft | Availability and performance vary by device; model and task requirements are not uniform (Microsoft’s Windows local-LLM guide) |
| Android phone or tablet | Supported Android AICore features using Gemini Nano, such as certain summaries and smart replies | Android 14 or newer is required for AICore, but manufacturer and device support differ (Google’s AICore support page) |
| Apple device | Eligible Apple Intelligence features using downloaded on-device models | Hardware, operating-system version, storage, language, and regional feature availability all matter (Apple’s eligibility and setup guidance) |
| Coding on a computer | Visual Studio Code’s BYOK local-model path through a local provider such as Ollama | Some service-dependent functions, including semantic search, inline suggestions, embeddings, and Copilot services, are unavailable offline (VS Code language-model documentation) |
| Android Studio experimentation | A local provider such as Ollama or LM Studio connected to a downloaded model | Google warns of lower accuracy, higher latency, and fewer features than cloud models (Android Studio’s local-model guide) |
How do I run local AI on a Windows computer?
Windows offers both built-in local experiences and separate runtimes. The practical pattern is the same: select a compatible model, download it once, then launch inference from the cached copy while offline.
Check whether your PC is a Copilot+ PC
Microsoft’s 2025 Copilot+ PC minimum specifications are 16 GB of RAM, a 256 GB SSD, Windows 11 version 24H2 or newer, and an NPU capable of at least 40 TOPS (Microsoft’s Copilot+ PC specifications). These figures describe the Copilot+ class, not a universal minimum for every local model. A conventional Windows 10 or Windows 11 machine may still run another local model if its CPU, GPU, memory, and storage meet that model’s requirements.
Use a cached model with Foundry Local
- While online, install the Foundry Local components and review the available model catalog.
- Download the model that matches your task and hardware. Keep the device powered during a large download.
- Confirm the model is listed as downloaded or cached, then run a short prompt before disconnecting.
- Turn off networking and start the local inference session. Microsoft notes that the runtime may try to refresh catalog data at startup, but its cached catalog supports offline use.
- When offline, select only the cached model. Cloud models, web-grounded answers, and account-backed features will not substitute for it.
Expect different startup times and response quality across models. Microsoft explicitly says local model availability and performance depend on the device, so a model that loads on one Windows PC may be impractical on another.
When should I use another Windows runtime?
Choose a separate runtime when you need a wider choice of open models, a local API for several applications, or control over quantization and context size. Install it, download the model, and test the application that will call it while offline; installing a runtime alone does not make a cloud-connected app local.
Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchPC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Can Android phones use AI without Wi-Fi?
Some can. Google says Android AICore is available on Android 14 and higher, with support varying by device and manufacturer. On supported phones and tablets, Gemini Nano runs locally for selected features such as text summarization and smart replies (Google’s Android AICore documentation).
How to verify Android support
- Install the latest system and Google component updates while connected.
- Look for the device’s AI or AICore settings and confirm that the feature is enabled. The menu name can differ by manufacturer.
- Complete any model download or setup prompt on Wi-Fi and power.
- Test the exact operation—such as summarizing a locally stored message or generating a smart reply—in airplane mode.
A phone can be Android 14 or newer and still lack a particular feature. Manufacturer customization, memory, language, and regional rollout determine what appears. If the feature disappears when you disable data, it is not an offline function on that device, regardless of the marketing name.
What can Apple Intelligence do offline?
Apple downloads on-device Apple Intelligence models after setup, and Apple recommends Wi-Fi and power so the download completes faster. Eligibility depends on the exact device family, operating-system release, available storage, language matching, and feature availability in your region. Check Apple’s current support requirements before assuming a feature will work offline (Apple Support: How to get Apple Intelligence).
Prepare and test an Apple device
- Update to the supported operating-system version and set a supported device language and Siri language combination.
- Enable Apple Intelligence in Settings and leave the device on Wi-Fi and power until the on-device models finish downloading.
- Check free storage; the models occupy local space and the requirement can change as Apple adds features.
- Use airplane mode to test the particular writing, notification, or image feature you need. Try both a new prompt and an existing local file.
Some Apple Intelligence actions may still use Apple’s private cloud processing or an external service when a task exceeds on-device capability. A disabled network can therefore change the result or remove an option. The support page’s device, software, language, and storage matrix is the authoritative eligibility check.
Recommended Free Tools
How do I use a local model for coding?
Visual Studio Code supports a bring-your-own-key (BYOK) path for local models, including a local provider such as Ollama. Once the provider and model are installed, the model can answer prompts without sending code to a remote service. This is useful on restricted networks or with proprietary repositories.
Offline coding setup
- Install the local provider and download a coding-capable model while connected.
- Start the provider’s local inference service and verify that VS Code can see the model.
- Open a repository that is stored on the device, select the local model in the chat or agent configuration, and run a code question while still online.
- Disconnect networking and repeat the same question, including a request that requires reading a local file.
- Keep a conventional editor, compiler, tests, and documentation snapshots available; the model cannot fetch a missing package or current API reference.
VS Code documents important limits for this offline route: semantic search, inline suggestions, and features that rely on embeddings or Copilot services are unavailable. Chat-style generation can work while those richer indexing and completion features do not, so plan your workflow around commands and capabilities that remain enabled (VS Code’s model documentation).
How much hardware and storage does offline AI need?
There is no single minimum specification. Smaller quantized models can run on ordinary laptops, while larger models need more RAM, faster graphics hardware, or a neural-processing unit. Storage covers both the model files and temporary working space for the context you provide.
| Example requirement | What it applies to | How to interpret it |
|---|---|---|
| 16 GB RAM, 256 GB SSD, Windows 11 24H2 or newer, NPU of at least 40 TOPS | Microsoft’s 2025 Copilot+ PC minimum specification | Eligibility for that PC class, not a universal requirement for local AI |
| 12 GB RAM and 4 GB storage | Gemma E4B example in Android Developers’ 2026 Android Studio guide | A requirement example for that named model and setup |
| 24 GB RAM and 17 GB storage | Gemma 26B MoE example in the same guide | A substantially larger model example, not a phone-wide standard |
The Android Developers figures are model-specific examples (Android Studio local-model requirements). Leave additional headroom for the operating system, the runtime, cached prompts, and your files. An external SSD can provide space when internal storage is tight, but it cannot add missing RAM, a required NPU, or unsupported operating-system features.
Free tools Windows power users keep installed
One-click scans. No signup required.
What are the trade-offs of offline AI?
Offline access improves availability and can reduce exposure of prompts to a network, but it is not a free replacement for a cloud model. Google’s Android Studio guidance warns that local models can be less accurate, slower, and limited to fewer features than cloud Gemini models (Google’s local-model guidance).
Rank #2
- AI MINI PC WORKSTATION - Powered by the Intel Core Ultra 5 226V (3.50GHz base, 4.50GHz boost) with a dedicated 97 total TOPS (47 NPU + 64 GPU), this mini PC outperforms the Core i5 14450HX, Ryzen 7 6800H in real-world AI tasks; the K17 AI local workstation enables real-time generative AI tasks without the cloud on Gemma-4-E4B & E2B—supporting text generation, code completion, summarization, intelligent chat, and data analysis directly on your edge device for enhanced privacy, zero latency, and offline capability.
- GAMING PC WITH INTEL ARC 130V GPU - Experience a quantum leap in integrated graphics with the Intel Arc 130V GPU (boosting up to 1.85GHz), which leaves the competition in the dust by delivering comparable or superior gaming and content creation performance while consuming up to 50% less power than leading rivals like the Radeon 890M—this groundbreaking efficiency means you get desktop-class discrete performance (rivaling the GTX 1650) in a silent, cool-running mini PC, with cutting-edge features like hardware ray tracing, XeSS AI upscaling, and full AV1 encoding support that competitors' integrated solutions simply can't match
- UPDATE DRIVERS - Intel Graphics Driver 32.0.101.8509 (WHQL Certified – Released 02/13/26) for Intel Arc 130V GPU delivers XeSS 3 Multi-Frame Generation (MFG) supporting up to 4× AI-based frame output; enhances gaming performance by 10% average FPS uplift and up to 25% improvement in 1% low (99th percentile) FPS for reduced stuttering across 9-game suite including Black Myth: Wukong (+13.8%), Fortnite S34 (+17.9%), DOTA 2 (+16.0%), PayDay 3 (+12.6%), *Counter-Strike 2* (+8.0%), and Cyberpunk 2077 (+6.1%); XeSS 3 MFG officially extended to Lunar Lake platform GPUs (Arc 130V and 140V) alongside Arc B/A Series discrete GPUs.
- WHY LPDDR5X IS BETTER THAN DDR5 - Equipped with 16GB of premium SK Hynix LPDDR5x memory running at an incredible 8533 MT/s, this mini PC delivers nearly 2x the bandwidth of standard SO-DIMM DDR5 (4800–5600 MT/s). The soldered, ultra-low-latency design reduces power draw and unlocks smoother multitasking, faster app loading, and significantly better iGPU gaming performance—especially on Intel Core Ultra integrated graphics—so you can game at higher settings and zip through creative workloads without stutter or slowdown.
- TRANSFORM YOUR WORKSPACE WITH TRIPLE 4K DISPLAY SUPPORT: Unleash unparalleled productivity by connecting three crystal-clear 4K monitors at 60Hz via DUAL HDMI 2.1 TMDS and USB4 port—effortlessly run stock tickers on one screen, complex spreadsheets on another, and video conferencing on the third, or dominate trading and financial modeling with real-time data sprawled across your entire field of view without any lag or stuttering.
- Quality: Smaller models may miss nuance, produce weaker code, or struggle with long documents.
- Latency: The device’s CPU, GPU, NPU, thermals, and power mode affect response time. Sustained generation can trigger thermal throttling.
- Context size: A local model may accept fewer pages or files than the cloud service you normally use.
- Freshness: Without a connection, it cannot check current news, prices, live weather, newly released software, or an online database.
- Feature coverage: Search grounding, synchronization, semantic indexing, embeddings, and account-based actions may be disabled.
- Battery and heat: Long prompts and large models can drain a phone or laptop quickly; carry power if the task is sustained.
For high-stakes medical, legal, financial, safety, or operational decisions, treat an offline model as an assistant and verify its output against trusted material stored locally or consult a qualified professional when connectivity returns.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Is offline AI private?
Privacy depends on the specific implementation, not merely on the words “local model.” Microsoft says Foundry Local inference inputs and outputs do not leave the machine. Google describes on-device processing for supported AICore features. Those statements should not be generalized to every app that contains an AI button.
Check whether telemetry, crash reports, account synchronization, update checks, or optional cloud fallback remain enabled. A local model can process your prompt on-device while the surrounding app still uploads diagnostics or syncs conversation history. For sensitive work, review the provider’s data controls, disable cloud fallback where the interface allows it, and observe network activity on a managed device.
What should I do when an offline model fails?
The model or feature is missing
Reconnect, finish the download, and verify free storage. Confirm that the model is actually cached rather than merely listed in a catalog. On phones, check device, language, and regional eligibility; on Windows, check the model’s hardware requirements.
The app keeps asking for internet
Identify the specific operation that triggered the request. It may be web search, account login, catalog refresh, embedding generation, license validation, or a cloud fallback rather than inference itself. Select the local provider or cached model explicitly and repeat the test with a local file.
Responses are too slow or inaccurate
Use a smaller model, shorten the prompt, reduce the number of attached files, or switch to a model designed for your task. Keep the device plugged in and cool, but do not assume a faster drive will solve a CPU-, GPU-, or memory-bound workload.
The output contains outdated information
Offline models have no live retrieval. Supply dated reference documents locally, ask the model to cite those files, and mark the answer as requiring verification when the underlying facts may have changed.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
A coding assistant cannot complete a task
Check whether it depends on semantic search, embeddings, inline suggestions, or a cloud service. VS Code lists those limitations for its local BYOK path. Use local file selection, terminal tools, tests, and a locally stored API reference instead of expecting cloud-indexed repository intelligence.
What is the safest offline-AI checklist before travel or an outage?
- Install updates and the local runtime while connected.
- Download every model you intend to use and confirm its cached status.
- Keep free storage for the model, temporary context, and output files.
- Save source documents, project folders, dictionaries, and reference material locally.
- Write down the model name, provider, launch steps, and fallback workflow.
- Test in airplane mode on the same device, language, account state, and files you will use later.
- Measure battery use and carry a charger or power bank for long sessions.
- Export important results to local files; do not rely on cloud history to recover them.
- For sensitive data, confirm whether cloud fallback and telemetry can be disabled.
- Keep a non-AI method for the task, such as a calculator, reference book, editor, or scripted tool.
Which offline AI approach should I choose?
Choose built-in phone features when your device is supported and your needs are narrow, such as short summaries or smart replies. Choose a local computer runtime when you need to select among models, work with larger files, or connect AI to a coding environment. Choose a Copilot+ PC only after confirming that its local features solve your task; buying hardware does not make every AI app offline.
Whatever the platform, make the decision from the airplane-mode test rather than the product label. The model that completes your real task, on your real files, at an acceptable speed and privacy level, is the useful offline option.
Frequently Asked Questions
Will offline AI work in airplane mode on a phone?
Only if the model and the specific feature have already been downloaded and are designed for on-device inference. Airplane mode is a useful test, but some phones still require an initial activation, language pack, or account check before the local feature becomes available.
Can an offline model access files on an external drive?
Usually yes, if the operating system and app can read the drive while disconnected and the files are in a supported format. Test permissions and keep the drive connected during the full workflow; removing it or letting the device sleep can interrupt context loading.
How do I update an offline model?
Reconnect periodically, check the runtime’s model-management screen, and download updates before you leave coverage. Keep the previous model until the replacement passes your offline test, because an update can change quality, storage use, or hardware requirements.
Can offline AI translate or transcribe without cloud services?
It can when the app includes downloadable language and speech models, but support is feature- and language-specific. Download the required language packs and test a representative recording offline; a text model alone does not provide speech recognition.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →
