Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Scan for outdated or missing drivers - takes under a minuteDriver Scan →A local model advertised with a 128K context window can accept a large input, but that number does not show how reliably it can find and use information at every position in that input. To test for “lost in the middle,” ask the same questions across different context lengths while moving the answer-bearing passage from the beginning through the middle to the end. Compare accuracy by position and report the gap between the best and worst results.
What a 128K context window does—and doesn’t—tell you
A context window is an input-capacity limit, not a promise of uniform retrieval or reasoning quality across the entire input. A model may accept a long prompt and still answer differently depending on where the relevant evidence appears. Nor does a larger context limit, by itself, establish that the model can use all of that context effectively.

As an Amazon Associate I earn from qualifying purchases.
This distinction was examined in Nelson F. Liu and coauthors’ peer-reviewed 2024 paper, “Lost in the Middle: How Language Models Use Long Contexts”. The authors tested multi-document question answering and synthetic key-value retrieval. They found that performance could change substantially when the relevant information moved within the input; the pattern was often stronger at the beginning and end than in the middle. The paper describes this as a “distinctive U-shaped performance curve.”
Recommended Free Tools
The finding is a reason to test a particular model and setup, not proof that every model has the same weakness or degree of positional sensitivity. The paper also reports that extending a model’s context does not necessarily improve its ability to use the information in it.
#1 Best Overall

- 【High-Performance APU】The MS-S1 MAX features an AMD Ryzen AI Max+ 395 APU, integrating a Zen 5 architecture CPU (up to 5.1GHz, 16C/32T, 64M L3 Cache), an RDNA 3.5 GPU, and an NPU (50 TOPS). The total system output is 126 TOPS. It provides powerful parallel computing capabilities for demanding AI workflows. It is ideal for running local LLMs, multimodal models, and computationally intensive tasks
- 【128GB UMA Memory】Equipped with up to 128GB of LPDDR5x-8000MT/s unified memory, it enables the CPU and GPU to access a shared, high-bandwidth memory pool with extremely low latency. Ideal for large-scale AI inference, 3D workloads, and complex timelines in video editing. It eliminates traditional VRAM bottlenecks, ensuring smoother data transfer during high-intensity computations. The UMA design maximizes performance stability under high loads
- 【Flexible Expansion】The MS-S1 MAX features USB4 V2 (up to 80Gbps), dual 10GbE LAN, HDMI 2.1 (up to 8K60), a full-length PCIe x16 expansion slot, and dual M.2 slots supporting up to 16TB RAID 0/1. Wi-Fi 7 provides stronger signal coverage and a more stable wireless experience. The slide-out design facilitates upgrades and maintenance. It easily adapts to personal, studio, or rack-mount enterprise environments
- 【High-Efficiency Cooling System】Utilizing an aerospace-grade aluminum alloy chassis, copper base plate, six heat pipes, dual turbine fans, and advanced PCM thermal conductive material, it maintains stable cooling performance even under continuous load. This system supports 130W continuous power and 160W peak power operation, with a built-in 320W power supply. It boasts multiple global certifications including CCC, FCC, UL, CE, and UKCA, ensuring stable and reliable operation in various environments
- 【Cluster Design】Two MS-S1 MAX units can be configured as a dual-unit cluster to run a large 235B Q4 model locally, achieving an output speed of 10.87 tok/s. Supporting 2U rack deployment, multiple MS-S1 MAX units can be cascaded into a distributed cluster to create a high-efficiency AI computing center. A cluster of four MS-S1 MAX units successfully ran a DeepSeek-R1 671B Q4 large model. A reserved cluster power-on interface allows for unified start-up and shutdown
How to test whether your local LLM loses information in the middle
Run matched tests: keep the question and surrounding material fixed, and change only the answer passage’s position. Repeat at several input lengths. This helps separate a position effect from the simple difficulty of processing more text.
- Choose a task and define the answer key. For a simple diagnostic, use a synthetic key-value lookup: provide records, ask for the value associated with a target key, and specify the exact correct answer in advance. For a more realistic test, use multi-document question answering with one passage containing the answer and other documents acting as distractors. Score the two task types separately; they measure different capabilities.
- Build matched prompt variants. Keep the question, answer-bearing passage, distractors, and instructions the same. Place the answer passage near the beginning, at several intermediate positions, and near the end. Change only its location, adjusting the distractor order as needed to preserve the rest of the test conditions.
- Repeat at multiple context lengths. Include short and medium inputs as well as a long input approaching the model’s advertised limit. Confirm the actual token count with the model tokenizer or inference stack; word and character counts are not reliable substitutes. Treat the claimed maximum as a limit to approach carefully, not as evidence that the test ran at that length.
- Hold the inference setup steady. Record and keep fixed the model checkpoint, quantization, tokenizer and prompt template, inference engine, sampling settings, question, and distractors. Changing these between position variants makes it harder to attribute a score difference to passage location.
- Run the same cases and score them consistently. Use a predefined answer key, record incorrect answers and refusals, and apply the same scoring rule to every variant. If generation is nondeterministic under your settings, repeat cases and report how many runs you performed.
- Compare results by position and length. Plot accuracy at each passage position for each context length. Report the best and worst position results and their gap, alongside the individual scores. A single aggregate score can hide a severe middle-position drop.
The original authors’ repository includes materials and procedures for multi-document QA with one answer-bearing passage among 10, 20, or 30 documents, as well as key-value retrieval data: Lost in the Middle experimental repository. These are reproducible starting points, but check that the software and data work with your model and inference environment.
Rank #2

- Unlock next-generation AI computing with AMD Ryzen AI Max+ 395 processor featuring 16 cores, 32 threads, up to 5.1GHz boost clock, and integrated Ryzen AI engine delivering up to 126 TOPS AI performance. EVO-X3 is designed for local AI models, content creation, development, and professional workloads.
- OCuLink External GPU Expansion – Upgrade Beyond a Mini PC: Take your graphics performance further with a dedicated OCuLink (PCIe 4.0 x4) interface. Connect an external GPU dock to add desktop-class graphics power for AAA gaming, AI acceleration, 3D rendering, video production, and advanced creative applications. EVO-X3 gives you the flexibility of a compact PC with workstation-level expansion capability.
- AI NPU with XDNA 2 ARCHITECTURE - Powered by 16 “Zen 5” CPU cores, 50+ peak AI TOPS XDNA 2 NPU and a truly massive integrated GPU driven by 40 AMD RDNA 3.5 CUs, the Ryzen AI MAX+ 395 is a transformative upgrade and delivers a significant performance boost over the competition. The Ryzen AI Max+ 395 excels in consumer AI workloads like the llama.cpp-powered application: LM Studio. Shaping up to be the must-have app for client LLM workloads, LM Studio allows users to locally run the latest language model without any technical knowledge required and unleash their creativity and productivity.
- AMD RADEON 8090S iGPU GAMING PC - The AMD Radeon RX 8060S offers all 40 CUs with up to 2.9 GHz graphics clock and uses the new RDNA 3.5 architecture. The powerful iGPU is positioned between an RTX 4060 and 4070 laptop GPU and therefore enables gaming in FHD at maximum details in most demanding games. The 8060S can also utilize the full 128GB pool, which is perfect for running LLMs such as Deepseek 70B Q8, which runs comfortably on this machine.
- EIGHT CHANNEL LPDDR5X - LPDDR5X is a new ground breaking memory small form factor installed on-board. With blazing speeds up to to 8000MT/s, it runs 1.5x faster than the DDR5 SODIMMs; 90% better performance over DDR5 SODIMMs in video conferencing and photo editing; 30% better performance in productivity apps; 12% better performance in digital content workloads.
What to report so the result is useful
A result applies to the tested configuration, not automatically to every version of the model family. Include enough detail for another person to interpret or repeat the run:
Free tools Windows power users keep installed
One-click scans. No signup required.
- Exact model checkpoint and quantization.
- Tokenizer, prompt template, inference engine, and sampling settings.
- Actual token counts and tested context lengths.
- Task type, question set, answer key, and how distractors were constructed.
- Accuracy at each tested passage position, plus the best-to-worst gap.
- Incorrect answers, refusals, and the number of runs per case.
Liu and coauthors argue that a claim of robust long-context use requires performance to be minimally affected by the relevant information’s position, including a minimal difference between best- and worst-case performance. That criterion is more informative than citing a context limit alone.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How much does a needle-in-a-haystack test prove?
A single-needle test—putting one fact into a large body of text and asking for it—can diagnose whether a model retrieves that fact under a particular setup. One successful answer, or even a high score on one such test, does not establish reliable retrieval across positions, multi-document comprehension, or synthesis across several sources.
A 2025 preprint, “Retrieval Quality at Context Limit,” reports that Gemini 2.5 Flash answered all 26 injected single-fact questions correctly at tested context sizes through 92% of its context limit; the test exceeded the limit at the next step. The setup used a Friends transcript, 20 fictional inserted facts, and direct factoid questions. This is a bounded result for that hosted model and test design—not a result for local models or a general refutation of positional effects: “Retrieval Quality at Context Limit”.
Rank #4
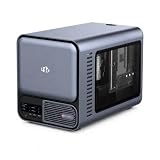
- 【YOUR PRIVATE TOKENS POWERED BY LOCAL LLM】 Driven by NIMO OS and local AI computing power, allocation optimizes local model inference for fast global search, custom AI agent workflows, and multimodal knowledge bases. It delivers secure storage, smart photo organizing, audio processing, and isolated multi-user privacy—offering a seamless, safe environment to handle your documents, photos, audio and videos without subscription fees.
- 【INTEL CORE ULTRA 7 356H PERFORMANCE】Built around the 16-core Intel Core Ultra 7 356H, NIMO AI NAS Pro delivers a powerful x86 platform for private cloud storage, virtualization, containers, media workflows and demanding local AI applications, giving creators, developers and advanced users strong everyday compute performance.
- 【EXPANDABLE GPU COMPUTE WITH PCIE GEN5 X8】A full-size PCIe x16 slot with PCIe Gen5 x8 signaling provides a flexible path for compatible discrete GPU expansion. Add GPU acceleration for local LLM inference, generative AI, RAG, rendering, video processing and other compute-intensive workloads as your needs grow.
- 【DUAL 10GBE FOR DATA-HEAVY WORKFLOWS】Dual 10GbE Ethernet provides the bandwidth needed for fast transfers of AI datasets, 4K/8K media, backups and large project files. Ideal for creators, AI workstations, small teams and homelabs that need high-speed multi-user access to centralized storage and compute resources.
- 【BUILT FOR LOCAL AI & PRIVATE DATA】Run compatible LLM inference, RAG knowledge bases, generative AI, computer vision and GPU-intensive workflows locally while keeping important models and business data on your own system, reducing dependence on remote cloud processing and giving users greater control over sensitive workloads.
Use a needle test as one diagnostic, and vary the fact’s location and total input length. If you want to make a broader claim about long-context use, add realistic multi-document questions and report those results separately from synthetic lookup.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Repair Windows errors before they cause bigger problems3Scan for outdated or missing drivers - takes under a minuteDoes a larger context window mean the model can use all of it?
No. The limit describes how much input the model can accept in a supported configuration; it does not guarantee that every relevant detail will be retrieved or used equally well at every position. A useful evaluation therefore measures task accuracy across multiple context lengths and passage positions. There is no current head-to-head result in the cited studies that ranks local 128K models, quantizations, or inference backends, so results from one setup should not be turned into a general model ranking.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




