A KV cache stores the attention keys and values a language model has already computed for tokens in an active sequence. Reusing that state avoids repeating work during token-by-token generation, but the cache takes memory and grows with the sequence. When a model’s weights fit in GPU memory, cache capacity and the traffic needed to read the cache can become important limits on how many requests a serving system handles and how quickly it generates. That is a common serving constraint, not a rule that the KV cache always matters more than the weights.
What the KV cache stores
In a decoder-only language model, attention layers calculate key and value tensors from the tokens being processed. During inference, the KV cache retains those tensors for tokens already seen in each active sequence. It is runtime state derived from the input and generated tokens—not a copy of the prompt, and not a store of the model’s learned parameters.
As an Amazon Associate I earn from qualifying purchases.
The learned parameters, usually called weights, are loaded to run the model. The cache is built as requests are processed and discarded or otherwise managed when their state is no longer needed. Hugging Face’s Transformers v5.3.0 caching documentation describes the cache as holding keys and values and growing with sequence length.
Free tools Windows power users keep installed
One-click scans. No signup required.
Why caching speeds up generation—and uses memory
Without reuse, earlier tokens would be processed again
Generation is autoregressive: the model produces a token, then uses it as part of the input to predict the next one. Earlier tokens still matter to those predictions. Recomputing their attention state at each step would repeat work, so the model can instead reuse the keys and values already stored for them.
#1 Best Overall

- [Color] PCB color may vary (black or green) depending on production batch. Quality and performance remain consistent across all Timetec products.
- DDR3L / DDR3 1600MHz PC3L-12800 / PC3-12800 240-Pin Unbuffered Non-ECC 1.35V / 1.5V CL11 Dual Rank 2Rx8 based 512x8
- Module Size: 16GB KIT(2x8GB Modules) Package: 2x8GB ; JEDEC standard 1.35V, this is a dual voltage piece and can operate at 1.35V or 1.5V
- For DDR3 Desktop Compatible with Intel and AMD CPU, Not for Laptop
- Guaranteed Lifetime warranty from Purchase Date and Free technical support based on United States
Hugging Face’s Transformers v4.50.0 Optimizing inference documentation describes the repeated KV computation that occurs as generated output becomes input. Caching avoids repeating that computation, exchanging some compute for memory use.
Every active sequence adds runtime state
As tokens are added to a sequence, its cached state grows. Serving several requests at once means maintaining state for several active sequences. Longer contexts and higher concurrency can therefore consume more cache memory, leaving less room for additional work on the accelerator.
Rank #2

- Office Gaming Mini PC - UPGRADED GMKtec Nucbox M5 Ultra Series is equipped with the powerful AMD Ryzen 7 7730U processor, 8 Cores/16 Threads, Base 2.00GHz (Power Saving Quiet Mode) with Turbo Boost up to 4.50GHz (Performance Mode) in BIOS settings, Based on the ZEN 3+ architecture, this small but powerful mini pc delivers satisfying results in productivity, office work, and gaming. 35% Performance increase over AMD Ryzen 5 7430U/ Ryzen 7 5700U, 5600U, 5560U, 5500U.
- 16GB DDR4 RAM & 256GB PCIe SSD - Installed with DDR4 16GB RAM (1x16GB), the Nucbox M5 Ultra mini pc support expansion to 64GB RAM. Featured with 256GB M.2 2280 PCIe 3.0 SSD, support dual slot expansion to 4TB SSD. (Upgrades not included)
- DUAL NIC LAN 2.5G RJ45 - Fast Network Speeds: Enjoy up to 2500Mbps data transmission speed without worrying about lagging. Ideal for working, gaming, and surfing the internet. Great for Untangle, Pfsense or as a server office PC.
- Mini Desktop Computer with 4K Triple Screen Display - Nucbox M5 Ultra integrates AMD Radeon Graphics 8 Cores 2000 MHz GPU to deliver powerful graphics processing power to easily handle the demands of complex design software, 4K@60Hz UHD video editing, and playback. It can connect to 3 display screens simultaneously.
- Fast Internet WiFi 6E + BT5.2 Connection - GMKtec Mini PC with WiFi-6E Wireless, have 2.5G/5G/6G triple band, more faster and lower latency. Bluetooth 5.2 allowing you more quickly to connect other wireless devices (headset, mouse, keyboard, etc.) Interface features 2*USB3.2 ports, 2*USB2.0 ports, 1*HDMI 2.0 port(4K@60Hz), 1*USB-C port(PD/DP/DATA), 1*DP Port, 1*Audio 3.5mm (HP&MIC), 1*DC Power Port.
Cache capacity and memory bandwidth are related to performance in different ways. Capacity constrains how much state can fit; during decoding, reading and moving cached state also uses memory bandwidth. The importance of either constraint depends on the model, workload, hardware, cache data type, and serving implementation. The available documentation does not establish a universal cache-size formula or a single point at which cache pressure overtakes weight-related limits.
When the cache can limit throughput more than weights
Weights and KV cache compete for finite device memory, but they play different roles. A large model may be weight-limited: its parameters may consume so much memory that loading the model is the main obstacle. If the weights fit, runtime cache can become a major capacity constraint, especially with long contexts or many simultaneous requests. In that regime, the cache can limit how many sequences fit on the device at once and, in turn, the serving system’s throughput.
Rank #3
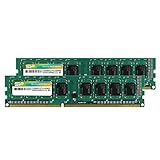
- Efficient performance: A lower voltage of 1.35 V is applied to reduce 20% power, enabling to effectively decrease hardware power consumption.
- System upgrade: With our high quality memory module, ideal for virtualization, cloud computing and multitasks handling, 100% factory-tested for stability, durability and compatibility.
- Durability Armed: 100% factory-tested to make sure the high stability, durability and compatibility.
- Compatibility is imperative: Compatible with major DDR3L / DDR3 motherboards.
- 【NOTE】The DDR3L UDIMM is backed by a lifetime warranty to promise complete services and technical support.
That does not mean the cache is always the throughput bottleneck. Prefill, when the prompt is processed, and decode, when output tokens are generated, have different performance characteristics. Latency targets, batch size, model dimensions, attention implementation, accelerator bandwidth, cache precision, context and output lengths, and concurrency all affect the result. The cited sources explain the cache’s memory demands and management techniques, but do not give a universal crossover point between weight and cache limits.
Ways serving systems manage KV memory
Flexible allocation with paged attention
PagedAttention organizes KV cache into blocks that can be allocated more flexibly than a single contiguous region. The approach is designed to reduce memory waste and support sharing. In their 2023 paper, Kwon and colleagues reported 2–4× higher throughput at the same latency level than the systems they compared, including FasterTransformer and Orca, on the paper’s evaluated workloads. That is a scoped experimental result, not a guaranteed improvement for every model, engine, or workload today.
Rank #4

- RYZEN 7 H 255 CPU - The Ryzen 7 H 255 is a chip from the Hawk Point family and is an upgraded version of the older Ryzen 7 8745H and has 8 cores (16 threads thanks to SMT support) that run at up to 4.9 GHz, together with the powerful Radeon 780M iGPU. Unlike Zen 3, Zen 4 offers AVX512 support along with other improvements such as larger caches/registers/buffers across the board.
- GAMING PC - The Radeon 780M (12 CUs / 768 shaders, up to 2,600 MHz) can drive multiple displays simultaneously with a resolution of up to 8K. Hardware encoding and hardware decoding of the most common video codecs (AV1, AVC, HEVC) is also no problem; playing the latest games on FSR settings without issues.
- WHY CHOOSE DDR5 5600MHz DUAL CHANNEL (2×16GB): With a 5600MHz clock—a 17% frequency uplift over 4800MHz—this kit delivers massive bandwidth gains that elevate real-world performance. Gamers enjoy higher minimum FPS and less stutter in open-world and sim titles for a smoother competitive experience. Video editors and 3D creators benefit from faster 4K/8K timeline scrubbing, quicker renders in DaVinci Resolve and Premiere, and swifter asset loading. For AI/LLM workloads, the superior throughput reduces I/O bottlenecks, cuts token generation latency, and accelerates model fine-tuning by keeping processing cores fed with data—so you wait less and create more.
- 32GB DDR5 RAM + 512GB SSD - The K12 mini computer is equipped with Dual 16GB (Total 32GB) SO-DIMM DDR5 5600MHz memory sticks. 512GB PCIE 4.0 SSD Drive with 3x M.2 2280 Expansion slots. Each slot capable of reading up to 8TB. (24TB MAX)
- QUAD SCREEN 4K DISPLAY SUPPORT - K12 Mini PC support 4-screen 4K/8K output via HDMI 2.1 (8K@60Hz), DisplayPort 1.4 (4K@60Hz), and USB Type-C Transfer speed (supporting PD3.0/DP1.4/DATA). Ideal for gaming, video editing, and multitasking, it provides expansive and crisp multi-display support.
Reuse for requests with matching prefixes
Automatic prefix caching can reuse KV blocks from earlier requests when a new request has a matching prefix. This avoids redundant work for shared prompt content. It is most relevant when requests actually share prefixes; it does not make unrelated prompts interchangeable. vLLM documents this feature as automatic prefix caching.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Offloading to free accelerator memory
Offloading moves some cache state away from the accelerator to reduce GPU memory pressure. That can make more room for other work, but moving state can cost time. Hugging Face’s cache-strategy documentation describes possible throughput degradation and notes that the effect depends on the model and generation choices. Exact support and behavior vary by engine and version.
Best Value

- Boosts System Performance: 32GB DDR5 RAM laptop memory kit (2x16GB) that operates at 5600MHz, 5200MHz, or 4800MHz to improve multitasking and system responsiveness for smoother performance
- Accelerated gaming performance: Every millisecond gained in fast-paced gameplay counts—power through heavy workloads and benefit from versatile downclocking and higher frame rates
- Optimized DDR5 compatibility: Best for 12th Gen Intel Core and AMD Ryzen 7000 Series processors — Intel XMP 3.0 and AMD EXPO also supported on the same RAM module
- Trusted Micron Quality: Backed by 42 years of memory expertise, this DDR5 RAM is rigorously tested at both component and module levels, ensuring top performance and reliability
- ECC Type = Non-ECC, Form Factor = SODIMM, Pin Count = 262-Pin, PC Speed = PC5-44800, Voltage = 1.1V, Rank And Configuration = 1Rx8
Setting a cache budget
Serving engines may expose a cache-memory budget. Allocating more memory to cache can support more active state, but reserving too much can leave insufficient memory for other allocations and cause an out-of-memory error. vLLM’s LLM API documentation describes this capacity-versus-OOM tradeoff. Check the documentation for the engine version in use rather than assuming that option names or behavior are the same across serving systems.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How to decide which approach fits
- If requests are long or concurrency is high: investigate whether cache capacity is limiting the number of sequences that fit. Consider allocation efficiency and the engine’s supported cache controls.
- If prompts frequently share prefixes: prefix reuse may reduce repeated processing for those matching portions.
- If GPU memory is tight: offloading may free accelerator memory, but measure its effect on generation speed for the actual model and workload.
- If raising the cache budget: balance the capacity needed for active requests against memory required by the model and other runtime allocations; excessive reservation risks OOM.
No single technique improves end-to-end performance in every case. Context length, output length, request concurrency, prefix reuse, latency goals, hardware, and engine implementation determine which tradeoff matters.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




