Start by deciding which services must survive an outage, then map what each depends on. Add redundancy only where it removes a consequential failure point you can operate and test. Two servers do not make a service highly available if both rely on the same switch, firewall, storage, power, or DNS.
Decide what “available” means for your homelab
Not every service needs the same protection. A home automation controller may be important during a power outage; a media server may be acceptable to restore later. Before changing hardware, set a target for each service:
As an Amazon Associate I earn from qualifying purchases.
- Required availability: Must it keep working through a component failure, or is manual recovery acceptable?
- Acceptable interruption: How long can it be unavailable before the outage becomes a problem?
- Acceptable data loss: Could you recreate data since the last backup, or must recent changes be preserved?
- Recovery owner and method: Who will restore it, and what steps, credentials, and spare parts will they need?
These answers define whether a service needs automatic failover, a documented manual recovery, or simply a reliable backup. They also prevent spending effort on a low-impact service while a critical dependency remains unprotected.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Map each service’s dependency chain
Trace the path from a client to the service and back. Include external dependencies as well as the server hosting the application. A typical path might include internet access, DNS, firewall, switch, host, storage, and power. A failure anywhere in that chain can make the service unavailable.
#1 Best Overall

- 【DeskPi RackMate T1】It's made of aluminum alloy and acrylic frame mini chassis which you can setup your own cluster or home assistant server. For 10 inch 4U Server Cabinet (DeskPi RackMate T0), please refer to ASIN B0DPGZPTPP. For 10 inch 12U Server Cabinet (DeskPi RackMate T2), please refer to ASIN B0DT2XM22G.
- 【10-inch width】The cabinet has a width of 10 inches, which is a relatively small size that saves space while accommodating sufficient equipment. With dimensions of 11x7.8x16 inches, it is suitable for small offices, home environments, and large enterprises looking to save space.
- 【Open Design】The cabinet adopts an open design, allowing easy access to all devices inside. This design facilitates equipment installation and maintenance, aids in device cooling, and maintains optimal working conditions.
- 【8U Standard】The cabinet has a height of 8U, which is a standard unit size. With 1U equaling 1.75 inches, 8U implies a height of 14 inches.
- 【Translucent Design】Both sides are made of translucent acrylic, providing dust resistance and reduced weight. This design allows direct observation of the cabinet's interior, and users can add ambient lights for decoration.
Draw a separate chain for each service, then mark shared components. If several services rely on one DNS resolver, switch, firewall, storage system, or power strip, that component is a common failure point. A pair of compute nodes does not remove it.
- Network: Does access depend on the internet, one firewall, one switch, a VLAN, or a particular link?
- Name resolution: Can clients reach the service by IP if DNS is unavailable? Does the resolver itself depend on the service it helps locate?
- Compute: Which host runs the application, and can another host run it with the available CPU, memory, and configuration?
- Storage: Is data local to one host, on one shared device, or replicated? What happens if the storage system is unavailable or corrupted?
- Power: Are both hosts, the switch, and the firewall on the same outlet or battery backup?
- Administration: Can you reach the management interface during the failure, and do you have the credentials and configuration needed to recover?
For each dependency, record the failure effect, the workaround, and whether the workaround has been tested. This turns a vague goal—“make the lab redundant”—into a list of specific risks.
Choose the least complicated protection that meets the target
Resilience options cover different failure types. A backup is not a standby server, and a UPS is not a backup. Pick protections against the failures that matter for each service rather than treating any one measure as universal.
Rank #2

- Adjustable Depth: 23-40'' adjustable depth is used for servers and network equipment, ensuring enough space for AV equipment, components, and cabling, while allowing you to access ports and equipment from multiple sides.
- Strong Load Capacity: Ground-Mounted Load Capacity: 500 lbs, Wall-Mounted Load Capacity: 150 lbs. The av rack is made of carbon steel for better weldability performance and can help save space while meeting your need to place multiple devices.
- User-friendly Design: Ergonomic design makes the open frame av rack easier to use. The additional top panel is able to place other items with more available space. Roller design moves anywhere and anytime, is convenient, and is more energy-saving.
- Complete Accessories: We provide the accessories you need, including 2 x Pallets, 145 x M5*10 Cross Head Screws, 4 x Casters, 4 x M10*50 Expansion Screws,10 x M6*12 Cage Nuts, 1 x Grounding Wire, 1 x User Manual.
- Wide Application: The server rack wall mount maximizes the use of available space, suitable for retail venues, classrooms, offices, and other places where space is limited.
| Protection | Useful for | Does not by itself solve |
|---|---|---|
| Tested backup and restore procedure | Recovering from data loss, corruption, accidental deletion, or a failed system | Keeping a service continuously available during recovery |
| Spare part or documented manual recovery | Replacing a failed component or rebuilding a service after an outage | Automatic failover or loss of data without a recoverable copy |
| UPS / battery backup | Providing a limited runtime or time for an orderly shutdown during utility-power interruption | Failures unrelated to utility power, such as a failed switch or corrupted storage |
| Redundant firewall or compute node | Taking over some work after a covered device failure, if configuration and dependencies support it | Shared dependencies, faulty changes, or a recovery path that has not been tested |
Prioritize recoverable backups and a written restore procedure before adding a second copy of everything. A UPS can help with power interruptions, but size it for the actual connected load and the runtime or shutdown window you want; it will not protect against unrelated component failures. Proxmox VE’s administration guide search excerpt recommends a UPS, but that excerpt does not establish sizing guidance for a particular system or load: Proxmox VE Administration Guide.
Use firewall failover only when the network can support it
OPNsense documents a firewall high-availability pattern using CARP virtual IPs. With a suitable Layer 2 design, a backup firewall can take over a virtual address when the primary fails. Optional pfSync state replication can help existing connections survive a transition; it is not a promise that every session will remain uninterrupted. OPNsense recommends a dedicated state-synchronization interface for security and performance, and says firewall versions should match for state-synchronization compatibility. See OPNsense High Availability.
CARP depends on the network between the firewalls working as expected. OPNsense’s setup guide calls for matching interface assignments and correct handling of CARP traffic. The firewalls need the appropriate shared Layer 2 domain and switching fabric. Switch settings such as IGMP snooping without a querier, MAC restrictions, storm controls, or uncoordinated switching fabrics can disrupt failover. Virtualized and cloud networks may restrict multicast, MAC movement, or gratuitous ARP, making CARP unreliable or unsupported. Mismatched virtual IP settings or lost advertisements can cause split brain, where both firewalls behave as active. Check the deployment constraints in OPNsense’s Configure CARP guide.
Rank #3

- 【Powerful Load-bearing】12U Network Rack Open Frame is constructed from durable cold rolled steel; Rack shelf supports enhance stability, wall-mounted capacity of 130lbs, the ground-mounted up to 260lbs
- 【Considerate Designs】Open-frame layout, including a top panel adding space, anti-slip shelf stops fixing devices and compatible racks for stack and expansion to meet requirements of home server rack
- 【Complete Accessories】A 12U open frame server rack, two ventilated shelves, four shelf stops, four velcro straps and a set of equipment mounting screws
- 【Versatile Application】Ideal for space-efficient multi-device setups in warehouses, retail, classrooms, offices and more; Excellent choices as AV Rack/IT Rack
- 【Effortless Setup】 Network Rack includes hardware, a comprehensive manual, mounting hole drilling template and an online assembly video to simplify setup
Configuration synchronization introduces its own risk: OPNsense warns not to configure the backup node to synchronize back to the master, because that can create configuration errors. Treat synchronized configuration as a controlled design choice, not a substitute for keeping a known-good configuration backup.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Plan cluster quorum and workload behavior
A cluster can keep workloads running through some failures, but it does not eliminate control-plane dependencies. Docker Swarm requires a manager majority for management operations. Its documented figures are specific to Swarm managers: three managers require a majority of two and tolerate one manager failure; five require a majority of three and tolerate two. Docker recommends an odd number of managers and notes that one manager has no manager-failure tolerance. These numbers describe quorum, not general homelab reliability or application availability. See the Docker Swarm administration guide.
If a Swarm loses quorum, existing tasks on workers can continue running, but managers cannot add, update, or remove nodes, or start, stop, move, or update tasks until quorum returns or recovery occurs. A workload that is already running may therefore remain available while the operator cannot make the management changes needed to respond to the outage.
Rank #4

- 【DeskPi RackMate T1】It's made of aluminum alloy and acrylic frame mini chassis which you can setup your own cluster or home assistant server. For 10 inch 4U Server Cabinet (DeskPi RackMate T0), please refer to ASIN B0DPGZPTPP. For 10 inch 12U Server Cabinet (DeskPi RackMate T2), please refer to ASIN B0DT2XM22G.
- 【10-inch width】The cabinet has a width of 10 inches, which is a relatively small size that saves space while accommodating sufficient equipment. With dimensions of 11x7.8x16 inches, it is suitable for small offices, home environments, and large enterprises looking to save space.
- 【Open Design】The cabinet adopts an open design, allowing easy access to all devices inside. This design facilitates equipment installation and maintenance, aids in device cooling, and maintains optimal working conditions.
- 【8U Standard】The cabinet has a height of 8U, which is a standard unit size. With 1U equaling 1.75 inches, 8U implies a height of 14 inches.
- 【Translucent Design】Both sides are made of translucent acrylic, providing dust resistance and reduced weight. This design allows direct observation of the cabinet's interior, and users can add ambient lights for decoration.
Place managers across genuinely separate failure domains where practical. Docker’s guidance discusses distributing managers across availability zones; a typical home network does not have independent zones unless you deliberately separate power and network locations. Several managers connected to the same switch and power source may still be lost together. Add nodes only after deciding which workloads can move, whether storage and networking follow them, and how you will recover control-plane state.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Keep backups and failover separate in your recovery plan
Failover is intended to preserve service through selected failures; backups are for restoring data or systems after loss, corruption, or mistakes. Replication can copy an unwanted change or corrupted data to another node, so it is not a replacement for a protected, recoverable backup.
Free tools Windows power users keep installed
One-click scans. No signup required.
For Docker Swarm, Docker documents backing up the entire /var/lib/docker/swarm directory from a manager. It recommends stopping Docker first for a consistent backup; a hot backup is possible but less predictable. If auto-lock is enabled, preserve the unlock key. Restoring requires the documented recovery sequence and checking that expected services return. This is a Swarm-specific procedure, not a generic backup recipe for other homelab software. Follow the current instructions in the Docker Swarm administration guide.
Best Value
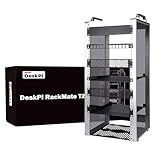
- 【DeskPi RackMate T2】It's made of aluminum alloy and acrylic frame mini chassis which you can setup your own cluster or home assistant server. For 10 inch 4U Server Cabinet (DeskPi RackMate T0), please refer to ASIN B0DPGZPTPP . For 10 inch 8U Server Cabinet (DeskPi RackMate T1), please refer to ASIN B0CSCWVTQ7 .
- 【10-inch width】The cabinet has a width of 10 inches, which is a relatively small size that saves space while accommodating sufficient equipment. With dimensions of 11.02x10.23x23.22 inches, it is suitable for small offices, home environments, and large enterprises looking to save space.
- 【Open Design】The cabinet adopts an open design, allowing easy access to all devices inside. This design facilitates equipment installation and maintenance, aids in device cooling, and maintains optimal working conditions.
- 【12U Standard】The cabinet has a height of 12U, which is a standard unit size. With 1U equaling 1.75 inches, 12U implies a height of 21 inches.
- 【Translucent Design】Both sides are made of translucent acrylic, providing dust resistance and reduced weight. This design allows direct observation of the cabinet's interior, and users can add ambient lights for decoration.
For every backup that matters, know where it is stored, how it is protected, and how to restore it without relying on the system that failed. A backup that has never been restored is an unverified recovery plan.
Look for common-mode failures and operating costs
Redundancy helps only when the alternative can function independently enough to take over. Before adding a second device, check whether it shares the same failure modes:
- Shared power: Both devices use the same outlet, UPS, or power circuit.
- Shared network: Both depend on one switch, uplink, or firewall interface.
- Shared storage: Multiple hosts rely on one storage device or a single data copy.
- Shared configuration: A bad or incompatible update is synchronized to both systems.
- Version skew: Different versions prevent state replication or produce different behavior.
- Network partition: Nodes cannot communicate, even though each may still be running.
- Split brain: Multiple nodes believe they should be active, risking conflicts or inconsistent service.
- Maintenance burden: More components require monitoring, patching, configuration control, and regular failover tests.
Document which failures each redundant component covers and what remains shared. If the second device adds more operational work than the risk it removes, a tested manual recovery plan may be the better design.
Test both failure and restoration
A feature described as automatic failover does not prove that a particular deployment will fail over correctly. Test the path under controlled conditions, one component at a time, and verify both service behavior and recovery.
- Write down the expected result. Identify the service, the component to isolate, what should remain available, and how much interruption or data loss is acceptable.
- Record a baseline. Confirm normal access, DNS resolution, data availability, and management access before the test.
- Isolate one component safely. For example, disconnect one host or a planned network link. Avoid pulling power or cutting connectivity in a way that could corrupt data or affect unrelated services.
- Check user-visible behavior. Test from a client, not only from the server console. Confirm whether the service remains reachable and whether existing sessions or new connections behave as expected.
- Check management and dependencies. Verify that DNS, storage, monitoring, and the control plane remain usable, and note any manual actions required.
- Restore the component. Confirm that the system returns to a stable state, that data is consistent, and that failback does not create a second outage.
- Practice backup recovery separately. Restore data or configuration to a safe target and confirm the result matches what the service needs.
- Update the runbook. Record actual behavior, commands or interface paths, credentials required, and any gap between expected and observed recovery.
Repeat after major network, software, or configuration changes. A simple design with a tested restore path is often more dependable than a larger cluster whose shared dependencies and recovery steps are unknown.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




