Freedom251 › AI transcription tools
Vosk
What Vosk is
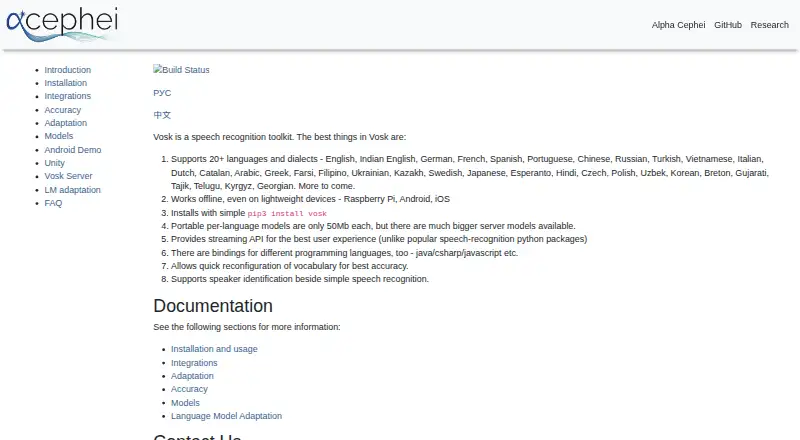
Vosk is a free, open-source toolkit for adding offline speech recognition to applications. It supports more than 20 languages and dialects and provides a streaming API. The toolkit can run without an internet connection on lightweight devices such as Raspberry Pi, Android, and iOS. Developers can reconfigure vocabulary, and most small models allow dynamic vocabulary changes. Small models are typically around 50 MB and need about 300 MB of runtime memory; large server models can require up to 16 GB. Developer interfaces include Python, Java, C#, and JavaScript, among others. Vosk Server has implementations for WebSocket, gRPC, MQTT, and WebRTC, and listed integrations include Asterisk, FreeSWITCH, Jigasi, and UniMRCP. The server can be installed with Docker and configured to use a locally mounted model folder. Listed systems include Linux x86_64 and arm64, Raspberry Pi 3/4, macOS x86 and M1, and Windows x86 and 64 for the Python package. ARMv6 and Windows ARM64 are not supported; iOS builds are available on request. The API repository identifies its license as Apache-2.0.
Who it suits
Vosk is aimed at developers adding speech recognition to applications, particularly when offline operation or streaming is needed. Its FAQ presents it as a practical library for applications and suggests Kaldi for research.
What it does well
- Works offline on mobile and lightweight devices.
- Supports more than 20 languages and dialects.
- Provides a streaming recognition API.
- Vocabulary can be reconfigured.
- Includes bindings and multiple server protocols.
What to know first
- ARMv6 and Windows ARM64 are not supported.
- iOS builds are available on request.
- Large server models can require up to 16 GB.
Limits
Small models are typically around 50 MB and require about 300 MB of runtime memory; large server models can require up to 16 GB. ARMv6 and Windows ARM64 are unsupported, and iOS builds are available on request.
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| Vosk Open Source | offline speech recognition · mobile and server · 10 platforms | Free |
As alphacephei.com lists them, read 11 Oct 2026. The maker's own page has the final word.
Getting started
- Visit the Vosk website.
- Choose a model suited to the target device and its memory.
- Use a developer binding or install Vosk Server with Docker.
- For a Docker server, configure a locally mounted model folder.
- Connect through a supported server protocol or listed integration.
Vosk is an open-source toolkit for adding speech recognition to applications, rather than a ready-made transcription workspace. It suits developers who need recognition to run offline, from small devices to servers. Its appeal is flexible local deployment; the right model and supported platform still depend on the target hardware.
Overview
Vosk supports more than 20 languages and dialects and can recognize speech without an internet connection, including on Raspberry Pi, Android, and iOS devices. That makes it a practical choice for applications that need speech input when connectivity is absent or unreliable. Developers looking for a finished transcription product should look elsewhere: Vosk is a toolkit to build into software.
Model requirements vary widely. Small models are typically around 50 MB and use about 300 MB of runtime memory; large server models can require up to 16 GB. This range gives developers options for constrained devices and server deployments, but model selection directly affects whether a target device can run the system.
Key features
Offline and streaming recognition
Vosk combines offline operation with a streaming API, allowing applications to process speech as it arrives without relying on a network connection. Speaker identification and timestamps can add structure to recognized speech, while TXT and SRT are supported export formats. These capabilities suit applications that need locally processed, time-aligned speech; they do not make Vosk a complete transcription workflow on their own.
Configurable vocabulary and developer interfaces
Vocabulary reconfiguration lets developers adapt recognition to an application's terminology, and most small models support dynamic vocabulary changes. Bindings include Python, Java, C#, and JavaScript, among other languages, giving teams several ways to integrate the toolkit. The breadth is useful for application development, though adapting vocabulary and choosing a compatible model remain implementation decisions.
Server deployment and integrations
Vosk Server supports WebSocket, gRPC, MQTT, and WebRTC implementations. It can be installed with Docker and configured to use a locally mounted model folder. Integrations include Asterisk, FreeSWITCH, Jigasi, and UniMRCP, which can make it relevant to telephony and communications systems. The server's possible memory demand makes hardware planning especially important for larger models.
Pricing
Vosk Open Source: free. The plan includes offline speech recognition for mobile and server use across 10 platforms. Vosk is open source under the Apache-2.0 license, so it fits developers who want to build and deploy recognition without a subscription. There are no paid tiers or stated seat and usage caps in this plan.
Platforms
Vosk lists Android, iOS, Linux, macOS, self-hosted deployments, and Windows. Its Python package supports Linux x86_64 and arm64, Raspberry Pi 3 and 4, macOS x86 and M1, and Windows x86 and 64. ARMv6 and Windows ARM64 are unsupported, and iOS builds are available on request. Those limits matter when selecting devices: broad platform coverage does not mean every processor architecture has a ready build.
Who it's for
Vosk is a strong fit for developers building speech recognition into applications that need offline operation, streaming, configurable vocabulary, or local server deployment. Its small models make lightweight hardware an option, while its language bindings and server protocols give teams multiple integration paths. It is less suited to users seeking a finished transcription workspace, or researchers who want a speech-recognition research toolkit; the project points research users toward Kaldi.
Pros and cons
- Pros: Offline recognition works on devices including Raspberry Pi, Android, and iOS, which suits deployments that cannot depend on connectivity.
- Pros: Streaming, timestamps, speaker identification, and configurable vocabulary support application-specific recognition workflows.
- Pros: Python, Java, C#, JavaScript, multiple server protocols, and Docker deployment offer several integration routes.
- Cons: Model memory ranges from about 300 MB for typical small models to as much as 16 GB for large server models, limiting what some devices can run.
- Cons: ARMv6 and Windows ARM64 are unsupported, and iOS builds require a request, which can constrain platform plans.
- Cons: Vosk is a toolkit rather than a finished transcription workspace, so it best serves teams prepared to integrate recognition into their own software.
Alternatives
Choose Kaldi if speech-recognition research is the priority; it is free and its Apache License 2.0 permits commercial use and redistribution. Notta is an alternative for readers who prefer a transcription product with a free plan capped at one seat and 120 transcription minutes per month. CMU Sphinx is another free toolkit option, with a BSD-like license that permits commercial distribution.
Gladia is an alternative with a free trial and a Starter asynchronous plan priced at $0.61 a month. Speechmatics offers a free plan with $100 in credits, two concurrent real-time sessions, and 10 pre-recorded files per second. Superwhisper provides a free plan for voice-to-text in any app, meeting recording and transcription, and 100+ languages. MacWhisper offers free transcription and subtitle export, with a Pro plan at €64 a month billed Pay Once. SpeechRecognition is another free, open-source library for working with supported speech engines and APIs.
For broader directories, browse Speech Recognition Software, Transcription Software, and Speech-to-Text Software.
Verdict
Choose Vosk if you are building an application that needs offline or streaming recognition and want control over local deployment. Its free, open-source toolkit, device range, and developer interfaces are compelling for that use. Look elsewhere if you need a ready-to-use transcription workspace, or confirm that the target hardware and platform fit the chosen model before committing to a deployment.
Verdict
Vosk provides offline recognition, streaming, and developer interfaces across a range of devices and server protocols. Check its platform limits and model memory requirements when choosing a deployment.
Questions
Does Vosk work offline?
Yes. It supports offline speech recognition, including on Raspberry Pi, Android and iOS.
How much does Vosk cost?
The listed Vosk Open Source plan is free.
Which languages and developer interfaces does it support?
It supports more than 20 languages and dialects. Bindings include Python, Java, C# and JavaScript, among other languages.
Can Vosk identify speakers and export transcripts?
Speaker identification and labeling, timestamps, and TXT and SRT export are listed.
What license does Vosk use?
The Vosk API GitHub repository identifies its license as Apache-2.0.
Which systems are supported?
The installation page lists Linux x86_64 and arm64, Raspberry Pi 3/4, macOS x86 and M1, and Windows x86 and 64 for its Python package. ARMv6 and Windows ARM64 are unsupported; iOS builds are available on request.
Facts from Vosk's own pages
- API access
- Yes · alphacephei.com, 20 Sept 2026
- Deployment
- The server can be installed with Docker and configured to use a locally mounted model folder. · alphacephei.com, 11 Oct 2026
- Developer interfaces
- The project provides bindings for Python, Java, C#, and JavaScript, among other languages. · alphacephei.com, 11 Oct 2026
- Export formats
- TXT,SRT · alphacephei.com, 20 Sept 2026
- Integrations
- The integrations page lists Asterisk, FreeSWITCH, Jigasi, and UniMRCP integrations. · alphacephei.com, 11 Oct 2026
- Intended users
- The FAQ describes Vosk as a practical, plug-and-play speech recognition library for applications, while suggesting Kaldi for research. · alphacephei.com, 11 Oct 2026
- Languages
- The toolkit supports more than 20 languages and dialects. · alphacephei.com, 11 Oct 2026
- License
- The Vosk API GitHub repository identifies its license as Apache-2.0. · github.com, 11 Oct 2026
- Model sizes
- Small models are typically around 50 MB and require about 300 MB of runtime memory; large server models can require up to 16 GB. · alphacephei.com, 11 Oct 2026
- Offline use
- Vosk works offline, including on lightweight devices such as Raspberry Pi, Android, and iOS. · alphacephei.com, 11 Oct 2026
- Platform limits
- The installation page says ARMv6 and Windows ARM64 are not supported, and iOS builds are available on request. · alphacephei.com, 11 Oct 2026
- Product
- Vosk is a speech recognition toolkit for offline speech recognition. · alphacephei.com, 11 Oct 2026
- Server protocols
- Vosk Server has implementations for WebSocket, gRPC, MQTT, and WebRTC. · alphacephei.com, 11 Oct 2026
- Speaker identification
- Vosk supports speaker identification alongside speech recognition. · alphacephei.com, 11 Oct 2026
- Speaker identification
- Yes · alphacephei.com, 20 Sept 2026
- Streaming
- Vosk provides a streaming API for speech recognition. · alphacephei.com, 11 Oct 2026
- Support
- The project directs users to GitHub issues, email, Telegram, and an invitation-only WeChat group for questions. · alphacephei.com, 11 Oct 2026
- Supported systems
- The installation page lists Linux x86_64, Linux arm64, Raspberry Pi 3/4, macOS x86 and M1, and Windows x86 and 64 for its Python package. · alphacephei.com, 11 Oct 2026
- Timestamp support
- Yes · alphacephei.com, 20 Sept 2026
- Vocabulary
- Vosk allows vocabulary reconfiguration, and its models page says most small models support dynamic vocabulary changes. · alphacephei.com, 11 Oct 2026
Where Vosk stands on Freedom251
- AI transcription tools#10 of 46
- Speech-to-Text Software#19 of 35
- Transcription Software#27 of 46
- Speech Recognition Software#20 of 32