What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Splink itself is not incompatible with API calls. It is a Python package, and its getting-started guide shows it running from ordinary Python code. What usually breaks is the fit between a full record-linkage run and the request path it sits inside: the time, memory, CPU, data transfer, and concurrency limits that an HTTP request must respect. For short, predictable work, a synchronous endpoint can succeed. For longer or variable jobs, accept the request, process it outside the request cycle, and let the client check back for the result.
What Splink is, and what it is not
Splink is a Python package for probabilistic record linkage (entity resolution). It deduplicates and links records in datasets that lack unique identifiers. The documented workflow has three broad stages: estimating model parameters, predicting the pairs of records likely to match, and clustering those pairs into groups. Each stage can be expensive on a large input, and the cost depends on your data and settings rather than on any single number.


As an Amazon Associate I earn from qualifying purchases.
The official getting-started guide states that Splink requires Python 3.10 or later, and that DuckDB is installed by default. Spark and PostgreSQL are optional backends that you install separately. Confirm the installed version before copying any example, because the API has changed across releases.
The project’s repository makes a broad performance claim: it is “capable of linking a million records on a laptop in around a minute.” This is a statement from the project maintainers (MOJ Analytical Services, repository viewed 2026-10-07). It is not a guarantee, an independent benchmark, or an estimate for your dataset, your settings, or a server-side request handler.
The request path has several clocks
A linkage call can fail against any one of several limits. The most common mistake is to tune only the compute timeout while the client or gateway gives up earlier.
| Boundary | What it limits | Documented value |
|---|---|---|
| Serverless function timeout (AWS Lambda) | Maximum time one invocation may run | Configurable from 1 to 900 seconds (15 minutes) for ordinary invocations, per AWS Lambda configuration documentation viewed 2026-10-07 |
| API gateway integration timeout (AWS API Gateway) | How long the gateway waits for the backend before returning an error to the caller | A default of 29 seconds is cited in AWS API Gateway documentation viewed 2026-10-07. The applicable value depends on API type and configuration, so check your deployment. |
| Client or proxy timeout | How long your calling application or any reverse proxy waits | Not stated by AWS; set by your client library or infrastructure |
| Memory allocation | Working memory available to the process | Depends on your platform configuration; no single value applies |
Raising the Lambda timeout does nothing to a shorter gateway deadline. The request will still fail at the gateway, and the function may keep running after the caller has received an error. The three timeouts must be compared as a chain, and the shortest one governs what the client sees.
Rank #2
The limits above are AWS examples, not a universal API rule. Other providers and self-hosted stacks set their own defaults.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Fix the driver behind crashes, sound loss and screen glitches3Clear out junk files and repair common Windows errorsIdentify which failure you actually have
“Splink won’t run in my API” covers at least six different problems. Each one points to a different fix.
Rank #3
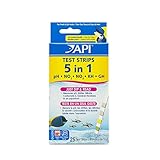
- Contains one (1) API 5-IN-1 TEST STRIPS Freshwater and Saltwater Aquarium Test Strips 25-Count Box
- Monitors levels of pH, nitrite, nitrate carbonate and general water hardness in freshwater and saltwater aquariums
- Dip test strips into aquarium water and check colors for fast and accurate results
- Helps prevent invisible water problems that can be harmful to fish and cause fish loss
- Use for weekly monitoring and when water or fish problems appear
| Symptom | Likely category | First thing to check |
|---|---|---|
| Import error or missing module at cold start | Deployment or packaging | Whether the package and its dependencies are in the deployed bundle, and whether the runtime is Python 3.10 or later |
| Gateway returns a 504 while the backend is still working | Gateway deadline shorter than the job | Measured job duration against the integration timeout |
| Function reports it exceeded its timeout | Compute time limit | Per-stage timings and the configured function timeout |
| Process is terminated for exceeding memory | Memory headroom | Peak memory at the largest realistic input size |
| Connection or query error from the backend | Database or backend setup | Backend installation, credentials, and file or connection paths |
| Errors only when requests overlap | Concurrency and shared state | Whether requests share a single database connection or mutable linker state |
Diagnose in this order
- Record the environment. Run
pip show splinkandpython --versionin the same environment the API uses. Note the backend you chose, the row and column counts of the input, and the linkage settings. - Time each stage. Wrap parameter estimation, pair prediction, and clustering in separate timers. Run the measurement at the largest input you realistically expect, not a small sample. A tiny test set can hide the cost that matters.
- Compare against every boundary. Set the measured upper-bound duration against the function timeout and the full end-to-end deadline, including the gateway and any client or proxy limit. If the total is larger than the shortest boundary, the request cannot succeed synchronously.
- Look for repeated work. Check whether the input is reloaded or copied on every request, whether the model is retrained when a stored model would do, and whether intermediate results are recomputed. These are hypotheses to test. Measuring each stage will show which, if any, applies to your case.
- Test concurrency explicitly. Send parallel requests and watch for errors that appear only under overlap. Section below covers the most common cause.
- Decide from the measurement. Keep the job synchronous only if the upper-bound runtime fits comfortably inside the shortest boundary with headroom. Otherwise, move it to a background job.
Concurrency and the DuckDB global connection
Splink’s default backend, DuckDB, has a shared module-level connection in its Python API. The DuckDB documentation explains the risk directly: “That is because the duckdb module uses a shared global database – which can lead to hard to debug issues if used from within multiple different packages” (DuckDB Python API overview, viewed 2026-10-07).
In a web service, this matters when several requests share one module-level connection or mutable state. The fix is to manage connection objects deliberately, creating them per request or per worker in a way that prevents threads from sharing one. Then confirm the fix by sending parallel requests and comparing results against sequential runs. This is a specific caveat, not an explanation for every failure, so do not assume it is your cause without reproducing it.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Choose between synchronous and background processing
Use the measured upper bound and the shortest boundary to decide. The table below compares the two designs on the factors that usually decide the choice.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Repair Windows errors before they cause bigger problemsFix Now →| Factor | Synchronous endpoint | Background job |
|---|---|---|
| Typical fit | Short, predictable runs that finish well inside the shortest timeout | Long or variable runs, or inputs whose size varies widely |
| Client experience | Single request and response | Submit, receive a job identifier, then poll or receive a completion notice |
| Failure behavior | A timeout returns an error to the caller, and work may continue unseen | Failures are recorded against the job and can be retried or reported |
| Added complexity | Low | Requires job state storage, a worker, and a retrieval path |
| Reporting progress | Not practical | Status can be stored and read at any point |
Choose synchronous only when your measurements show a comfortable margin under the shortest boundary. If the workload grows over time, plan for the background design before the margin disappears.
Run linkage as a background job
AWS publishes an asynchronous processing pattern for API Gateway and Lambda (AWS asynchronous API guidance, viewed 2026-10-07). The same shape works with other queues and runners.
- Accept the request. The endpoint validates the input, creates a job record with a unique identifier and a status of queued, and returns that identifier to the caller quickly.
- Queue the work. Place the job on a queue or hand it to a worker process. The API handler does not run the linkage itself.
- Process the job. A worker loads the input, runs the Splink stages, and writes the output to storage. It updates the status at each stage so progress is visible.
- Record the outcome. On success, store the result location and mark the job complete. On failure, store the error and mark the job failed so it can be inspected or retried.
- Return status on request. Provide a status endpoint keyed by the job identifier. The client polls it, or you send a notification when the job completes.
Keep the job record separate from the linkage code. That separation lets you change the worker, the backend, or the storage without changing the client contract.
Quick Recap
When a different backend helps
- Spark and PostgreSQL are documented alternate backends in Splink. They are not automatic fixes for a timeout. Moving the same workload to a different backend leaves the request path unchanged.
- Choose a backend based on measured workload and where your data already lives. Data locality affects transfer cost and latency, and those affect runtime as much as the linkage algorithm does.
- Test any backend change with the same upper-bound input you used for the original measurement, so the comparison is fair.
Practical next steps
- Confirm the installed Splink version, Python runtime, and backend in the environment that serves the API.
- Measure each linkage stage at the largest realistic input, with the configured memory allocation.
- Compare that duration against the function timeout, the gateway integration timeout, and the client deadline, using the smallest value as the limit.
- If the job fits with margin, keep it synchronous and test parallel requests. If it does not, move it to a background job with a status endpoint.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →



