What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
A trace can show that an agent attempted a tool call, and an approval gate can stop a pending call before it runs. Neither fact, by itself, proves that every route to a protected resource is authorized. The distinction matters: observability tells you what a configured trace recorded; enforcement decides whether a specific action may proceed.
What did the harness miss?
The title’s “logged miss” describes a specific event, but without the underlying trace and system account, its tool, arguments, target, policy result, timestamp, and outcome cannot be established. A call absent from a trace is not proof that it never happened. OpenAI tracing is configurable, and tracing is unavailable when Zero Data Retention is enabled; the meaning of an absent event depends on the deployment’s actual configuration. See OpenAI’s tracing documentation.


As an Amazon Associate I earn from qualifying purchases.
That uncertainty is also a useful design lesson: a trace is evidence of recorded events, not a substitute for an authorization decision. Record enough context to connect a proposed call to its policy decision and eventual execution result, while being precise about which events the tracing configuration captures.
Recommended Free Tools
What does a log prove—and what does a stop prove?
OpenAI’s Agents SDK distinguishes recording an event from interrupting execution. When a tool requires approval, the SDK records an interruption rather than executing that tool, returns the interruption and resumable state, and lets the application approve or reject before resuming the same run. The log can document that lifecycle; the application’s decision is what determines whether the pending call proceeds. OpenAI puts the responsibility plainly: “Add review and enforcement to your own harness.” Read the approval lifecycle documentation.
A stop that held is meaningful evidence about the particular pending call and the boundary that intercepted it. To make the claim verifiable, identify the proposed tool call, the component that made the decision, whether execution occurred, and the records linking the request, decision, and outcome. Do not infer from one intercepted call that every path to the same resource is governed.
Where should authorization happen?
Put the decisive check where the action can still be blocked—at or immediately before the side effect. OpenAI recommends validating side-effecting tools close to execution and checking the proposed target, action, arguments, identity, and scope. A request-scoped choice about which tools are available does not replace authorization that depends on the arguments or resource a tool will access. For OpenAI’s JavaScript SDK, those checks belong in execution or an appropriate tool input guardrail or approval flow; MCP servers must authorize their own protected operations. OpenAI’s guardrail guidance explains these boundaries.
In practical terms, check not only “may this caller use this tool?” but also “may this caller perform this action on this resource, with these arguments, in this task or engagement?” A check that runs only after a result arrives may provide useful detection, but it cannot prevent the side effect that already occurred.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchRank #2
Why the harness boundary matters
OpenAI describes the harness as the control plane around the model: it owns the agent loop, model calls, tool routing, handoffs, approvals, tracing, recovery, and run state. Sandbox compute is the execution plane for files, commands, packages, storage, and related work. The harness can keep authentication, billing, audit logs, human review, and recovery state outside an individual execution container. See the sandbox and harness documentation.
This separation helps protect control-plane responsibilities from the environment in which model-directed work runs. It does not make authorization universal: the application still needs to identify every route by which a protected action can be requested and enforce policy at the right boundary.
Coverage varies by tool path
A policy layer is only as broad as the paths it actually covers. OpenAI’s SDK documentation says tool guardrails apply to function tools and appropriately configured local MCP tools, while handoffs use a different path. The documented guardrail pipeline excludes hosted MCP tools, other hosted tools, built-in computer, shell, and apply-patch tools, and direct agent-as-tool guardrail configuration. A system that relies on that pipeline must account for these exclusions rather than treating “guardrails enabled” as blanket coverage. Check the current coverage notes.
Rank #3
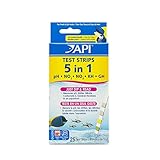
- Contains one (1) API 5-IN-1 TEST STRIPS Freshwater and Saltwater Aquarium Test Strips 25-Count Box
- Monitors levels of pH, nitrite, nitrate carbonate and general water hardness in freshwater and saltwater aquariums
- Dip test strips into aquarium water and check colors for fast and accurate results
- Helps prevent invisible water problems that can be harmful to fish and cause fish loss
- Use for weekly monitoring and when water or fish problems appear
Anthropic’s Managed Agents documentation makes a related distinction: permission policies can return allow, ask, or deny; an ask pauses for a user response, and a denial under automatic server-side evaluation cannot be overridden by a confirmation response. Custom tools are outside those managed policies, so the application must make the execution decision for them. See Anthropic’s Managed Agents documentation.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →These are product-specific coverage statements, not interchangeable guarantees. For each implementation, map custom tools, MCP servers, handoffs, hosted and built-in tools, shell or computer execution, and direct API routes to the component that authorizes them.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.A practical authorization review
For each action that can affect protected data or systems, document the answers to these questions:
- Decision location: Is the check in instructions, a tool wrapper, the harness, a gateway, or the target service?
- Timing: Does it run before the side effect, after the result, or as an asynchronous review interruption?
- Decision inputs: Does policy consider the tool, arguments, target resource, caller identity, and task or engagement scope?
- Coverage: Which custom functions, MCP servers, handoffs, hosted or built-in tools, shell or computer actions, and direct routes are included or excluded?
- Failure behavior: Does an unavailable reviewer fail closed, pause for human review, deny, or permit a constrained alternative?
- Evidence: Can an operator connect the call, policy outcome and reason, approver, execution result, and trace record?
Keep authentication and durable audit records in the control plane where practical, and make the target service or execution boundary enforce the authorization that protects the resource. Use traces to investigate and correlate; use a pre-execution policy decision to prevent an unauthorized side effect.
What the claim can—and cannot—establish
The architecture supports a careful conclusion: a recorded miss and a successful stop can reveal a gap between visibility and enforcement, but only the specific event record can establish what happened in a particular harness. The right scope for “the stop held” is the call that was pending and the boundary that stopped it. The right scope for “the harness lacks authorization” is the author’s own design and threat model—not every tool, route, or framework by implication.
OpenAI’s Agents SDK and sandbox guidance and Anthropic’s Managed Agents documentation were accessed on 2026-10-04 UTC. Their implementation details can change; consult the linked product documentation when applying them to a specific deployment.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




