Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Scan for outdated or missing drivers - takes under a minute3Clear out junk files and repair common Windows errorsThere is no universal millisecond value that makes a trading bot’s request latency “good.” Set an alert from the delay your strategy can tolerate, measure the relevant request span as a distribution, and require a deliberate amount of persistence before notifying anyone. Track errors, timeouts, traffic volume and venue rate limits alongside latency so an alert points toward a cause rather than just a symptom.
Define exactly what “request latency” measures
Before choosing a threshold, specify the start and end of the timed operation. For example, client-to-exchange request latency can run from the bot dispatching an order request until it receives the exchange response. That does not include the time an order waits in the bot’s internal queue before dispatch, nor does it necessarily measure when the order fills.
As an Amazon Associate I earn from qualifying purchases.
Keep distinct operations in distinct metrics when their deadlines differ. Order submissions, market-data polling, account reads and fill confirmation are not interchangeable. A proxy-to-backend measurement is different again: Google Cloud’s Apigee guidance treats target latency as excluding proxy overhead, so a target-latency alert alone does not represent the full client experience. Google Cloud Apigee cluster monitoring guidelines
Name the service-level indicator (SLI) in terms that make its scope testable, such as “order-submission requests receiving an exchange response within the objective.” Record useful bounded dimensions—venue, operation, endpoint class, deployment or region, and result class. Avoid per-order labels, which can create unbounded time series.
#1 Best Overall
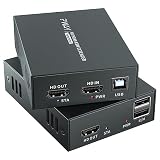
- 4K@60Hz Ultra HD HDMI KVM Extension: Extend HDMI video and USB control up to 196ft/60m over a Cat6/Cat7 Ethernet cable while supporting up to 4K@60Hz resolution. Ideal for long-distance display and computer control in offices, conference rooms, classrooms, control rooms, studios, and home theater systems.
- Wide Resolution & Audio Compatibility: Supports 4K@60Hz, 4K@30Hz, 1080p@24/25/30/50/60Hz, and other common HDMI formats for flexible use with different displays and source devices. Delivers clear video and stable audio pass-through for PCs, laptops, media players, DVRs, NVRs, projectors, and monitors.
- USB KVM Control for Keyboard & Mouse: This HDMI KVM extender transmits both HDMI signal and USB control through one Ethernet cable, allowing you to control a remote computer, DVR, NVR, media player, or laptop with a keyboard and mouse from the display side.
- HDMI Loop Out on Transmitter: The transmitter features an HDMI loop out port, so you can connect a local monitor near the source device while sending the same video signal to a remote display. Convenient for monitoring, presentations, security rooms, and dual-location viewing.
- POC Single Power & Stable Plug and Play Design: With POC technology, only one power adapter is needed to power the extender set, reducing cable clutter and making installation cleaner and easier. Built with a metal housing, EDID function, LED status indicators, and RJ45 UTP connection for stable long-distance transmission.
Choose a threshold from the strategy and healthy baseline
Start with the strategy’s tolerated delay and the venue’s documented constraints, then compare them with the latency distribution observed in the actual deployment under healthy conditions. The available published guidance does not establish a correct request-latency target for any particular strategy or exchange. Google’s Apigee guidance makes the same general point for its service: the alert threshold depends on the installation’s SLO.
Choose a tail statistic that reflects the share of requests you need to protect. A p95 threshold asks whether the slower tail is worsening while excluding the slowest five percent from that statistic; p99 focuses on the slowest one percent. Neither number is a complete SLO by itself. If the objective is that a specified fraction of requests complete within a limit, measure that fraction directly rather than relying only on an estimated percentile.
Rank #2

- 【4K VIDEO + REMOTE USB CONTROL OVER 120M】Extend UHD HDMI video and USB 2.0 signals up to 120m/394ft through a single Cat 5e or higher cable. Connect a remote keyboard, mouse, flash drive, or other USB device to interact with the computer from another location with real-time response.
- 【KVM EXTENSION OVER YOUR EXISTING IP NETWORK】 Leverage your current Ethernet infrastructure—no dedicated KVM cabling, no costly rewiring. Deploy remote keyboard, mouse, and peripheral control anywhere there's a network connection, reducing installation costs, shortening deployment time, and making post-installation upgrades simple and scalable. Perfect for server rooms, control centers, and distributed workstations.
- 【GO BEYOND BASIC POINT-TO-POINT EXTENSION】Unlike basic video-only extenders, this IP-based design carries video plus USB interaction and can work either as a direct connection or through compatible Gigabit Ethernet switches. This provides more installation flexibility when equipment needs to be located farther apart.
- 【ZERO-LATENCY PERFORMANCE FOR REAL-TIME WORK】Designed for applications where timing matters, this solution provides zero-latency transmission for responsive remote computer control. Ideal for control rooms, server environments, professional AV installations, classrooms, and workstations where delayed interaction can disrupt the workflow.
- 【4K@30HZ 1080P@120HZ HIGH REFRESH RATE VIDEO WITH HDMI INPUT】Supports video resolutions up to 3840×2160@30Hz, 4096×2160@30Hz and 1080P@120Hz, along with common Full HD and VESA resolutions. HDCP 1.4 support helps maintain compatibility with protected content and connected HDMI equipment.
You can also define a separate severe threshold for delays likely to make an order stale or miss an execution opportunity. Set that level from the strategy’s actual deadline; do not infer it from examples published for unrelated API services.
Recommended Free Tools
Measure the latency distribution, not just the average
A mean can conceal a small but consequential set of very slow requests. Instrument a histogram or equivalent distribution metric, and inspect p50, p95 and p99 alongside request counts. Prometheus client documentation describes histograms as recording observations into configurable buckets, with bucket counts, a sum and a total count. Prometheus Python client: Histograms
Rank #3

- Equipped with two sets of (DP + DP + USB-B) Input ports and two DP Output ports to enabling extended dual-monitor display across two connected PCs
- Experience dual 8K@60 vision with DP1.4, enhanced by TESmart's pioneering EDID emulation technology. Enhanced with four technologies: G-Sync, FreeSync, FEC, and DSC
- Resolutions up to 8K (4320p)@60Hz: Resolutions up to 8K@60Hz are supported. It is backward compatible with 4K (2160p)@60Hz/120Hz/144Hz. DSC technology allows the transmission of 7680x4320@60Hz 4:4:4 and 3840x2160@144Hz resolutions
- EDID Emulators: With EDID emulators in each input port, your computers always receive the correct display information. Free you from the hassle of constantly adjusting display settings
- Ideal KVM for Gaming: Supports Dynamic HDR, including HDMI Dynamic HDR metadata, HDR10+, and Dolby Vision, providing higher dynamic range and color accuracy for more realistic display effects. It also supports Variable Refresh Rate (VRR), Fast Vactive (FVA), and Auto Low Latency Mode (ALLM), reducing screen tearing, stuttering, and input lag for a smoother experience
Set bucket boundaries finely enough around the objective and alert limits to answer the question you care about. If your objective is 200 ms but the histogram has no useful resolution near 200 ms, the resulting measurement cannot distinguish performance around that boundary precisely. For an SLO expressed as a fraction of requests within a latency limit, calculate the good-request share from the relevant bucket and confirm how your monitoring backend handles histogram semantics.
Make persistence, severity and recovery explicit
Brief spikes can come from an isolated request or measurement fluctuation. Use a pending duration long enough to avoid paging on noise, but no longer than the strategy can safely tolerate degraded execution. Set the evaluation interval, persistence requirement, notification severity and recovery rule intentionally.
Rank #4

- Dual Band WiFi: 2.4GHz (2400 - 2485 MHz),5GHz/5.8GHz (5150 - 5850 MHz); Gain: 3dBi; Direction: Omni-directional; Antenna Connector: RP-SMA Male Connector;
- Package: 2 x WiFi Bluetooth Antennas;
- Compatible with: Wireless Network Router, WiFi AP Hotspot Modem, WiFi USB Adapter, Desktop PC Wireless Mini PCI Express PCIE Network Card Adapter;
- Compatible with: WiFi IP Security Camera; Wireless Video Surveillance DVR Recorder; Truck RV Van Trail Rear View Camera, Reverse Camera, Backup Camera, Industrial Router IoT Gateway Modem, M2M Terminal, Remote Monitoring and Control, Wireless Video, Wireless Extender;
- Compatible with: Furrion vision s backup camera, 5GHz 5.8GHz FPV Camera Monitor, FPV Drone Racing Quadcopeter Controller; 5GHz 5.8GHz Wireless AV Video Audio Receiver Extender;
Published cloud settings are examples of alert mechanics, not trading-bot recommendations:
| Example | Metric and condition | Evaluation and recovery | Scope |
|---|---|---|---|
| Amazon CloudWatch | p90 API Gateway latency above 2500 ms | 60-second evaluation interval; 300-second pending period and 300-second recovery period | AWS recommended alarm for API Gateway stages; not a bot benchmark. AWS recommended PromQL alarms |
| Google Cloud Apigee | p99 proxy latency at five seconds | Sustained for five minutes | Production example in the Apigee hybrid v1.16 guide; the guide says the threshold depends on the installation SLO. Google Cloud Apigee cluster monitoring guidelines |
| TierZero.dev | p95 fill latency at 1.5 seconds | Sustained for two minutes | Third-party Solana bot example; it measures fill latency, not necessarily client-to-exchange request response. TierZero.dev monitoring example |
One practical design is a warning for a persistent breach of the ordinary tail objective and a more urgent alert when severe latency threatens the strategy’s deadline or occurs with errors and timeouts. Choose whether each condition creates a dashboard notice, ticket, page or safety action according to operational impact. Test any automated response; latency alone does not establish that stopping trading is safe.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Pair latency with traffic, errors and rate-limit signals
Latency without context is hard to interpret. Keep request volume, timeout and error ratios, connection and retry behavior, and venue rate-limit responses visible beside the latency series. When there is no traffic, a percentile may be unavailable or meaningless; handle low-volume periods explicitly and use a separate liveness or expected-traffic signal if needed.
For Binance Spot, route weights vary, and the /api/v3/exchangeInfo response exposes RAW_REQUESTS, REQUEST_WEIGHT and ORDERS limits. A 429 response means a request-rate limit was exceeded; clients should back off, and the Retry-After header gives a wait duration. Repeated violations can lead to an IP ban. Binance.US also documents IP-based limits and automated 418 bans for repeated violations or failure to back off. These behaviors are venue-specific and may change, so check the current documentation for the venue you use. Binance Spot REST API information · Binance.US API documentation
Quick Recap
A practical setup sequence
- Separate the operations: define the timed span for each request class, including its start and end events; keep queue delay and fill confirmation separate from exchange response time.
- Set the objective: use the strategy’s tolerated delay, venue constraints and healthy deployment baseline to choose a latency limit and tail statistic.
- Instrument the tail: record a histogram or equivalent distribution, with buckets around the objective and alert limits; include request counts so low-volume periods are identifiable.
- Configure alert behavior: define evaluation interval, pending duration, severity and recovery condition based on the strategy’s tolerance for degraded execution.
- Add diagnostic signals: show errors, timeouts, retries, request volume and rate-limit responses alongside latency, and decide what each alert should trigger.
- Validate against real operating conditions: confirm that the measured span, labels, bucket resolution and low-traffic behavior match the intended alert before relying on it for intervention.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




