Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchWindows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallChoose audio settings for the specific voice-AI endpoint and task—not by picking a supposedly universal “best” rate. Check whether the endpoint expects speech-recognition input, text-to-speech output, telephony audio, or a live stream, then match its required container, encoding, sample rate, channels, and framing. For recognition input you control, preserve a lossless source such as FLAC or LINEAR16 when supported; convert only when the receiving system requires it.
Start with the job the audio must do
Audio settings for speech recognition are not automatically right for text-to-speech or realtime voice. First identify the pipeline stage and the exact API, model, and request type. Then use that endpoint’s current documentation as the compatibility contract.
As an Amazon Associate I earn from qualifying purchases.
- Speech recognition: Match an accepted input encoding and rate. If you control the original recording and the endpoint supports it, Google recommends FLAC or LINEAR16 rather than lossy encoding because lossy compression can affect recognition. This is Google’s guidance, not a guarantee about every provider or model. Google Cloud Speech-to-Text encoding guide.
- Text-to-speech: Check the output formats and rates for the particular TTS API and model. Output support does not establish what a speech-recognition endpoint accepts.
- Realtime or telephony: Check whether audio is exchanged as a complete file or as framed stream chunks, and whether the endpoint imposes codec or rate constraints.
Understand what “WAV” and “sample rate” tell you
WAV is a container, not a complete audio specification
A WAV file wraps audio data and metadata; its extension alone does not tell you the encoding, bit depth, channel count, or sample rate. A WAV may carry LINEAR16 or another encoding, so verify its header and contents rather than trusting the filename. Google Cloud documents that it can infer encoding and sample rate from WAV or FLAC headers when those values are omitted, and its guide describes WAV with LINEAR16 or μ-law. Google Cloud Speech-to-Text encoding guide.
FLAC is a lossless audio format. LINEAR16 is a linear PCM encoding commonly carried in WAV. Neither label removes the need to check whether the endpoint accepts the representation you are sending.
#1 Best Overall
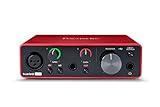
- Pro performance with great pre-amps - Achieve a brighter recording thanks to the high performing mic pre-amps of the Scarlett 3rd Gen. A switchable Air mode will add extra clarity to your acoustic instruments when recording with your Solo 3rd Gen
- Get the perfect guitar and vocal take with - With two high-headroom instrument inputs to plug in your guitar or bass so that they shine through. Capture your voice and instruments without any unwanted clipping or distortion thanks to our Gain Halos
- Studio quality recording for your music & podcasts - Achieve pro sounding recordings with Scarlett 3rd Gen’s high-performance converters enabling you to record and mix at up to 24-bit/192kHz. Your recordings will retain all of their sonic qualities
- Low-noise for crystal clear listening - 2 low-noise balanced outputs provide clean audio playback with 3rd Gen. Hear all the nuances of your tracks or music from Spotify, Apple & Amazon Music. Plug-in headphones for private listening in high-fidelity
- Everything in the box: Includes Pro Tools Intro+, Ableton Live Lite, Cubase LE, and Hitmaker Expansion: a suite of essential effects, powerful software instruments, and easy-to-use mastering tools
Sample rate is a requirement, not a quality ranking
Sample rate describes how many audio samples are represented per second. A higher number is not automatically better for a given voice-AI task: the receiving model may require or produce a particular rate, and the encoding can have its own constraints. Google Cloud’s guide, for example, lists AMR at 8 kHz, AMR-WB at 16 kHz, and Opus at 8, 12, 16, 24, or 48 kHz. Follow the documented combination for the selected endpoint and codec rather than applying 16 kHz, 24 kHz, or 44.1 kHz as a blanket rule. Google Cloud Speech-to-Text encoding guide.
Compare formats by endpoint behavior
| Choice | What to verify | Practical guidance |
| Container and encoding | Whether the API expects WAV/FLAC or raw audio, and which codec or PCM representation it accepts | A file extension is not enough; match the actual encoded data and any header metadata. |
| Lossless or lossy | Whether the source is under your control and the endpoint accepts a lossless option | For recognition, Google advises FLAC or LINEAR16 when possible; do not generalize that advice into a universal accuracy guarantee. |
| Sample rate | The selected model’s accepted or produced rate and any codec-specific limits | Use the documented rate. Resample only when a downstream component requires a different one. |
| File or stream | Whether data includes a file header or arrives in chunks | Preserve the expected framing; raw stream chunks are not interchangeable with a complete WAV file. |
| Channels and bit depth | Accepted channel count and sample representation | Confirm both in the endpoint documentation and the actual audio data. |
Provider examples: the same settings do not apply everywhere
OpenAI speech output
The cited OpenAI audio API reference lists MP3, Opus, AAC, FLAC, WAV, and PCM for speech output, with MP3 as the default. That list describes the cited output endpoint; it does not establish which formats every OpenAI audio input endpoint accepts. Check the reference for the specific endpoint you are using. OpenAI API Reference: Audio.
Rank #2

- The new generation of the songwriter's interface: Plug in your mic and guitar and let Scarlett Solo 4th Gen bring big studio sound to wherever you make music
- Studio-quality sound: With a huge 120dB dynamic range, the newest generation of Scarlett uses the same converters as Focusrite’s flagship interfaces, found in the world's biggest studios
- Find your signature sound: Scarlett 4th Gen's improved Air mode lifts vocals and guitars to the front of the mix, adding musical presence and rich harmonic drive to your recordings
- All you need to record, mix and master your music: Includes industry-leading recording software and a full collection of record-making plugins
- Everything in the box: Includes Pro Tools Intro+, Ableton Live Lite, Cubase LE, and Hitmaker Expansion: a suite of essential effects, powerful software instruments, and easy-to-use mastering tools
Google Gemini TTS
Google’s Gemini TTS documentation describes unary output as a complete WAV file: mono, 24 kHz, 16-bit signed little-endian PCM in a RIFF container. Its streaming output is headerless 24 kHz mono 16-bit PCM by default. Those are different representations even though their audio samples may otherwise correspond, so code that writes or combines streaming chunks must not treat them as complete WAV files without adding the appropriate file structure. The page also describes μ-law and A-law alternatives. Google AI for Developers: Gemini TTS.
Recommended Free Tools
Google Cloud Speech-to-Text
The encoding guide lists several recognition encodings, including LINEAR16, FLAC, MULAW, AMR, AMR-WB, OGG_OPUS, and WEBM_OPUS. Their supported rates differ; for instance, the guide lists AMR at 8 kHz, AMR-WB at 16 kHz, and Opus at 8, 12, 16, 24, or 48 kHz. WAV and FLAC headers can provide encoding and rate information. Treat these as Google Cloud Speech-to-Text specifications, not cross-provider rules. Google Cloud Speech-to-Text encoding guide.
Rank #3
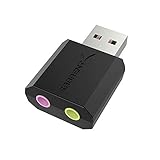
- PLUG IN AND HEAR SOUND IN SECONDS - USB Type-A connector with a 3.5mm stereo headphone output and a separate 3.5mm mono microphone input. No drivers, no software, no external power - the adapter is USB bus-powered and is recognized as a standard USB audio device.
- WORKS ON WINDOWS, MAC AND LINUX - Driverless on Windows 98SE/ME/2000/XP/Server 2003/Vista/7/8, Linux and Mac OSX, and compliant with the USB Audio Device Class 1.0 specification, so any system that supports class-compliant USB audio will see it. Select it as the sound output and input device after plugging it in.
- TWO JACKS, TWO JOBS - The green jack is stereo OUT for headphones or powered speakers; the pink jack is mono microphone IN for a 3.5mm mic. It does NOT support 4-pole headsets on a single combo plug, it does NOT power passive speakers, and it does NOT add surround sound - it is a stereo 2-channel adapter.
- FOR LAPTOPS AND DESKTOPS THAT NEED AN AUDIO PORT BACK - Adds a headphone and mic port to a laptop, desktop, or mini PC whose onboard jack has failed or was never there. Managed and work-issued computers can block new USB audio devices by policy - check with your IT department before ordering for a company machine.
- SABRENT SUPPORT AND WARRANTY - What is in the box: one USB audio sound adapter. Backed by a 1-year limited warranty, extended to 2 years when you register within 90 days on the manufacturer's website.
Google Cloud Gemini TTS on Agent Platform
The cited Google Cloud documentation describes WAV/linear PCM at 24 kHz and μ-law/A-law at 8 kHz for the documented Gemini 3.8 TTS models. In that path, the sampleRate field is ignored; when a different rate is needed, Google advises client-side resampling. This is a model- and API-path-specific behavior, so verify it for the model and interface you select. Google Cloud Gemini TTS overview.
Quick Recap
Best Value
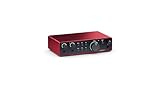
- The new generation of the artist's interface: Connect your mic to Scarlett's 4th Gen mic pres. Plug in your guitar. Fire up the included software. Start making your first big hit
- Studio-quality sound: With a huge 120dB dynamic range, the newest generation of Scarlett uses the same converters as Focusrite’s flagship interfaces, found in the world's biggest studios
- Never lose a great take: Scarlett 4th Gen's Auto Gain sets the perfect level for your mic or guitar, and Clip Safe prevents clipping, so you can focus on the music
- Find your signature sound: Air mode lifts vocals and guitars to the front of the mix, adding musical presence and rich harmonic drive to your recordings
- With Scarlett 4th Gen, you have all you need to record, mix and master your music: Includes industry-leading recording software and a full collection of record-making plugins
Rank #4

- Podcast, Record, Live Stream, This Portable Audio Interface Covers it All - USB sound card for Mac or PC delivers 48kHz audio resolution for pristine recording every time
- Be ready for anything with this versatile M-AUDIO interface - Record guitar, vocals or line input signals with two combo XLR / Line / Instrument Inputs with phantom power
- Everything you Demand from an Audio Interface for Fuss-Free Monitoring - 1/4" headphone output and stereo 1/4" outputs for total monitoring flexibility; USB/Direct switch for zero latency monitoring
- Get the best out of your Microphones - M-Track Duo’s transparent Crystal Preamps guarantee optimal sound from all your microphones including condenser mics
- The MPC Production Experience - Includes MPC Beats Software complete with the essential production tools from Akai Professional
Convert only when the receiving pipeline requires it
- Inspect the target requirements. Record the accepted container or raw representation, encoding, sample rate, channels, bit depth, and whether the request is a complete file or streaming data.
- Inspect the source audio. Check the real encoding and metadata rather than relying on its extension. If a WAV or FLAC header is present, ensure it accurately describes the audio.
- Keep a lossless source for recognition when practical. If the endpoint accepts it, use the original lossless audio or a lossless representation instead of introducing a lossy conversion first.
- Make one deliberate conversion. Resampling changes the sample rate; transcoding changes the encoding or container. Avoid unnecessary conversion chains that can discard information. If the needed rate differs from a TTS service’s fixed output rate, resample on the client where the provider’s documentation calls for it.
- Validate the actual request. Confirm that declared sample rate matches the samples, the channel count and encoding are accepted, and stream chunks have the framing expected by the endpoint.
Common mistakes to avoid
- Choosing 16 kHz or 24 kHz by habit: Neither rate is universally right. The endpoint, model, and encoding determine the compatible choice.
- Calling every WAV “lossless”: WAV is a container; check the encoding it contains.
- Assuming upsampling restores detail: Increasing a file’s sample rate does not recreate frequencies or audio information that were absent from the source.
- Using a TTS output list as an input-format list: Capabilities are endpoint-specific.
- Assuming a rate parameter is honored: Google’s cited Agent Platform Gemini TTS path ignores
sampleRatefor the documented models and formats. - Wrapping raw stream chunks as if they were a full file: Headerless PCM does not include the RIFF header required for a conventional WAV file.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




