Use one Playwright page in a loop: navigate to each URL, then save a screenshot to a unique filename. This example writes full-page PNGs sequentially, logs each HTTP status, and continues if one URL fails. It assumes PNG screenshots; use a different workflow if you need PDFs or saved HTML.
Capture each URL into its own screenshot
Install the playwright package and make sure the browser engine is available in your project. The example uses Node.js ES modules and Chromium. Save it as capture-batch.mjs, then run it with Node.js.
| # | Preview | Product | Price | |
|---|---|---|---|---|
| 1 |
|
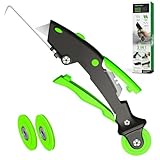
King&Charles Versatile Screen Roller Tool, 3pcs Different Roller+Hook+Trim | $12.99 | Buy on Amazon |
As an Amazon Associate I earn from qualifying purchases.
import { chromium } from 'playwright';
import { mkdir } from 'node:fs/promises';

const urls = [
  'https://example.com',
  'https://playwright.dev',
];
const outputDir = 'captures';

await mkdir(outputDir, { recursive: true });
const browser = await chromium.launch();

try {
  const context = await browser.newContext();
  const page = await context.newPage();

  for (const [index, url] of urls.entries()) {
    const filename = `${outputDir}/page-${String(index + 1).padStart(3, '0')}.png`;

    try {
      const response = await page.goto(url, {
        waitUntil: 'domcontentloaded',
        timeout: 30_000,
      });
      const status = response?.status();

      // Treat HTTP error responses as failed captures; remove this check
      // if you also want screenshots of error pages.
      if (status !== undefined && status >= 400) {
        console.error(`HTTP ${status}: ${url}`);
        continue;
      }

      await page.screenshot({ path: filename, fullPage: true });
      console.log(`${status ?? 'no main response'} ${url} -> ${filename}`);
    } catch (error) {
      console.error(`Failed: ${url}: ${error.message}`);
    }
  }
} finally {
  await browser.close();
}
The index makes every output path distinct, even if the input contains the same URL more than once or different URLs that would produce the same sanitized label. The files are named page-001.png, page-002.png, and so on in the captures directory. They are full-page captures; set fullPage: false for the viewport instead. See the Playwright Page API for the installed version’s available screenshot options.
Choose how the batch handles navigation and HTTP responses
Readiness is a trade-off
waitUntil: 'domcontentloaded' waits for the document to be parsed, but it may be too early for a site that renders important content afterward in client-side JavaScript. In that case, wait for an application-specific selector before taking the screenshot, for example with await page.locator('main').waitFor(). Playwright also supports load and commit navigation conditions. Its documentation discourages networkidle for testing and defines it as at least 500 ms without network connections; analytics and other persistent requests can make it an unreliable readiness signal. See the Page API.
#1 Best Overall
- --- 𝐏𝐀𝐓𝐄𝐍𝐓 𝐀𝐏𝐏𝐋𝐈𝐄𝐃 𝐅𝐎𝐑---
- 🏡【𝐊𝐢𝐧𝐠&𝐂𝐡𝐚𝐫𝐥𝐞𝐬 𝐑&𝐃 𝐈𝐧𝐭𝐞𝐧𝐭𝐢𝐨𝐧】Versatile Screen Tool - combines the core functions of multi-size roller, hidden hooks, and replaceable blades, and designed this multifunctional screen tool. It solves the problems of traditional screen installation tools with single functions, lack of safety and adaptability. It truly realizes multiple uses of one tool, making screen replacement time-saving, labor-saving, and worry-free. One-time purchase can meet your installation or replacement needs.
- 🏡【𝟑 𝐒𝐢𝐳𝐞𝐬 𝐈𝐧𝐭𝐞𝐫𝐜𝐡𝐚𝐧𝐠𝐞𝐚𝐛𝐥𝐞 𝐑𝐨𝐥𝐥𝐞𝐫𝐬】Flexible Adaptation - In view of the differences in thickness of different window splines, we gift the roller into three specifications: Convex 0.13", Concave 0.13", and Concave 0.18", ensuring perfect matching with the mainstream rubber strip sizes on the market. Feature①: The roller is made of high-hardness plastic, which is strong and durable while avoiding the risk of traditional metal rollers scratching the screen mesh. Feature②: Metal bearing design - smoother rotation, even pressure without deviation. TIPS: you can use the provided Allen wrench to quickly disassemble and replace them.
- 🏡【𝐁𝐥𝐚𝐝𝐞 𝐅𝐮𝐧𝐜𝐭𝐢𝐨𝐧-𝐑𝐞𝐭𝐫𝐚𝐜𝐭𝐚𝐛𝐥𝐞&𝐒𝐭𝐨𝐫𝐚𝐠𝐞&𝐑𝐞𝐩𝐥𝐚𝐜𝐞𝐚𝐛𝐥𝐞】①Retractable-When in use, just hold button, blade will slow rollout, convenient trimming and cutting. Blade can be retracted to prevent Accident scratches. ②Blade has double locking device: it automatically locks to prevent retraction during work and is completely closed to prevent accidental touch when retracted. Ansure your safety. ③Replaceable - A separate button is provided for changing the blades. ④Blade is made of steel-sharp, durable and won't rust. ⑤Storage-Handle has built-in blade storage design to place complimentary blade.Extra equipped 2xreplacement blades- increase service life of tool.
- 🏡【𝐇𝐢𝐝𝐞𝐚𝐛𝐥𝐞 𝐑𝐞𝐦𝐨𝐯𝐚𝐥 𝐇𝐨𝐨𝐤】The hooks are sharp and can hook out the aged spline. The removal hook can be stored and hidden in the handle slot box. OPEN the box cover, take out the hook and insert it into the groove for use. can RETRACT after use to prevent the hook tip from scratching clothes or tool boxes. Hook made of Stainless steel material won't rust.
Navigation success is not the same as an HTTP success
A 404 or 500 response is a valid HTTP response, so page.goto() does not necessarily throw. The script checks the returned response status and skips saving pages with status 400 or higher. Remove that check if you want to save screenshots of error pages. A missing response is logged as no main response; it is not treated as a confirmed successful HTTP status.
Keep a failed URL from stopping the batch
The per-URL try/catch logs navigation or screenshot errors and proceeds to the next item. The outer finally closes Chromium even if the batch encounters an error. The example does not retry failures; add a retry policy only if it fits the sites you are capturing, since repeated requests can have side effects or encounter rate limits.
Reuse a page, open multiple pages, or isolate browser state
For serial captures, reusing one page is straightforward and avoids creating a new tab for each URL. A browser context can also contain multiple pages; the Playwright Pages guide states, “Each BrowserContext can have multiple pages.” Use multiple pages when your workflow needs several tabs at once, rather than merely to save files one by one. See the Pages guide.
Pages in a context share that context’s browser configuration and session state. If captures should not inherit cookies or other browser state from another task, create a fresh non-persistent context for the job. Playwright describes non-persistent contexts as independent browser sessions that do not write browsing data to disk. See the BrowserContext API and Browser contexts guide.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Other output formats and useful adjustments
- Viewport PNG: set
fullPage: falseor omit the option. - Full-page PNG: use
fullPage: true, as in the example. It captures beyond the current viewport, though content loaded only after scrolling may need additional page-specific handling. - PDF: use Playwright’s separate PDF capability rather than
page.screenshot(). PDF support and options are documented in the Page API. - HTML: saving rendered page markup is a different output from a screenshot; the code above deliberately does not create HTML snapshots.
Troubleshoot common batch failures
- Invalid URL, SSL error, timeout, unreachable server, or failed main-resource load: Playwright can throw during navigation. Check the URL and network access, adjust the timeout for slow sites where appropriate, and let the per-URL handler record the failure.
- HTTP 404 or 500 but no thrown error: inspect
response.status(). Decide whether to skip those captures, as this script does, or save the error page for diagnosis. - Screenshot misses content:
domcontentloadedmay precede client rendering. Wait for a selector or other application-specific readiness signal before callingpage.screenshot(). - Files overwrite each other: do not form paths from raw, untrusted URLs. Use an index or a carefully sanitized label; the indexed filenames above remain unique for duplicates.
- Later pages inherit earlier session state: create and close a separate browser context for each capture job that requires isolated cookies or local state.
Or skip the browser setup
If you want an API call instead of managing Playwright and Chromium, ScreenshotNeo takes a screenshot from a URL. Its API can return PNG, JPEG, WebP, or PDF. For example, this cURL call saves a WebP response:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webpSee the ScreenshotNeo API documentation for setup and options. It accepts cookie banners before capture and removes 60+ known consent platforms, newsletter popups, and chat widgets; each step can be turned off. Bot checks, blank pages, timeouts, failed loads, and cache hits are not billed, and responses identify the page verdict and billing status in headers. Its MCP server offers take_screenshot, get_page_info, and capture_pdf for AI agents. The Free plan includes 1,000 shots per month with no card; paid plans start at $5 for 3,000 shots.
Sign up for ScreenshotNeo’s free plan: 1,000 screenshots a month, no card required.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Repair Windows errors before they cause bigger problems3Scan for outdated or missing drivers - takes under a minuteFrequently Asked Questions
Does this batch script capture PDFs or HTML files?
No. It writes full-page PNG screenshots. PDF output and saved HTML require different Playwright operations.
Can the script capture the same URL more than once?
Yes. Each input entry gets a different indexed filename, so duplicate URLs do not overwrite each other.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




