Recommended Free Tools
If one homelab host failed tonight, could the services you care about restart on the survivors? The answer depends on more than node count: eligible hosts need enough usable CPU and memory, access to the workloads’ storage and required devices, and a network and cluster configuration that can complete recovery without losing quorum. Inventory the workloads, choose the failure you need to withstand, and test the recovery path before relying on it.
What “survives a node failure” actually means
A host failure can take its local disks, network interfaces, attached devices and every service concentrated on that machine with it. A surviving server with spare RAM does not help if it cannot reach a VM’s disk, access a required physical device, or participate in the cluster’s recovery rules. Nor does a cluster with enough total resources necessarily have enough capacity in the nodes eligible to restart a particular workload.
As an Amazon Associate I earn from qualifying purchases.
Separate three outcomes when planning:
- Hypervisor recovery: a VM or container can be started or relocated on a surviving host.
- Application availability: the application remains usable, perhaps through its own replicas or failover, rather than waiting for a guest to restart.
- Data availability: the application can still reach consistent, usable data on storage that remains accessible during the failure and recovery.
These are related but not interchangeable. Proxmox VE HA policies govern resource recovery and relocation; they do not establish a universal restart time for a given homelab. A Kubernetes high-availability control plane likewise does not, by itself, ensure worker capacity, application replicas, persistent storage, or application data will survive a host failure.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Choose the failure you want to withstand
Start by naming a single failure scenario. “One node dies” could mean a hypervisor loses power, but the practical consequences may include losing its local storage, network path, or attached hardware. A failed storage device, network link, or power domain is a different scenario and needs its own check.
#1 Best Overall

- 【DeskPi RackMate T2】It's made of aluminum alloy and acrylic frame mini chassis which you can setup your own cluster or home assistant server. For 10 inch 4U Server Cabinet (DeskPi RackMate T0), please refer to ASIN B0DPGZPTPP . For 10 inch 8U Server Cabinet (DeskPi RackMate T1), please refer to ASIN B0CSCWVTQ7 . NOTE: the rack is designed for 10-inch form factors and is not compatible with standard 19-inch enterprise equipment.
- 【10-inch width】The cabinet has a width of 10 inches, which is a relatively small size that saves space while accommodating sufficient equipment. With dimensions of 11.02x10.23x23.22 inches, it is suitable for small offices, home environments, and large enterprises looking to save space.
- 【Open Design】The cabinet adopts an open design, allowing easy access to all devices inside. This design facilitates equipment installation and maintenance, aids in device cooling, and maintains optimal working conditions.
- 【12U Standard】The cabinet has a height of 12U, which is a standard unit size. With 1U equaling 1.75 inches, 12U implies a height of 21 inches.
- 【Translucent Design】Both sides are made of translucent acrylic, providing dust resistance and reduced weight. This design allows direct observation of the cabinet's interior, and users can add ambient lights for decoration.
Do not count two paths as independent redundancy if they depend on the same underlying component. For example, two services on separate guests are not protected from a host failure if both guests reside on that host. Write down what fails together, then assess the surviving nodes and paths that remain.
Inventory services and their dependencies
Make a list of every VM, container and Kubernetes workload. Classify each as essential (must return), useful (should return if capacity permits), or safe to leave down until the failed node is repaired. This prevents an optional workload from consuming capacity needed by a critical service during a constrained recovery.
For each workload, record configured and observed resource use, storage location, network needs, and hardware dependencies. A configured CPU or memory allocation is useful for identifying what a host may need to provide, but ordinary idle-time snapshots alone do not describe demand during an outage, when other workloads may be busy and storage may be recovering.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteRank #2

- 【Powerful Load-bearing】12U Network Rack Open Frame is constructed from durable cold rolled steel; Rack shelf supports enhance stability, wall-mounted capacity of 130lbs, the ground-mounted up to 260lbs
- 【Considerate Designs】Open-frame layout, including a top panel adding space, anti-slip shelf stops fixing devices and compatible racks for stack and expansion to meet requirements of home server rack
- 【Complete Accessories】A 12U open frame server rack, two ventilated shelves, four shelf stops, four velcro straps and a set of equipment mounting screws
- 【Versatile Application】Ideal for space-efficient multi-device setups in warehouses, retail, classrooms, offices and more; Excellent choices as AV Rack/IT Rack
- 【Effortless Setup】 Network Rack includes hardware, a comprehensive manual, mounting hole drilling template and an online assembly video to simplify setup
- CPU: configured allocation and observed demand during representative busy periods.
- Memory: configured guest memory and actual use, plus resources reserved for the host and storage services.
- Storage: where the guest disk or persistent volume lives, which nodes can access it, and whether it can serve reads and writes during recovery.
- Network: required paths and bandwidth, including whether recovery traffic shares a link with cluster communication.
- Dependencies: physical devices, local-only disks, network paths, or services that exist on only one host.
Mark any dependency that cannot move with the workload. Free CPU and RAM cannot compensate for an inaccessible disk or a device attached only to the failed host.
Calculate capacity for each survivor scenario
For each possible failed host, add up the essential workloads that must run on the remaining eligible nodes. Then compare their combined demand with usable capacity on those nodes after reserving resources for the hypervisor and storage system. Repeat the exercise for useful workloads if you want to know what can return after essentials.
- Remove the failed node from the capacity picture. Count only resources and storage paths that remain available in that scenario.
- Assign essential workloads to eligible survivors. Respect device, network, storage and placement constraints; do not assume every workload can start anywhere.
- Compare demand with usable capacity. Include the host and storage system’s own needs, not just guest allocations.
- Account for recovery load. Storage recovery and rebalancing can consume memory, CPU, disk performance and network bandwidth at the same time workloads are returning.
- Repeat for every single-node failure you intend to tolerate. One host may have more eligible destinations or spare capacity than another.
Proxmox VE’s published system requirements give a general baseline of 2 GB for the operating system and Proxmox services, in addition to guest memory. They also recommend about 1 GB per TB of used storage additionally for Ceph and ZFS. These are general published requirements, not a sizing guarantee for a particular guest mix or recovery event; actual OSD count, guest behavior and recovery load matter. See Proxmox VE System Requirements.
Rank #3

- WALL-MOUNT SERVER CABINET FOR IT & AV SETUPS – Designed for home labs, office IT networks, AV systems and security installations while helping maximize usable floor space in compact environments.
- 24-INCH DEEP NETWORK RACK – 24-Inch overall depth and 20-Inch usable mounting depth help buyers confirm fit for switches, routers, patch panels, NAS systems, PoE devices and AV components in structured cabling and office IT setups.
- HEAVY-DUTY WALL-MOUNT LOAD CAPACITY – Supports up to 133 lbs (60 kg) of installed equipment when securely mounted to a solid wall structure, helping protect network, AV, security and IT hardware in compact installations.
- LOCKING GLASS DOOR & VENTILATED ACCESS – Tempered glass front door with perforation pattern and removable side panels provide controlled access, equipment visibility and airflow support for enclosed 18U rack setups.
- ACTIVE COOLING & COMPLETE INSTALLATION KIT – Integrated top fan supports active ventilation and heat removal. Includes 2 fixed shelves, PDU, brush cable entry panels and complete mounting hardware for faster setup.
Do not turn a reassuring total across all nodes into a pass: the relevant question is whether enough usable capacity remains on eligible survivors in the specific failure scenario.
Free tools Windows power users keep installed
One-click scans. No signup required.
Check quorum and the recovery rules
For Proxmox VE HA, quorum and resource recovery rules are part of the capacity plan, not an administrative detail to check after a failure. Proxmox lists at least three cluster nodes for reliable quorum. That is guidance about quorum, not proof that a three-node cluster has enough CPU, memory or storage to run the failed node’s workloads. Consult the Proxmox VE Cluster Manager guidance and the Proxmox VE High Availability Manager rules for your configuration.
Understand what happens if no eligible node can start a resource, or a recovery attempt fails. Proxmox HA has start and relocation policies; a resource that cannot be recovered can enter an error state requiring administrator action. Record who will investigate and what manual recovery is safe rather than assuming HA will keep retrying until the service returns.
Rank #4
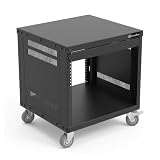
- 8U Universal 19-inch Equipment Rack Cabinet Case with Locking Wheels for AV, Networking, Computer Server, Home Theater Rackmount Gear
- Compatible with American 5mm and European 6mm rackmount standards. 5mm and 6mm Screws Packs are included.
- Open Front and Back,8U Rack Spacing Design with Protective-Vented Side Panels. Front and Real Rail Rack. No Door. Textured-Matte Black Finish. Holds AV/Networking Equipment up to 18-inches Deep.
- Front locking 3" Caster Wheels move easily on carpet. 1U Blank Panel is included. Dimensions Assembled: 20” x 18” x 20.5” with wheels. Weight Capacity is 330lbs with wheels and 440lbs without wheels.
- This Standard 19"8U Rack is Ideal for businesses, DJs, Sound Studios,home theaters with needs to organize Server/Network Equipment, Power Amplifiers, Microphones, DVD Players, Electronics etc. Compatible with ALL AxcessAbles rack drawers, shelves, rack accessories as well as all standard 19" rack accessories in the marketplace.
Verify storage can serve the survivors
Ask two separate questions: can an eligible recovery node access the workload’s disk or persistent volume, and can the storage system serve it while rebuilding or rebalancing? A storage design may preserve access yet perform poorly under recovery load, delaying service restoration or competing with other cluster traffic.
For Proxmox Ceph, the documentation says a hyper-converged setup should have at least three, preferably identical, servers. It notes that recovery can take a long time in small clusters and recommends SSDs in small setups to reduce recovery time. It also cautions that increasing OSD capacity can make one OSD failure trigger more recovery work. In its words: “More capacity allows you to increase storage density, but it also means that a single OSD failure forces Ceph to recover more data at once.” These are design considerations, not a promise about how long a particular pool will take to recover. See Proxmox VE Ceph.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Check the documented redundancy and failure behavior of the storage you actually use. Shared storage, distributed storage, and local disks with backups have different recovery paths; none should be treated as interchangeable merely because a guest can be restarted.
Best Value
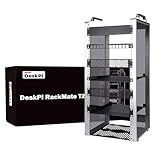
- 【DeskPi RackMate T2】It's made of aluminum alloy and acrylic frame mini chassis which you can setup your own cluster or home assistant server. For 10 inch 4U Server Cabinet (DeskPi RackMate T0), please refer to ASIN B0DPGZPTPP . For 10 inch 8U Server Cabinet (DeskPi RackMate T1), please refer to ASIN B0CSCWVTQ7 .
- 【10-inch width】The cabinet has a width of 10 inches, which is a relatively small size that saves space while accommodating sufficient equipment. With dimensions of 11.02x10.23x23.22 inches, it is suitable for small offices, home environments, and large enterprises looking to save space.
- 【Open Design】The cabinet adopts an open design, allowing easy access to all devices inside. This design facilitates equipment installation and maintenance, aids in device cooling, and maintains optimal working conditions.
- 【12U Standard】The cabinet has a height of 12U, which is a standard unit size. With 1U equaling 1.75 inches, 12U implies a height of 21 inches.
- 【Translucent Design】Both sides are made of translucent acrylic, providing dust resistance and reduced weight. This design allows direct observation of the cabinet's interior, and users can add ambient lights for decoration.
Protect cluster communication from recovery traffic
Corosync is time-sensitive, so cluster communication needs a reliable, low-latency path. Proxmox recommends physically separating Corosync traffic from other traffic. Its Ceph guidance recommends at least 10 Gbps dedicated for Ceph traffic, while noting that disk performance affects the bandwidth needed. If Ceph recovery shares a network with Corosync, the recovery traffic can interfere with the latency-sensitive cluster stack and risk quorum loss. See the cluster communication guidance and Ceph networking guidance.
If Corosync uses LACP, account for failover behavior as well. Proxmox documents a scenario in which default LACP timing can take 90 seconds to fail over; fast LACP settings on both sides can reduce that to 3 seconds. Those values describe the documented scenario, not a general measurement of every switch, link, or network configuration. Verify your own switch and host settings rather than assuming a bonded link is automatically fast enough.
Compare recovery approaches by what they protect
| Approach | What it addresses | What you still need to verify |
|---|---|---|
| Proxmox HA with shared or distributed storage | Hypervisor-level resource recovery, subject to cluster rules and eligible destinations. | Quorum, workload headroom on survivors, storage access and recovery performance, network isolation, and operational complexity. See HA Manager and Ceph guidance. |
| Kubernetes HA control plane | Control-plane availability. The kubeadm guide describes stacked control plane and etcd as using less infrastructure, while external etcd separates those roles and requires more infrastructure. | Worker capacity, application replicas, persistent storage and application data remain separate checks. A control plane alone does not make these survive a host failure. See the Kubernetes kubeadm HA guide. |
| Recovery from backups without HA | A path to restore service after a failure, rather than automatic continuation through hypervisor or application redundancy. | Whether the acceptable downtime and data-loss window can be met depends on the backup and restore design. Backup alone does not make a service highly available; no universal recovery objective follows from having backups. |
Choose based on the service’s consequence of downtime and the recovery path you can operate—not on the label “HA.” A control-plane design, hypervisor restart policy, and backup restore solve different parts of the problem.
Run a planned failure exercise
A capacity worksheet is a hypothesis until you test the actual failure path. Schedule a controlled exercise for a noncritical workload first, with a safe rollback plan. Avoid deliberately taking down production-critical services without understanding the consequences.
- Record the starting state: workload placement, resource demand, storage health, cluster membership and network configuration.
- Simulate or perform the chosen failure in a controlled window, following the platform’s safe procedure.
- Observe detection, eligibility and restart behavior, then note whether storage recovery or network contention changes the outcome.
- Measure elapsed time separately for failure detection, workload restart, storage recovery and user-visible service restoration. Do not substitute a platform setting or estimate for a measured result.
- Confirm data and application behavior after recovery, then document any manual action required, bottleneck found or workload left down.
Repeat after material changes to host resources, storage layout, network paths or workload placement. Your measured recovery times apply to the tested hardware and scenario; platform documentation does not establish the time your own setup will take.
Turn the result into a clear decision
For each essential service, record one outcome for the selected failure: returns automatically, returns only after manual action, or cannot return on the surviving infrastructure. Pair that outcome with the tested service-restoration time and any data or dependency limitation observed. If an essential workload cannot fit or cannot reach its data, either change the design, reduce what must return, or explicitly accept the downtime and recovery process.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




