Recommended Free Tools
GLM-5.3-Flash is a 320-billion-parameter, open-weight model with 18 billion parameters active per token—not an 18B model in total. NVIDIA lists its maximum context as 1,048,576 tokens, while Z.ai describes it as the first natively multimodal model in the GLM-5 series. Those headline figures describe different things: the parameter count is not a memory estimate, and the context maximum is not a guarantee that every hosting service or setup can use a full million tokens.
What do 320B total parameters and 18B active parameters mean?
Z.ai’s model card lists 320 billion total parameters and 18 billion active per token. GLM-5.3-Flash uses a mixture-of-experts design: the total figure describes the model’s parameters, while the active figure describes the portion engaged for processing a given token. Calling it simply an “18B model” leaves out most of its model weights and gives a misleading impression of its overall size. Z.ai’s model card also reports a 30-trillion-token multimodal pre-training corpus.


As an Amazon Associate I earn from qualifying purchases.
Active parameters are not a direct measure of the memory needed to load and serve the model. The weights, their precision or quantization, inference engine, context length, and serving setup all matter. NVIDIA documents its native FP8 endpoint running tensor-parallel across eight H100 GPUs; that is one specific hosted configuration, not a universal minimum for every local setup. NVIDIA’s model card identifies H100 hardware for its configuration.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Clear out junk files and repair common Windows errorsFree Scan →Can GLM-5.3-Flash really handle a million tokens?
NVIDIA lists a maximum context length of 1,048,576 tokens. Treat that as an advertised model-card maximum, not a promise that a particular API, interface, or local deployment accepts that much input or performs well across the entire window. A provider can impose a lower limit, and practical performance depends on the serving system and task.
#1 Best Overall

- [Local AI Inference & 70B Model Ready] Equipped with the AMD Ryzen 7 PRO 8845HS processor, NEXUS is engineered for heavy local AI workloads. With a full-size GPU bay, it runs 70B LLMs natively without an internet connection. Ideal for AI developers and tech enthusiasts who need private environment for coding and model testing.
- [132TB Mass Storage with ZFS Integrity] Features a hybrid storage architecture (3×NVMe + 4×3.5" HDD) supporting up to 132TB. Utilizing the enterprise-grade ZFS file system and ECC memory, it prevents data corruption and bit rot—a must-have for professional photographers and video editors safeguarding 4K/8K RAW footage.
- [OpenClaw-Driven Automation Workflow] The built-in OpenClaw execution layer allows complex automated tasks to be processed locally. Even when offline, your backup schedules and AI file organization continue seamlessly. Say goodbye to monthly cloud subscriptions and high latency.
- [Dual 10GbE & USB4 Ultra-Connectivity] Experience server-class speeds with dual 10GbE ports and a 40Gbps USB4 interface. It enables multi-user real-time collaboration on large project files directly from the NAS, ensuring zero-lag editing for creative studios and production teams.
- [Open-Source ZimaOS for Total Privacy] Running on the fully open-source ZimaOS, NEXUS ensures your data stays physically on-premise with no backdoors. It acts as a "Digital Fortress" for privacy-conscious families and small businesses who demand absolute data sovereignty.
The GLM-5 repository discusses a “solid 1M-token context” for GLM-5.2 and lists GLM-5.3-Flash among the current GLM-5 family. That family-level discussion provides context, but NVIDIA’s 1,048,576-token listing is the specific maximum documented for GLM-5.3-Flash here. See the GLM-5 repository.
Is it multimodal, and what can it process?
Z.ai calls GLM-5.3-Flash “the first natively multimodal model in the GLM-5 series.” NVIDIA explicitly lists text and image input with text output for its endpoint. Its described use cases include visual question answering, reasoning over multiple images, document and screenshot understanding, coding and tool-using agents, and long-context document work. NVIDIA’s endpoint accepts up to eight images per request; that limit applies to that endpoint and should not be assumed for other providers or self-hosted deployments.
NVIDIA also lists reasoning, function and tool calling, and multi-token prediction for speculative decoding. These are capabilities in its model-card description, not a guarantee that every serving framework exposes them in the same way.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Repair Windows errors before they cause bigger problems3Scan for outdated or missing drivers - takes under a minuteRank #2
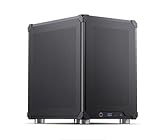
- Pre-Installed AI Models: High-performance local 14 billion parameter Large Language Model runs directly out of the box with multiple LLM models installed and ready to use
- Easy Model Management: One-click switching between different AI models and simple downloads of latest suitable models to stay current with AI development
- Advanced AI Features: RAG framework and Embedding Models come pre-installed, enabling immediate local document ingestion and vectorization for enhanced AI capabilities
- Compact Design: Mini ITX PC case featuring mesh panels on all sides for optimal airflow and cooling in a space-saving form factor
- Local Computing Power: Cost-effective personal AI server that processes everything locally, ensuring privacy and eliminating cloud dependency for AI workloads
How is the model designed for long context?
Z.ai says the model combines sparse attention with linear attention and uses Manifold-Constrained Hyper-Connections (mHC). The publisher attributes lower long-context serving costs and improved scaling efficiency to these choices. These are design goals and publisher claims, not independently established performance guarantees.
NVIDIA’s model card describes a 45-layer stack: 34 KDA linear-attention layers and 11 sparse-attention layers, with 288 routed experts per mixture-of-experts layer. It identifies top-8 routing. These are NVIDIA’s detailed model-card figures; they add architectural detail without changing the distinction between total and active parameters.
What hardware or software do you need to run it?
There is no single hardware requirement established for every local configuration. The model’s 320B total parameters, selected weight precision or quantization, inference engine, and requested context all affect memory and compute needs. NVIDIA’s eight-H100 endpoint setup illustrates an enterprise-scale native-FP8 serving route, not a consumer-PC recommendation or a proven minimum for every quantized deployment.
Rank #3
Z.ai lists SGLang, vLLM, TokenSpeed, Transformers, KTransformers, and Unsloth as serving routes. The model card includes an SGLang example and links to Docker Model Runner. Compatibility and configuration can change as model and framework versions evolve, so check the current model card and the chosen engine’s instructions before deployment. The model card and serving notes are here.
For configuration, the model’s notes say reasoning_effort accepts low, high, or max, with max as the default. They also advise explicitly passing clear_thinking=true in chat scenarios. Confirm these options against the current framework and model revision you use.
Should you use a hosted API or self-host the weights?
Both hosted access and self-hosting are available routes, but the right choice depends on whether operational control or convenience matters more. A hosted API avoids managing the serving infrastructure, while self-hosting gives you control over the deployment environment. The available model information does not establish comparable data-handling terms or live prices across providers, so check each service’s current policies and pricing directly.
Rank #4
- Check actual limits: Confirm the provider’s context window, image allowance, and support for tools or reasoning settings; do not assume advertised model capabilities are exposed unchanged.
- Estimate deployment resources: For self-hosting, verify memory and compute requirements for the chosen precision, quantization, engine, and context length.
- Compare current billing: Establish the price per billing unit and region for hosted service, or the infrastructure cost for a managed or self-hosted setup.
- Review data handling: Compare each service’s terms and controls for the data you intend to send.
What do the license and price claims establish?
NVIDIA’s model card says the model is ready for commercial use and that usage is governed by the MIT License. Its trial endpoint has separate NVIDIA API Trial Terms. A model license and a hosting service’s terms are distinct, so review both for the route you use. NVIDIA’s model card describes the license and endpoint terms.
Z.ai claims GLM-5.3-Flash costs roughly one-tenth as much as GLM-5.2. That is a relative comparison by the publisher; the available pricing information does not specify a comparable current price, billing unit, or regional rate. Check the current price table for the provider you plan to use before estimating costs.
What limitations should you account for?
NVIDIA warns that outputs can be inaccurate, biased, or objectionable, and that the model can make errors in multi-step reasoning. It also says image-understanding quality varies with image resolution and quality. For consequential workflows, test representative inputs and apply safeguards appropriate to the use case rather than treating the model’s capability labels as a reliability guarantee. NVIDIA’s limitations and safety notes provide further detail.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




