The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →To find image URLs reliably, collect the image declarations in the original HTML, then inspect the rendered page if JavaScript or scrolling reveals more. Record each URL with its element and source attribute: an img can have a fallback src, multiple srcset candidates, and responsive alternatives in picture and source. A browser may select only one of those candidates, so its choice is not the same as a complete inventory.
What “every image” means
A page can declare several possible URLs for one visual image. A useful extractor distinguishes a candidate inventory—URLs declared in markup—from the selected image the browser currently uses. It should also distinguish discovering a URL from deciding whether that image is a tracking pixel.
As an Amazon Associate I earn from qualifying purchases.
No single request or selector can guarantee every image a site might show. The methods below cover image URLs exposed in HTML and the rendered DOM; pages that depend on interaction or other rendering techniques may need site-specific handling.
Which image attributes and elements should you inspect?
img[src]is the image URL or fallback.img[srcset]can list alternative URLs with width (w) or pixel-density (x) descriptors. Preserve each candidate and its descriptor rather than treatingsrcas the only useful URL.pictureand its childsourceelements can declare additional responsive candidates. Inspect theirsrcsetand, where present,srcattributes.loadingindicates whether an image uses browser-level lazy loading. It does not reveal every site’s loading strategy.- Some sites put an eventual image URL in a custom
data-*attribute whilesrccontains a placeholder. Names such asdata-src,data-lazy-srcanddata-originalare observed conventions, not standardized or exhaustive names. Inspect the actual markup rather than assuming one attribute works everywhere.
Resolve relative URLs against the document’s base URL, including any base element in the HTML. Keep the original attribute value as well as the resolved URL so you can trace where a candidate came from.
#1 Best Overall

- USB-C 2-in-1 storage OTG: The Lexar JumpDrive Dual Drive D40E features USB Type-A and Type-C connectors in a slim, portable form factor for easy device compatibility
- Transfer speeds up to 100MB/s: Based on internal testing, performance may vary depending upon the host device, interface, and usage conditions. 1MB=1,000,000 bytes
- Plug and Play: Widely compatible with USB Type-C smartphones, tablets, laptops, Macs, and traditional Type-A devices, no software installation required. The 360° swivel design allows for easy switching between connectors without the hassle of losing a cap
- Durable & Compact: The Lexar D40E USB memory stick features a metal enclosure, withstands temperatures from 0° to 50° C (32°F to 122°F), and is lightweight at 26g with dimensions of 70.4 x 16.9 x 11.7mm
- Security & Warranty: Securely protects files using an advanced security software solution with 256-bit AES encryption. Backed by a Lexar 3-year limited warranty
How to inventory the initial HTML in Python
This dependency-free example fetches a page and records img and source declarations. It parses each srcset into URL-and-descriptor pairs, including URLs such as data URLs that contain a comma. It does not execute JavaScript or trigger scrolling, so it only finds declarations present in the response.
from html.parser import HTMLParser
from urllib.parse import urljoin, urlsplit, urlunsplit
from urllib.request import Request, urlopen

class ImageMarkup(HTMLParser):
    def __init__(self):
        super().__init__(convert_charrefs=True)
        self.base_href = None
        self.items = []

    def handle_starttag(self, tag, attrs):
        attrs = dict(attrs)
        if tag == "base" and attrs.get("href") and self.base_href is None:
            self.base_href = attrs["href"]
        if tag in ("img", "source"):
            self.items.append({"element": tag, "attributes": attrs})


def parse_srcset(value):
    """Return (URL, descriptor) pairs from a srcset attribute."""
    candidates = []
    i, n = 0, len(value)
    while i < n:
        # Skip spaces and separator commas before a candidate.
        while i < n and (value[i].isspace() or value[i] == ","):
            i += 1
        if i >= n:
            break

        # A URL token runs to whitespace. Commas inside a data URL stay intact.
        start = i
        while i < n and not value[i].isspace():
            i += 1
        url = value[start:i]

        # A trailing comma ends a candidate with no descriptor.
        if url.endswith(","):
            url = url.rstrip(",")
            if url:
                candidates.append((url, ""))
            continue

        # Read a descriptor, if present, up to the next candidate separator.
        while i < n and value[i].isspace():
            i += 1
        start = i
        while i < n and value[i] != ",":
            i += 1
        descriptor = value[start:i].strip()
        if url:
            candidates.append((url, descriptor))
        if i < n:
            i += 1
    return candidates


def absolute_url(value, base):
    if not value:
        return None
    return urljoin(base, value)

page_url = "https://example.org/page"
request = Request(page_url, headers={"User-Agent": "Mozilla/5.0"})
with urlopen(request, timeout=20) as response:
    html = response.read().decode(response.headers.get_content_charset() or "utf-8", errors="replace")
    document_url = response.geturl()

parser = ImageMarkup()
parser.feed(html)
base_url = urljoin(document_url, parser.base_href) if parser.base_href else document_url

for item in parser.items:
    attrs = item["attributes"]
    print({
        "page": document_url,
        "element": item["element"],
        "src": absolute_url(attrs.get("src"), base_url),
        "srcset": [
            {"url": absolute_url(url, base_url), "descriptor": descriptor}
            for url, descriptor in parse_srcset(attrs.get("srcset", ""))
        ],
        "loading": attrs.get("loading"),
        "data_attributes": {
            key: value for key, value in attrs.items() if key.startswith("data-")
        },
    })
Replace the example page address with the page you are authorized to inspect. The script records declarations rather than downloading the image files. Network failures, access controls, or a response that differs by session can limit what it sees. If you process untrusted pages, also set sensible timeouts and apply your own network and security controls.
Rank #2

- 2 in 1: USB C + USB 3.0, 32GB usb c flash drive has dual ports, usb 3.0 port is applied to all devices which have usb 3.0 interface and usb c port is widely used in all Android smartphones with OTG function
- High Speed USB 3.0: Read speed up to 90 MB/s, Write speed up to 30 MB/s, the speed of USB 3.0 interface is faster than USB 2.0, save time to wait, increases work productivity. Note: Speed will be limited if you use the USB key in the USB 2.0 interface
- Large Compatibility: The USB 3.0 Connector is compatible with USB 3.0 & USB 2.0 backward USB 1.1 devices, such as Laptop, Desktop, Car Audio, Tablet, TV, Speakers, Projector. USB-C port is compatible with all Android Smartphones
- Expand Storage: Good performance in storing, transferring and sharing digital data with families, friends, colleagues, customers. It can expand the capacity of smartphone, you can watch movies or share pictures when you go on vacation with your family
- Note: Make sure your smartphone is equipped with OTG function and need to open OTG function in Settings when you plug memory stick, then you can transfer easily data bewteen different devices
When does a browser render become necessary?
A static fetch is a good first pass, but it cannot run page scripts. Some pages insert images after JavaScript executes; others fetch more items as the visitor scrolls. Browser-level lazy loading can defer fetching until an image is near the viewport, and a page’s load event may fire before its lazy-loaded images have finished loading. A declaration may therefore be visible in the HTML even when the browser has not fetched that image yet.
If the response is incomplete, use a browser automation workflow: load the page, wait for relevant content, inspect the DOM, and scroll in bounded increments where the page loads more content on demand. Collect after each step and stop when no new candidates appear or when your documented scroll or time limit is reached. Google’s guidance on lazy-loaded content emphasizes making content available as it becomes visible; browser rendering and scrolling help expose that behavior to an extractor.
Rank #3

- USB-C 2-in-1 storage OTG: The Lexar JumpDrive Dual Drive D40E features USB Type-A and Type-C connectors in a slim, portable form factor for easy device compatibility
- Transfer speeds up to 100MB/s: Based on internal testing, performance may vary depending upon the host device, interface, and usage conditions. 1MB=1,000,000 bytes
- Plug and Play: Widely compatible with USB Type-C smartphones, tablets, laptops, Macs, and traditional Type-A devices, no software installation required. The 360° swivel design allows for easy switching between connectors without the hassle of losing a cap
- Durable & Compact: The Lexar D40E USB memory stick features a metal enclosure, withstands temperatures from 0° to 50° C (32°F to 122°F), and is lightweight at 26g with dimensions of 70.4 x 16.9 x 11.7mm
- Security & Warranty: Securely protects files using an advanced security software solution with 256-bit AES encryption. Backed by a Lexar 3-year limited warranty
What JavaScript can collect from the rendered page
Run this in the page’s browser console after the page has rendered. It returns current img selections plus declarations from img and source elements. Run it again after scrolling to capture elements added later. This does not split srcset into every declared candidate; it preserves the raw attribute and reports the browser-selected currentSrc separately.
(() => {
  const absolute = value => value ? new URL(value, document.baseURI).href : null;
  const elements = [...document.querySelectorAll("img, picture source")];
  return elements.map(el => {
    const attrs = Object.fromEntries(
      [...el.attributes].map(attr => [attr.name, attr.value])
    );
    return {
      page: location.href,
      element: el.tagName.toLowerCase(),
      src: absolute(el.getAttribute("src")),
      srcset: el.getAttribute("srcset"),
      currentSrc: el instanceof HTMLImageElement ? el.currentSrc || null : null,
      loading: el.getAttribute("loading"),
      dataAttributes: Object.fromEntries(
        [...el.attributes]
          .filter(attr => attr.name.startsWith("data-"))
          .map(attr => [attr.name, attr.value])
      ),
      attributes: attrs
    };
  });
})()
currentSrc is useful when you need to know which source the browser selected for an image at that moment. It is not a substitute for enumerating all candidates: selection can depend on viewport, device characteristics, and the picture sources. The raw srcset string preserves declarations for later parsing.
Rank #4

- 2-in-1 Dual Design: Features both USB-C and USB-A connectors, making it compatible with phones, tablets, MacBooks, PCs, and laptops-no adapter needed
- Wide Compatibility: Works seamlessly with USB A and USB C devices, ensuring reliable file transfers across smartphones, computers, and more
- Ample Storage Options: Available in 16GB/32GB/64GB/128GB providing plenty of space for photos, videos, music, and documents
- Portable & Lightweight: Compact and durable design for travel, school, or daily use-take your files anywhere
- Plug-and-Play Convenience: No software or drivers required; simply insert into USB-C or USB-A ports and start transferring files instantly
How to handle lazy-loaded and site-specific image URLs
First inspect the element before and after it enters the viewport. If the standard source attribute contains a placeholder and a data-* attribute contains a different value, record both values and the attribute names. Then scroll in limited steps and collect the DOM again. Some sites only add or update the real source after the relevant code runs.
Do not assume that setting every custom data attribute as src reproduces the site’s behavior. The attribute may need a site-specific script, or it may not be an image URL at all. Treat these values as candidates until you can verify the resulting request or rendered image.
Best Value
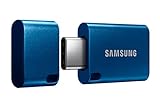
- USB-C STORAGE ON THE GO: This sleek drive is supported by Samsung NAND flash and is incredibly compact to fit in the palm of your hand; Count on reliable performance and fast transfer speeds while staying compact
- PERFORMANCE WITH SPEED: No need to choose between performance and reliability; Experience a fast, powerful flash drive that transfers 4GB files in just 11 seconds with up to 400MB/s USB 3.2 Gen 1 read speeds and is backward compatible with USB 3.0/2.0
- MODERN MEETS ICONIC: The ultra-sleek USB-C drive looks as good as it performs; Featuring a reversible plug, the Type-C inserts into your devices seamlessly every time; Transfer large files with style and ease
- ALWAYS CONNECTED: USB-C is compatible across devices, including laptops, tablets, phones and cameras, with enough space for 63,730 photos or maximum 12 hours of 4K video; With up to 256GB of storage space, this pocket-sized thumb drive comes in handy wherever you go
- TOUGH & TRUSTED: Files stay secure, no matter the terrain; Samsung's flash memory technology makes the Type-C a trustworthy drive to store your valuable data; It's waterproof, shock-proof, magnet-proof, temperature-proof, and X-ray-proof body, plus it's backed by a 5-year limited warranty
How to identify tracking pixels without mislabeling images
Finding an image URL and classifying its purpose are separate tasks. Preserve the candidate inventory first. If you flag likely tracking pixels, combine signals such as rendered dimensions, hidden or off-screen styling, surrounding context, and URL patterns, and retain the observations behind each flag.
A tiny image is not proof of tracking: it could be a legitimate icon, spacer, or interface asset. There is no universal size threshold that establishes tracking intent. The WHATWG HTML Standard notes an anti-tracking concern with lazy loading: if a browser loaded lazy images while scripting was disabled, strategically placed images could let a site infer approximate scroll position from when requests arrive. That concern explains one browser behavior; it is not a pixel-detection rule.
What this workflow may still miss
- Images only revealed after a click, login, or other interaction may require reproducing that interaction in the browser.
- Content behind a closed shadow root, images drawn into a canvas, and CSS background images are not covered by the snippets above; they need separate, page-specific inspection.
- Blocked requests, network errors, session differences, and content fetched through a page-specific API can make the visible result differ from the initial response.
- Scrolling needs a stopping rule. A page with endless loading cannot be exhaustively traversed without a limit.
For repeatable work, save the page URL, collection time, element type, attribute name, raw value, resolved URL, responsive descriptor, and—when a browser is used—the selected currentSrc. That record makes it possible to distinguish what the page declared from what the browser actually selected.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




