If a probabilistic AI assigns a group of comparable predictions about 90% probability, the predicted event should occur in about 90% of those cases in the population and time period being evaluated. That is what calibration makes a confidence number mean. It does not prove that any one answer is correct, and a conversational claim such as “I’m 90% sure” is not a measured probability unless it has been tested against suitable outcomes.
What does 90% confidence actually mean?
For a probabilistic classifier, calibration is the match between the probabilities it predicts and the frequencies observed after outcomes are known. If a system assigns roughly 90% probability to an event across a suitable set of cases, that event should happen roughly 90% of the time in that evaluation population. The remaining cases are not necessarily errors in the model’s arithmetic; they are part of what a 90% probability allows.
As an Amazon Associate I earn from qualifying purchases.
The claim needs a clearly defined event and comparison group. “Correct” might mean that the model’s top class matches a verified label, or that a specified outcome occurs within a stated time window. The evaluation should also identify the population and period represented by its cases. Without those details, “90% confidence” is too vague to interpret reliably. The statistical definition is summarized by the 2023 classifier-calibration survey and a 2021 PNAS paper on reliability diagrams.
Calibration is what makes a confidence number interpretable as a frequency. It is an empirical property of predictions across cases, not a guarantee attached to a single prediction.
#1 Best Overall

- Contains multiple precision calibration weights - 1 x 500g, 1 x 200g, 2 x 100g, 1 x 50g, 2 x 20g, 1x10g. Total Set of Weights: 1000g. Made of carbon steel with a chrome-plated, mirror-polished surface for precision and corrosion resistance.
- Comes with 1 plastic storage case and 1 piece calibration weight tweezer. M2 Class: Tolerance: 10g: ±6mg; 20g: ±8mg; 50g: ±10mg; 100g: ±16mg; 200g: ±30mg; 500g: ±80mg.
- Function of Precision Calibration Gram: Metric calibration weight for calibrating the weights, or electronic balances and scales.
- Stainless Steel Anti-oxidation: These calibration weights are made of solid feeling coated metal. Ensure the quality of the weight will not be damaged and can be reused multiple times.
- Great scale test calibration weight suitable for commercial and educational purposes. Perfect for digital kitchen scale, jewelry scale, diamond scale, precision balance test.
If an AI says it is 90% confident, should it be right 9 times out of 10?
Only if “90%” is a probability for a defined outcome and the system has been shown to be calibrated on relevant cases. A model can produce a number, or phrase an answer as “90% sure,” without that number having been validated as a probability. For a verbal self-assessment, ask what exactly the percentage refers to and whether it was evaluated against labeled outcomes for the task at hand.
For language models, confidence can refer to different things: probabilities assigned to individual tokens, an estimate about a whole generated answer, or a model’s self-assessment of that answer. These are different objects and require different evaluation approaches. The 2024 NAACL survey on confidence estimation and calibration reviews these distinctions; a verbal percentage alone is not evidence that the answer has a 90% chance of being correct.
Rank #2

- 17 PCS PRECISION WEIGHTS: This calibration weight set contains 17 pieces of different weights (includes 1x10mg, 2x20mg, 1x50mg, 1x100mg, 2x200mg, 1x500mg, 1x1g, 2x2g, 1x5g, 1x10g, 2x20g, 1x50g, 1x100g) and 1 piece for tweezers.
- HIGH ACCURACY: The permissible error is -0.003 to +0.003g. The calibration weight kit can be used for digital pocket scale, jewelry carat scale, diamond scale, precision balance test.
- HIGH QUALITY: These weights are made of solid feeling coated metal, with chrome-plated surface, which can resist corrosion. Ensure the quality of the weight will not be damaged and can be reused multiple times.
- EASY TO USE: The scale calibration weight kit comes with a tweezers, makes it convenient to pick the weights. Metric calibration weight for calibrating the weights, or electronic balances and scales.
- SUITABLE FOR MULTIPLE INDUSTRIES: The calibration weights for digital scale suitable for general laboratory, commercial, experimental, educational purpose and daily life use.
How do you tell whether an AI model is overconfident?
Use held-out, labeled examples that represent the intended deployment task. For each example, record the model’s probability and whether the defined outcome occurred. Then group predictions into confidence ranges and compare each group’s average confidence with its observed outcome rate.
Free tools Windows power users keep installed
One-click scans. No signup required.
- Define the outcome. Specify what counts as correct or what event the probability predicts, how it is labeled, and any relevant time window.
- Choose representative evaluation cases. Use labeled examples that reflect the population, task, and operating conditions in which the probability will be used. Keep these cases separate from data used to train the model or fit a calibration adjustment.
- Group predictions by confidence. For example, collect predictions near 90% and calculate the fraction for which the defined outcome occurred. Record the number of cases in each group.
- Compare confidence with observed frequency. If a group averaging about 90% confidence is correct 75% of the time, that is evidence of overconfidence in that group. If it is correct 96% of the time, the model is underconfident there.
- Check uncertainty and repeat across ranges. Small groups can produce noisy rates. Examine uncertainty around each observed rate, and do not treat a single group as the full picture.
A reliability diagram, also called a calibration curve, makes the comparison visible: one axis shows stated confidence and the other shows observed accuracy or frequency. Points on the diagonal indicate that the two align; gaps show where they differ. In multiclass classification, clarify whether the diagram uses confidence in the top predicted class or separate one-versus-rest plots for each class, because those show different aspects of performance. The survey discusses interval estimation and the sensitivity of summary measures to bin choices (classifier-calibration survey).
Rank #3

- We are proud to be the online market pioneer in high precision weights since 2017 and have received many compliments from our customers over the years
- We finally get the chance to hold ourselves to a higher standard in terms of certificates. Since 2023, our certificates are issued annually by the top institute located in East Asian Continent
- The accuracy class has never been lower than F1. Includes 25 pcs weights, a nice aluminum storage case with foam pad, a plastic storage box for tiny weights, tweezer and cleaning cloth
- SUS304 Stainless Steel, cylinder or flake shape, structural stability. Meet most needs of the measurement or the calibration, can be used for balance scale, mini electronic scales, jewelery scale and so on
- Pdf format certificate could be download on Product documents. No paper copy of the certificate attached. Please let us know if you need higher standard E1/E2 or other weight combinations. We value your voice very much
Can a model be calibrated but still be wrong?
Yes. Calibration is assessed across a set of cases, not by certifying individual predictions. Even a well-calibrated group of predictions near 90% will include cases where the event does not occur. Aggregate calibration cannot tell you whether one particular prediction is correct; estimating reliability among similar cases may reveal local patterns, but that estimate also depends on data and modeling choices. The authors of a 2022 paper on local calibration put the individual limitation plainly: “it is in general impossible to measure the reliability of an individual prediction” (PMLR paper).
Results also depend on whether the evaluation cases match the situation in which the model is used. A change in population, task, labeling practice, or conditions over time can make previously measured calibration less relevant. A reliability diagram or one summary statistic is therefore evidence about the evaluated cases, not an automatic assurance for every future decision.
Rank #4
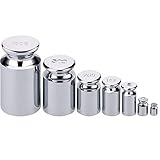
- WEIGH SCALES CALIBRATION: 7 PCS of calibration weights include 1g, 2g, 5g, 10g, 20g, 50g, 100g, a total of 188 grams. Various scales for precise measuring. Enough quantity for your use.
- HIGH-QUALITY: Our Calibration Weights use steel chrome plating manufacturing process, the workmanship is fine. Super mirror polished, smooth and corrosion-resistant.
- ACCURATE MEASUREMENT: These small weights are useful to test the accuracy of scales, keeping your scale calibrated. Making your experiment more effective.
- WIDE RANGE OF USE: Our scale calibration weights suit for general laboratory, commercial, educational use. Such as digital pocket scale, jewelry carat scale, diamond scale, precision balance test.
- WHAT YOU GET: 1g*1, 2g*1, 5g*1, 10g*1, 20g*1, 50g*1, 100g*1, our 7*24 friendly customer service for peace of mind.
Which metrics should be checked alongside calibration?
Calibration is one dimension of probabilistic performance. A system can assign probabilities that match observed frequencies yet provide little useful separation between cases. Conversely, it can rank cases effectively while its reported probabilities are systematically too high or too low. The “triptych” framework separates reliability, discrimination, and overall predictive performance (International Journal of Forecasting, 2024).
| Measure | Question it helps answer | Important limitation |
|---|---|---|
| Reliability diagram | Do observed frequencies track predicted confidence across ranges? | Its interpretation depends on the cases, grouping choices, and uncertainty in each group. |
| Expected calibration error (ECE) | What is the weighted average absolute gap between confidence and accuracy across bins? | It depends on the binning scheme; report that scheme. A low ECE alone does not show that predictions are informative. |
| Maximum calibration error (MCE) | What is the largest confidence–accuracy gap among bins? | It highlights a worst bin, but can be sensitive to small bins. |
| Brier score and other proper scoring rules | How good are the probabilistic predictions under a scoring rule? | Use these alongside calibration diagnostics rather than treating one score as a complete explanation of performance. |
| ROC curve | How well does the model rank positive cases ahead of negative cases? | It assesses discrimination, not whether the probability values themselves match observed frequencies. |
| Local calibration error | Are predictions reliable among similar cases, even if an aggregate hides a pattern? | Local estimates depend on how similarity is modeled and do not establish the truth of an individual prediction. |
ECE is commonly calculated as a weighted average of the absolute difference between each bin’s mean confidence and its observed accuracy, with weights based on the number of examples in each bin. Changing the bins can change the result, so report the binning scheme and interpret the statistic with the diagram and sample sizes. The CORP approach is one proposed stable, reproducible construction of reliability diagrams using isotonic regression and the pool-adjacent-violators algorithm; it is an approach, not a universal guarantee.
Best Value

- 5 Combination Set: the 5kg calibration weight set includes one 2kg weight, two 1kg weights, and two 500g weights, with a total weight of 5kg; The product can be freely combined into ten weight combinations: 500g, 1kg, 1.5kg, 2kg, 2.5kg, 3kg, 3.5kg, 4kg, 4.5kg, and 5kg, achieving multipurpose application of one item
- High Precision Standard: this set of calibration weights meets the M1 precision level requirements, and its error limit strictly follows the International Organization for Legal Metrology (OIML) R111 recommended standard, with an error of no more than 25mg per 1kg; It can provide reliable and trustworthy calibration basis for commercial scales, precision electronic scales, and laboratory equipment, ensuring that your weighing results are accurate and error free
- Chrome Plated Steel Material: the calibration weights are made of high density steel casting, and the surface is finely chrome plated; This process not only provides excellent corrosion and wear resistance, ensuring stability, but also has a smooth surface that is easy to clean, corrosion resistant, not easy to rust, and has good stability, which can effectively avoid the impact of residual stains on calibration accuracy
- Easy to Application: each weight is designed with a picking groove or knob at the top for easy gripping, ensuring stable operation even when hands are wet or gloves are worn; Meanwhile, the unified standard size design enables them to stack stably during storage and transportation, saving space
- Widely Applicable Scenarios: this 5kg calibration weight set is a suitable choice for daily equipment accuracy verification in laboratories, schools, jewelry workshops, pharmacies, and food processing plants; It is also applicable to quality inspection departments of small and medium sized enterprises, roasting coffee shops and other places that need to comply with trade regulations, and is an important tool to ensure fair transactions and production quality
What should a team do if probabilities are miscalibrated?
First diagnose where and how the probabilities diverge from observed frequencies using representative labeled data. If the system needs adjustment, a post-hoc calibration method can map its original probability outputs to revised probabilities without retraining the underlying model. The right method depends on the observed pattern; calibration approaches have different trade-offs, including susceptibility to overfitting and computational effort.
- Measure calibration on held-out examples from the intended task and population.
- Choose an adjustment suited to the pattern found, rather than assuming one method is best for every model.
- Fit that adjustment on a separate labeled set, not on the final evaluation cases.
- Re-evaluate the adjusted probabilities on data that was not used to fit the adjustment, and examine calibration together with discrimination and proper-score performance.
For language models, define whether the target is a token, a generated answer, or a self-assessment before selecting an evaluation method. The available literature describes a heterogeneous and developing field rather than a single confidence procedure that applies to every generative task.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →



