Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Scan for outdated or missing drivers - takes under a minute3Repair Windows errors before they cause bigger problemsFor user-facing reliability paging, alert on whether customers are experiencing failures and how quickly those failures are consuming the service’s error budget. CPU utilization can help explain an incident, but on its own it does not show whether users are affected. Keep CPU alerts for specific, imminent resource risks that could quickly cause an outage—not as a substitute for service-level alerts.
Why error-budget alerts are more useful than CPU thresholds
A CPU threshold reports an internal condition: processors are busy. That may be an early warning or a clue during troubleshooting, but it is not itself evidence that a service is failing for users. A service can have high CPU and still meet its reliability objective; conversely, a dependency failure or software defect can harm users while CPU looks normal.
As an Amazon Associate I earn from qualifying purchases.
Google’s incident-management guidance puts the distinction plainly: “Alerts should be based on end-to-end measures of customer/client experience, not based on a system’s internal behavior.” Internal metrics can be fragile indicators of user impact as an implementation changes. The exception is a targeted preventive alert for an imminent hard resource limit that could cause abrupt failure. Google SRE’s alerting guidance explains this symptom-first approach.
In practice, use service-level indicators (SLIs) to measure the user-visible behavior that matters, service-level objectives (SLOs) to define the target, and error-budget burn alerts to decide when reliability risk warrants action. Keep CPU and other diagnostic metrics available to explain what is happening after an impact alert fires.
#1 Best Overall

- 【Heavy-Duty 9 Outlet PDU】 Designed for standard 19" server racks, this 1U rack mount power strip provides 9 US standard outlets (15A/125V/1875W), ideal for data centers, network cabinets, and audio-visual setups needing reliable power distribution.
- 【Individual Switch Control】 Each outlet is equipped with its own illuminated on/off switch, so you can manage connected devices individually instead of unplugging them. The switch modules are fully independent: if one outlet trips, only that outlet shuts down while all remaining outlets keep running normally — no whole-strip shutdown, no interruption to your other equipment. A tripped switch also tells you exactly which device has reached its load limit, giving you faster, more sensitive overload protection and a clear visual cue for troubleshooting.
- 【Overload Protection & Power Monitoring】 Equipped with overload protection and a digital power monitoring display, this PDU safeguards your equipment from overloads while providing real-time voltage and current data for secure operation. The switch will automatically trip if the current exceeds 15A. Simply having wires or cables touch the switch will not cause it to trip — the switch only responds to an overload condition.
- 【Durable Metal Construction】 Built with a sturdy metal housing and a 14AWG heavy-duty 6.5FT power cord, ensuring durability and stable performance even in high-demand environments like professional server rooms and industrial settings.
- 【Versatile Installation】 Ideal for studios, labs, and data centers, ensuring peak performance and reliability. Designed for 1U rackmount for hassle-free cable management. Supports horizontal installation in server racks with included mounting brackets.
What an error budget and burn rate mean
Error budget
An error budget is the amount of failure allowed by an SLO during its measurement period. For example, a 99.99% availability target permits 0.01% unavailability over the applicable window. The measured quantity must match the SLI: availability, successful requests, or another explicitly defined user-facing measure. Google SRE’s explanation of error budgets gives the 99.99% example.
Burn rate
Burn rate describes how quickly a service consumes its error budget relative to the SLO. A burn rate of 1 consumes the full budget over the SLO window; a rate above 1 uses it sooner. For a 99.9% SLO measured over 30 days, Google’s workbook illustrates that burn rate 1 corresponds to a 0.1% error rate and budget exhaustion in 30 days, while burn rate 10 corresponds to a 1% error rate and exhaustion in 3 days. These figures illustrate the relationship; they are not universal alert thresholds. The workbook chapter on alerting describes the calculation and examples.
Rank #2

- High-Resolution Touch Display – Features a 6.91 inch LCD with 1424x280 resolution, delivering sharp visuals and responsive touch control for efficient server management. NOTE: There will be a protective film on the screen surface. Please remove it before use.
- 10 inch 1U Rack-Mountable Design – Compact and space-saving, this monitor fits seamlessly into 10inch server racks, making it ideal for data centers and network cabinets.
- Compatible with DeskPi RackMate Series – Specifically designed for DeskPi RackMate T0/T1/T2/T0 Plus/T1 Plus/TL1/T1/2 Plus Server Cabinet and Standard 10 inch Server Rack, ensuring perfect integration and ease of installation.
- User-Friendly Touch Interface – The capacitive touchscreen allows for intuitive operation, reducing reliance on external input devices.
- Durable & Efficient for Server Use – This monitor offers reliable performance in server environments with low power consumption and robust construction.
How to set up SLO burn-rate alerts
- Choose the user-facing SLI. Define what counts as a good or bad event for the service, such as a successful request or an available response. Make the measurement reflect the customer experience rather than an infrastructure proxy.
- Set the SLO and its measurement window. State the target and the period over which the error budget applies. A burn rate has meaning only relative to that target and window.
- Decide what requires immediate action. A page should indicate a problem that needs an on-call responder now. Route slower consumption that can be addressed within days to a ticket; retain passive logs for information that needs no immediate response.
- Use multiple time windows or burn rates. A short window can detect an acute incident quickly, while a longer window can distinguish sustained degradation from a brief spike. Google’s workbook offers example paging baselines of 2% of budget consumed in one hour and 5% in six hours, plus a ticket baseline of 10% in three days. Treat these as starting examples, then tune them to traffic, service behavior, and on-call capacity.
- Put the SLI on the service dashboard. Responders need to confirm the customer impact quickly. Keep CPU and other diagnostic data nearby to investigate causes; an SLO dashboard can reveal that an objective is being violated without identifying why. Google’s monitoring guidance discusses the role of dashboards and other service data.
- Review alert outcomes. Adjust thresholds and routing if alerts repeatedly demand no action, or if meaningful incidents are not producing a timely signal. Preserve the distinction between a symptom-based page and a preventive resource warning.
How to choose between a page, ticket, and CPU warning
| Signal | What it tells you | Best use | Key limitation |
|---|---|---|---|
| SLI and burn rate | Whether user-facing reliability is off target and how quickly the budget is being consumed | Page for urgent, actionable impact; ticket for slower degradation | It may show that the objective is failing without explaining the cause |
| CPU utilization | An internal resource is under load | Diagnosis, or a narrowly targeted warning before an imminent hard limit | High CPU does not by itself establish customer harm; normal CPU does not rule it out |
| Logs | Recorded events useful for later investigation | Preserve information that requires no immediate response | Passive records do not replace an actionable alert |
Google’s incident guidance distinguishes alerts that demand immediate action from work better handled as tickets within days or information that can remain in logs. The notification should match the urgency, not merely the fact that a metric crossed a line. Google SRE’s monitoring chapter covers this alerting and monitoring context.
Adjust burn-rate alerts for low-traffic services
Short-window error ratios can be misleading when request volume is small. Google’s workbook notes that one failed request in a service receiving 10 requests per hour produces a 10% hourly error rate. That percentage may reflect a single event rather than a sustained outage, so copying thresholds designed for a high-volume service can create noisy alerts.
Rank #3
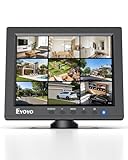
- EXTENDED USE: Designed for security monitoring and other long-running display tasks, this compact screen is suited for CCTV, DVR, NVR, server rooms, equipment checks, and other setups needing a dedicated display
- CONNECT YOUR GEAR: HDMI, VGA, BNC, and AV inputs support PCs, DVRs, NVRs, cameras, retro computers, and other video sources. USB Media Playback lets you play compatible videos, photos, and music without a PC
- CLEAR 4:3 VIEW: The native 1024x768 resolution and 4:3 aspect ratio match many surveillance systems, legacy computers, and industrial equipment, helping you view content without forcing a widescreen format
- SECURITY MONITORING: Use this small display as a dedicated screen for CCTV cameras, DVRs, and NVRs. Its compact size works well in control areas, equipment rooms, workbenches, and other space-limited monitoring stations
- IT & SERVER WORK: Keep a dedicated screen near your equipment for BIOS setup, server access, network troubleshooting, device testing, and maintenance without taking up the space of a full-size monitor
For a low-volume service, consider both the error ratio and the number of requests behind it, as well as the service’s normal quiet periods. Decide whether one failure is urgent based on its actual user impact, and route the alert accordingly. Avoid treating a short-window percentage alone as proof of sustained degradation; use longer context or another suitable signal when a small denominator makes the ratio unstable.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Where CPU alerts still belong
Keep an internal-metric alert when it identifies a concrete failure mode that could become user-impacting before an SLI alert can provide useful warning—for example, an imminent hard resource quota or capacity limit. Make the condition specific, the consequence clear, and the response actionable. Otherwise, use CPU as diagnostic context rather than a universal paging trigger.
Rank #4

- Efficient Power Distribution: The Metered PDU is designed to efficiently distribute power to devices in a rack. It features 6 C13 outlets with a maximum output of 15A and a 6.5ft power cord for easy installation
- Wide Voltage Compatibility: Supports a universal voltage range of 100-250V, making it compatible with various power sources including utility outlets, generators, and UPS systems for versatile applications
- Real-Time Power Monitoring: Features a built-in power meter with OLED display that allows you to monitor voltage, amperage, and power usage in real-time for better energy management
- Enhanced Safety Features: Equipped with built-in surge protection module and L and N double-break switch to protect your valuable equipment from power surges and electrical hazards
- Durable Rack-Mount Design: Constructed with anodized T6 hardened aluminum profile for durability and longevity, designed to fit standard 19 inch 1U rack-mount configurations with included cage screws
The operational rule is straightforward: page on customer symptoms and urgent budget risk; use targeted preventive alerts for imminent resource failures; use internal metrics to investigate the cause.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWindows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallQuick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




