An error tracker reports only what your application detects, classifies as an error, and successfully ships out as telemetry. Anything that breaks outside that chain stays invisible: a checkout that quietly does nothing, a browser crash your server never hears about, a log dropped by sampling, or an exporter that fails silently. A dashboard with no errors is therefore not proof that users got what they came for.
Why “no errors” is not “no problems”
OpenTelemetry’s observability primer frames reliability around whether a service does what users expect. Its example is a service that is up and responding while a user’s add-to-cart action fails. Every infrastructure check is green, yet the thing the user came to do did not happen. If no exception was thrown, an exception-based tracker has nothing to count.


The practical lesson: pair exception counts with user-centered indicators, such as whether add-to-cart, sign-up or payment actually completed.
The path a failure signal must travel
Think of each failure as a signal that has to survive six stages. A break at any stage produces the same symptom: silence.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
- User-visible behavior: something goes wrong for a person.
- Application detection and classification: the code notices and labels it an error.
- Client and server instrumentation: the relevant runtime is actually instrumented.
- Sampling and processing: the signal is not filtered or dropped.
- Exporter and network delivery: the data leaves the process and arrives.
- Backend ingestion and alerting: the backend accepts it and someone is notified.
Not every tracker has every weakness below, and no vendor solves all of them automatically. Use these as a checklist for your own setup.
Where failures go unseen
Nothing was instrumented
OpenTelemetry describes observability as depending on traces, metrics and logs that the application emits. A backend cannot infer behavior that was never instrumented, and missing data alone does not tell you whether the code path is healthy or simply unwatched. Background jobs, third-party callbacks and rarely used flows are common blind spots.
The failure looks like a success
A handler that catches an error and returns a friendly page with an HTTP 200, a payment that is “pending” forever, or an empty result shown where data should be: none of these raise an exception. Detection only works if code or a business-level signal marks the outcome as failed. Where you can, emit explicit signals for the outcome that matters (order completed, message delivered), not only for crashes.
The browser is a separate problem
Server-side coverage says little about what happens in the user’s browser. The current OpenTelemetry JavaScript documentation describes browser client instrumentation as experimental and mostly unspecified. That status can change, so confirm your SDK, version and actual browser use case instead of assuming parity with server instrumentation.
Sampling discarded the evidence
Sampling is deliberate data loss, which is fine for cost control but dangerous for rare failures. Microsoft’s Azure Monitor OpenTelemetry configuration page says that, in the configuration it describes, logs associated with unsampled traces are dropped by default, while metrics are never sampled there. That is one product’s documented behavior, not a universal rule. Sampling defaults vary by product, language and configuration, so read your own.
The telemetry pipeline itself failed
Monitoring code can break too. OpenTelemetry’s error-handling specification says implementations must not throw unhandled exceptions at runtime, which means a failing SDK is built to fail quietly. It recommends self-diagnostics and mentions signals such as exporter upload time and processor queue size, and says suppressed errors should be logged. Not all SDKs expose the same diagnostics, so check what yours offers. A quiet tracker does not establish that telemetry was delivered.
Rank #4
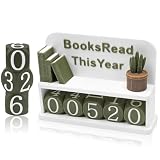
- Bookend + Counter Accent: bookshelf-style decor with a built-in rolling number block window, keeping reads upright while adding a visible progress marker to desks, shelves, nightstands, and book nooks
- Easy Number Updates: five rotating cylinders with clear high-contrast digits, quick to roll forward after each finish, making yearly goals feel visible and motivating without apps, sticky notes, or clutter
- Clean Minimal Look: raised "Books Read This Year" lettering with a neutral two-tone palette, blending into modern farmhouse, cozy cottage, classroom, and office decor while still standing out in photos
- Giftable for Book People: thoughtful choice for book lovers, teachers, librarians, and writers, great for birthdays, graduation, back to school, and holiday stocking stuffers for reading friends
- Stable Display on Shelves: compact block design sits neatly beside novels and planners, helping organize small spaces and keep the count easy to spot during study sessions, bedtime reading, or work breaks
How to check your own setup
The sources do not prescribe one universal test; this procedure is an editorial recommendation built on their points about instrumentation, self-diagnostics and sampling.
- Inject a known failure in each runtime you run (server, browser, background worker) and confirm it appears in the backend and triggers an alert. Do this in an environment that mirrors production sampling.
- Test a silent failure, such as a handler that returns success while the action fails, and see whether any signal exists for it.
- Review sampling and filtering rules and note whether errors, and the logs attached to them, are exempt from being dropped.
- Watch the pipeline’s health: exporter errors, queue sizes, upload latency and dropped-data counters, where your SDK provides them.
- Add outcome indicators for the journeys that matter and alert on their success rate, not only on exceptions.
Comparing monitoring approaches
If you are evaluating tools or designs, judge them on these axes. The sources support the first four as meaningful technical dimensions; they provide no vendor scores or pricing.
Recommended Free Tools
Best Value

- Organize Review and Track Your Reading Progress: Whether you're a dedicated reader or enjoy books occasionally, remembering every detail can be challenging. This meticulously designed guided reading journal serves as your companion, allowing you to organize reviews, meticulously track your reading progress, and compile comprehensive notes. Use it to structure your thoughts, ideas, and opinions, providing inspiration for your own writing endeavors.
- Intelligently Crafted for Versatility: Holds up to 110 book reviews, this versatile book reading journal offers ample space for ideas and quotes. Engage in reading challenges to meet yearly goals, thanks to dedicated sections. The numbered and navigational pages facilitate easy review access, and features like the "FAVORITE BOOKS" list empower you to track your favorite books effortlessly.
- Ideal Gift for Avid Readers: Searching for the perfect gift for book enthusiasts? Look no further! Our reading journal boasts a variety of colors and materials for its covers, catering to diverse preferences. Whether it's the elegance of white, the freshness of olive green, or the vibrancy of yellow, we have options to suit every taste. Beyond its aesthetic charm, this book journal becomes a cherished record of your unique reading journey.
- Sturdy and Premium Quality: Embrace the durability of our book log journal, featuring an exquisite vegan leather hardcover measuring 5.8x8.3 inches. The FSC certified 120gsm sustainably sourced thick paper ensures a luxurious writing experience. With added features like a colored ribbon bookmark, pen loop, elastic closure for convenient storage, and a pocket for loose papers or bills, this elegant journal is designed to withstand the test of time.
- Satisfaction Guaranteed: Transform your literary passion into words with confidence. If you encounter any quality concerns or are unsatisfied with our LoveBook Reader's Log for any reason, our commitment to your satisfaction remains unwavering. Reach out to us through Amazon email, and we'll promptly assist you in the replacement or refund process. Your reading experience is our priority.
| Question | What to look for |
|---|---|
| Coverage | Does it cover the real user journey and every relevant runtime, browser as well as server? |
| Detection | Are errors found from exceptions, failed outcomes, or explicit business signals? |
| Sampling and filtering | What is dropped by default, and can errors be exempted? |
| Pipeline visibility | Can you see SDK, queue, exporter and ingestion failures? |
| Practical costs | Privacy implications, operating cost and the effort of maintaining instrumentation. |
What the evidence does not tell us
No published statistic was found that quantifies how often error trackers miss severe failures, so treat any such rate with suspicion. OpenTelemetry’s documentation, last modified August 29, 2025, says the project is supported by more than 90 observability vendors (documentation index). That counts framework support; it says nothing about how complete anyone’s coverage is.
The Bottom Line
Treat silence from your error tracker as a question, not an answer. Verify each stage from detection to delivery with a known failure, and measure whether users succeed, not just whether exceptions occur.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




