When an LLM gateway starts failing, first distinguish the error’s source: a quota or rate limit, a gateway overload, an upstream timeout, or a provider failure that triggered retries or fallback. These four patterns are useful on-call categories—not a statistically proven ranking of the most frequent incidents. Preserve the original response and reconstruct each provider attempt before changing traffic or routing.
Why am I getting 429 errors from my LLM gateway?
HTTP 429 does not identify one universal limit. Depending on the gateway and provider, it can mean an organization request limit, a provider or model cap, a spending limit, or an upstream provider’s rate limit. Check the response body and relevant headers before deciding which limit has been reached. LLMGateway documents upstream rate limits as provider errors that may qualify for retry or fallback depending on routing configuration and available providers; its documentation distinguishes those from its transient overload response, HTTP 529. LLMGateway’s rate-limit documentation


As an Amazon Associate I earn from qualifying purchases.
Mitigate the limit that is actually binding
- Identify whether the constraint belongs to the organization, model, provider, spending policy, or gateway route.
- Reduce bursts or concurrency if requests are arriving too quickly or accumulating in flight.
- Honor
Retry-Afterwhen the response supplies a valid value. If it does not, use bounded exponential backoff with jitter. - Set both a maximum retry count and a maximum total retry duration. OpenAI’s troubleshooting guidance likewise recommends limiting retries and overall retry time. OpenAI’s API rate-limit troubleshooting
Why did my streaming response time out?
A timeout may end a generation while tokens are still arriving. LLMGateway describes its timeout as a total-duration limit rather than an idle timer, and says the limit applies to each upstream attempt. A retry or fallback begins a new attempt window, so the request’s end-to-end duration can exceed the timeout for one attempt. LLMGateway’s timeout documentation
Recommended Free Tools
Separate a failed start from a broken stream
If the request fails before the client receives output, the gateway may be able to retry or route another attempt, subject to its rules. If output has already started, a later stream error is different: replaying the request transparently could duplicate or conflict with content the client has already consumed. LLMGateway documents that a later streaming error ends the stream rather than transparently replaying it. LLMGateway’s routing documentation
#1 Best Overall
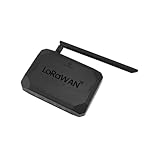
- NO SUBSCRIPTION FEES & PRIVATE LORAWAN NETWORK: Build a local LoRaWAN IoT network with the built-in SIoT server and pre-installed Node-RED. Collect data, create dashboards, and run automation flows locally without required cloud service fees. Suitable for DIY makers, home gardeners, educators, and small IoT prototype projects.
- LOCAL DATA PROCESSING & PRIVACY CONTROL: Sensor data can be processed on the local network through the built‑in MQTT/SIoT server, reducing reliance on third‑party cloud platforms. Local automation rules continue running when internet access is unavailable — suitable for home, garden, greenhouse, and classroom IoT setups.
- 4KM COVERAGE & 8-CHANNEL RELIABILITY: Equipped with the SX1302 8-channel LoRaWAN chip, -140dBm sensitivity, 27dBm max transmit power, and included 5dBi antenna. Supports up to 4km coverage in open environments, helping connect garden sensors, greenhouse nodes, garages, mailboxes, and remote monitoring points.
- NODE-RED DRAG-AND-DROP VISUAL AUTOMATION:Automation rules, data dashboards, and control logic can be built with little to no coding using the pre‑installed Node‑RED. Flows such as reading soil moisture, checking temperature, and sending relay commands are created through a visual interface — reducing setup time for maker, education, and prototype projects.
- EASY SETUP WITH WIFI AP & MQTT INTEGRATION: Configure the gateway via Wi-Fi AP mode using a laptop or mobile device. Built-in MQTT broker supports integration with Node-RED dashboards, and other MQTT-compatible platforms. Designed for indoor residential, educational, and prototyping use; not intended for outdoor installation.
For diagnosis, capture request and attempt start and end times, provider and model, time to first token, retry count, stream termination state, and whether a final stream chunk arrived. These are useful fields to collect where available, not a guarantee that every gateway exposes them.
Why did the gateway retry or switch providers?
Retries and fallback depend on the error class and routing mode. LLMGateway documents retries for selected provider- or gateway-side failures, including some 5xx responses, timeouts, connection failures, upstream 429s, and certain provider account or mapping problems. It says genuine client errors such as invalid requests are not retried. Its routing documentation also notes two important boundaries: sticky routing can bypass cross-provider fallback, and a stream error after output reaches the client ends that stream rather than triggering a transparent replay. These are documented behaviors for that product, not universal gateway rules. LLMGateway’s routing documentation
Inspect the attempt chain, not just the final result
A successful final response can hide failed provider attempts. Record the error classification, attempt count, provider selected for each hop, credential source where exposed, and whether output had already been committed to the client. Compare the raw attempt errors with the final client response before concluding that the original provider recovered.
What does a 529 gateway overloaded error mean?
In LLMGateway’s documented behavior, HTTP 529 indicates transient gateway overload and is distinct from a quota-related 429. The documentation recommends honoring Retry-After for this response. Do not assume that 529 has the same meaning across gateways; status-code behavior is implementation-specific. LLMGateway’s rate-limit documentation
When slow upstreams create gateway pressure
Slow provider responses can leave more inference calls in flight at once, increasing concurrency pressure. Correlate overload responses with active in-flight requests, upstream latency, concurrency, and provider-specific error rates. Unbounded retries can add load precisely when the gateway is struggling; shape traffic, investigate slow upstreams, and keep both retry attempts and total retry time bounded.
How should an on-call responder investigate a gateway incident?
- Preserve the evidence. Save the original status, response body, headers, request ID, timestamp, model, and provider mapping before retrying manually or changing configuration.
- Classify the failure. Decide whether it is invalid client input, a gateway-enforced limit or overload, an upstream provider error, a timeout, or an interruption after streaming began.
- Reconstruct each attempt. Separate the final client response from individual provider attempts. Note which provider handled each attempt, the error at each hop, retry count, and whether output had reached the client before failure.
- Compare routes and error groups. Check the failing provider/model mapping against viable alternatives, then compare errors by mapping and by error type. LLMGateway describes incident views that include error counts and rates, upstream-versus-gateway distinctions, status, stream state, and retry details. LLMGateway’s incident-view documentation
- Apply one bounded mitigation. Reduce bursts or concurrency, honor retry guidance, change routing only if an alternative is viable, or roll back a recent configuration change. Reassess both success rate and latency after the change.
How should you compare providers or routes during an incident?
Compare routes only when there is a viable alternative, and use operational evidence rather than a general vendor ranking. These dimensions help separate a genuine recovery option from a route that merely shifts the failure:
- Error class and observed availability for the affected workload.
- Latency and timeout behavior, including time to first token and stream completion.
- Rate-limit and quota headroom for the model and provider.
- Streaming and tool compatibility required by the request.
- Fallback eligibility and retry boundaries for the route.
- Visibility into individual provider hops and attempt-level errors.
These are diagnostic comparison criteria, not the results of a comparative performance test. Product-specific routing, timeout, and rate-limit behavior should be checked in the relevant documentation. Rate limits · Timeouts · Routing
Free tools Windows power users keep installed
One-click scans. No signup required.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




