Free tools Windows power users keep installed
One-click scans. No signup required.
Self-hosted IBM Bob needs a customer-managed Red Hat OpenShift Container Platform (OCP) environment; it does not require a universal number of GPUs. For Bob Core production, IBM gives a separate planning profile of about 36.5 vCPU, 53.4 GiB of RAM and 50 GiB of persistent volumes after recommended CPU and memory headroom. Those figures cover Bob’s tenant workload, not the full OpenShift cluster. GPUs are needed only if you also host the model inference service yourself, and that service must be sized for the chosen model and workload.
What runs on your infrastructure?
Self-hosted Bob’s backend runs on OpenShift. Model inference is a separate service: Bob’s Model Inference Gateway connects to deployed models, but Bob does not provision, host or manage the model-serving infrastructure. That separation matters when you estimate capacity: do not add a presumed GPU count to Bob’s backend requirements. See IBM’s self-hosted deployment overview and model documentation.
As an Amazon Associate I earn from qualifying purchases.
IBM lists OpenShift Container Platform versions 4.20, 4.21 and 4.22 as supported. Bob workloads must run on amd64/x86_64 worker nodes. A mixed-architecture cluster can be used if operators ensure Bob workloads are scheduled to amd64 nodes; Bob does not apply those scheduling constraints automatically. Confirm the supported platform version when planning a deployment, since version support can change. IBM’s system requirements page gives the platform details.
How much CPU, RAM and persistent storage does Bob need?
IBM’s system requirements distinguish the raw aggregate resource estimates for different Bob stacks from a separate Bob Core production profile. Treat these as Bob tenant workload capacity, not total cluster sizing: platform services, other tenants, high availability and growth need to be considered separately.
#1 Best Overall
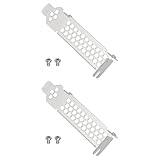
- Compatible with Dell PERC H330 H730p H740p Boss 7HYY4, Compatible with MegaRAID 9361-4i, Compatible with LSI 9361-8i RAID 12G, 9361 SAS 12G RAID, Compatible with MegaRAID SAS9340-8i 12G RAID.
- Also compatible with Lenovo IBM M1215 SAS Controller 46C9114 46c9115, Compatible with IBM M1215 46C9115 46C9112 46C9114, M5210 00AE852 46C9111 12GB SSD/SATA.
- Made of steel, sturdy, durable, and resistant to deformation.
- Used for replacing the low-profile bracket when installing a RAID controller card in a chassis. Provides a secure hold, ensuring the controller card is firmly attached to the PCIe slot.
Raw aggregate figures by stack
| Bob stack | CPU | Memory | Persistent volumes | Status |
|---|---|---|---|---|
| Bob Core | 22.1 vCPU | 35.1 GiB | About 30 GiB | Baseline available |
| Bob Core + RAG | 38.1 vCPU | 69.1 GiB | About 62 GiB | Baseline available |
| Bob Core + Z Understand | 30.1 vCPU | 74.1 GiB | About 2,288 GiB | Provisional; benchmarking in progress |
| Bob Core + RAG + Z Understand | 46.1 vCPU | 108.1 GiB | About 2,320 GiB | Provisional; benchmarking in progress |
These are raw aggregate Bob tenant estimates from IBM’s stack requirements. The Z Understand storage figures are especially important to treat as provisional: IBM says benchmarking is in progress, so they are not settled capacity guidance.
Bob Core production planning profile
Separately, IBM gives a Bob Core production profile of 28.1 vCPU, 41.1 GiB RAM and about 50 GiB of persistent volumes. IBM recommends adding 25–30% headroom for CPU and memory, which it expresses as approximately 36.5 vCPU and 53.4 GiB RAM. The cited profile leaves persistent volumes at about 50 GiB; it does not state an equivalent storage headroom multiplier. Use the headroom-adjusted CPU and memory figures when planning worker capacity, and size storage for the selected stack and its performance needs.
Rank #2

- High Storage Capacity of 18TB and up to 45 TB compressed capacity
- Supports transfer speeds of 400 MB/s (native), 1,000 MB/s (2.5:1) with Generation
- Barium Ferrite (BaFe) technology
- Support for tape drive hardware encryption
- Compatible with Linear Tape File System (LTFS)
The raw Bob Core stack-table estimate (22.1 vCPU, 35.1 GiB and about 30 GiB) and the separate production profile (28.1 vCPU, 41.1 GiB and about 50 GiB) are different IBM figures for different planning contexts. Do not substitute one for the other without deciding which profile applies to your deployment.
What OpenShift cluster capacity should you plan for?
Bob’s tenant figures are not a complete cluster bill of materials. IBM’s minimum reference topology for a dedicated cluster has nine nodes: three control-plane nodes, three infrastructure nodes and three worker nodes. The reference node resources and totals are shown below; the aggregate is approximate.
Rank #3

- 1U Profile: 1U Universal Rack Mount Rails occupy one rack unit of vertical space; supports 1U servers and fixed-mount network hardware in standard four-post cabinets
- Adjustable Depth: Our server rack rails telescoping rail pair extends from 16 to 30 inches; adapts to shallow wall cabinets and deeper floor-standing server racks
- Four-Post Fit: This rack mount rails engineered for square-hole and round-hole 4-post frames; pairs with common 19-inch EIA-310-D rack layouts
- Broad Model Use: These server rails work with APC, HP, IBM, Dell, and Compaq cabinet configurations as a generic support rail; not a manufacturer-branded original part
- Tool-Free Length Lock: Thumb screws secure depth setting without extra tools; numbered scale on inner rail eliminates guesswork during cabinet fit-up
| Node pool | Count | Per-node reference | Pool total |
|---|---|---|---|
| Control plane | 3 | 4 vCPU, 16 GiB RAM | 12 vCPU, 48 GiB RAM |
| Infrastructure | 3 | About 4 vCPU, 16 GiB RAM | About 12 vCPU, 48 GiB RAM |
| Workers | 3 | 20 vCPU, 24 GiB RAM, 200 GiB local storage | 60 vCPU, 72 GiB RAM, 600 GiB local storage |
| Reference cluster total | 9 | — | About 84 vCPU, 168 GiB RAM and 600 GiB worker storage |
After OpenShift overhead, IBM estimates that the worker pool in this reference provides around 57 vCPU and 63 GiB of allocatable capacity. IBM says that is enough for the Bob Core production profile with recommended CPU and memory headroom. The reference’s 600 GiB of worker local storage is not the same as Bob’s roughly 50 GiB persistent-volume footprint: it also accommodates platform services and growth. These topology and allocatable-capacity estimates are from IBM’s system requirements.
A dedicated cluster is not mandatory. IBM says Bob can run on a shared cluster if it has sufficient capacity. In either case, account for OpenShift’s own services, high availability, existing workloads and expected growth instead of treating Bob’s tenant figures as total cluster requirements. IBM’s deployment overview describes the shared-cluster option.
Rank #4

- Used Book in Good Condition
Does IBM Bob need GPUs?
Not for the Bob backend by virtue of being Bob. The GPU requirement belongs to the inference service that serves the model. If you connect Bob to a cloud model API, the provider operates the inference hardware and your Bob deployment may need no customer-managed inference GPU. If you host an open-weight model on your own infrastructure, size that separate serving tier for the model and expected use.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →IBM identifies model quantization, context length, serving runtime (for example, vLLM or TGI), concurrency and target throughput as factors in CPU, RAM, GPU/VRAM and capacity planning. Its documentation names Mistral 3.5, NVIDIA Nemotron 3 and Poolside Laguna S2.1 among self-hosted model references. IBM’s October 1, 2026 release article identifies NVIDIA Nemotron 3 Ultra and Poolside Laguna S 2.1 for the disconnected route. Model availability and compatibility can vary by deployment route; check IBM’s current supported-model guidance and the model and runtime vendors’ hardware recommendations before selecting GPUs. IBM’s October 1, 2026 release article says hardware sizing follows vendor guidance because it depends on quantization, context length and the number of developers served at once.
Best Value

- 1U Profile: 1U Universal Rack Mount Rails occupy one rack unit of vertical space; supports 1U servers and fixed-mount network hardware in standard four-post cabinets
- Adjustable Depth: Our server rack rails telescoping rail pair extends from 16 to 30 inches; adapts to shallow wall cabinets and deeper floor-standing server racks
- Four-Post Fit: This rack mount rails engineered for square-hole and round-hole 4-post frames; pairs with common 19-inch EIA-310-D rack layouts
- Broad Model Use: These server rails work with APC, HP, IBM, Dell, and Compaq cabinet configurations as a generic support rail; not a manufacturer-branded original part
- Tool-Free Length Lock: Thumb screws secure depth setting without extra tools; numbered scale on inner rail eliminates guesswork during cabinet fit-up
Choose an inference arrangement
| Arrangement | Where inference runs | GPU responsibility | Key consideration |
|---|---|---|---|
| On-cluster self-hosting | On OpenShift, such as with OpenShift AI or another serving setup | Your organization sizes and operates the inference resources | Suitable for air-gapped or self-hosted model deployments; ensure the serving endpoint is reachable from Bob. |
| Private infrastructure | Separate GPU servers or a private inference cluster | Your organization or platform team | Plan private-network connectivity and operate the separate serving tier. |
| Cloud model provider | A provider endpoint, such as AWS Bedrock, Azure OpenAI or Google Vertex AI | The provider operates inference hardware | Bob needs endpoint connectivity and appropriate provider access; customer-managed inference GPUs may not be needed. |
IBM’s serving guidance calls for an OpenAI-compatible API endpoint reachable from the Bob cluster. The options above are described in IBM’s model gateway documentation. The choice is therefore about more than GPU ownership: consider the data boundary, network route, supported model, operational responsibilities and expected serving behavior.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.What storage and installation prerequisites matter?
Storage classes, access modes and performance
IBM identifies Managed NFS and OpenShift Data Foundation (Ceph-backed RBD and CephFS) as supported storage classes. PostgreSQL, OpenSearch and Redis use ReadWriteOnce (RWO) volumes; shared configuration and certificates require ReadWriteMany (RWX). Check that the storage classes you intend to use provide the required access modes.
IBM strongly recommends SSD-backed block storage for PostgreSQL and high-performance block storage for OpenSearch. Insufficient throughput or I/O—particularly for PostgreSQL—can increase response times, slow indexing and reduce stability. Storage capacity alone is not enough: select storage with suitable performance for the database and search workloads. These requirements are detailed in IBM’s storage guidance.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Installation access and workstation
Installation requires an administrative workstation with network access to the cluster, the release bundle, access to IBM’s entitled container registry and cluster-admin access (or equivalent permissions for cluster-scoped resources). IBM’s installation prerequisites list these requirements. The workstation is an installation tool; IBM does not specify a special GPU workstation requirement for the Bob backend.
How to size a deployment before buying or allocating GPUs
- Choose the Bob stack. Use the appropriate raw tenant estimate for Core or optional RAG and Z Understand components. Treat Z Understand storage estimates as provisional while IBM labels them benchmarking in progress.
- Choose the cluster arrangement. Decide whether Bob will use a shared cluster with sufficient capacity or a dedicated cluster. Include OpenShift overhead, other tenants, high availability and growth in the cluster plan.
- Validate worker and storage capacity. For Bob Core production, use IBM’s separate headroom-adjusted profile of approximately 36.5 vCPU and 53.4 GiB RAM, plus about 50 GiB persistent volumes. Verify that worker nodes can supply allocatable resources and that storage supports the required RWO/RWX modes and I/O performance.
- Select the model endpoint. Decide whether inference will run on-cluster, on private infrastructure or through a cloud provider. Confirm the endpoint is reachable from Bob and meets IBM’s OpenAI-compatible API guidance.
- Size inference separately. Once the model, runtime, quantization, context length, concurrency and throughput target are known, use the model and serving vendors’ hardware guidance and capacity-test the inference service. The available IBM guidance does not establish a universal GPU count for Bob.
IBM reports that self-hosted deployment became generally available on September 24, 2026, in its October 1, 2026 release article.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




