The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Exo, GPUStack, and LocalAI solve different parts of running language models across computers. Exo focuses on connecting devices for distributed inference; GPUStack manages GPU clusters and model-serving services, including documented multi-node inference backends; LocalAI offers both request routing across workers and a separate way to shard certain models. Choose by deciding whether you need more request capacity, one model spread across machines, or a managed cluster—not by treating the three as interchangeable tools.
First decide what “multi-node” means for your workload
Two architectures can look similar from the outside but solve different problems:
As an Amazon Associate I earn from qualifying purchases.
- Replicas and routing: Separate workers each run a model instance. A router sends requests among them. This can increase the number of requests handled concurrently, but an individual request is generally served by one worker.
- Sharding or distributed inference: Multiple devices cooperate on the same model’s inference. This can make a model run across devices that would not handle it individually, but requires a compatible runtime, hardware, and interconnect.
LocalAI makes this distinction explicit in its documentation: federated mode routes a whole request to a selected worker, while its P2P worker mode lets multiple workers contribute to one inference. GPUStack is principally a cluster and serving-management layer, but documents distributed inference paths as well. Exo describes connecting devices for distributed inference. Those descriptions do not establish that every tool supports every architecture or hardware mix.
Recommended Free Tools
How the three projects differ
| Project | Primary role | Multi-node approach described in official documentation | Key constraint to check |
|---|---|---|---|
| Exo | Connect devices into an AI cluster for inference | Automatic device discovery, topology-aware auto-parallelization, tensor parallelism, MLX and MLX distributed; the README also describes RDMA over Thunderbolt 5. | Confirm that the devices, runtime, operating systems, and network topology fit the exact release’s supported configuration. |
| GPUStack | Manage GPU clusters and model-serving services | Central server, scheduler, controllers, workers, gateway, and inference servers; documentation describes bootstrapping Ray for distributed vLLM and lists multi-node support for vLLM, SGLang, and MindIE. | Distributed execution depends on the selected backend, accelerator, model, and release—not simply on adding a worker. |
| LocalAI | Serve models locally, with separate options for worker routing and distributed deployments | P2P federated routing or llama.cpp-compatible worker sharding; a separate production-oriented distributed mode uses frontends, workers, PostgreSQL, and NATS. | P2P sharding is limited to llama.cpp-compatible models; production distributed mode has explicit state, authentication, and coordination requirements. |
This comparison reflects the projects’ official documentation reviewed on October 7, 2026. Features and compatibility can change between releases, so check the documentation for the version you plan to deploy.
#1 Best Overall

- System Compatibility Note: 2-slot card, 271x112x39mm, single 8-pin power, 200W TDP. Verify chassis clearance and PSU capacity before purchase.
- Dedicated Support: Please contact us directly through Amazon for any product questions or assistance you may require.
- 24GB GDDR6 on 192-Bit Bus: Massive 24GB memory with 456 GB/s bandwidth – ideal for LLMs, AI inference, 3D rendering, and generative design.
- Intel Xe2-HPG Architecture: Built on Intel's next-gen architecture with 20 Xe cores and 160 XMX engines for AI acceleration (197 INT8 TOPS).
- PCIe 5.0 Support: PCI Express 5.0 x16 interface for maximum bandwidth with the latest workstation platforms.
When Exo is the better fit
Choose it to pool compatible devices for inference
Exo presents itself as a way to connect devices into an AI cluster. Its README describes automatic discovery, topology-aware parallelization, tensor parallelism, MLX inference and MLX distributed communication. It also describes RDMA over Thunderbolt 5. This makes device and network topology part of the deployment decision, rather than an afterthought: a setup’s behavior depends on whether its actual devices and interconnect are supported together.
Treat performance claims as configuration-specific
The Exo README advertises latency and tensor-parallel speedup figures, including a Thunderbolt 5 latency-reduction claim. These are project-published claims, not an independent head-to-head result for Exo, GPUStack, and LocalAI. They should not be read as a general guarantee for a different model, device count, network, or workload. If performance is decisive, reproduce the project’s stated setup and measure your own environment.
Rank #2

- System Compatibility Note: This large 180mm depth power supply may not fit in all cases; please verify chassis PSU clearance (180mm x 150mm x 86mm) and check that your system requires a 1600W unit. The TempGuard feature works natively with the included cables.
- Dedicated Support: Please contact us directly through Amazon for any product questions or assistance you may require.
- Exceptional Efficiency with Low Noise: Certified 80 PLUS Gold and Cybenetics Platinum, achieving up to 90% efficiency with a Cybenetics Lambda A noise rating for ultra-quiet operation under load.
- ATX 3.1 & PCIe 5.1 Compliant: Fully compliant with the latest standards, handling up to 220% total power excursions to ensure stable, reliable power for modern GPUs and motherboards.
- Native 12V-2x6 Connectors with TempGuard: Dual native 12V-2x6 (12+4 pin) connectors feature a dual-color design for secure fit confirmation and TempGuard technology to monitor temperature at the terminal point for added safety.
When GPUStack is the better fit
Choose it when cluster and service operations matter
GPUStack describes itself as an open-source GPU cluster manager. Its overview covers multi-cluster management across on-premises environments, Kubernetes, and cloud providers, along with pluggable inference engines, monitoring, and model serving. Its architecture documentation describes a server with an API server, scheduler, and controllers; worker-side runtime and serving management; an AI gateway for routing and load balancing; a database; and inference servers.
Verify the backend behind distributed inference
GPUStack’s documentation says it can bootstrap a Ray cluster on demand to run distributed vLLM across workers. Its FAQ lists multi-node, multi-GPU support for vLLM, SGLang, and MindIE. These are backend-specific paths, not proof that an arbitrary model will distribute across any GPU combination. Before committing, match the intended inference server and model to the exact GPUStack release and accelerator support information.
Rank #3
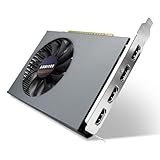
- Quad HDMI Multi-Monitor Mastery: Unleash unparalleled productivity with four independent HDMI ports. Simultaneously drive four separate displays from a single card, creating an immersive workstation for trading, programming, digital signage, or multi-tasking without the need for multiple adapters or extra cards.
- Robust 4GB DDR3 Memory for Multi-Screen Workloads: Equipped with substantial 4GB of DDR3 video memory, this card is optimized to handle the increased graphical demands of running multiple screens. It ensures smooth performance across various applications, from extensive spreadsheets to web browsing and multimedia playback on all displays.
- Seamless Setup & Instant Productivity Boost: Experience true plug-and-play installation. Designed for simplicity, it allows you to effortlessly create a sophisticated multi-monitor array right out of the box. It's the ultimate and most cost-effective solution to dramatically expand your screen real estate and workflow efficiency.
- Standard-Profile Design with Active Cooling: Built on a reliable, standard-profile form factor, this card ensures broad compatibility with most standard desktop PC cases.( Not suitable for SFF case)
- Optimized Power Efficiency for Easy Upgrades: Engineered with optimized power consumption, this card draws all necessary power directly from the PCIe slot, eliminating the need for external power connectors. This makes it a safe, simple, and energy-efficient upgrade for nearly any standard desktop system.
When LocalAI is the better fit
Use P2P mode when its specific trade-offs match
LocalAI’s P2P documentation describes ad-hoc clusters, community sharing, and experimentation. In federated mode, a whole request is routed to a selected worker; in worker mode, workers share model weights and contribute to one inference. The latter is documented as exclusive to llama.cpp-compatible models. LocalAI characterizes P2P federated mode as experimental or tech-preview quality, so it is not the same choice as its separate production-oriented distributed deployment.
Use distributed mode for a production-oriented deployment
LocalAI’s distributed-mode documentation describes stateless frontends, a SmartRouter, worker nodes, PostgreSQL-backed state and registry, and NATS coordination. It requires authentication to be enabled and does not support SQLite for distributed state. The documented Docker Compose quick start brings up PostgreSQL, NATS, a frontend, and a worker for local testing; the documentation recommends managed PostgreSQL and NATS for production.
Rank #4

- NVIDIA & AMD DESKTOP GPU READY — Designed to fit PCIe desktop graphics cards up to 4 slots wide, give any compatible laptop a massive boost in power by connecting the latest NVIDIA GeForce and AMD Radeon GPUs (GPU & power supply not included)
- NEXT-GEN THUNDERBOLT 5 PERFORMANCE — Featuring an ultra-fast bandwidth of up to 80 Gbps, enjoy the smoothest performance with a Thunderbolt 5 connection that easily manages the most demanding creative apps and AAA games
- MULTI-DEVICE COMPATIBILITY — From Thunderbolt 4 and Thunderbolt 5 laptops to USB 4 gaming handhelds, integrate the Razer Core X V2 to seamlessly turn compatible devices into gaming or creative powerhouses instantly
- SIMPLE SETUP — Connect the Razer Core X V2 to a compatible device via an included Thunderbolt 5 cable to get a graphical boost when needed and simply unplug when done
- MODULAR GPU & PSU SUPPORT — Swap out to the latest GPU and ATX PSU—or upcycle an older card with PCIe Gen 4 support via easy tool-free install using included thumbscrews
Model placement and transfer need planning. Shared-model mode assumes that workers mount the same models directory at the same path. Without that arrangement, model snapshots are staged to workers. LocalAI warns that controllers and workers need enough disk for copies unless shared-model mode is enabled. It also warns that an empty registration token can leave worker file transfer unauthenticated. Account for authentication, reachable network paths, storage, and model staging before exposing or expanding a deployment.
Choose by the operational problem you need to solve
| If your priority is… | Start by evaluating… | Why |
|---|---|---|
| Distributing inference across a set of devices | Exo | Its project description centers on device discovery and distributed inference, with topology-aware features. |
| Central management of GPU workers and model services | GPUStack | Its documented architecture includes scheduling, controllers, worker management, routing, monitoring, and model-serving components. |
| Routing requests across workers in a production-oriented LocalAI deployment | LocalAI distributed mode | It documents frontends, a router, worker nodes, and PostgreSQL/NATS-backed coordination. |
| Sharing one inference among workers using a supported llama.cpp model | LocalAI P2P worker mode | That mode documents worker sharding, with llama.cpp compatibility as its stated boundary. |
| Scaling concurrent requests | Compare routing and replica behavior in the intended deployment | Request routing and sharding one model solve different bottlenecks; the project name alone does not tell you which behavior you will get. |
These are starting points, not universal rankings. The official documentation does not establish a common, independently verified benchmark across the three projects, so it cannot support a defensible claim that one is universally faster or cheaper.
Best Value

- 4 HDMI Multi Monitor Display Expansion: Equipped with four HDMI outputs, this GT 740 graphics card supports up to 4 monitors with extended display and duplicate display modes. Ideal for multi-monitor setups, office productivity, presentations, and everyday desktop use.
- 4GB GDDR5 Graphics Memory for Desktop Applications: Featuring 4GB GDDR5 video memory and a 128-bit memory interface, this video card provides stable graphics performance for office applications, HD video playback, web browsing, and general computing tasks.
- Trading Workstation and Office PC Upgrade: Designed for multi-screen workflows, this graphics card is suitable for trading computers, office PCs, business desktops, home office setups, and workstation environments. Expand your display space for charts, documents, dashboards, and multiple applications.
- Single Slot PCIe Graphics Card Design: Featuring a single slot form factor and PCI Express x16 interface, this video card fits standard desktop systems. Compatible with PCIe 3.0 and PCIe 2.0 motherboards for flexible PC upgrades.
- Low Power Desktop Upgrade and Windows Support: Powered directly through the PCIe slot without an external power connector, this GT 740 graphics card simplifies installation. Supports compatible Windows systems including Windows 11, Windows 10, Windows 8, Windows 7, and Windows XP.
What to verify before deploying
- Workload: Decide whether the bottleneck is concurrent requests, model size, latency, or a mix. State whether requests should go to separate instances or one model should span devices.
- Model and runtime: Check the model format, inference backend, and release-specific compatibility. In particular, do not assume LocalAI P2P worker sharding applies beyond llama.cpp-compatible models.
- Accelerators and interconnect: Check supported devices and the actual connection between nodes. GPUStack publishes accelerator support information; Exo documents Thunderbolt 5 networking support. Neither description guarantees compatibility for every combination.
- Control plane and dependencies: Decide whether you need GPUStack’s cluster-management components, LocalAI’s PostgreSQL and NATS dependencies for distributed mode, or Exo’s device-discovery approach.
- Security and storage: For LocalAI distributed mode, plan authentication, worker transfer security, database and messaging services, disk capacity, and whether shared-model paths are viable.
- Failure and observability: Determine how you will monitor workers, handle unavailable nodes, and restore service. Review the chosen release’s operational documentation rather than assuming features described for another version.
How to make a fair performance comparison
Benchmark only configurations that deliver the same kind of result. A request routed to a replica is not directly comparable to a single model sharded across nodes unless the test question and workload make that distinction explicit. Keep the model, quantization, prompt and context length, concurrency, hardware, software versions, and network conditions consistent where possible. Record both throughput and per-request latency, and note whether model loading, staging, and coordination are included. Attribute any vendor-published figures to the project and its stated setup; do not convert them into a general ranking.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




