Free tools Windows power users keep installed
One-click scans. No signup required.
An AI QA agent can help draft and run API tests, but it should not decide on its own what the API is supposed to do. A dependable workflow gives the agent a clear contract, narrowly scoped tools, a safe test environment, and human review of proposed assertions and changes.
The available product documentation describes ways to build such workflows, but it does not establish a specific author-built stack or measured outcome. This guide therefore distinguishes documented capabilities from an implementation pattern: adapt the steps to the API, runtime, and safeguards your team actually uses.


As an Amazon Associate I earn from qualifying purchases.
Start with the API behavior, not the model
Before generating tests, give the workflow an authoritative description of expected behavior. That may be an API schema, an existing request collection, explicit acceptance criteria, or a combination. The agent needs enough context to distinguish intended behavior from one response it happened to observe.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Define which environment is safe to call and which operations are in scope. Read-only requests are a different risk from creating, changing, or deleting records. Do not expose production credentials or grant write access merely because an agent can call an endpoint.
Bound the agent’s job
A useful QA workflow divides work into inspectable actions: read the approved API context, propose test cases, draft or update test scripts, execute permitted requests, and report results. Each action should have a clear boundary, especially when it can alter data or affect a shared service.
- Limit access to the relevant schema, collection, environment configuration, and test data.
- Keep secrets outside generated scripts and restrict credentials to the test environment and required permissions.
- Require review before accepting generated test changes or enabling potentially destructive calls.
- Record what the agent changed and which requests it ran so failures can be investigated.
Generate assertions that express the contract
Tests should check stable properties of the API, not blindly encode a sample response. Depending on the contract, useful checks may include status codes, response shape, required fields, and invariants. Values such as generated IDs, timestamps, or other variable data need assertions suited to their behavior rather than exact matching against one example.
Postman documents Agent Mode for API workflows including writing tests, and its test-script guidance says: “Tell Agent Mode what to do, and it generates post-response scripts for you.” That establishes a documented capability, not proof that generated assertions are correct for a particular API. See the Postman Learning Center for Agent Mode and test-script guidance.
Rank #2
Review each proposed assertion against the API’s intended behavior. If a specification is ambiguous, resolve that ambiguity with the API owner or acceptance criteria; do not treat the agent’s suggestion or a single observed response as the oracle.
Run tests where failures are interpretable
Execute requests against a controlled test environment with known data and dependencies. The report should make clear which test ran, what it expected, what happened, and whether the failure points to an API regression, an unavailable dependency, a flaky condition, an invalid assumption, or an agent/tool error.
Postman documents local and cloud Agent Mode options, including cloud task execution in an isolated sandbox with an audit trail. Those choices affect where work runs and how it is inspected; they do not remove the need to control credentials, test data, and permissions. Product details are in Postman’s Agent Mode documentation.
Rank #3
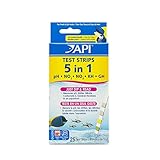
- Contains one (1) API 5-IN-1 TEST STRIPS Freshwater and Saltwater Aquarium Test Strips 25-Count Box
- Monitors levels of pH, nitrite, nitrate carbonate and general water hardness in freshwater and saltwater aquariums
- Dip test strips into aquarium water and check colors for fast and accurate results
- Helps prevent invisible water problems that can be harmful to fish and cause fish loss
- Use for weekly monitoring and when water or fish problems appear
Test the agent as well as the API
An agent workflow has its own failure modes: incorrect tool calls, broken handoffs, retry loops, session-state mistakes, or errors in the adapter that sends requests to a model. Separate tests of your orchestration logic from tests of external integrations.
- Use deterministic simulated model behavior to test owned workflow logic such as tool calls, handoffs, guardrails, retries, streaming, and sessions.
- Test provider request conversion and authentication at the adapter boundary, using mocked transport or the real provider where appropriate.
- Exercise the actual sandbox lifecycle and isolation when those properties matter; a simulated model interaction does not prove the infrastructure boundary works.
OpenAI’s Agents SDK documentation describes ScriptedModel for testing the SDK run loop and related behaviors without depending on a model provider. It also distinguishes those tests from provider and sandbox integration checks. See Agents SDK: Testing.
Choose a runtime by control and responsibility
The right architecture depends on who should own the agent loop, state, tools, and execution environment. OpenAI documents three starting points with different control boundaries:
| Option | Documented role | What the choice means |
|---|---|---|
| Agents API | “Run an agent with the Codex harness managed by OpenAI” | Use a managed runtime for longer-running work; inspect its session, tool, sandbox, and event concepts before adopting it. |
| Agents SDK | “Control the agent loop in your application with reusable agents, tools, and handoffs” | Your application retains control of the loop and its workflow behavior. |
| Responses API | “Work directly with model responses and control your integration” | Interact with model responses directly or use them as a foundation for a custom agent. |
These descriptions are from OpenAI’s Agents documentation. They are not interchangeable labels: compare API context, execution location, state ownership, auditability, integration boundaries, and the level of control your team needs.
Keep review and acceptance explicit
Generated tests should enter the same review path as other test code. A reviewer should be able to see the expected behavior, the assertion, the execution result, and any changes to test data or environment configuration. A passing run is evidence that the tested conditions passed; it is not proof that the suite covers every regression or that the assertions reflect the full contract.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWindows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallDo not promise a particular increase in speed, coverage, or defect detection without measurements from the actual workflow. The cited product documentation describes features and test boundaries, not quantified QA outcomes.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




