Quick wins for a faster PC:
Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →Build the proxy as a stable application-facing gateway, then make its routing policy explicit: retry eligible failures against another deployment of the same model group before switching to a configured fallback group. Keep provider credentials server-side, cap the combined retry time and attempt count, and test the features your application actually uses. A gateway can improve resilience, but it becomes infrastructure you must operate—and a fallback model may not behave like the primary one.
What the proxy does in a multi-provider architecture
An LLM proxy, or gateway, gives your application one controlled boundary for requests to multiple model providers. Instead of distributing provider-specific credentials, routing logic, and usage controls through every client, the application sends requests to the gateway. The gateway authenticates the caller, applies policy, selects an upstream deployment, translates the request as needed, and returns a response with operational telemetry.
As an Amazon Associate I earn from qualifying purchases.
LiteLLM describes its open-source interface as supporting “100+ LLMs” through an OpenAI-format interface. That is a capability claim made by the LiteLLM project; the accessed page does not state a year for the figure, and it is not an independently audited provider count. An OpenAI-compatible interface can reduce client integration work, but it does not establish that the underlying models or all their features are interchangeable.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteA typical request path
- Client to gateway: The application sends a request using a gateway credential, rather than an upstream provider key.
- Authorization and limits: The gateway checks the caller or team and applies configured access, rate, or budget controls. LiteLLM’s request-flow documentation places virtual-key validation and rate-limit checks before routing.
- Routing: The gateway resolves the client-facing model name to a model group and selects an available deployment in that group.
- Provider request: The gateway authenticates to the selected provider and maps the request into the provider’s format.
- Response and telemetry: The gateway returns the response and records usage or invokes configured callbacks. LiteLLM documents spend logging and callbacks as asynchronous work after the response.
Model group versus provider deployment
A model group is the logical name your clients request. It can have multiple deployments behind it. A provider deployment is a concrete upstream target, such as a particular provider endpoint, account, or region. Keeping these concepts separate lets the gateway first try a peer deployment that is intended to serve the same logical model, and move to a different model group only when the configured fallback policy calls for it.
#1 Best Overall

- 【AMD Ryzen 4300U True 4-Core CPU: Outperforms N95 & i3-10110U】KAMRUI P2 Mini PC is equipped with true 4-core AMD Ryzen 4300U processor built on advanced 7nm Zen2 architecture,This means you get consistent, unthrottled performance for hours on end, whether you’re running multiple browser tabs, streaming 4K content, or managing virtual machines. Compare that to Intel N95 (4 efficiency cores that throttle under load) or Intel i3-10110U (only 2 cores total), and the difference is night and day: The KAMRUI P2 AMD Ryzen 4300U (28W) is 40% faster than the Intel i3-10110U and 25% faster than the Intel N95 in multi-core tasks, ensuring smooth, lag-free performance even during heavy workloads.
- 【Integrated AMD Radeon Graphics: 2.5X Stronger for Tri 4K】The KAMRUI P2 AMD 4300U Mini PC have unlocked the full potential of the built-in AMD Radeon Vega 5 graphics with 28W power delivery, making it 2.5 times stronger than the Intel UHD graphics found in the N95 and i3-10110U. This means you can enjoy Tri 4K@60Hz displays without a single stutter, perfect for productivity setups, home theaters, or even light photo/video editing and casual gaming. While the Intel N95/i3-10110U struggle to run a single 4K display without lag, The KAMRUI AMD 4300U Mini PC handles Tri 4K effortlessly, turning your workspace into a high-efficiency hub or your living room into a premium entertainment center.
- 【Large Storage Capacity, Easy Expansion】KAMRUI Pinova P2 mini computers is equipped with 16GB LPDDR4 for faster multitasking and smooth application switching. 512GB M.2 SSD ensures fast startup, fast file transfers and plenty of storage space,eliminating slow loading times and ensuring fast responsiveness. the two storage slots (1x M.2 2280 SATA/NVMe PCIe3.0 slot, 1x M.2 2280 SATA slot) can be combined to provide up to 4TB of total storage(Not included). This gives you enough space for all your projects, media and data.
- 【4K Triple Display】KAMRUI Pinova P2 4300U mini desktop computers is equipped with HDMI2.0 ×1 +DP1.4 ×1+USB3.2 Gen2 Type-C ×1 interfaces for faster transmission, Triple 4K@60Hz Display, KAMRUI P2 mini computer is ideal for visual home entertainment, home office, conference rooms, etc. USB3.2 Gen2 Type-A port ×2 with a transfer speed of up to 10 Gbps (21 times faster than USB 2.0) for efficient data transfer. Ideal for seamless multitasking between spreadsheets, browsers and presentations, or for an immersive entertainment experience.
- 【USB3.2 Gen2 Type-C 10Gbps, Versatile connectivity】KAMRUI P2 mini desktop pc fast and versatile connectivity! The USB3.2 Gen2 Type-C port offers a data transfer rate of 10Gbps and simultaneously supports DisplayPort 1.4 video output. The P2 AMD Ryzen 4300U Mini PC is complemented by Gigabit LAN, WiFi and Bluetooth, so nothing stands in the way of a productive working environment.
Design retries and failover as separate controls
A retry repeats a request within the current model group, often against another deployment. A fallback routes the request to a different configured group, which may mean a different provider or model. LiteLLM’s Router documentation describes both same-group retries and cross-group fallbacks as separate mechanisms. Choose their order deliberately: retrying a peer may preserve intended model behavior, while switching groups may be the only useful route around a provider-wide outage.
Define which failures qualify
Do not treat every unsuccessful response as a reason to retry. Rate limits, transient server errors, and transport timeouts are common candidates for retry or fallback, but classify them according to your application and the provider behavior you observe. Invalid input, bad credentials or configuration, and policy refusals generally require a different response than an upstream availability problem. The LiteLLM documentation describes retry mechanisms; it does not define a universal error taxonomy for every provider.
For each failure class, specify whether to retry the same deployment, try a peer deployment, move to another group, or return the error to the caller. Make sure authorization and policy errors cannot be mistaken for transient availability failures.
Rank #2

- 【Great power in a small computer】Get fast performance from the AMD Ryzen 5 3500U CPU (2.1GHz-3.7GHz, 4 Cores 8 Threads) inside this mini pc, TDP 15W up to 25W. It's perfect for all your home office and business use, like daily computing, web browsing, and smooth media streaming. This small desktop computer handles everyday tasks easily and quietly.
- 【Work on many things at once with lots of storage】This mini PC comes with 16GB of fast DDR4 RAM (expandable up to 32GB), allowing you to smoothly run multiple programs, dozens of browser tabs, and large files all at once. It also features a spacious 512GB NVMe SSD that provides ample storage and delivers dramatically faster boot-ups, app launches, and file transfers compared to a traditional hard drive.
- 【See everything clearly on one or two 4K screens】Connect one or two monitors for more space to work or play. Dual HDMI ports on this mini pc support super sharp 4K Ultra HD video. It's great for doubling your work area for business or watching movies in high definition.
- 【Fast modern connections in a tiny box】Enjoy a better and more stable internet connection with the latest WiFi 6. Use Bluetooth 5.3 to connect wireless headphones, keyboards, and mice without wires. This small pc is very compact to save desk space and has extra USB ports (USB 2.0×2, USB 3.0×2, Type-c 2.0×1, Type-c 3.2 full featured×1, HDMI×2) for your printer, webcam, or other computer accessories.
- 【Reliable Warranty and Support】We provides 1 year warranty for each Mini computers. So you don't need to worry about any product problems. If you have any questions about the product, please contact our customer service, we will provide 24-hour professional technical support and serve you at any time.
Bound attempts and total time
Set both an attempt limit and an end-to-end time budget. A gateway retry can be multiplied by retries in the client library or provider SDK; if each layer retries independently, the request can take much longer than any one layer’s timeout suggests. LiteLLM documents retry configuration at several levels and notes that its Router owns retry behavior for proxy requests. Its routing documentation also describes exponential backoff for rate-limit errors with configurable retry counts and delay.
Decide how much of the caller’s latency budget is available for recovery. A retry or fallback that finishes after the application has abandoned the request may add load without helping the user. Retries may also result in additional upstream requests; check the providers’ terms and actual request behavior to understand billing rather than assuming failed attempts are free.
Make the decision path observable
For every attempt, record a correlation ID, requested model group, selected deployment and provider, attempt number, failure class, latency, and final outcome. This is an operational design recommendation, not a universal event schema prescribed by the cited product documentation. Avoid putting sensitive prompts, credentials, or unnecessary personal data in logs.
Rank #3

- 【AMD Ryzen 3 5300U CPU: Outperforms N150 & 3500U】 BOSGAME E5 mini PC is powered by the TSMC 7nm FinFET architecture AMD Ryzen 3 5300U processor (4 Cores, 8 Threads, up to 3.8GHz boost, 6MB total cache). Compared to low-end Intel N150 or 3500U chips which only have 4 single threads and throttle under load, the 5300U delivers over 30% faster multi-core speed. Run 30+ browser tabs, large Excel sheets, and Zoom meetings simultaneously without system lag.
- 【8GB DDR4 RAM & 256GB NVMe SSD Storage】 Installed with high-speed 8GB DDR4 dual-channel memory and a fast 256GB M.2 2280 SSD, eliminating slow boot times and application loading delays. To accommodate growing data requirements, the upgradeable hardware design features dual SODIMM slots that allow you to expand memory up to 64GB RAM, ensuring smooth operation during heavy multitasking.
- 【High-Capacity Dual M.2 SSD Storage Expansion】 Never worry about running out of space for your business files. In addition to the pre-installed 256GB system drive, the motherboard houses an extra empty internal M.2 2280 NVMe PCIe 3.0 slot. This allows you to easily add a second solid-state drive for up to an additional 2TB of storage capacity (upgrades not included) without needing to remove or reinstall the original operating system.
- 【Radeon 6-Core Graphics & Triple 4K Displays】 Integrated with official AMD Radeon Graphics (6 Graphics Cores, 1500 MHz frequency) for casual gaming, photo editing, and crisp 4K media decoding. Featuring 1x HDMI 2.0 port, 1x DisplayPort, and 1x Full-Function Type-C port, the E5 outputs true 4K@60Hz resolution to three monitors at once. This multi-screen setup eliminates constant window-switching for traders, programmers, and office workers.
- 【Dual 2.5GbE LAN Ports for Advanced Networking】 Experience fast wired network transmission speeds up to 2500Mbps without lagging or buffering. The integration of dual 2.5 Gigabit Ethernet ports (powered by Realtek RTL8125 controller) makes this compact computer an exceptional hardware choice for tech enthusiasts. Easily configure it into software routers, hardware firewalls (pfSense, OpnSense), home NAS servers, or local homelabs.
A conceptual request sequence is:
- Caller sends a request to the proxy.
- Proxy checks authorization, limits, and routing policy.
- Proxy calls the primary deployment.
- If the failure is eligible, proxy retries a peer deployment within the same model group.
- If that path is exhausted and policy permits it, proxy calls a configured fallback group.
- Proxy returns the successful response or surfaces an error when no eligible route remains.
Define what happens if a streaming response fails after partial output has reached the caller. Once output has been emitted, silently restarting on a different provider can duplicate or contradict content. Whether to stop, signal an error, or use another recovery behavior depends on the client protocol and workload; there is no single strategy established for all gateways.
Check compatibility instead of assuming it
An OpenAI-style request surface is an integration convenience, not a guarantee of feature parity. LiteLLM says it translates or maps provider requests. Anthropic’s guidance on other LLM gateways warns that a gateway that does not forward newer client capabilities can prevent those features from working. Treat compatibility as a tested property of each client, gateway configuration, and upstream combination.
Build a capability matrix for your workload
List the features your application depends on and test each one against every route that may receive traffic:
Rank #4

- Office Gaming Mini PC - UPGRADED GMKtec Nucbox M5 Ultra Series is equipped with the powerful AMD Ryzen 7 7730U processor, 8 Cores/16 Threads, Base 2.00GHz (Power Saving Quiet Mode) with Turbo Boost up to 4.50GHz (Performance Mode) in BIOS settings, Based on the ZEN 3+ architecture, this small but powerful mini pc delivers satisfying results in productivity, office work, and gaming. 35% Performance increase over AMD Ryzen 5 7430U/ Ryzen 7 5700U, 5600U, 5560U, 5500U.
- 16GB DDR4 RAM & 256GB PCIe SSD - Installed with DDR4 16GB RAM (1x16GB), the Nucbox M5 Ultra mini pc support expansion to 64GB RAM. Featured with 256GB M.2 2280 PCIe 3.0 SSD, support dual slot expansion to 4TB SSD. (Upgrades not included)
- DUAL NIC LAN 2.5G RJ45 - Fast Network Speeds: Enjoy up to 2500Mbps data transmission speed without worrying about lagging. Ideal for working, gaming, and surfing the internet. Great for Untangle, Pfsense or as a server office PC.
- Mini Desktop Computer with 4K Triple Screen Display - Nucbox M5 Ultra integrates AMD Radeon Graphics 8 Cores 2000 MHz GPU to deliver powerful graphics processing power to easily handle the demands of complex design software, 4K@60Hz UHD video editing, and playback. It can connect to 3 display screens simultaneously.
- Fast Internet WiFi 6E + BT5.2 Connection - GMKtec Mini PC with WiFi-6E Wireless, have 2.5G/5G/6G triple band, more faster and lower latency. Bluetooth 5.2 allowing you more quickly to connect other wireless devices (headset, mouse, keyboard, etc.) Interface features 2*USB3.2 ports, 2*USB2.0 ports, 1*HDMI 2.0 port(4K@60Hz), 1*USB-C port(PD/DP/DATA), 1*DP Port, 1*Audio 3.5mm (HP&MIC), 1*DC Power Port.
- Streaming behavior, including errors after partial output.
- Tool or function calls and their argument formats.
- Structured-output or schema-constrained responses.
- Image and audio inputs, if the application sends them.
- Context and token limits relevant to your prompts.
- Stop conditions, finish reasons, refusal behavior, and error mapping.
Record differences that affect callers. Do not claim universal support for a feature simply because a gateway accepts an OpenAI-format request. A fallback policy should also decide whether the logical model alias is allowed to change semantics and whether callers or operators can see which provider actually served the request.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Protect credentials and operate the gateway
Keep provider credentials on the server side of the proxy and issue gateway credentials to clients. A central gateway can support user or team attribution, budgets, rate limits, audit logging, and provider switching; Anthropic identifies these as functions gateways can provide. Centralization also concentrates operational responsibility: the team must maintain the gateway, keep it compatible with client features, and manage the security of its credentials and logs.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Production topology for a self-hosted gateway
LiteLLM’s production deployment guide describes monolithic and microservice options. Its documented multi-instance pattern uses stateless gateway services behind a load balancer, PostgreSQL for keys, teams, users, spend, and configuration, and Redis for shared rate limiting, router state, or cache when running multiple instances. The guide also calls out a stable salt key for encrypted provider credentials. These are LiteLLM’s documented product choices, not requirements for every custom proxy; choose state stores and topology according to the gateway you deploy.
Best Value
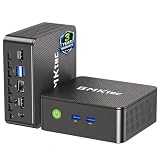
- WHY CHOOSE G3 ULTRA MINI PC PENTIUM GOLD 7505 - Choose the Intel Pentium Gold 7505 for snappier everyday responsiveness: It delivers up to 30% faster single-core performance than the Ryzen 5 3500U, making office apps and web browsing feel noticeably quicker, while its Intel UHD Graphics (48 EUs) provides 2.4x the GPU performance of the N100 & N150's 24-EU graphics, ensuring smoother 4K streaming and light photo editing.
- 16GB RAM MEMORY & 512GB STORAGE - GMKtec Nucbox G3 Ultra mini computer is prebuilt with 16GB LPDDR4 RAM at 3200 MT/s, you will enjoy a speedier experience with Built-in 512GB M.2 SATA Hard Drive. Our mini desktop pc boots up in seconds, work on multiple browser tabs, software applications and quickly transfers files. There is a primary slot and secondary expansion storage. Primary slot is M.2 2280 PCIE and secondary slot is M.2 2280 SATA.
- RICH INTERFACE - Nucbox pentium mini computer is equipped with 3* USB 3.2 Gen2 ports, up to 10Gbps/S, 1*USB 2.0, HDMI(4K@60Hz)*2, 3.5mm Audio Jack. Supports WiFi 6, and Gigabit Ethernet RJ45 2.5GbE network connectivity, Bluetooth 5.2. This Mini PC supports multiple device connection and can be used with servers, monitoring equipment, office equipment, displays, projectors, televisions, etc.
- 4K DUAL SCREEN DISPLAY - Mini desktop computer is equipped with upgraded Intel Graphics(max 1000MHz), supports 4K video playback and AV1 decoding, connect the pc with a projector as a home theatre, enjoy a variety of entertainments. Two HDMI 2.0 ports allows you to multi-task efficiently on two 4K@60Hz displays.
- UPGRADED COOLING FAN - The G3 Ultra has upgraded the cooling fan to reduce fan noise and thermals. We are using an upgraded thermal paste as well to help reduce heat on the CPU.
AWS’s reference architecture for a multi-provider generative AI gateway, whose technical accuracy was reviewed July 1, 2025, shows containers on ECS or EKS behind AWS networking and load-balancing components, with RDS, ElastiCache, Secrets Manager, and S3 logs. It includes Bedrock and external providers such as OpenAI, Anthropic, Vertex AI, and Cohere. This is an AWS-specific reference design, not a neutral benchmark or a universal deployment requirement.
Operational checks to put in place
- Monitor gateway health and readiness separately from provider-specific health signals.
- Roll out routing and credential changes in a controlled way, with a rollback path.
- Rotate secrets and confirm that every gateway replica receives the intended updated configuration.
- Check that rate-limit and router state behave consistently across instances.
- Decide whether cooldown or circuit-breaker behavior is needed to avoid repeatedly sending traffic to an unhealthy route.
- Minimize sensitive data in logs while retaining enough attempt-level detail to diagnose routing decisions.
- Alert on changes in fallback rate and end-to-end latency, not just whether the gateway process is running.
Choose self-hosted or managed routing
The choice is primarily about control and operational ownership. A self-hosted proxy gives your team control over its deployment and routing policy, but your team must scale, secure, update, and maintain it. A managed routing service removes some gateway infrastructure work, but its model scope and controls are bounded by that service.
| Decision axis | Self-hosted proxy | Managed model routing |
|---|---|---|
| Operations | Your team operates, scales, secures, and updates the gateway; compatibility maintenance remains your responsibility. | The service provider manages routing infrastructure within the service boundary. Google Cloud presents its model-routing service as an alternative to hosting and maintaining a standalone proxy. |
| Provider and model scope | Can be configured for supported providers, but coverage and feature parity depend on the proxy and its integrations. | Google Cloud’s Agent Platform routing documentation describes Gemini, Anthropic Claude, and OpenAI GPT-family models within that service context. |
| Control and portability | More control over deployment and routing policy, with continuing maintenance work. | Less gateway infrastructure to operate, with scope bounded by the service’s supported models and configuration. |
| Likely fit | Teams that need provider breadth, self-managed policy, or integration with their own environment. | Teams whose model and governance needs fit the managed service and who prefer less gateway operations. |
The fit descriptions are practical inferences from the documented capabilities, not guarantees about every organization’s requirements. Confirm current model availability, feature support, and service boundaries before committing to either design.
Quick Recap
Implementation checklist
- Set the gateway boundary: Decide which client-facing model names and caller identities the application will use.
- Map groups to deployments: Document each logical model group and the concrete provider deployments behind it.
- Write failure policy: Classify eligible failures, choose same-group retry behavior, and specify when a cross-group fallback is allowed.
- Set combined limits: Coordinate client, gateway, and SDK retry counts, timeouts, and backoff against one end-to-end latency budget.
- Test route compatibility: Exercise the capability matrix on every route that could serve production traffic.
- Protect and attribute: Keep upstream keys server-side, scope gateway credentials, and decide what usage and audit data to retain.
- Deploy redundantly where required: If the gateway is on the critical request path, plan for replica failure and the state-sharing needs of your selected implementation.
- Exercise failure paths: Verify the behavior for rate limits, timeouts, provider errors, exhausted retries, and interrupted streams before relying on automatic recovery.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




