Freedom251 › AI Talking Photo Apps
SadTalker
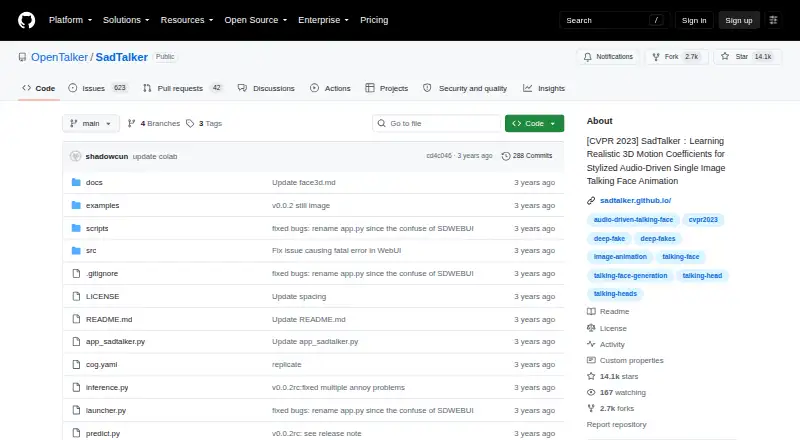
What SadTalker is
SadTalker generates a talking-head video from one portrait image and speech audio. It derives head-pose and facial-expression coefficients from audio to animate a face, with still, reference and resize modes as well as full-image animation. Command-line examples support GFPGAN enhancement, and the project links to Hugging Face and Colab demos. For local use, it documents a Gradio demo and command-line inference on Windows, Linux and macOS. Setup requires dependencies and model files: Linux instructions specify Python 3.8, PyTorch, FFmpeg and repository requirements, while Windows instructions include Python, Git, FFmpeg and model files. Pre-trained models are linked from Google Drive, GitHub Releases and Baidu. The project says its open-source code runs offline and collects no personal information or other data. SadTalker is free under Apache 2.0, except for listed third-party components, and output is 720p or lower without a watermark. The project also links a Discord integration and a Stable Diffusion WebUI extension. Its stated use restrictions prohibit unlawful or harmful use, including fraud and portrait-rights infringement.
Who it suits
It suits people seeking to create an animated talking-head video from a portrait and speech audio, including those who want local inference. Users should be prepared to install the documented dependencies and model files.
What it does well
- Creates video from a portrait and speech audio.
- Includes still, reference and resize modes.
- Documents local Gradio and command-line use.
- Runs offline, according to the project.
- Output is watermark-free.
What to know first
- Output resolution is 720p or lower.
- Setup requires dependencies and model files.
- Third-party components are excepted from the Apache 2.0 license.
Limits
Generated output is 720p or lower. The Apache 2.0 license has exceptions for listed third-party components.
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| SadTalker open-source software | Apache 2.0 except listed third-party components · offline code | Free |
As github.com lists them, read 4 Oct 2026. The maker's own page has the final word.
Getting started
- Visit the project at https://github.com/OpenTalker/SadTalker.
- Choose the documented setup path for Windows, Linux, or macOS.
- Install the dependencies specified for the selected setup path.
- Download pre-trained model files from one of the linked sources.
- Run the local Gradio demo or command-line inference, or try the linked Hugging Face or Colab demo.
SadTalker turns one portrait and a speech recording into an animated talking-head video. It is best for people comfortable installing open-source software who want a local workflow; the trade-off is a technical setup and output capped at 720p or lower.
Overview
Rather than act as a general video editor, SadTalker focuses on deriving head pose and facial-expression motion from speech. Its still, reference, resize, and full-image modes offer different ways to animate an image, while optional GFPGAN enhancement is supported in command-line examples. That focused toolset suits portrait animation, but not projects that need broader editing features or output above 720p.
The project describes its open-source code as able to run completely offline and says it collects no personal information or other data. That makes local use appealing when keeping processing on your own machine matters. The license is Apache 2.0, except for listed third-party components; the README also prohibits uses that harm others’ rights or violate law or social ethics, including fraud and portrait-rights infringement.
Key features
Portrait animation
SadTalker generates 3D head-pose and expression coefficients from audio to animate a face. The range of image modes gives users some flexibility in how they approach the source portrait, and the command-line examples support GFPGAN enhancement. Watermark-free output is a practical plus, but the 720p-or-lower ceiling rules it out when higher resolution is required.
Local use and demos
Users can run a local Gradio demo or command-line inference, or try project-linked Hugging Face and Colab demos. The README also describes Discord integration and a Stable Diffusion WebUI extension. These routes provide options for different workflows, though the local path requires installation work and downloadable models rather than a simple turnkey editor.
Pricing
SadTalker open-source software: free. The plan is open source under Apache 2.0, except for listed third-party components, and supports offline code use. It is the natural fit for users who can handle setup and want local control without a software charge. There is no paid tier or free trial; the practical cost is the time and technical effort involved in installing dependencies and models.
The documented Linux setup uses Python 3.8, PyTorch, FFmpeg, and the repository requirements. Windows setup also requires Python, Git, FFmpeg, and model files; setup paths are documented for macOS as well. Pre-trained models are linked through Google Drive, GitHub Releases, and Baidu.
Platforms
SadTalker supports Linux, macOS, Windows, and self-hosted use. This breadth is useful for people prepared to configure software on their own systems, but it does not make the setup requirements disappear.
Who it's for
Choose SadTalker if you want a free, watermark-free way to animate a portrait from speech and value offline operation enough to install and maintain an open-source project. It is less suitable if you need high-resolution output, a polished hosted editing workflow, or minimal setup. The project identifies the work as a CVPR 2023 paper by researchers affiliated with Xi’an Jiaotong University, Tencent AI Lab, and Ant Group.
Pros and cons
- Pro: Offline operation and local inference give users control over where portrait and audio processing happens.
- Pro: Free, watermark-free output avoids both a software charge and an export mark.
- Pro: Gradio, command-line, Discord, and Stable Diffusion WebUI routes accommodate more than one way of working.
- Con: Installation depends on technical components such as Python, PyTorch, FFmpeg, and model files.
- Con: Output is limited to 720p or lower, which excludes higher-resolution delivery needs.
- Con: Use is subject to the project’s stated restrictions against rights-harming or unlawful and socially unethical use.
Alternatives
AI Video Lip Sync Tools is a broader starting point for comparing lip-sync software. Choose VEED instead if web, mobile, or extension platforms suit you better; its free plan exports at 720p with a watermark, while Creator exports up to 1080p and removes the watermark. Muse is a free, open-source option for MIDI output rather than portrait animation.
CHAMELAION LipSync API may suit users looking for an API or web workflow: its free Starter tier provides 24,000 tokens and two minutes of video translation plus lip sync, with a watermark. LipDub offers API and web access; its free Seed tier includes one minute at 1080p with a watermark, alongside AI dubbing, voice cloning, and lip sync. lipsyn.cc is another API or web option, with a free five-second preview and a paid Quick Take option for five minutes.
Morph Studio is a web-based alternative for broader text- and image-to-video work, with a free tier of 75 monthly credits and 90-day asset retention. Rendley offers API and web access with a free tier and no time limit. Sync Labs may fit users seeking API or web lip-sync generation; its free tier includes three generations per month, each up to 20 seconds, plus limited text-to-speech and Sync 3 generations.
Verdict
SadTalker is a strong fit for technically comfortable users who want free, watermark-free portrait animation and offline control. Its main advantage is that local workflow; its main reasons to look elsewhere are the installation burden and 720p-or-lower output ceiling.
Verdict
SadTalker provides local and demo-based workflows for animating a portrait from speech, with offline operation described by the project. Check the setup requirements, output limit and stated use restrictions before using it.
Questions
Is SadTalker free?
Yes. Its open-source plan is free.
What license does it use?
The SadTalker license is Apache 2.0, except for listed third-party components.
Which platforms does it support?
Setup paths are documented for Windows, Linux, and macOS; the project also links online demos.
Can SadTalker run offline?
The project says its open-source code runs completely offline and collects no personal information or other data.
What output resolution does it support?
Output is 720p or lower and is watermark-free.
What does setup require?
Linux instructions include Python 3.8, PyTorch, FFmpeg, and repository requirements. Windows instructions include Python, Git, FFmpeg, and model files.
Facts from SadTalker's own pages
- Enhancement
- The CLI examples support GFPGAN enhancement for generated videos. · github.com, 4 Oct 2026
- Founded
- 2022 · github.com, 28 Sept 2026
- Integrations
- The README says SadTalker is integrated into Discord and offers a Stable Diffusion WebUI extension. · github.com, 4 Oct 2026
- License
- The repository license identifies Apache 2.0 as the SadTalker license, except for listed third-party components. · github.com, 4 Oct 2026
- Local use
- The README documents a local Gradio demo, command-line inference, and Windows, Linux, and macOS setup paths. · github.com, 4 Oct 2026
- Models
- Pre-trained models are linked for download from Google Drive, GitHub Releases, and Baidu. · github.com, 4 Oct 2026
- Modes
- The project describes still, reference, and resize modes, as well as full-image animation. · github.com, 4 Oct 2026
- Motion generation
- It generates 3D head-pose and expression coefficients from audio to animate a face. · sadtalker.github.io, 4 Oct 2026
- Offline operation
- The project says the open-source code runs completely offline and collects no personal information or other data. · github.com, 4 Oct 2026
- Online demos
- The project links to Hugging Face and Colab demos. · sadtalker.github.io, 4 Oct 2026
- Purpose
- SadTalker generates a talking-head video from a single portrait image and speech audio. · github.com, 4 Oct 2026
- Research context
- The project page identifies SadTalker as a CVPR 2023 work by researchers affiliated with Xi'an Jiaotong University, Tencent AI Lab, and Ant Group. · sadtalker.github.io, 4 Oct 2026
- Setup requirements
- The documented Linux setup uses Python 3.8, PyTorch, FFmpeg, and the repository requirements; Windows setup also requires Python, Git, FFmpeg, and model files. · github.com, 4 Oct 2026
- Support
- The README directs users to its FAQs before opening an issue and links to project discussions. · github.com, 4 Oct 2026
- Use restrictions
- The README prohibits use that harms others' rights or violates applicable law or social ethics, including fraud and portrait-rights infringement. · github.com, 4 Oct 2026
Where SadTalker stands on Freedom251
- AI Talking Photo Apps#7 of 25
- AI Video Lip Sync Tools#8 of 28