Freedom251 › Text-to-Speech Software
PaddleSpeech
What PaddleSpeech is
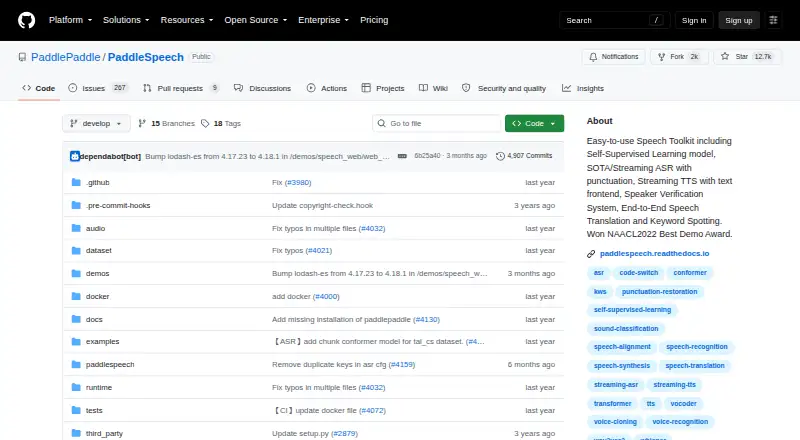
PaddleSpeech is a free, Apache-2.0 open-source toolkit for speech and audio tasks on the PaddlePaddle platform. It provides automatic speech recognition, including streaming recognition with punctuation restoration, and text-to-speech with streaming output. Its rule-based Chinese frontend performs text normalization and grapheme-to-phoneme processing, including polyphone and tone-sandhi handling. Other listed capabilities include speaker verification, keyword spotting, audio classification, speech translation, and punctuation restoration. Developers can use a command-line interface, Python APIs, a server, or a streaming server, and the project describes local deployment with client access. Models and examples use datasets such as LibriSpeech, LJSpeech, AIShell, and CSMSC. Linux, Windows, and Mac OS X are supported, with Linux and Python 3.8 or later recommended. API access, voice cloning, and WAV or PCM export are listed. Commercial use is allowed. The English-to-Chinese speech translation CLI requires precompiled Kaldi tools and is supported only on Ubuntu.
Who it suits
PaddleSpeech suits developers and researchers building speech applications, training or deploying models, and needing command-line, Python, or server interfaces. It also fits commercial use where an open-source toolkit is appropriate.
What it does well
- Free Apache-2.0 open-source toolkit
- Streaming speech recognition and synthesis
- Voice cloning and API access
- Supports Linux, Windows, and Mac OS X
- Commercial use permitted
What to know first
- Linux is recommended for installation
- Speech translation CLI supports Ubuntu only
- Requires PaddlePaddle and gcc dependencies
- No free trial is listed
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| PaddleSpeech | Apache-2.0 licensed toolkit · requires PaddlePaddle · installation recommends Linux with Python >=3.8 | Free |
As github.com lists them, read 13 Oct 2026. The maker's own page has the final word.
Verdict
PaddleSpeech combines recognition, synthesis, translation, and other audio tasks in one open-source toolkit. Its broad interfaces and platform support are useful, while the Ubuntu-only speech-translation CLI is a specific constraint.
Facts from PaddleSpeech's own pages
- API access
- Yes · github.com, 20 Sept 2026
- Audience
- The project describes its intended uses as industrial applications and academic research, including training, inference, testing, and deployment. · github.com, 12 Oct 2026
- Award
- The README states that PaddleSpeech won the NAACL 2022 Best Demo Award. · github.com, 13 Oct 2026
- Chinese frontend
- Its rule-based Chinese frontend includes text normalization and grapheme-to-phoneme processing, including polyphone and tone sandhi handling. · github.com, 13 Oct 2026
- Commercial use
- Yes · github.com, 20 Sept 2026
- Deployment
- The repository includes server examples for ASR, TTS, and audio classification, as well as streaming ASR and TTS servers. · github.com, 13 Oct 2026
- Export formats
- wav,pcm · github.com, 20 Sept 2026
- Installation
- The project recommends Linux and Python 3.8 or later; it also lists Windows and Mac OS X support. · github.com, 12 Oct 2026
- Integrations
- The README links to AI Studio demos and examples, and documents a Hugging Face Spaces TTS demo. · github.com, 13 Oct 2026
- Interfaces
- Users can try models through its command-line interface or Python, and the project provides server and streaming server options. · github.com, 13 Oct 2026
- License
- The repository states that PaddleSpeech is provided under the Apache-2.0 License. · github.com, 13 Oct 2026
- Limit
- The README says its English-to-Chinese speech translation tool requires precompiled Kaldi tools and is supported for use on Ubuntu only. · github.com, 12 Oct 2026
- Models and datasets
- The toolkit lists mainstream models and datasets including LibriSpeech, LJSpeech, AIShell, and CSMSC. · github.com, 13 Oct 2026
- Other audio tasks
- The toolkit includes speaker verification, keyword spotting, audio classification, and speech translation. · github.com, 13 Oct 2026
- Platforms
- windows,macos,linux,api · github.com, 20 Sept 2026
- Product
- PaddleSpeech is an open-source toolkit on the PaddlePaddle platform for speech and audio tasks. · github.com, 13 Oct 2026
- Purpose
- PaddleSpeech is an open-source toolkit for speech and audio tasks built on the PaddlePaddle platform. · github.com, 12 Oct 2026
- Requirements
- The README lists gcc >= 4.8.5, PaddlePaddle, and Python >= 3.8 as dependencies. · github.com, 13 Oct 2026
- Speech recognition
- It provides automatic speech recognition, including streaming ASR with punctuation restoration. · github.com, 13 Oct 2026
- Speech synthesis
- It provides text-to-speech synthesis, including a streaming TTS system and Chinese text frontend. · github.com, 13 Oct 2026
- Speech translation limit
- The documented speech translation tool translates English to Chinese and its CLI experience is supported only on Ubuntu. · github.com, 13 Oct 2026
- Support
- The project invites users to submit questions in Discussions and bug reports in Issues. · github.com, 13 Oct 2026
- Supported operating systems
- The README lists Linux, Windows, and Mac OSX as supported operating systems and recommends Linux. · github.com, 13 Oct 2026
- Voice cloning
- Yes · github.com, 20 Sept 2026
Where PaddleSpeech stands on Freedom251
- Text-to-Speech Software#51 of 223
- Text-to-speech tools#84 of 232