Freedom251 › Analytical Data Store Software
Apache Kylin
What Apache Kylin is
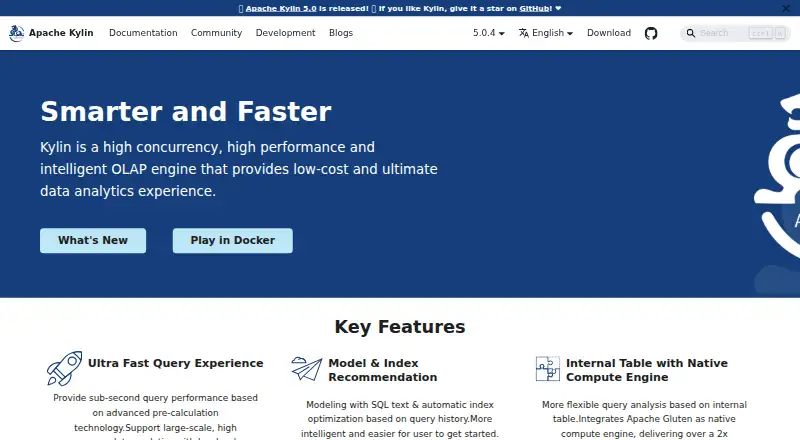
Apache Kylin is an open-source OLAP engine for data analytics, designed for large-scale queries and many concurrent users. Its pre-calculation technology is intended to support sub-second queries. Kylin 5 can create models from SQL text and recommend index optimizations using query history. It also integrates Apache Gluten as a native compute engine; the overview describes a 2–4× performance improvement compared with vanilla Spark. For combined streaming and batch analysis, Kylin supports Apache Kafka and fusion models. It can connect to Tableau, Power BI, and Excel. Its web interface supports table management, model design, job triggering, and configuration maintenance, and deployment can use query, job, or all server modes. Kylin uses Apache Spark for compute with Yarn or Standalone mode. Data storage can use HDFS or S3-compatible file systems, while metadata can use MySQL or PostgreSQL. It runs on Linux and is distributed under the Apache License v2. The listed free plan costs nothing, with source and binary packages available.
Who it suits
Apache Kylin suits teams running analytics on Linux that need SQL-based modeling, concurrent queries, or streaming and batch analysis. It also fits environments using the listed BI tools and storage systems.
What it does well
- Designed for sub-second queries and high concurrency.
- Models can be created from SQL text.
- Supports Kafka and streaming-batch fusion models.
- Connects to Tableau, Power BI, and Excel.
- Provides query, job, or all server deployment modes.
What to know first
- The environment documentation lists Linux-only support.
- HTTPS is disabled by default in Kylin 5.
- Requires Apache Spark for compute.
Limits
The plan is listed as free. The facts state no free-plan quotas or feature limits.
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| Apache Kylin | Open source OLAP engine · source and binary packages available under Apache License v2 | Free |
As kylin.apache.org lists them, read 8 Oct 2026. The maker's own page has the final word.
Getting started
- Visit https://kylin.apache.org/.
- Choose the source or binary package; version 5.0.4 is offered.
- Deploy on a Linux operating system.
- Configure Apache Spark with Yarn or Standalone mode.
- Select HDFS or S3-compatible storage and MySQL or PostgreSQL for metadata.
- Use the web UI to manage tables, design models, trigger jobs, and maintain configurations.
Apache Kylin is an open-source OLAP engine for SQL analytics, aimed at teams operating large data platforms on Linux. It is strongest when fast, concurrent BI queries and streaming-plus-batch analysis justify a substantial self-hosted deployment.
Overview
Kylin uses pre-calculation to target sub-second queries for large, high-concurrency analytics workloads. That approach suits dashboards and repeated analytical queries, where many users need timely results. The trade-off is operational: Kylin depends on Spark for compute, HDFS or S3-compatible storage, and MySQL or PostgreSQL for metadata, so it is a better fit for teams already equipped to run data infrastructure than for organizations seeking a managed, low-maintenance service.
The Apache Software Foundation distributes Kylin under Apache License v2. Version 5.0.4 is offered as source and binary packages, along with ASC and SHA-256 verification files. SQL and row-level security are supported.
Key features
Modeling and query performance
Pre-calculation is the core performance strategy: it is designed to deliver sub-second queries while handling large numbers of concurrent analytics requests. Kylin 5 can create models from SQL text and recommend index optimizations using query history, which gives teams a way to tune models around observed workloads. The payoff is most relevant when query patterns are recurring enough to benefit from modeled data.
Kylin 5 also integrates Apache Gluten as a native compute engine. The project overview describes a 2–4× performance improvement compared with vanilla Spark, making this an appealing option for teams already using Spark that want to pursue faster computation within Kylin.
Streaming, batch, and BI
Kylin accepts Apache Kafka as a streaming data source and supports fusion models for analyzing streaming and batch data together. This can suit organizations that need both incoming data and established analytical datasets in one modeling environment. Its named BI connections include Tableau, Power BI, and Excel, allowing existing reporting workflows to connect to Kylin.
Management and security
Kylin Server's web interface supports table management, model design, job triggering, and configuration maintenance. Deployments can use query, job, or all server modes, offering flexibility in how teams assign server responsibilities. Kylin 5 supports HTTPS, but it is disabled by default; teams should account for enabling it and configuring either a bundled or third-party certificate.
API authentication uses Basic Authentication. An API request can store authentication information in cookies for subsequent visits. The project directs general and security-feature questions to its user and developer mailing lists, and undisclosed vulnerability reports to the Apache security address.
Pricing
Apache Kylin is free and open source. The Apache Kylin plan costs nothing and provides the OLAP engine through source and binary packages under Apache License v2. There is no free trial because the software is already available without charge. The license removes a software purchase price, but it does not remove the technical work of operating Spark, storage, metadata, and the Kylin deployment.
Platforms
Kylin supports Linux operating systems only. It is self-hosted, provides a web interface, and has an API. Deployment documentation describes Spark compute running in Yarn or Standalone mode, HDFS or S3-compatible storage, and MySQL or PostgreSQL metadata. The Linux restriction and infrastructure requirements rule it out for teams that need a broadly supported desktop or managed cloud application.
Who it's for
Kylin is best for data engineering and analytics teams with Linux and Spark operations in place, especially those serving concurrent BI workloads or combining Kafka streams with batch analysis. SQL-based modeling, row-level security, and connections to established BI tools support organizational analytics use. It is a weaker choice for small teams without infrastructure expertise or anyone requiring non-Linux deployment.
Pros and cons
- Pros: Pre-calculation is designed for sub-second queries at high concurrency, a meaningful fit for busy analytical workloads.
- Pros: Kafka support and fusion models bring streaming and batch analysis into the same platform.
- Pros: SQL-based model creation, query-history-driven index recommendations, and named Tableau, Power BI, and Excel connections support established analytics workflows.
- Pros: Apache License v2 and free source and binary packages avoid software licensing costs.
- Cons: Linux-only support excludes teams whose deployment standard is another operating system.
- Cons: Spark, storage, and metadata dependencies demand infrastructure ownership rather than a lightweight installation.
- Cons: HTTPS is off by default, so secure deployments require deliberate configuration.
Alternatives
For a free SQL query engine with self-hosted deployment, consider PrestoDB. Apache Drill is another free Apache-licensed option, with embedded or cluster deployment. Choose Apache Hive for open-source data warehouse software, or Apache Impala for free Apache-licensed software with source and binary releases.
Comunica is free and available under the MIT license for open and commercial projects, with support for more operating systems than Kylin. Denodo Platform has a free Developer plan with a single server, four cores, 50 data products, and 2.5 TB per year, alongside unlimited data sources, consumers, and Data Marketplace users. Starburst Galaxy offers a free tier for up to three clusters and standard execution for ad hoc queries, as well as a Pro plan starting on request. Apache Arrow DataFusion is a free Rust library and CLI distributed as source artifacts, with Linux, macOS, and self-hosted platforms.
Browse Query Engine Software, OLAP Databases, and OLAP Software for more options.
Verdict
Choose Apache Kylin if your team runs Linux and Spark-based data infrastructure and needs high-concurrency SQL analytics, particularly across streaming and batch data. Its pre-calculation approach, modeling tools, and BI connections make a strong case for demanding workloads without software license fees. Look elsewhere if you need a managed service, a lighter operational footprint, or support beyond Linux.
Verdict
Apache Kylin offers an OLAP engine with SQL modeling, streaming support, and connections to named BI tools. Its Linux-only support and deployment requirements are important considerations.
Questions
How much does Apache Kylin cost?
The Apache Kylin plan is listed as free, and the pricing model is free.
Is Apache Kylin open source?
Yes. The project is distributed under Apache License v2.
Which operating systems does Kylin support?
The environment documentation says Kylin supports Linux operating systems only.
Which storage and metadata systems can it use?
It supports HDFS or S3-compatible file systems for data storage, and MySQL or PostgreSQL for metadata.
Can Kylin analyze streaming data?
Yes. It supports Apache Kafka as a streaming source and fusion models for streaming and batch analysis.
Which BI tools can connect to Kylin?
The product page names Tableau, Power BI, and Excel.
Facts from Apache Kylin's own pages
- API security
- Kylin's APIs use Basic Authentication, and users can authenticate through an API request that stores authentication information in cookies for later visits. · kylin.apache.org, 8 Oct 2026
- BI integrations
- The product page names Tableau, Power BI, and Excel as BI tools it can connect to. · kylin.apache.org, 8 Oct 2026
- Compute
- Kylin 5 integrates Apache Gluten as a native compute engine; the overview describes 2–4× performance improvement compared with vanilla Spark. · kylin.apache.org, 8 Oct 2026
- Deployment
- Kylin provides a web UI and can be deployed with query, job, or all server modes. · kylin.apache.org, 8 Oct 2026
- Downloads
- The download page offers version 5.0.4 source and binary packages, with ASC and SHA-256 verification files. · kylin.apache.org, 8 Oct 2026
- Founded
- 2014 · kylin.apache.org, 28 Sept 2026
- HTTPS
- Kylin 5 supports HTTPS, which the documentation says is disabled by default; it supports a bundled certificate or third-party certificates. · kylin.apache.org, 8 Oct 2026
- Internal tables
- Kylin 5 supports internal tables for flexible queries and lakehouse scenarios. · kylin.apache.org, 8 Oct 2026
- License
- The project homepage states that Apache Kylin is distributed under the Apache License v2. · kylin.apache.org, 8 Oct 2026
- License and maker
- The site identifies Apache Kylin as an Apache Software Foundation project distributed under the Apache License v2. · kylin.apache.org, 8 Oct 2026
- Modeling
- Kylin 5 can create models from SQL text and recommend index optimizations based on query history. · kylin.apache.org, 8 Oct 2026
- Operating system
- The environment check documentation says Kylin supports Linux operating systems only. · kylin.apache.org, 8 Oct 2026
- Product
- Apache Kylin is an open source OLAP engine for big data analytics, designed for sub-second queries on trillions of records. · kylin.apache.org, 8 Oct 2026
- Query performance
- The product site describes sub-second queries using pre-calculation technology and support for large-scale, high-concurrency analytics. · kylin.apache.org, 8 Oct 2026
- Query speed
- Its pre-calculation technology is designed to provide sub-second queries and support large-scale, high-concurrency analytics. · kylin.apache.org, 8 Oct 2026
- Storage
- Kylin supports HDFS or S3-compatible file systems for data storage, and MySQL or PostgreSQL for metadata. · kylin.apache.org, 8 Oct 2026
- Streaming
- Kylin supports Apache Kafka as a streaming data source and fusion models for streaming and batch analysis. · kylin.apache.org, 8 Oct 2026
- Support
- The project directs users to its user mailing list and Apache Kylin JIRA for questions and issues. · kylin.apache.org, 8 Oct 2026
- Technical requirements
- Deployment documentation says Kylin uses Apache Spark for compute, supports Yarn or Standalone mode, and supports MySQL or PostgreSQL for metadata. · kylin.apache.org, 8 Oct 2026
- Web interface
- Kylin Server provides a web UI for managing tables, designing models, triggering jobs, and maintaining configurations. · kylin.apache.org, 8 Oct 2026
Where Apache Kylin stands on Freedom251
- Analytical Data Store Software#4 of 28
- OLAP Software#5 of 32
- Analytics Databases#6 of 31
- Query Engine Software#6 of 28
- OLAP Databases#7 of 30
- Big Data Analytics Software#8 of 30