Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →NVIDIA is the clear leader in merchant data-center AI accelerators as of August 10, 2026. AMD is the main general-purpose alternative. Google, AWS, Microsoft and Meta have built powerful custom chips for their own cloud or platform workloads, while Broadcom supplies much of the custom silicon, networking and optical infrastructure behind hyperscale AI.
Huawei is especially important in China and sovereign infrastructure. Cerebras, Groq, SambaNova and Intel compete in narrower inference or enterprise niches. Apple, Qualcomm and MediaTek are major on-device AI chip makers, but their phone and PC NPUs should not be ranked directly against HBM-equipped data-center accelerators.

As an Amazon Associate I earn from qualifying purchases.
There is therefore no honest universal top-10 ranking. The right choice depends on whether you need model training, fine-tuning, inference, cloud capacity, on-premises hardware, sovereign deployment or low-power edge AI.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →The short answer
For most data-center AI deployments, NVIDIA remains the safest overall choice. Its advantage combines GPU performance with CUDA, mature libraries, networking, rack-scale systems, cloud availability and a large base of developers and optimized models.
#1 Best Overall
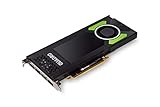
- This Quadro P4000 is based on NVIDIA Pascal architecture and delivers up to 70% more performance than the NVIDIA maxwell-based Quadro M4000, system interface - PCI Express 3.0 x16
- With greater Graphics performance you can work with large models, scenes, and assemblies with improved interactive performance during design, visualization, and simulation.
- The P4000 is the most powerful, single slot VR Ready Professional visual computing solution.
- Tuned and tested drivers with support for the latest releases of OpenGL, DirectX, Vulkan, and NVIDIA CUDA ensure compatibility with the latest versions of professional applications.
- Creation and playback of HDR video H.264/hevc decode and encode engines.Supported platforms: Microsoft Windows 10 (64- and 32-bit), Microsoft Windows 8.1 and 8 (64- and 32-bit), Microsoft Windows 7 (64- and 32-bit), Microsoft Windows Server 2008 (64- and 32-bit), Microsoft Windows Server 2012, Microsoft Windows Server 2012 R2 64, Microsoft Windows Server 2016, Linux – Full OpenGL implementation, complete with NVIDIA and ARB extensions (64- and 32-bit)
- Best overall merchant accelerator: NVIDIA
- Best general-purpose alternative: AMD Instinct
- Best captive cloud silicon: Google TPU and AWS Trainium, depending on the cloud and workload
- Most important custom-ASIC and networking supplier: Broadcom
- Important internal platform chips: Microsoft Maia and Meta MTIA
- China-focused AI infrastructure leader: Huawei Ascend
- Specialized inference contenders: Cerebras, Groq and SambaNova
- Important edge-AI suppliers: Apple, Qualcomm and MediaTek
This answer separates companies that sell accelerators to many customers from hyperscalers that mostly use their chips internally, and from suppliers that design or manufacture the components without selling a conventional GPU card.
What counts as an AI chip maker?
The term AI chip maker covers several different businesses:
- Merchant accelerator designer: designs and sells chips or complete systems to many customers. NVIDIA and AMD are the clearest examples.
- Custom-silicon designer: creates an accelerator for a particular hyperscaler, model company or large customer. Broadcom is a major example.
- Hyperscaler chip developer: designs internal processors and exposes them mainly through its own cloud or services. Google TPU, AWS Trainium, Microsoft Maia and Meta MTIA fit this model.
- Specialist accelerator vendor: targets a particular workload, such as low-latency inference or wafer-scale dataflow computing. Cerebras, Groq and SambaNova belong here.
- Edge-AI chip supplier: integrates an NPU into a phone, laptop or embedded device. Apple, Qualcomm and MediaTek are prominent examples.
- Foundry, memory or packaging supplier: manufactures or enables AI chips but may not design the accelerator. TSMC, Samsung, SK hynix and Micron are crucial to the supply chain, but they should not be placed in the same ranking as NVIDIA.
This distinction matters because a company can be strategically important without offering a chip that an ordinary buyer can purchase as a PCIe card or server component.
Top AI chip makers compared
| Company | Role and products | Main workloads | Who can access it? | Main advantage | Main limitation |
|---|---|---|---|---|---|
| NVIDIA | Merchant GPUs, networking and complete AI systems | Training, fine-tuning, inference and HPC | Cloud providers, OEMs and on-premises buyers | CUDA platform, broad software support and scale | Cost, supply dependence and ecosystem lock-in |
| AMD | Instinct MI350/MI355X and upcoming MI400 systems | Training, inference and HPC | Cloud and enterprise buyers | Large memory configurations and a non-NVIDIA path | ROCm compatibility and optimization require testing |
| TPU, including Ironwood and TPU 8-series | Large-scale training and inference | Primarily Google Cloud customers | Efficient tightly integrated cloud platform | Cloud, region and software-stack dependence | |
| AWS | Trainium3 and Inferentia | Cloud training and inference | Primarily through AWS EC2, SageMaker and Bedrock | AWS integration and potential cloud economics | AWS Neuron migration and AWS lock-in |
| Broadcom | Custom AI ASIC design, networking and optical connectivity | Hyperscaler training and inference infrastructure | Large customers and system partners | Behind-the-scenes custom silicon and networking scale | Not a conventional merchant GPU supplier |
| Microsoft | Maia 200 inference accelerator | Azure inference | Azure services and selected previews | Purpose-built Microsoft infrastructure | Not generally sold as a standalone accelerator |
| Meta | MTIA custom silicon | Recommendation and generative-AI inference | Mostly Meta’s own infrastructure | Workload-specific efficiency at massive internal scale | Not an external merchant product |
| Huawei | Ascend accelerators and Atlas systems | China-focused training and inference | Primarily Chinese and sovereign deployments | Domestic ecosystem and supply-chain relevance | Export controls, availability and software constraints |
| Cerebras | Wafer-Scale Engine and CS-3 systems | High-throughput inference and dataflow workloads | Cloud and complete-system deployments | Very large on-wafer compute and memory architecture | Different deployment and programming model |
| Groq | Language Processing Unit and inference cloud | Predictable, low-latency inference | Primarily through Groq services and partners | Fast and deterministic token generation for supported models | Narrower workload and ecosystem fit |
| SambaNova | Dataflow AI systems and SN50 | Enterprise and agentic inference | Cloud and enterprise systems | Dataflow execution and integrated deployment | Less general-purpose than mainstream GPU platforms |
| Intel | Gaudi 3 and upcoming Crescent Island | Enterprise AI and inference | Cloud, OEM and enterprise buyers | Ethernet-based systems and established enterprise presence | Not currently a peer to NVIDIA for frontier training |
| Apple, Qualcomm and MediaTek | Integrated phone and PC NPUs | On-device AI | Devices using their platforms | Low power, privacy and local processing | Not designed for frontier-model data-center training |
The maturity and evidence column also matters when comparing these products. NVIDIA and AMD have broad merchant availability; hyperscaler products are often backed by company specifications and cloud listings; specialist products may have strong results for particular models but fewer apples-to-apples public tests.
1. NVIDIA: the clear merchant-market leader
NVIDIA is the strongest single answer to the question of which company leads AI chips. That statement refers specifically to merchant data-center accelerators: hardware sold or rented to many independent customers, rather than all AI silicon including internal ASICs and smartphone NPUs.
NVIDIA reported Q1 fiscal 2027 Data Center revenue of $75.2 billion, up 92% year over year. Its fiscal 2026 Data Center revenue was $193.7 billion, up 68%. Those figures include more than an individual GPU: NVIDIA sells a platform spanning accelerators, NVLink and NVSwitch, networking, rack-scale systems, software and support.
Why NVIDIA remains ahead
- CUDA: the dominant developer and deployment ecosystem for GPU-accelerated AI.
- Libraries and tools: CUDA-X libraries, TensorRT, profiling tools and optimized implementations for common operations.
- Scale-up and scale-out: NVLink, NVSwitch, InfiniBand and Ethernet networking help connect large accelerator clusters.
- Availability: NVIDIA systems are offered by major clouds, OEMs and specialist infrastructure providers.
- Portability: a model developed on one NVIDIA cloud can usually be moved more easily to another NVIDIA-based environment than to a different accelerator architecture.
The Portuguese Competition Authority’s analysis of access to AI chips places NVIDIA above 90% of discrete data-center GPU share. The same report cites known cluster data of approximately 88% for NVIDIA, 7% for AMD and 4% for Google. These figures do not represent the entire AI-accelerator market: they exclude or underrepresent many custom ASICs and depend on the measured denominator. Read the competition analysis.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteProducts and buying profile
As of 2026, NVIDIA’s active roadmap includes Blackwell and Blackwell Ultra, followed by Vera Rubin. NVIDIA says Rubin-based instances will be deployed by AWS, Google Cloud, Microsoft Azure and Oracle Cloud Infrastructure. NVIDIA’s fiscal 2026 results and its Vera Rubin production announcement describe the roadmap.
Best for: frontier-model pre-training, distributed training, mixed workloads, on-premises clusters, broad framework compatibility and organizations that want the least migration risk.
Trade-offs: NVIDIA hardware is expensive, power-dense and subject to supply constraints. CUDA can also create switching costs. Export controls affect which products can be shipped to China. NVIDIA’s SEC filing says licenses are required for certain China exports and that limited H200 shipments to specific Chinese customers were permitted in 2026.
Do not repeat the claim that NVIDIA owns 80% or 90% of “all AI chips” without defining the denominator. NVIDIA’s position is overwhelming in merchant data-center GPUs, but custom cloud ASICs, edge NPUs, networking chips and memory are different markets.
Recommended Free Tools
2. AMD: the strongest general-purpose alternative
AMD is the main non-NVIDIA option for buyers who need a broadly capable data-center accelerator. Its Instinct MI350X and MI355X target large-scale training, inference and high-performance computing, with high HBM capacity and AMD’s ROCm software platform. AMD Instinct MI350 information.
AMD reported about $6.7 billion in Q2 fiscal 2026 Data Center revenue, up 107% year over year. That segment includes EPYC CPUs as well as Instinct GPUs, so the number is not a pure AI-chip revenue comparison with NVIDIA’s Data Center figure. See AMD’s results.
AMD’s MI400 family and Helios rack-scale system are scheduled for customer shipments in the second half of 2026. Helios combines MI455X GPUs with EPYC Venice CPUs, Pensando networking and ROCm. AMD has also announced a planned deployment of up to 6 gigawatts of GPUs with Meta, with first-gigawatt shipments expected in the second half of 2026. MI400 details and the AMD–Meta announcement.
Where AMD makes sense
- Organizations that want a second source for large accelerator deployments.
- Workloads that benefit from high HBM capacity and bandwidth.
- Teams that prefer a more open software and hardware strategy.
- Cloud or OEM buyers able to validate ROCm support for their exact models.
ROCm is substantially more capable than the early alternatives to CUDA, but compatibility should never be assumed. Test the exact PyTorch version, attention kernels, quantization path, MoE routing, distributed collectives and inference server. A theoretical performance advantage disappears if the model runs with missing kernels or low utilization.
Free tools Windows power users keep installed
One-click scans. No signup required.
Best for: large-memory training and inference, HPC, supply diversification and buyers willing to validate their software stack.
Trade-offs: AMD’s merchant share remains far below NVIDIA’s, and ROCm optimization coverage is less uniform across models and third-party tools. Many performance projections are vendor measurements or forecasts rather than independent end-to-end results.
Rank #2

- Powered by the NVIDIA Blackwell architecture and DLSS 4 OC mode: 2640MHz/Default mode: 2610MHz (Boost Clock)
- Military-grade components deliver rock-solid power and longer lifespan for ultimate durability
- Protective PCB coating helps protect against short circuits caused by moisture, dust, or debris
- 3.125-slot design with massive fin array optimized for airflow from three Axial-tech fans
- Phase-change GPU thermal pad helps ensure optimal thermal performance and longevity, outlasting traditional thermal paste for graphics cards under heavy loads
3. Google: the TPU platform
Google’s Tensor Processing Units are custom accelerators designed around Google’s software and cloud infrastructure. They can be highly competitive for organizations that are comfortable using Google Cloud, JAX and OpenXLA, but they are not normally purchased as standalone PCIe cards.
Google’s seventh-generation Ironwood TPU is generally available for training, reasoning and inference. Google lists up to 9,216 chips per pod and 42.5 exaflops per pod, and says Ironwood delivers four times the per-chip performance of Trillium. Google’s product page also lists TPU 8t for training and TPU 8i for inference as coming soon. Google Cloud TPU documentation.
Google publicly lists Ironwood on-demand pricing at $12 per chip-hour in us-central1 and $13.20 per chip-hour in europe-west2. That is a cloud chip-hour price, not a directly comparable whole-system GPU price. It excludes the many factors that determine total cost, including host resources, storage, networking, utilization, reservation terms and engineering effort. Google TPU pricing.
The software path centers on JAX, OpenXLA and PyTorch/XLA. This can work extremely well for models designed around that stack, but it differs from the CUDA and TensorRT workflow many AI teams already use.
Best for: Google Cloud customers, JAX/OpenXLA workloads, very large training jobs and inference deployments that can be optimized for TPU.
Trade-offs: region and capacity dependence, TPU-specific compilation and debugging, and less drop-in portability than a CUDA-based system.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
4. AWS: Trainium and Inferentia
AWS develops its own AI chips to reduce dependence on merchant accelerators and improve the economics of workloads running inside AWS. Trainium targets training and large-scale inference; Inferentia is focused primarily on inference.
Trainium3 UltraServers are generally available and use AWS’s first 3-nanometer AI chip. AWS claims up to 4.4 times more compute, four times better energy efficiency and nearly four times more memory bandwidth than Trainium2 UltraServers. A Trn3 UltraServer scales to 144 Trainium3 chips and up to 362 FP8 petaflops, according to AWS. These are AWS’s product claims and should not be treated as independent apples-to-apples benchmark results. AWS Trainium3 announcement.
AWS Neuron is the software stack for Trainium and Inferentia. It supports PyTorch, JAX, distributed training and custom-kernel development. AWS Neuron documentation.
Trainium is normally accessed through AWS EC2, SageMaker and Bedrock rather than bought as an ordinary accelerator card. That access model is the central trade-off:
- Advantage: AWS-native organizations can use existing identity, storage, orchestration and managed-AI services.
- Risk: moving a model to or from Trainium can require Neuron-specific engineering.
- Operational issue: regional capacity, reservations and queue availability can matter as much as the chip specification.
Best for: AWS-native companies running large training or inference workloads and optimizing total cloud cost within AWS.
Trade-offs: cloud lock-in, Neuron migration work and limited usefulness for teams seeking portable on-premises hardware.
5. Broadcom: the custom-silicon and networking enabler
Broadcom belongs on a list of top AI chip companies, but not as a conventional GPU competitor. Its importance comes from designing custom accelerators for hyperscalers and supplying the networking, switching, optical interconnect and packaging technologies needed to connect large AI clusters.
Broadcom reported $10.8 billion in AI semiconductor revenue in Q2 fiscal 2026, up 143% year over year, and guided to $16 billion in AI semiconductor revenue for Q3. The figure includes custom accelerators and AI networking, so it cannot be compared directly with NVIDIA GPU revenue. Broadcom’s Q2 fiscal 2026 results.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallCrashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteBroadcom has disclosed collaborations involving Meta’s MTIA program and OpenAI-designed accelerators. Meta–Broadcom partnership and the OpenAI–Broadcom collaboration.
Broadcom’s role includes custom XPU design, chiplets, switches, optical connectivity and system-level integration. Its customers can obtain a highly tailored accelerator, but most readers cannot buy a Broadcom AI accelerator in the same way they can buy an NVIDIA or AMD card.
Best for: understanding the supply side of hyperscaler AI infrastructure and custom-ASIC growth.
Rank #3

- Bus Type: PCI Express 3.0 x16
- Graphics Engine: NVIDIA Tesla K40
- Memory: 12 GB GDDR5
Trade-offs: customer concentration, limited public product detail and dependence on a small number of very large buyers. Calling Broadcom the second-largest AI chip company without defining the measurement is misleading.
6. Microsoft: Maia 200 for Azure inference
Microsoft’s Maia 200 is a custom inference accelerator designed for Microsoft’s Azure infrastructure. Microsoft says it is built on TSMC’s 3-nanometer process and includes 216GB of HBM3e, 7TB/s of memory bandwidth, more than 10 FP4 petaflops, more than 5 FP8 petaflops and a 750-watt SoC TDP. Microsoft’s Maia 200 announcement.
Maia 200 is deployed in Azure’s US Central region near Des Moines, with US West 3 near Phoenix planned. Microsoft is previewing a Maia SDK with PyTorch and Triton support.
Maia is strategically important because it lets Microsoft optimize its own inference infrastructure, but it is not currently a generally purchasable standalone alternative to NVIDIA GPUs. Claims that Maia is faster or cheaper than TPU, Trainium or NVIDIA should be attributed to Microsoft unless an independent, controlled benchmark establishes the comparison.
7. Meta: MTIA at internal scale
Meta’s MTIA family is designed around the company’s own ranking, recommendation and generative-AI workloads. Meta says it deploys hundreds of thousands of MTIA chips for inference across its applications and is developing four new generations within two years. Meta’s MTIA roadmap.
MTIA 300 is in production for ranking and recommendation training. Meta says MTIA 400, 450 and 500 will expand into generative-AI inference. This is an example of a custom chip succeeding by being optimized for a known workload and a controlled software environment.
Meta continues to use NVIDIA and AMD hardware, however. MTIA is therefore a workload-specific complement rather than evidence that Meta has replaced merchant GPUs. Outside customers generally access Meta’s infrastructure indirectly through Meta’s products and services, not by ordering MTIA cards.
8. Huawei: China-focused and sovereign AI infrastructure
Huawei Ascend is the most important publicly documented Chinese AI-compute platform in this comparison. Its significance is partly technical and partly geopolitical: export controls, Chinese domestic procurement and supply constraints alter which systems are available in China and in other sovereign deployments.
Huawei says its Ascend 910C powers Atlas 900 A3 SuperPoD systems containing up to 384 chips, and that more than 300 systems had been deployed to more than 20 customers by September 2025. These are Huawei-reported figures, not independent benchmark results. Huawei’s Ascend roadmap.
Huawei announced Ascend 950PR for the first quarter of 2026 and Ascend 950DT for the fourth quarter of 2026, with future plans extending to Ascend 960 and 970. Actual availability, software compatibility and deployment scale should be checked for the buyer’s geography and procurement channel.
U.S. advanced-computing export controls and Chinese domestic purchasing policies materially reshape the market. Bureau of Industry and Security controls and NVIDIA’s regulatory filing illustrate why a global ranking may not describe the practical choices available in China.
Other Chinese accelerator companies include Cambricon, Biren, Hygon and Moore Threads. They should be assessed separately from global merchant rankings because domestic software ecosystems, import restrictions and local supply chains can be decisive.
9. Specialized inference companies
Cerebras: wafer-scale systems
Cerebras takes a fundamentally different approach from a conventional multi-GPU server. Its WSE-3 uses wafer-scale integration with approximately 900,000 compute cores, and the CS-3 is sold as a complete AI system rather than a plug-in GPU. Cerebras WSE-3 and Cerebras CS-3.
Windows Errors? Fix Them Before They Spread
Repair common Windows errors and clear accumulated junk for a smoother, more stable PC - no reinstall needed.Free scan · no reinstallOutdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchThe architecture is particularly relevant to large-memory, dataflow and high-throughput inference use cases. Cerebras announced a multiyear agreement to deploy 750 megawatts of wafer-scale systems for OpenAI customers beginning in 2026. OpenAI–Cerebras announcement.
Best for: workloads where very high throughput or low latency benefits from Cerebras’s wafer-scale architecture.
Limitation: it is not a universal replacement for a CUDA GPU cluster. System availability, supported models and software integration must be evaluated directly.
Groq: deterministic, low-latency inference
Groq’s Language Processing Unit uses large on-chip SRAM, static scheduling, a custom compiler and direct chip-to-chip connectivity. The design aims for predictable latency and fast token generation for supported inference workloads. Groq LPU architecture.
Free tools Windows power users keep installed
One-click scans. No signup required.
Rank #4

- GPU Computing Processor
- 16GB HBM2
- PCIe 3.0 x16
- Fanless - Passive Cooling
- 3584 CUDA Cores
Groq and NVIDIA signed a non-exclusive inference-technology licensing agreement in December 2025. Groq said it would remain an independent company. In June 2026, Groq announced a $650 million funding round and said it operated 13 data centers across multiple regions; those are company-reported figures. Licensing agreement and funding announcement.
Best for: interactive applications with strict response-time targets and models supported by Groq’s compiler and service.
Limitation: headline claims such as fastest inference are meaningful only when the model, quantization, batch size, concurrency and latency metric are specified.
SambaNova: dataflow inference
SambaNova targets enterprise and agentic-AI inference with integrated dataflow systems. Its SN50 platform is positioned for high-speed inference and has been associated with collaborations involving Intel. SambaNova’s SN50 announcement.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →SambaNova can be attractive when a buyer wants an integrated system rather than a general-purpose accelerator cluster. It should not be treated as interchangeable with NVIDIA or AMD: model compatibility, serving tools, precision support and deployment form factor determine whether its specialization is useful.
10. Intel: an enterprise alternative with a narrower current position
Intel Gaudi 3 is available in OAM and PCIe forms, uses Ethernet networking and supports common frameworks including PyTorch. Intel Gaudi 3.
Intel’s future Crescent Island data-center GPU is focused on inference. Intel lists 160GB of LPDDR5X memory and expects customer sampling in the second half of 2026. Crescent Island announcement.
Intel matters to enterprise buyers seeking an alternative ecosystem, Ethernet-based scale-out or integration with existing Intel infrastructure. It should currently be described as a challenger and enterprise option, not as a peer to NVIDIA for frontier-model training.
Recommended Free Tools
11. Apple, Qualcomm and MediaTek: top edge-AI chip makers
On-device AI is a separate market from data-center AI. Phones and laptops prioritize battery life, thermal limits, privacy, local responsiveness and unified memory. A data-center accelerator prioritizes HBM capacity, bandwidth, scale-out networking and sustained cluster throughput.
- Apple: the M4 Neural Engine is rated at up to 38 trillion operations per second. Apple M4.
- Qualcomm: the Snapdragon X Elite advertises up to 45 TOPS from its Hexagon NPU. Snapdragon X Elite.
- MediaTek: the Dimensity 9500 uses an NPU 990 and compute-in-memory NPU aimed at low-power smartphone inference. Dimensity 9500.
AMD, Intel and NVIDIA also supply chips or platforms for AI PCs and edge systems. But Apple’s 38 TOPS and Qualcomm’s 45 TOPS should not be compared directly with data-center FP8, FP4, BF16 or HBM-based accelerator figures. TOPS, FLOPS, precision, memory and power envelope all describe different things.
Why the supply chain matters: HBM, packaging and networking
The AI-chip contest is not only about who designs the accelerator. High-bandwidth memory, advanced packaging, power delivery, cooling and networking can determine whether a product ships at scale.
TSMC’s CoWoS packaging integrates accelerator dies with HBM in a compact package, a critical capability for modern AI systems. SK hynix, Samsung and Micron are major HBM suppliers. Micron lists HBM4 bandwidth above 2.8TB/s per stack, while Samsung lists HBM4 speeds of up to 13Gbps per pin. These supplier figures describe technology capability, not necessarily the performance of a complete AI system. TSMC CoWoS, Micron HBM4 and Samsung HBM4.
Do these 3 things before closing this tab:
1Repair Windows errors before they cause bigger problems2Fix the driver behind crashes, sound loss and screen glitches3Clear out junk files and repair common Windows errorsThis is why a comparison between isolated chip specifications can be misleading. A production system may be constrained by HBM supply, advanced packaging capacity, switch bandwidth, rack power, liquid cooling or the availability of a complete OEM configuration.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.How to choose the right AI chip
Instead of asking which chip is best, start with the workload and deployment constraints.
Step 1: Identify the workload
- Pre-training: prioritize distributed compute, accelerator-to-accelerator interconnect, optimizer support, checkpointing and software maturity. NVIDIA is the lowest-risk general choice; AMD, TPU and Trainium can be compelling when the model and team are optimized for them.
- Fine-tuning: memory capacity, framework compatibility, quantization and cost often matter more than peak throughput. AMD’s large-memory options, NVIDIA’s mature ecosystem and cloud alternatives can all be relevant.
- Inference prefill: this prompt-processing phase is relatively compute-heavy. GPUs and dense custom accelerators can perform well.
- Inference decode: generating tokens one at a time makes memory bandwidth, on-chip SRAM, batching, latency and token economics especially important. Groq and Cerebras may be attractive for particular serving patterns.
- Long-context or mixture-of-experts models: prioritize memory capacity, bandwidth, routing and collective communication rather than a single peak-FLOPS number.
- On-device AI: prioritize battery life, thermal limits, NPU support, quantization, unified memory and application integration.
Prefill and decode may also be separated across different hardware. Cerebras has described disaggregated inference architectures using different resources for the two phases. Cerebras on AWS.
Step 2: Decide between cloud and on-premises
- Choose NVIDIA or AMD systems when you need hardware portability, on-premises ownership or multiple cloud options.
- Choose Google TPU when the organization already uses Google Cloud and can work effectively with JAX, XLA or PyTorch/XLA.
- Choose Trainium or Inferentia when the workload is deeply integrated with AWS and the economics justify Neuron migration.
- Consider Maia or MTIA as platform capabilities rather than products you can ordinarily install yourself.
- Consider Cerebras, Groq or SambaNova when a managed specialist service or complete system solves a particular latency or throughput problem.
Step 3: Compare the hardware that the model actually uses
Check the following specifications and deployment characteristics:
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
- HBM capacity per accelerator and total usable memory.
- HBM bandwidth and on-chip SRAM or cache.
- Supported precisions, including FP32, BF16, FP8, FP4 and INT8.
- Accelerator-to-accelerator interconnect bandwidth and topology.
- CPU-to-accelerator and accelerator-to-storage paths.
- Rack-level power draw, cooling requirements and density.
- Whether the vendor offers a complete validated system or only a chip.
Step 4: Audit the software stack
Benchmark the exact model and software versions rather than relying on a compatibility logo. Evaluate CUDA and TensorRT against ROCm, JAX/XLA, AWS Neuron, Intel’s Gaudi software or a specialist compiler. Test attention kernels, MoE routing, quantization, sparsity, distributed collectives, profiling, debugging, checkpoint portability and inference-serving integrations.
Best Value
Team familiarity is a real cost. A cheaper accelerator can become more expensive if engineers must rewrite kernels, diagnose compiler failures or maintain a separate deployment path.
Step 5: Calculate useful output economics
Use cost per useful token, cost per completed training run or time-to-quality, not theoretical FLOPS alone. Include:
- Purchase price or cloud rental.
- Utilization, queue time and capacity reservations.
- Host CPUs, networking, storage and cooling.
- Engineering and porting costs.
- Regional availability and data-transfer charges.
- Power, facility and compliance costs.
- Model quality, throughput and latency targets.
Step 6: Check geography and availability
A technically excellent accelerator may be unusable if it is only available through one cloud, absent from the required region, announced but not shipping, blocked by export rules, unavailable in an OEM server or unsupported for the buyer’s model. Sovereign and China deployments require a separate analysis from the global merchant market.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →How to compare AI-chip benchmarks correctly
MLPerf Inference v6.0 is a useful independent comparison source, but its latest public release had submissions from 24 organizations and did not cover every custom accelerator or cloud chip. Absence from the table is not proof that a chip is slow; it may reflect availability, submission strategy or unsupported configurations.
When reading MLPerf or vendor results, compare:
- the same model and model version;
- precision and quantization format;
- batch size and concurrency;
- latency target and quality constraints;
- number of accelerators and complete system configuration;
- software, compiler and framework versions;
- power measurement method and whether host-system power is included;
- throughput, tail latency and cost rather than a single headline score.
Peak FP4, FP8, BF16, INT8 and FP32 figures are not interchangeable. Nor should a single chip be compared with a rack, pod or UltraServer. NVIDIA GB-series systems, AMD Helios, Google TPU pods, Huawei SuperPoDs and AWS UltraServers are integrated systems whose performance depends on memory, networking and software as well as the accelerator die.
Vendor claims such as up to 4.4 times more compute, fastest inference or best cost should be treated as vendor-reported unless an independent benchmark reproduces the exact comparison.
What the market numbers really say
TrendForce forecasts 2026 AI-server shipments to grow by more than 28% year over year. Its forecast assigns 69.7% of shipments to GPU-based AI servers and 27.8% to ASIC-based AI servers. These are shipment forecasts, not revenue, installed-base or total AI-accelerator market-share figures. TrendForce’s AI-server forecast.
The same forecast expects combined 2026 capital expenditure from Google, AWS, Meta, Microsoft and Oracle to grow 40% year over year. That helps explain why custom chips are strategically important even though most are not sold to the public: hyperscalers can justify custom silicon when their own workloads are large and stable enough to repay the design cost.
The market is also shifting from training-only comparisons toward inference economics. Agentic applications, long-context models and high-volume serving make decode latency, memory movement, utilization and energy per token increasingly important.
Common mistakes when ranking AI chip makers
- Using a vague market share denominator: “NVIDIA has 90% of AI chips” is meaningless unless it specifies discrete GPUs, AI servers, accelerator revenue, known clusters or all custom silicon.
- Putting captive chips beside merchant GPUs without an access label: Google TPU, AWS Trainium, Maia and MTIA may be powerful but are generally accessed through their owners’ platforms.
- Comparing a chip with a rack or pod: complete system design can dominate individual-die specifications.
- Ranking peak TOPS or FLOPS across precisions: FP4, FP8, BF16 and INT8 numbers measure different operating points.
- Ignoring software utilization: mature kernels and compilers can matter more than theoretical peak throughput.
- Calling Broadcom a GPU vendor: Broadcom is primarily a custom-silicon and networking supplier.
- Assuming Meta or Microsoft sells merchant accelerators: their chips are primarily internal infrastructure.
- Ignoring China: export controls and domestic procurement create a different competitive landscape.
- Mixing edge and data-center AI: phone and PC TOPS are not directly comparable with HBM-equipped server accelerators.
- Ranking by market capitalization: company valuation is not accelerator market share, benchmark leadership or deployment suitability.
What changes next
- Custom ASIC share should grow: hyperscalers and model companies have enough workload scale to justify specialized silicon, although GPUs remain essential for flexibility and model development.
- NVIDIA’s Rubin rollout will test platform scale: the outcome will depend on production, networking, cloud deployment and software availability, not just chip specifications.
- AMD MI400 and Helios will test the alternative ecosystem: adoption will depend on ROCm maturity, memory capacity, supply and large customer deployments.
- HBM4 and advanced packaging will remain strategic bottlenecks: accelerator demand is constrained by more than wafer fabrication.
- Inference will become more architecture-specific: prefill and decode, latency targets, long context and agentic workloads will reward different designs.
- Regional ecosystems will diverge: export controls and sovereign-computing policies will influence which companies can realistically serve each market.
Bottom line
NVIDIA is the top AI chip maker if the question means the best-positioned supplier of general-purpose merchant data-center accelerators. AMD is the principal alternative. Google TPU and AWS Trainium can be excellent choices inside their respective clouds, while Microsoft Maia and Meta MTIA show how hyperscalers are tailoring silicon to internal workloads.
Broadcom is a leading enabler of that custom-silicon shift, not a conventional GPU vendor. Huawei matters most in China and sovereign infrastructure. Cerebras, Groq and SambaNova can win specialized inference workloads, and Intel remains an important enterprise challenger. Apple, Qualcomm and MediaTek lead a separate on-device market.
For an actual purchase, replace “best AI chip” with “best accelerator for this model, latency target, geography, software stack and total cost.” That question produces a useful answer; a universal ranking does not.
Frequently Asked Questions
Who is the leading AI chip maker in 2026?
NVIDIA is the clear leader in merchant data-center accelerators as of August 10, 2026. Its lead comes from GPUs, CUDA, optimized libraries, networking, complete systems and broad cloud and OEM availability. This does not mean NVIDIA has the largest share of every AI-chip category, because custom ASICs and edge NPUs are separate markets.
Is AMD a better choice than NVIDIA for AI?
AMD is the strongest general-purpose alternative and can be attractive for large-memory workloads, supply diversification and buyers seeking a non-NVIDIA platform. NVIDIA is usually the lower-risk choice for broad framework compatibility and distributed training. The correct decision depends on testing the exact model, ROCm or CUDA software path, price and availability.
Can I buy Google TPU, AWS Trainium, Microsoft Maia or Meta MTIA directly?
Generally, these chips are accessed through their owners’ cloud or platform infrastructure rather than purchased as ordinary standalone accelerator cards. Google TPU is available through Google Cloud, Trainium through AWS services such as EC2 and SageMaker, and Maia and MTIA are primarily used in Microsoft and Meta infrastructure.
Is Broadcom an NVIDIA competitor?
Broadcom is not primarily a merchant GPU competitor. It designs custom AI accelerators for major customers and supplies networking, switching and optical-connectivity components used in AI clusters. Its reported AI semiconductor revenue includes both custom silicon and networking, so it should not be compared directly with NVIDIA GPU revenue.
What is the best AI chip for inference?
There is no universal winner. NVIDIA and AMD offer the broadest general-purpose inference platforms. Google TPU and AWS Inferentia or Trainium can be attractive within their clouds. Cerebras, Groq and SambaNova target particular throughput, latency or dataflow workloads. Compare the exact model, precision, batch size, concurrency, latency target, power and cost per useful token.
Are phone NPU TOPS comparable with data-center GPU performance?
No. Apple’s M4 Neural Engine and Qualcomm’s Snapdragon X Elite NPU are designed for low-power local inference, while data-center accelerators use HBM, different precisions, larger power budgets and multi-chip networking. TOPS figures from phones and PCs should not be placed directly beside data-center FP8, FP4 or BF16 figures.
The Bottom Line
NVIDIA is the best single answer for the top general-purpose AI chip maker in 2026, but it is not the answer for every AI-chip market. AMD is the main merchant alternative; Google and AWS lead cloud-custom silicon; Microsoft and Meta optimize internal platforms; Broadcom enables custom ASICs and networking; Huawei serves an especially important China-focused ecosystem; and Cerebras, Groq, SambaNova, Intel, Apple, Qualcomm and MediaTek compete in narrower segments.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

