What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Use NVMe SSD for the AI data your system is actively reading, writing, indexing, or shuffling; use HDD for large datasets you retain but access less often. For most workstations, NAS deployments, and data platforms, a tiered design that combines both is more practical than choosing one medium.
NVMe can remove storage latency and random-I/O bottlenecks, but a faster drive does not automatically make model training faster. If your pipeline is GPU-, CPU-, network-, or preprocessing-bound, replacing an HDD with NVMe may change little. Measure the real workload, size the active working set, and keep the remainder on economical capacity storage.
As an Amazon Associate I earn from qualifying purchases.
What each drive should do in an AI workflow
AI storage is not one uniform workload. A training or inference system usually handles several kinds of data at once: source datasets, transformed samples, feature indexes, checkpoints, logs, model weights, generated outputs, and backups. They have different access patterns and retention requirements.
Recommended Free Tools
NVMe SSD: the active performance tier
Place data on NVMe when the application repeatedly accesses it or waits on storage latency. Typical examples include the current training shard, preprocessing scratch space, embedding indexes, metadata databases, checkpoint files being written frequently, and inference services with strict response-time targets. Flash has no mechanical seek and can service random requests with much lower latency than a hard disk.
#1 Best Overall

- Video-optimized CMR drive up to 32TB for NVRs with AI for edge applications.
- ImagePerfect AI firmware delivers zero dropped frames while supporting heavier workloads
- Adapts intelligently with support for up to 64 HD video streams and 32 AI streams.
- Peace-of-mind with SkyHawk Health Management and 3 years of in-house Rescue Data Recovery Services.
- Designed for 550TB/year workloads and 2.5M hours MTBF, backed by 5-year limited warranty.
A Seagate Nytro 4350 illustrates the class of device: it is a PCIe Gen4 x4, NVMe 1.4, M.2 2280 drive. Its datasheet lists up to 5,500 MB/s sustained sequential read for the 480 GB, 960 GB, and 1.92 TB versions. That figure comes from 128 KB transfers at queue depth 32, at beginning of life; the datasheet also warns that the host system and previous workload affect application performance. It is a drive specification, not a guaranteed model-training speedup.
HDD: the capacity and retention tier
Use HDD when the priority is storing many terabytes at the lowest practical acquisition cost and the data can tolerate higher latency. Common examples are raw image, video, audio, and text corpora; completed project runs; historical checkpoints; backup repositories; data lakes; media archives; and data retained for compliance or reproducibility.
Seagate’s Exos enterprise portfolio describes hard drives for AI and other data-intensive applications, with capacities up to 32 TB per drive in the cited material. Western Digital’s comparison page shows HDD examples above 36 TB. Those are product snapshots, not universal capacity limits. Confirm the exact model, interface, firmware, region, availability, and enclosure before designing around a quoted capacity.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Fix the driver behind crashes, sound loss and screen glitches3Repair Windows errors before they cause bigger problemsWhy a hybrid is usually the sensible default
In a tiered design, NVMe holds the working set while HDD supplies the larger pool. Western Digital gives SSD examples for database logs and high-IOPS applications, and HDD examples for data lakes, backup repositories, and media archives. Seagate describes AI input and output moving to networked storage for long-term retention, mostly on HDDs. The principle is to match media to access frequency and latency sensitivity, not to label an entire AI project as either an SSD or HDD workload.
Rank #2

- 28TB Massive Enterprise Capacity
- 7200 RPM Performance
- SATA 6Gb/s Interface
- 512e Sector Format 3.5-Inch Enterprise Form Factor
- 2.5M-hours MTBF enterprise rating
Performance: what the specifications really tell you
Sequential throughput
Large, contiguous reads and writes are where both media types can be useful. NVMe has much higher interface and flash throughput; the 5,500 MB/s Nytro figure is one documented example under a controlled test. HDDs can sustain useful sequential transfer rates for bulk scans, restores, and exports, but their mechanical positioning makes small or scattered requests much slower.
Do not translate a sequential headline into end-to-end training performance. A data loader may read compressed files, decode them on the CPU, augment samples, batch requests, and send them over a network before a GPU sees the data. If any of those stages is slower than storage, a faster SSD sits idle.
Random I/O and latency
Random access and queue behavior often determine whether storage is the bottleneck. Index lookups, many small files, concurrent workers, and checkpoint metadata create requests that favor NVMe. HDD latency rises when heads seek between locations, and concurrent random work can reduce effective throughput further.
Measure the application’s queue depth and request size rather than comparing only advertised sequential MB/s. A benchmark that uses queue depth 32 does not predict a single-threaded data-loader result. Check read latency, write latency, IOPS, and tail latency with the same file sizes, worker count, concurrency, and filesystem used by the AI job.
Rank #3

- Breakthrough areal density: The first hard drive to feature up to 3TB per platter, enabling massive storage capacity in the same footprint for maximized data center efficiency.
- Enormous capacity: Up to 30TB of storage in an industry-standard 3.5-inch form factor.
- Time-tested excellence. Next-gen innovation: Blends 90% of trusted, proven components from previous generations with cutting-edge Mozaic 3+ technology for enhanced performance and reliability.
- Reduces power consumption: Up to 60% compared to 10TB drives for lower operational costs and energy consumption.
- Enterprise-class reliability: Designed for the stringent demands of hyperscale cloud service providers and enterprise data centers, providing durable, always-on performance essential for critical enterprise applications.
System-level performance is more than the drive
AWS documentation for FSx for Lustre demonstrates why storage-class specifications are not system benchmarks: throughput and latency depend on provisioned capacity, caching, network, and deployment configuration. The same applies to a local workstation or NAS. PCIe lane sharing, thermal throttling, filesystem behavior, RAID or erasure coding, encryption, network links, and CPU decompression can all dominate the result.
Capacity planning for datasets, checkpoints, and scratch space
Start with the data lifecycle, then calculate usable capacity. Keep separate estimates for the retained corpus, the active subset, temporary expansions, and independent backups.
Size the retained corpus
- Record the source size and the format used during training. Decoded images, caches, indexes, and uncompressed intermediates can require more space than the original files.
- Add versions you must reproduce, including prior dataset snapshots and model checkpoints.
- Reserve space for filesystem overhead, parity or mirror protection, and growth. Raw drive capacity is not the same as usable capacity.
- For an archive or enterprise-capacity pool, a 32 TB-class enterprise hard drive is a category grounded in the Exos portfolio; it is not a promise that every chassis, controller, or geography supports that drive.
Size the active working set
Measure how much data the workers touch during the busiest phase, not merely the size of the complete corpus. If the active set fits on NVMe, you can retain the full corpus on HDD and stage only the required shards. If it does not fit, use a larger SSD tier, a cache, or a scheduler that prefetches the next shard while the current one is processed.
Account for scratch and checkpoints
Preprocessing may temporarily create several copies: source files, decoded data, shuffled shards, and output indexes. Checkpointing can produce large bursts of writes and then read those files during validation or restart. Allocate headroom so a full disk does not stall workers or corrupt a write. For write-heavy use, compare the SSD’s endurance rating and warranty terms, not just capacity and read speed.
Rank #4

- External hard drive with optional RAID0/RAID1 modes, pre-formatted as two individual drives to be compatible without the need to format before use
- Contains 2 top-tier enterprise grade drives for high-speed, reliable access to large files, options for redundancy, and long term durability. Perfect for creators and power users
- Supports USB 3.1 and 10Gbps data transfer speeds, so you can quickly access your files and stream media
- Ideal for photographers, videographers, editors, graphic designers
- Multiple size options to suit your needs
Cost per terabyte: useful direction, not a live price quote
Enterprise market comparisons consistently show HDD costing less per unit of capacity, but the ratios below are dated vendor analyses rather than current retail prices.
| Claim | Scope and qualification |
|---|---|
| 6× HDD acquisition-cost-per-terabyte advantage | Seagate AI-scale comparison using Forward Insights Q3 2023, an IDC HDD forecast from April 2023, and a TRENDFOCUS forecast from August 2023; not an independently verified current retail ratio. |
| 9× HDD manufacturing capital-expenditure efficiency | Seagate’s exabyte-scale comparison with NAND manufacturing; it does not directly predict a drive’s retail price. |
| 4× less operating power per terabyte for HDD | Seagate comparison; a per-terabyte analysis, not a per-drive guarantee. |
| 10× less embodied carbon for HDD | Seagate’s five-year lifecycle comparison, citing Sara McAllister et al., “A Call for Research on Storage Emissions,” Hotcarbon.org, 2024. |
| 7.4×–9.9× enterprise SSD premium | Western Digital comparison citing IDC enterprise research for 2024–2028 (July 2024) and the TechInsights NAND Market Report Q3 2024; enterprise-market scope, not consumer street pricing. |
Use those figures to understand the direction of the market, then calculate your own total cost. Include drive price, usable capacity after redundancy, bays or an enclosure, controller, cooling, electricity, networking, migration labor, and the cost of keeping a second copy. A single inexpensive HDD is not a backup strategy.
Choosing media by AI workload
| Workload or data role | Preferred tier | Reasoning |
|---|---|---|
| Frequently reused training shards | NVMe SSD when storage limits the loader | Low latency and high random-I/O capability help concurrent workers; verify with a pipeline test. |
| Large raw corpus accessed periodically | HDD capacity pool | Lower acquisition cost per terabyte and useful sequential reads make retention economical. |
| Feature or embedding index | NVMe SSD | Many small lookups are latency-sensitive. |
| Completed checkpoints and prior runs | HDD, with independent backup | Retention matters more than interactive latency after the run finishes. |
| High-frequency checkpoint writes | NVMe scratch or checkpoint tier, then HDD archive | Absorb write bursts on the performance tier and move immutable versions to capacity storage. |
| Inference service with strict response targets | NVMe for model and index data | Reduces storage wait when requests are not fully cached in memory. |
| Long-term backup or regulatory archive | HDD repository plus a separate protection copy | Capacity economics favor HDD, while recoverability requires redundancy and tested restores. |
How to design a workstation, NAS, or larger platform
AI workstation
- List the datasets and models used in the next project cycle and mark which files are read or written every minute.
- Install a compatible M.2 NVMe drive for the active set and scratch area. Check that the motherboard provides the required PCIe generation, lane allocation, boot support, and M.2 2280 clearance.
- Use internal SATA/SAS or an external enclosure for the HDD capacity tier. Verify the controller, bay height, power budget, cooling, and filesystem support.
- Benchmark the real data loader with the GPU enabled. Record samples per second, GPU utilization, CPU utilization, storage latency, and network throughput before and after staging data on NVMe.
- Copy completed checkpoints and source snapshots to the HDD tier, then verify hashes and test a restore.
NAS or small server
Keep the frequently accessed share, metadata, and cache on SSD while placing the bulk dataset on HDD. Ensure that the NAS can expose NVMe as a usable storage pool or cache rather than merely accepting the module as a boot device. For multiple users, test simultaneous reads and writes; network bandwidth can erase the benefit of a fast local drive.
Distributed or cloud platform
Separate hot, warm, and cold data classes in the storage service. Provision enough capacity and network bandwidth for the active tier, and use caching or prefetching for repeated scans. FSx for Lustre documentation is a reminder that provisioned capacity, cache state, network, and deployment choices determine observed throughput and latency. Validate the complete path from object or file storage to the worker, not just the advertised media specification.
Best Value
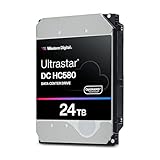
- Store vast amounts of data with a class-leading 24TB capacity, perfect for hyperscale environments, data centers, and big data applications.
- 7200 RPM, SATA 6Gb/s interface, and large 512MB cache, delivering fast, predictable performance for demanding server workloads.
- Designed for 24/7 operation with a high 2.5 million hours MTBF (Mean Time Between Failures) rating, ensuring enterprise-class durability and data dependability.
- Conventional Magnetic Recording (CMR): Employs proven CMR technology for consistent and reliable performance across various workloads.
- Engineered for massive scale-out (MSO), high-density data centers, and cloud storage applications.
A practical test before spending on NVMe
- Run one representative training or inference job from the current storage and log step time, samples per second, GPU utilization, data-loader wait time, and storage read/write latency.
- Repeat with the same software, workers, batch size, CPU affinity, network path, and dataset staged on NVMe.
- Compare the distribution of step times, not only the fastest run. Include startup, checkpoint, validation, and restart phases.
- If GPU utilization remains low while storage wait is high, NVMe may remove a bottleneck. If the GPU is already saturated or CPU preprocessing is limiting, storage replacement alone is unlikely to produce a meaningful gain.
- Test sustained writes until the expected checkpoint volume is reached. Watch for thermal throttling, cache exhaustion, and performance decline after the drive is filled.
The reviewed sources do not establish an independent, workload-controlled head-to-head benchmark of a named NVMe drive and HDD running the same AI pipeline. Treat any claimed universal training multiplier as unsupported unless it reports your workload, hardware, software, and test conditions.
Compatibility and reliability checks
- Interface: NVMe requires PCIe connectivity and an NVMe-capable slot or enclosure; HDD systems commonly use SATA or SAS. A physical M.2 fit does not guarantee electrical or firmware compatibility.
- Form factor: Confirm M.2 length, heatsink clearance, drive bays, and carrier trays before purchase.
- Endurance: Match the SSD’s rated write endurance to preprocessing and checkpoint volume. Heavy sustained writes can make a consumer-oriented drive a poor fit even when its read speed is high.
- Thermals: High-performance NVMe modules may throttle without airflow or a heatsink. HDD arrays also need airflow and vibration control.
- Data protection: Use mirrors, parity, snapshots, or replication as appropriate, and keep a physically or logically independent backup. RAID improves availability; it does not replace backup.
- Recovery: Periodically restore a dataset and a checkpoint to a spare system. A backup that has never been restored is an assumption, not a tested recovery plan.
Common mistakes and how to correct them
Buying NVMe for the entire corpus
This can multiply acquisition cost without improving jobs that read each file once or are limited by preprocessing. Keep the hot subset on SSD and the retained corpus on HDD unless measurements show the full corpus is repeatedly accessed.
Comparing a drive’s headline to a complete platform
A 5,500 MB/s sequential specification does not overcome a one-gigabit network, a slow decoder, shared PCIe lanes, or a saturated filesystem. Benchmark the path used by the application.
Free tools Windows power users keep installed
One-click scans. No signup required.
Filling the SSD completely
Leave operating headroom for temporary files, garbage collection, and checkpoints. Monitor free space and move immutable artifacts to the HDD tier before the performance tier becomes full.
Assuming HDD is unsuitable for AI
HDD is often the economical place for the largest and least frequently accessed part of an AI corpus. It becomes a problem when random access or latency stalls workers; staging, caching, batching, and sequential file layout can reduce that penalty.
Treating capacity as the only specification
Check interface, form factor, endurance, workload rating, controller support, warranty, redundancy, and regional availability. A high-capacity drive that cannot fit the chassis or sustain the write pattern is not a usable solution.
Decision checklist
- Identify the files accessed continuously, periodically, and rarely.
- Measure whether storage wait is limiting GPU or CPU utilization.
- Calculate usable, protected capacity rather than raw terabytes.
- Reserve NVMe for active data, indexes, scratch, and latency-sensitive services.
- Use HDD for retained corpora, archives, backups, and completed outputs when access allows.
- Price the complete system, including redundancy, enclosure, power, network, and migration.
- Verify exact model, interface, form factor, capacity, endurance, cooling, and host compatibility.
- Test the real pipeline and perform a restore before declaring the design production-ready.
Bottom line for AI storage buyers
Choose NVMe when storage latency or random I/O is demonstrably holding back an active workload. Choose HDD when economical, high-capacity retention is the primary requirement. In most mixed AI environments, the strongest design is a fast NVMe working tier feeding from and publishing to a larger HDD pool, with independent backups and measurements that confirm where the bottleneck actually is.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

