To scrape products from a Betta category page, first check whether the product listings are present in the page’s HTML or loaded by JavaScript. Then extract a defined set of fields from each listing, follow pagination with a clear stopping rule, and deduplicate by canonical product URL or stable product ID. Before crawling, check the site’s robots.txt, terms, rate limits and any published API or feed; a sitemap can help find pages but does not grant permission to scrape them.
Plan the crawl before writing selectors
Start with the exact Betta category URL you want to collect. Inspect the page source and links, pagination controls, sitemap references and any documented feed or API. The aim is to learn how the site exposes the category and its next pages before choosing a scraping method.
Define the record you need
Choose a narrow schema in advance. A useful product record can include:
- Canonical product URL or stable product identifier
- Product name
- Price and currency
- Availability
- Image URL
- Category URL
- Page URL where the listing appeared
- Retrieval timestamp
Keep raw HTML or response metadata if you need to reproduce or investigate extraction results later. Store the originating category-page URL with each record so you can trace it back to the page that supplied it.
Free tools Windows power users keep installed
One-click scans. No signup required.
#1 Best Overall

- Compact: Dimension: 7.9"x5.9"x5.9"; 1 Gallon tank; ideal for small spaces, aquarium beginners caring for a single betta, a few shrimp, snails, or a tiny goldfish. Also works as a temporary hospital tank, quarantine tank, or desktop decor (After deducting the filter part, the actual usable volume is approximately 0.8 gal and it will further decrease after adding substrate)
- Customizable Lighting: features a 3-color LED hood with 10 adjustable brightness levels to showcase your fish and tank décor
- Self-Cleaning Filtration: Hidden filter keeps tank clean for easier maintenance. Note: Clean filter sponge and pump regularly to avoid clogging; regular water changes are required — this small tank does not support zero-maintenance use
- Thoughtful Design: its top feeding hole allows for easy feeding without removing the lid; four silicone feet for stability and quiet operation
- Complete Starter Kit: 1x 1 gallon Fish Tank, 1x Filter Sponge, 1x Adjustable Water Pump, 1x LED Hood (Note: The light requires a power transformer (not included) for use. Compatible transformers include 5V 0.5A, 5V 1A, 5V 1.5A, and 5V 2A)
Check permission and site guidance
Review robots.txt, the site’s terms of service, any published rate limits, and available APIs or feeds before making requests. Limit the crawl to the pages and fields you need, use a modest request rate, and do not collect private or sensitive information without a lawful basis. A sitemap helps with URL discovery, but it does not override the site’s terms or replace a permission check.
Choose Requests and BeautifulSoup or Scrapy
For one small category whose products are already in the HTTP response, a simple HTTP client and HTML parser are usually enough. For a crawl spanning many pages or categories, Scrapy offers a more structured workflow with spiders, selectors, callbacks, retries, concurrency controls and pipelines. Its official documentation describes spiders and shows pagination and sitemap patterns: Scrapy documentation.
| Situation | Practical choice | Trade-off |
|---|---|---|
| One static page or a short, one-off crawl | HTTP client plus HTML parser | Simple to start, but pagination, retries and output handling need to be built as the crawl grows. |
| Many pages, recurring jobs or multiple categories | Scrapy | More setup, with built-in structure for requests, callbacks, selectors and pipelines. |
| Products are absent from the initial HTML response | Inspect network requests for a documented or permitted data endpoint; otherwise use a compliant browser-rendering workflow | Endpoint behavior and browser-rendered selectors are specific to the site and may change. |
| The site publishes a useful feed, API or sitemap | Use it for discovery or retrieval where its terms permit | Check what fields it contains and whether it covers the category pages and products you need. |
Inspect Betta’s category markup
Fetch the page once and determine whether its product cards are present in the response body. If they are, inspect a representative listing and find a repeated container that wraps its product fields. Prefer semantic elements, stable data attributes, or structured data such as JSON-LD when available. Avoid selectors based on incidental layout positions, such as “the third div inside the fifth container,” because redesigns can break them.
Check pagination and product links
Look for a next-page link, numbered page links, or a documented cursor. Inspect the destination URL and whether the next control disappears or becomes disabled at the end. Also check whether product links resolve to canonical URLs: tracking parameters or alternate URL forms can otherwise create duplicate records.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Rank #2

- Compact and stylish, designed for small spaces like desktops and countertops. Bring nature into your home while adding a sleek touch
- Effortless setup and maintenance with our step-by-step guide tailored exclusively for beginners
- High-clarity glass with 91.2% transmittance makes your aquascape "pop", delivering a truly immersive viewing experience
- Premium and remarkably simple filtration and lighting systems, keep water clear, plants flourishing, and fish happy with minimal effort on your part
- Each aquarium comes with a lid and a pre-glued leveling mat, ready to use out of the box
When raw HTML has no products
If a browser displays products that are missing from the initial HTTP response, inspect the browser’s network activity to see whether the page uses a documented or otherwise permitted data endpoint. Do not assume that an observed private endpoint is approved for automated use. If no suitable permitted endpoint is available, use a compliant browser-rendering strategy and account for JavaScript execution and page-load timing.
Scrape a static category with Requests and BeautifulSoup
The following Python pattern is deliberately site-neutral because selectors must be based on Betta’s actual markup. Replace the example selectors with stable ones observed on the target page, and confirm the next-page behavior before running a multi-page crawl. The script follows a next link until none remains and deduplicates products by URL.
import csv
import time
from datetime import datetime, timezone
from urllib.parse import urljoin, urldefrag

import requests
from bs4 import BeautifulSoup

START_URL = "https://example.com/betta-category"
HEADERS = {
    "User-Agent": "BettaCategoryResearch/1.0 (contact: [email protected])"
}

session = requests.Session()
seen_pages = set()
seen_products = set()
rows = []
page_url = START_URL

while page_url:
    page_url, _ = urldefrag(page_url)
    if page_url in seen_pages:
        print(f"Stopping: pagination loop detected at {page_url}")
        break
    seen_pages.add(page_url)

    response = session.get(page_url, headers=HEADERS, timeout=30)
    print("Page", response.status_code, page_url)
    response.raise_for_status()
    soup = BeautifulSoup(response.text, "html.parser")

    for card in soup.select(".REPLACE_WITH_PRODUCT_CARD_SELECTOR"):
        link = card.select_one("a.REPLACE_WITH_PRODUCT_LINK_SELECTOR")
        if not link or not link.get("href"):
            continue
        product_url = urljoin(page_url, link["href"])
        product_url, _ = urldefrag(product_url)
        if product_url in seen_products:
            continue
        seen_products.add(product_url)

        name_node = card.select_one(".REPLACE_WITH_NAME_SELECTOR")
        price_node = card.select_one(".REPLACE_WITH_PRICE_SELECTOR")
        availability_node = card.select_one(".REPLACE_WITH_AVAILABILITY_SELECTOR")
        image_node = card.select_one("img")

        rows.append({
            "product_url": product_url,
            "name": name_node.get_text(" ", strip=True) if name_node else "",
            "price": price_node.get_text(" ", strip=True) if price_node else "",
            "availability": availability_node.get_text(" ", strip=True) if availability_node else "",
            "image_url": urljoin(page_url, image_node.get("src", "")) if image_node else "",
            "category_url": START_URL,
            "page_url": page_url,
            "retrieved_at": datetime.now(timezone.utc).isoformat(),
        })

    next_link = soup.select_one("a.REPLACE_WITH_NEXT_LINK_SELECTOR")
    next_href = next_link.get("href") if next_link else None
    page_url = urljoin(page_url, next_href) if next_href else None
    if page_url:
        time.sleep(1)  # Adjust to the site's published guidance and crawl limits.

with open("betta-products.csv", "w", newline="", encoding="utf-8") as f:
    fields = ["product_url", "name", "price", "availability", "image_url",
              "category_url", "page_url", "retrieved_at"]
    writer = csv.DictWriter(f, fieldnames=fields)
    writer.writeheader()
    writer.writerows(rows)

print(f"Saved {len(rows)} unique products from {len(seen_pages)} pages")
Install the dependencies with python -m pip install requests beautifulsoup4. The example user agent identifies the crawler and provides a contact address; replace it with a real project name and monitored contact. The one-second delay is illustrative, not a claim about Betta’s limits: follow the site’s published guidance instead. If the category uses a cursor rather than a next-page link, change the loop to follow that documented cursor and stop when it is exhausted.
Use Scrapy for a multi-page crawl
Scrapy is useful when you need a crawl that can be scheduled, expanded across categories, or monitored through structured output. Its tutorial demonstrates extracting items and yielding a follow-up request from a next-page link; SitemapSpider can use sitemap URLs, including sitemap references exposed through robots.txt, and route URL patterns to callbacks. See the official Scrapy documentation for the applicable API details.
Recommended Free Tools
Rank #3

- 【𝐀 𝐅𝐫𝐢𝐞𝐧𝐝𝐥𝐲 𝐒𝐭𝐚𝐫𝐭𝐞𝐫 𝐊𝐢𝐭 𝐟𝐨𝐫 𝐅𝐢𝐬𝐡𝐤𝐞𝐞𝐩𝐢𝐧𝐠】Everything you need to start a thriving aquarium is right here: a crystal-clear fish tank, a multi-stage filtration system, a heater, a digital thermometer, a LED light with Timer, a water changer, and a net. It eliminates worries about water quality, temperature, or light, making it the perfect gift for a kid, a beginner, or anyone desiring the serenity of nature without the hassle.
- 【𝐇𝐢𝐝𝐝𝐞𝐧 & 𝐏𝐫𝐨𝐭𝐞𝐜𝐭𝐞𝐝】eWonLife small aquarium features a hidden multi-storage design that neatly tucks away all essential gear, including heaters and filters. This gives you a clutter-free view and allows your curious fish to explore happily, fearlessly, and free from harm from the pump
- 【𝐌𝐨𝐫𝐞 𝐅𝐢𝐥𝐭𝐞𝐫 𝐌𝐞𝐝𝐢𝐚, 𝐅𝐞𝐰𝐞𝐫 𝐖𝐚𝐭𝐞𝐫 𝐂𝐡𝐚𝐧𝐠𝐞𝐬】After the initial sponge filter, we've added ceramic rings and quartz balls to create a paradise for beneficial bacteria. Think of them as a tiny, powerful cleanup crew that constantly removes invisible toxins from fish waste. This creates a clear and stable environment where your aquatic friends can thrive, and far less work for you
- 【𝟕𝟖°𝐅 𝐂𝐨𝐧𝐬𝐭𝐚𝐧𝐭 𝐓𝐞𝐦𝐩𝐞𝐫𝐚𝐭𝐮𝐫𝐞 & 𝐄𝐚𝐬𝐲 𝐑𝐞𝐚𝐝𝐢𝐧𝐠𝐬】The included heater creates a stable, ideal 78°F world for your Betta fish and tropical fish to thrive. The clear LED thermometer instantly confirms the perfect conditions, so you can sit back and enjoy watching your fish swim happily
- 【𝐂𝐨𝐦𝐩𝐚𝐜𝐭 & 𝐂𝐫𝐲𝐬𝐭𝐚𝐥-𝐂𝐥𝐞𝐚𝐫 𝐃𝐞𝐬𝐤𝐭𝐨𝐩 𝐀𝐪𝐮𝐚𝐫𝐢𝐮𝐦】Made from high-clarity, durable plastic, this lightweight tank (15"L x 7.9"W x 8.3"H) fits perfectly on any desk or balcony. The 3.5 gallon swimming space is an ideal home for a Betta, small schooling fish (like Cardinal Tetra or Zebra Danios), and ornamental shrimp (such as Red Cherry or Blue Velvet)
A minimal spider outline looks like this. As with the Requests example, replace the selectors and starting URL with values verified against the target page:
import scrapy

class BettaCategorySpider(scrapy.Spider):
    name = "betta_category"
    start_urls = ["https://example.com/betta-category"]
    custom_settings = {
        "USER_AGENT": "BettaCategoryResearch/1.0 (contact: [email protected])",
        "ROBOTSTXT_OBEY": True,
        "FEEDS": {"betta-products.jsonl": {"format": "jsonlines"}},
    }

    def parse(self, response):
        for card in response.css(".REPLACE_WITH_PRODUCT_CARD_SELECTOR"):
            href = card.css("a.REPLACE_WITH_PRODUCT_LINK_SELECTOR::attr(href)").get()
            if not href:
                continue
            yield {
                "product_url": response.urljoin(href),
                "name": card.css(".REPLACE_WITH_NAME_SELECTOR::text").get(default="").strip(),
                "price": card.css(".REPLACE_WITH_PRICE_SELECTOR::text").get(default="").strip(),
                "availability": card.css(".REPLACE_WITH_AVAILABILITY_SELECTOR::text").get(default="").strip(),
                "image_url": response.urljoin(card.css("img::attr(src)").get(default="")),
                "category_url": self.start_urls[0],
                "page_url": response.url,
            }

        next_href = response.css("a.REPLACE_WITH_NEXT_LINK_SELECTOR::attr(href)").get()
        if next_href:
            yield response.follow(next_href, callback=self.parse)
Save the spider in a Scrapy project and run it with scrapy crawl betta_category. Use the actual selectors and verify that pagination terminates. Add an item pipeline or other explicit deduplication by canonical product URL or stable ID when listings can overlap across pages or categories. Scrapy’s settings and middleware let you adapt retries, concurrency and throttling to the site’s published limits rather than assuming a universal safe rate.
Make pagination terminate and results trustworthy
Pagination should have an explicit stop condition: no next-page link, an exhausted documented cursor, or a page that yields no new product identifiers. Do not rely only on a guessed maximum page number. Protect against repeated links and loops by recording visited page URLs; separately track product identifiers so overlapping listings do not inflate the result.
Normalize and deduplicate URLs
Resolve relative links against the page URL, remove fragments, and use the site’s canonical product URL or a stable product ID as the deduplication key. Be cautious about removing query parameters: some may identify different variants, while others may be tracking noise. Follow the site’s canonical URL signals and preserve distinctions that affect product identity.
Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Repair Windows errors before they cause bigger problems3Fix the driver behind crashes, sound loss and screen glitchesRank #4

- HALF MOON AQUARIUM KIT: Clear plastic, half-moon-shaped front allows for unobstructed viewing.
- IDEAL FOR BETTAS: Bettas require minimal maintenance and make great species for beginners.
- MOVABLE LIGHT: Energy-efficient LEDs can be positioned to light tank from above or below.
- CONVENIENT FEEDING: Clear canopy has a hole to make feeding fish easy.
- PERFECT FOR BEGINNERS: Small aquariums like this 1.1-gallon tank are a great way to get started in the freshwater fishkeeping hobby.
Validate the crawl
- Compare product counts page by page and look for unexpected drops or repeated counts.
- Check for duplicate product URLs and pages visited more than once.
- Log HTTP status codes, retrieval failures and parser errors.
- Sample records for missing names, prices, availability and image URLs.
- Retain the page URL for every record so extraction problems can be traced to their source.
For maintainability, keep representative HTML fixtures and test your selectors against them when the category template changes. A page can return successfully while a redesign silently changes field locations; parser validation catches that failure more usefully than accepting empty columns.
Find product URLs through sitemaps and crawlable links
Google’s ecommerce guidance describes category pages as paginated result sets and recommends crawlable links, with sitemap or merchant-feed support for product discovery. Its URL guidance discusses consistent URL handling, self-referencing canonicals, sitemap inclusion and noindex treatment for empty categories. These are useful discovery and URL-management practices, not permission to scrape. See Google’s ecommerce pagination guidance and Google’s URL structure guidance.
Scrapy’s SitemapSpider can read sitemap URLs and route URL patterns such as product and category paths to different callbacks. Check robots.txt for sitemap references, then verify that the sitemap’s scope and terms fit the intended crawl. A sitemap can help locate product URLs, but it may not include the listing fields or category relationships you need.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Handle JavaScript-rendered products
First distinguish “the page needs a little waiting” from “the initial response never contains the product data.” Inspect the raw response. If listing markup is there, parsing the HTML directly is usually simpler and avoids the overhead of browser rendering. If it is absent, look for a documented or permitted API or feed. If neither is appropriate, use a compliant browser workflow and wait for a meaningful condition, such as a product-list selector, rather than an arbitrary delay alone.
Best Value
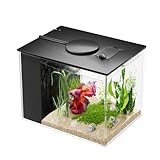
- Perfect Mini Habitat: Measuring just 7.8"L x 5.8"W x 6"H, our space-saving small fish tank with filter and light fits effortlessly on desks, countertops, or shelves. An ideal nano aquarium for bettas, shrimp, guppy fry (like sea monkeys), aquatic plants, or even as a frog habitat, offering versatile usage in any small space
- Vibrant 3-Color LED Lighting: Illuminate your underwater world with adjustable LED lights featuring 3 color modes (white, blue, warm white) and 10 brightness levels. Create the perfect ambiance to showcase your aquatic pets and promote healthy plant growth
- Discreet & Silent Filtration: A concealed filter pump system operates quietly out of sight to keep water crystal clear and well-oxygenated. This self cleaning fish tank design minimizes maintenance while ensuring a healthy environment for delicate fish and shrimp
- Perfect Beginner’s Tank & Present: This all-in-one fish tank starter kit is an ideal choice for first-time owners and makes a wonderful present for young pet enthusiasts. Parents can use this engaging betta tank to introduce youngsters to pet care responsibilities. It also works perfectly as a temporary tank during cleaning or a quarantine space for sick fish
- Convenient Feeding Design: The top cover includes a dedicated feeding opening, allowing easy access for daily feeding without needing to open the entire lid—keeping your fish secure and reducing evaporation
Rendering introduces additional failure modes: scripts may fail, consent dialogs may cover the page, content may load incrementally, and a selector can change with the site template. Treat the rendered DOM and any data endpoint as site-specific, and validate that the expected products actually appeared before saving a page as successfully scraped.
Troubleshoot common scraping failures
| Symptom | Likely cause | What to check or change |
|---|---|---|
| No product cards found | Selectors do not match the current template, or products are injected by JavaScript. | Inspect the response HTML and update selectors from stable attributes; if items are absent, investigate a documented or permitted endpoint or browser rendering. |
| Only the first category page is saved | The next-link selector is wrong, the link is disabled, or pagination uses a cursor. | Inspect the pagination markup and follow its actual next link or documented cursor; log the next URL on each iteration. |
| The crawl repeats pages or never ends | Next links point to the current page, URLs vary only by irrelevant parameters, or the site has a pagination loop. | Track visited normalized page URLs and stop when a URL repeats; inspect canonical and pagination links before deciding which parameters to normalize. |
| Duplicate products appear | Listings overlap between pages, or one product has several URL forms. | Deduplicate by canonical product URL or stable ID, and preserve meaningful variant distinctions. |
| HTTP errors or blocked requests | The site may restrict automated traffic, the request may be malformed, or the crawl rate may be inappropriate. | Check the response status and site rules, reduce request volume, identify the crawler with a contactable user agent, and stop if the site does not permit the activity. |
| Names or prices suddenly become blank | A template change or selector drift broke parsing. | Log missing-field rates, compare current HTML with a saved fixture and revise the parser after verifying the new markup. |
| Browser-rendered page has no products | Capture occurs before the listing loads, scripts fail, or the selector no longer matches. | Wait for a meaningful listing condition, verify rendering errors and inspect the final DOM before treating the page as complete. |
Or skip the browser setup
If your workflow needs screenshots of the rendered category page rather than structured product records, ScreenshotNeo is a website screenshot API and MCP server. It returns PNG, JPEG, WebP or PDF captures; it is not a substitute for extracting and validating product fields in a scraper. One GET request can capture a page:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://example.com/betta-category -o shot.webpSee the ScreenshotNeo documentation for API options. It removes known cookie/consent banners, newsletter popups and chat widgets before capture, and those cleanup steps can be turned off. Bot checks, blank pages, timeouts, failed loads and cache hits are not billed; response headers identify the page verdict and billing status. Its MCP server provides screenshot tools for AI agents. The free plan includes 1,000 screenshots per month with no card, and paid plans start at $5 for 3,000. Sign up for the free plan.
Cost, performance and reliability considerations
A direct HTTP request and HTML parser generally avoid browser-rendering overhead when the response already contains the products. Scrapy becomes valuable as the crawl expands because it organizes requests, callbacks, retries and item processing, but throughput should still respect the site’s documented limits. Browser rendering is appropriate when the content genuinely depends on JavaScript, not simply because it is available.
Reliability comes from observable stopping conditions and validation: record statuses, page URLs, counts and parse failures; deduplicate products; and detect pages with unexpectedly empty results. No extraction approach guarantees completeness if the site changes its templates, hides products, or changes pagination behavior, so monitor output quality and update selectors against verified markup.
Frequently asked questions
Does robots.txt give permission to scrape a category?
No. It is a crawl-control signal and may help identify sitemap locations, but it does not replace reviewing terms of service, published rate limits or other applicable requirements.
Should I save prices as text or numbers?
Preserve the displayed value and currency context. If you also normalize prices into numeric fields, keep the original text so formatting or parsing mistakes can be checked later.
Can a sitemap replace category-page pagination?
Sometimes it can help discover product URLs, but it may not provide category membership or listing fields. Use it only if its contents fit the data you need and its use is permitted.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




