Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Fix the driver behind crashes, sound loss and screen glitches3Repair Windows errors before they cause bigger problemsThe shortest reliable path is to send text and a selected voice from your server to a text-to-speech (TTS) endpoint, then return either a complete audio file or an audio stream to the app. Keep the provider credential off client devices, choose an encoding your playback stack can decode, enforce the provider’s text limit, and tell listeners that the voice is AI-generated.
This guide uses the OpenAI Audio API as a concrete implementation pattern, then shows how the same decisions apply to other services. It covers file generation, low-latency streaming, language and voice testing, security, disclosure, and the optional consent-controlled custom-voice workflow.
As an Amazon Associate I earn from qualifying purchases.
The basic architecture
A TTS integration has five moving parts: application text, a trusted backend, the provider request, audio delivery, and playback. The app should authenticate with your backend; the backend authenticates with the speech provider and decides what text, model, voice, and format are allowed.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware match- Collect text. This may come from a screen, a notification, generated content, or a database record. Normalize whitespace and remove markup that should not be spoken.
- Authorize the request. Check the signed-in user, entitlement, content policy, and any per-user quota before spending provider credits.
- Call the TTS endpoint. A request generally supplies a model, text input, and voice. Some models also accept speaking-style instructions.
- Receive audio. The provider returns bytes for a file response or chunks for a streamed response.
- Deliver it to the client. Return a finished file, a short-lived download URL, or a server-mediated stream. Do not expose the provider key.
- Play or save it. Use a format supported by the target browser, mobile framework, desktop player, or media pipeline.
Keeping this boundary on your server lets you rotate credentials, apply quotas, redact logs, cache repeated requests, and change providers without updating every installed client.
#1 Best Overall

- [Natural Audio Clarity] Operated with frequency response of 50Hz-16KHz, the podcasting XLR mic delivers balanced audio range, likely to resonate with your audience. Directional cardioid dynamic microphone corded will not exaggerate your voice, while rejects unwanted off-axis noise for vocal originality and intelligibility during your PS5 gaming streaming video recording. (Tips: Keep the top of end-addressing XLR dynamic microphone AM8 facing audio source, and suggested recording range is 2 to 6 in.)
- [XLR Connection Upgrade-Ability] To use XLR connection, connect the podcast microphone to an audio interface (or mixer) using a separate XLR cable (NOT Included) . Well-connected and smooth operation improves audio flexibility to make you explore various types of music recording singing. The streaming mic isolates the pristine and accurate sound from ambient noise with greater no interference and fidelity. (RGB and function key on mic are INACTIVE when using XLR connection.)
- [USB Connection with Handy Mute] Skip the hassle of setting something up and plug the cable to play the dynamic USB microphone directly, which suits for beginner creators or daily podcast. You can quickly control the gamer mic with tap-to-mute that is independent of computer/Macbook programs to keep privacy when live streaming. LED mute reminder helps you get rid of forgetting to cancel the mute. (RGB and function key are only available for USB connection, but NOT for XLR connection)
- [Soothing Controllable RGB] RGB ring on the desktop gaming microphone for PC, with 3 modes and more than 10 light colors collection, matches your PC gears accessories for gaming synergy even in dim room. You can control the RGB key button of the dynamic microphone USB directly for game color scheme gaming or live streaming. Configured memory function, the streaming microphone RGB no need to repeated selections after turnning off and brings itself alive when power on. (Only available for USB connection)
- [More Function Keys] Computer microphone with headphones jack upgrades your rhythm game experience and gets feedback whether the real-time voice your audience hear as expected. Get the desired level via monitoring volume control when gaming recording. Smooth mic gain knob on the PC microphone gaming has some resistance to the point, easily for audio attenuation or boost presence to less post-production audio. (Only available for USB connection)
Choose an API and verify access before coding
OpenAI as the runnable example
The OpenAI Audio API guide describes a speech endpoint using gpt-4o-mini-tts. Its request shape includes model, voice, and input; the newer model also supports optional instructions for delivery style. The documentation additionally describes tts-1 and tts-1-hd. Model availability and voice inventories can change, so confirm the live documentation and your account’s access when you implement.
Other paths
Google’s Gemini API and Google Cloud Text-to-Speech provide their own speech-generation and voice documentation. Apple’s AVFoundation provides platform speech synthesis. These are alternative integration paths, not equivalent benchmark results: the available documentation does not establish parity in voice quality, language coverage, price, or latency. Treat access, regional availability, supported formats, and account requirements as items to verify for your own deployment.
Build a generated-file path first
Returning one complete file is the simplest way to get a basic feature working. It is appropriate when a user can tolerate waiting for the whole utterance, when you need a downloadable asset, or when your player already handles the chosen container.
Server prerequisites
- A backend runtime that can make HTTPS requests and write or forward binary responses.
- The provider SDK or an HTTP client installed on the server.
- The provider key stored in an environment variable or secret manager, never in source control or a distributed app bundle.
- An application-level authentication check and a quota or rate-limit policy.
- A decision about whether generated files are temporary, cached, or retained.
Send a speech request
The following Node.js pattern follows the documented SDK shape. The voice value is deliberately read from configuration because voice names and availability are account- and provider-dependent.
import OpenAI from 'openai';
import fs from 'node:fs/promises';

const client = new OpenAI({
  apiKey: process.env.OPENAI_API_KEY
});

const text = getValidatedTextFromYourRequest();
const speech = await client.audio.speech.create({
  model: 'gpt-4o-mini-tts',
  voice: process.env.TTS_VOICE,
  input: text,
  instructions: 'Speak clearly at a measured pace.'
});

const bytes = Buffer.from(await speech.arrayBuffer());
await fs.writeFile('/var/tmp/utterance.mp3', bytes);
instructions is optional and should only be sent when the selected model supports it. If you use another model or provider, follow that service’s parameter names rather than assuming this object is portable.
Rank #2

- XLR MICROPHONE: requires an audio interface or mixer with an XLR input, not a USB microphone
- PODCAST-READY SOUND: broadcast-quality dynamic capsule tuned for speech, rejects room noise in untreated spaces
- BUILT-IN POP PROTECTION: internal pop filter and shock mounting tame plosives and desk thumps without extra accessories
- ALL-METAL BUILD: robust body designed to sit on air for years, matches the RØDECaster family
- IN THE BOX: PodMic with integrated swing mount, connects to any XLR interface, mixer or RØDECaster
Expose the result to the app
- Accept an authenticated application request containing the text or a reference to text already stored on your server.
- Validate length, content type, and authorization before calling the provider.
- Call the speech endpoint and inspect the response status before reading bytes.
- Set a content type that matches the actual output, such as an MP3 response when MP3 was requested or returned.
- Either stream those bytes directly to the authenticated client or save them behind a short-lived, access-controlled URL.
- Delete temporary files according to your retention policy and avoid writing the original text or audio into unrestricted logs.
Avoid making the mobile or browser client call the provider directly with a long-lived key. A public key in an installed binary or browser bundle can be extracted and reused by someone else.
Add streaming when latency matters
Streaming transfers audio in chunks so playback can begin before the complete utterance has been generated. It is useful for conversational interfaces, reading assistance, and long passages where waiting for a full file feels slow. It also makes the client responsible for buffering, interruption, reconnection, and audio framing.
Server-to-client streaming pattern
The exact SDK option and response object differ by provider. Conceptually, your backend forwards the provider’s response body as it arrives:
const providerResponse = await fetch(process.env.TTS_ENDPOINT, {
  method: 'POST',
  headers: {
    authorization: `Bearer ${process.env.TTS_API_KEY}`,
    'content-type': 'application/json'
  },
  body: JSON.stringify({
    model: process.env.TTS_MODEL,
    voice: process.env.TTS_VOICE,
    input: validatedText,
    format: process.env.TTS_FORMAT
  })
});

if (!providerResponse.ok || !providerResponse.body) {
  throw new Error(`TTS request failed: ${providerResponse.status}`);
}

for await (const chunk of providerResponse.body) {
  sendChunkToTheAuthenticatedClient(chunk);
}
This is an integration pattern, not a universal copy-and-paste request: replace the endpoint, fields, authentication method, and framing rules with those documented by your chosen service. Your client player must know whether each chunk is part of a containerized file or raw sample data. It must also stop cleanly when the user skips, pauses, or navigates away.
Do not assume every stream is a playable file
The OpenAI guide describes chunk transfer and recommends WAV or PCM when the fastest response time is the priority. A WAV file includes a container header; raw PCM does not. A player that expects a complete file may fail when handed headerless chunks, so test the provider’s framing with the exact browser or native audio API you plan to ship.
Rank #3

- 48V Phantom Power Required – The Maono PM320S professional XLR condenser microphone requires a stable 48V phantom power supply. Simply connect it to your audio interface, mixer, or preamp via the included XLR cable for plug‑and‑play operation, and it delivers pristine studio‑grade sound instantly. Whether you’re using it as a microphone for PC, a vocal microphone for singing, or a recording microphone for music production, the external power ensures consistent, reliable performance every time.
- Studio‑Grade Audio: Built with a large 16mm condenser capsule, this XLR condenser microphone captures extended frequency response and superior transient detail—ideal for studio recording, music production, and vocal tracking. It handles high SPL with ease, making it a versatile recording microphone for podcasting, streaming, vlogging, home studio, and content creation. Whether you're a singer, podcaster, or streamer, this condenser mic delivers broadcast‑quality sound for any application
- Low‑Noise Design for Crystal‑Clear Capture: The cardioid polar pattern effectively rejects off‑axis ambient noise, making it an excellent podcast microphone XLR for untreated rooms, while the integrated shock mount reduces vibration rumble from stands or desks. A pop filter and foam windscreen further tame plosives and saliva noise—perfect for vocal microphone for singing, streaming mic, or recording mic for voice‑over work—so your audio stays clean, immersive, and professionally polished.
- All‑In‑One Studio Kit: Engineered with rugged all‑metal housing, this condenser XLR microphone withstands daily studio use and accidental drops. The adjustable metal boom arm bracket offers stable positioning and folds neatly for easy portability. From podcast setups to music recording, it's the ideal studio microphone for producers, streamers, and vocalists—all at an incredible value, making it the go‑to podcast mic and recording mic for music, vocals, and online content creation
- Packing List: package includes microphone*1, boom arm*1, metal shock mount*1, pop filter*1, windscreen*1, XLR to XLR cable*1 and User manual*1
Google’s Gemini documentation describes streaming output as headerless, signed 16-bit little-endian PCM at 24 kHz, mono by default, while unary output uses a WAV container. That difference is why a streaming adapter may need to add framing, resample, or feed a low-level audio buffer rather than pass chunks to a file player.
Select an encoding that fits your playback stack
The OpenAI guide lists MP3 as the default and also documents Opus, AAC, FLAC, WAV, and PCM. Choose based on decoder support, bandwidth, seeking needs, and start-up latency rather than selecting a format by habit.
| Format | When it may fit | Implementation caution |
|---|---|---|
| MP3 | General file playback when broad compatibility and compact files matter. | Confirm that your target player accepts the returned MP3 profile. |
| Opus | Efficient compressed delivery where the client stack supports it. | Browser, mobile, and container support varies; test the complete path. |
| AAC | Platforms whose native media frameworks have strong AAC support. | Container and codec expectations differ between platforms. |
| FLAC | Lossless storage or processing before a later playback conversion. | Files are larger than lossy alternatives and are not universally playable. |
| WAV | Simple file handling or a documented low-latency choice. | Uncompressed audio consumes more bandwidth and storage. |
| PCM | Low-level real-time playback or audio processing. | Raw PCM needs sample-rate, channel, bit-depth, and framing metadata supplied by the provider. |
Keep the requested format and the response content type aligned. If you transcode, do it on a controlled server path and account for the extra CPU time and possible quality change.
Respect the text limit and prepare content
The OpenAI API reference lists a maximum speech input of 4096 characters. Treat that as a request constraint, not a suggestion. Validate before calling the API so users receive a useful error instead of a provider rejection.
Chunk long content deliberately
- Normalize whitespace, remove markup that should not be spoken, and preserve paragraph boundaries that affect pauses.
- Split at sentence or paragraph boundaries while keeping each request at or below the documented limit.
- Keep a small amount of context in your own metadata so the client can order chunks correctly; do not duplicate spoken text just to create context.
- Generate chunks sequentially when continuity matters, or in parallel when total completion time matters more than strict ordering.
- Join files only with a tool and container format that matches the encoded audio. For raw PCM, keep sample rate, channel count, and bit depth identical across chunks.
- Cache successful chunks using a key that includes the text, model, voice, instructions, and format. Invalidate that cache when any of those inputs changes.
There is no universal chunk size or retry policy. Choose one based on sentence length, provider limits, the amount of latency your product can tolerate, and whether a voice change between independent requests is acceptable.
Quick wins for a faster PC:
Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Rank #4

- LEGENDARY VOCAL CLARITY: A finely tuned frequency response with subtle midrange lift delivers warm, articulate vocals that cut through any mix, offering the unmistakable sound quality that has defined professional stages and studios for generations
- TRUSTED WORLDWIDE: The microphone of choice for artists and performers everywhere, from small venues to major stages, delivering consistent, professional sound for live performance, recording, podcasting, and broadcast use
- PRECISION CARDIOID PERFORMANCE: A uniform cardioid pickup pattern focuses tightly on your voice while minimizing background noise and feedback, ensuring clean, accurate vocal reproduction in any environment
- INTEGRATED POP PROTECTION: A refined spherical grille and built-in filter work seamlessly to reduce plosives, breath, and wind noise, preserving clarity and balance without the need for additional accessories
- ROAD-READY DURABILITY: Engineered with Shure’s legendary build quality, featuring a rugged metal construction and reinforced stand adapter designed to withstand the demands of touring and professional use
Choose a voice and language using real app content
OpenAI voice inventory and language qualification
The OpenAI guide lists 13 built-in voice names and says the voices are currently optimized for English. It also allows text in a listed set of other languages, but the documentation does not establish equal pronunciation quality across those languages. Do not infer language quality from the fact that a request is accepted.
Keep the voice choice in configuration rather than hard-coding it into every client. That lets you replace a voice if the provider retires it or changes availability. Store a human-readable label for your settings screen, but send the provider’s exact identifier in the backend request.
Test representative material
- Use the names, abbreviations, dates, numbers, punctuation, and specialist terms that occur in your product.
- Include short prompts and long paragraphs; a voice that sounds good in a demo sentence may mishandle dense content.
- Have fluent or native reviewers assess pronunciation and intelligibility for each language you intend to advertise.
- Test pauses, interruptions, replay, and switching between file and stream modes on every target device class.
- Record the model, voice, format, and provider version used for each evaluation so a later change is explainable.
Protect credentials, user text, and generated audio
Use a trusted service as the only component that holds the provider key. Put the key in a secret manager or protected environment variable, restrict who can read it, rotate it, and revoke it when exposure is suspected.
- Authenticate every application request. Bind usage to a user, device, or service identity before generating audio.
- Apply quotas and abuse controls. Limit request frequency, maximum text length, concurrent streams, and total generated characters according to your product policy.
- Minimize sensitive data. Do not send private text to a provider unless your privacy terms and user expectations permit it. Redact text and credentials from logs.
- Control retention. Decide how long temporary audio and source text remain, who can download them, and how deletion works.
- Validate provider responses. Check status, content type, byte counts, and stream termination. Treat malformed or unexpectedly large responses as failures.
- Separate tenants. Include tenant authorization in cache keys and download checks so one customer cannot retrieve another customer’s audio.
These controls are application responsibilities. A provider’s speech endpoint does not replace your authentication, privacy, or abuse-prevention layer.
Disclose that the voice is AI-generated
OpenAI’s official text-to-speech guide states: “Our usage policies require you to provide a clear disclosure to end users that the TTS voice they are hearing is AI-generated and not a human voice.” Put that notice where the listener can reasonably see it before or while audio plays; do not hide it only in a distant terms page.
Best Value
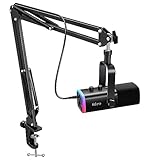
- USB/XLR Connectivity-AM8T comes with a dynamic microphone and a boom arm stand. Versatile PC gaming microphone kit with USB compatibility plug and play for PC in streaming or recording, without additional drivers. And also, while in XLR compatibility for mixer or sound card connection, the XLR studio vocal microphone is good at vocal, podcast, or musical instruments creation.
- Vibrant RGB Light-The streaming microphone RGB illuminates your gaming setup with customizable RGB lighting for a visually stunning game experience. You can easily control the RGB mode/colors or turn off by simply tapping the RGB button without making any complicated settings on specific software.
- Enhanced Features-Featured -50dB sensitivity and cardioid polar pattern, the USB recording mic kit not easily pick up background noise for delivering clear audio. The PC gaming microphone USB kit includes a boom arm for easy positioning, mute button and gain knob for precise control, headphones jack for real-time monitoring, and headphone volume control while streaming or recording.
- Decent for Gamers and Streamers-The XLR microphone designed specifically to meet the needs of gaming enthusiasts and streamers. Ideal for various applications, including gaming, streaming, podcasting, voiceovers, and more, which also works with popular streaming software like OBS and Streamlabs.
- Recording Microphone Kit-The dynamic microphone is more convenient for working from home or going out for podcasts, and the complete accessories allow for faster recording work due to its simple straightforward assembly. External windscreen of the XLR dynamic microphone filter out plosive voice.
A concise implementation might label a player “AI-generated voice” and repeat the disclosure in an accessibility label or settings screen. Review additional legal, accessibility, advertising, and sector-specific requirements for the countries and use cases in which your app operates. The provider statement is not a substitute for that review.
Use custom voices only as an optional, controlled workflow
Custom voice creation is separate from ordinary TTS. The OpenAI guide says access is limited to eligible customers and requires both a consent recording and a matching voice sample from the same person. Confirm eligibility before designing your product around it.
Documented recording sequence
- Confirm that the speaker owns or is authorized to license the voice for your intended use.
- Record the provider’s approved consent sentence exactly, with only one approved phrase in the consent recording.
- Record the sample from that same speaker. Use a quiet room, consistent delivery, and clean capture; the guide recommends professional XLR equipment as a quality option, not a requirement for ordinary TTS calls.
- Keep the sample at 30 seconds or less, as specified by the guide.
- Submit the consent recording and sample through the provider’s eligible custom-voice process, then store only the identifiers and files your retention policy allows.
The documented English consent phrase is: “I am the owner of this voice and I consent to OpenAI using this voice to create a synthetic voice model.” It is a provider workflow requirement, not general legal advice. If your speaker uses another language or your intended use changes, confirm the provider’s current approved phrase and obtain any additional rights or consents that apply.
The Tool Desk
Outbyte Driver Updater FREEFix the driver behind crashes, sound loss and screen glitchesFind Drivers →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →The guide states that an organization can create at most 20 custom voices. That limit, the eligibility rules, sample requirements, and available voice controls can change; verify them immediately before implementation. Keep custom-voice administration behind a separate, highly restricted workflow rather than exposing it as an arbitrary end-user setting.
Compare providers without inventing a winner
Choose a service by measuring the requirements that affect your app, not by assuming that one provider is fastest or sounds best. The available documentation does not establish a reliable cross-provider price, latency, or quality winner.
| Decision axis | What to verify | Evidence currently established |
|---|---|---|
| Language coverage | Supported languages, pronunciation quality, accents, and your target-region availability. | OpenAI documents a listed set of languages and English-optimized voices; equivalent quality across languages is not stated. |
| Streaming | Whether chunks arrive early, how they are framed, and whether interruptions are supported. | OpenAI documents chunked transfer; Gemini documents headerless PCM streaming at 24 kHz mono, 16-bit by default. |
| Output encoding | Containers and codecs accepted by your playback stack. | OpenAI documents MP3, Opus, AAC, FLAC, WAV, and PCM; other providers’ complete format matrices are not stated here. |
| Voice controls | Built-in voices, style instructions, pronunciation controls, and custom-voice access. | OpenAI documents 13 built-in voices and optional instructions for the newer model; custom voices are access-controlled. |
| Security integration | Server-side authentication, account boundaries, logging controls, and regional requirements. | Not stated as a comparable cross-provider score; inspect each provider’s current security documentation. |
| Cost and limits | Current pricing, quotas, overage behavior, and eligibility for your account. | No reliable current price or latency winner is established here; check official pricing and your account console. |
Run your own acceptance test
Prepare a fixed set of representative passages and run them through each eligible service under the same network and device conditions. Measure time to first playable audio, total completion time, failure rate, bandwidth, and the number of manual pronunciation corrections. Have reviewers score intelligibility for every advertised language. Keep the test date and model versions with the results because provider inventories and limits change.
Plan failures, retries, and operating cost
Handle common failure branches
- Validation failure: return a clear message when text exceeds the provider limit or contains unsupported content; do not retry unchanged input.
- Authentication or eligibility failure: alert operators, disable the affected feature flag, and avoid exposing provider error details that reveal secrets.
- Rate limiting: apply bounded backoff, queue non-urgent work, and tell the user when generation is delayed.
- Network interruption: for file mode, discard incomplete output and retry only when the request is safe to repeat; for streaming, stop the player cleanly and offer replay.
- Playback incompatibility: fall back to a format supported by the target stack or transcode on the server. Do not label raw PCM as WAV unless a valid WAV container has been created.
- Provider change: monitor model and voice identifiers, run a small canary request after configuration changes, and keep a rollback voice or model where policy permits.
Budget before launch
Speech spending depends on the provider’s current pricing, text volume, retries, selected model, custom-voice eligibility, and retention strategy. Because no dependable price figure is established here, obtain the current official rate for your account and multiply it by expected characters or requests, then add a reserve for retries and peak usage. Enforce a hard application quota so an unexpectedly popular or abused endpoint cannot create an unbounded bill.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Prelaunch checklist
- The client calls your authenticated backend, not the provider with an embedded key.
- Text is normalized and checked against the documented 4096-character OpenAI input maximum when that endpoint is used.
- The selected model, voice, instructions, and output format are recorded in server configuration.
- Generated-file playback works on every target platform with the actual returned content type.
- Streaming playback handles provider framing, buffering, cancellation, reconnects, and end-of-stream correctly.
- Language tests include real names, numbers, abbreviations, and domain vocabulary, reviewed by fluent speakers where appropriate.
- Temporary audio, source text, logs, caches, and download URLs follow a documented retention and tenant-isolation policy.
- Rate limits, quotas, retries, alerts, and a provider/model rollback path are in place.
- The interface clearly identifies the speech as AI-generated.
- Any custom voice is gated by eligibility, speaker consent, matching sample audio, rights review, and the provider’s current limits.
Bottom line
Start with a server-side generated-file request because it is easiest to validate, then add streaming only when measured latency justifies the extra buffering and framing work. Use the provider’s documented model, voice, input limit, and formats; test the result with your real content; and keep provider choice open by isolating the TTS call behind your own backend interface. Credential protection, clear AI disclosure, and a separate consent-controlled process for custom voices are core parts of the feature, not optional polish.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

