GPU temperature is the core-temperature value a monitoring tool reports, while hot spot temperature (also called junction temperature) is the hottest reading from a group of sensors on the GPU die. Hot spot is therefore often higher, but there is no industry-wide “normal” difference or universal safe temperature. Judge either reading against your exact GPU model’s published limits and any evidence of throttling.
The practical rule is simple: identify the sensor your utility is showing, find the maximum operating or slowdown specification for that specific card, and investigate cooling only when temperatures approach that limit or a throttle/thermal-violation indicator appears.
As an Amazon Associate I earn from qualifying purchases.
What each temperature reading actually measures
GPU temperature: the core reading
Utilities commonly label the main value GPU temperature, GPU current temperature or core temperature. NVIDIA defines its GPU Current Temp field as the core GPU temperature. It is a single reported metric, but the exact sensor implementation and label depend on the hardware and software interface.
Do these 3 things before closing this tab:
1Clear out junk files and repair common Windows errors2Fix the driver behind crashes, sound loss and screen glitches3Repair Windows errors before they cause bigger problemsHot spot temperature: the hottest junction
AMD GPUOpen’s ADLX SDK reference defines GPUHotspotTemperature as “the highest temperature measured on the die of the GPU from a collection of junction temperature sensors on the die.” The same documentation says this is sometimes called junction temperature. A hot spot value is therefore a maximum among several die-sensor readings, not an average of the entire chip.
#1 Best Overall
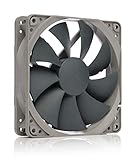
- High performance cooling fan, 120x120x25 mm, 12V, 4-pin PWM, max. 1700 RPM, max. 25.1 dB(A), >150,000 h MTTF
- Renowned NF-P12 high-end 120x25mm 12V fan, more than 100 awards and recommendations from international computer hardware websites and magazines, hundreds of thousands of satisfied users
- Pressure-optimised blade design with outstanding quietness of operation: high static pressure and strong CFM for air-based CPU coolers, water cooling radiators or low-noise chassis ventilation
- 1700rpm 4-pin PWM version with excellent balance of performance and quietness, supports automatic motherboard speed control (powerful airflow when required, virtually silent at idle)
- Streamlined redux edition: proven Noctua quality at an attractive price point, wide range of optional accessories (anti-vibration mounts, S-ATA adaptors, y-splitters, extension cables, etc.)
Because one value represents a core metric and the other represents the hottest point detected by a sensor group, they are not interchangeable. A higher hot spot does not, by itself, prove that the card is defective.
Memory temperature is a separate metric
GPU and memory temperatures describe different components. NVIDIA’s monitoring documentation lists GPU Current Temp and Memory Current Temp as separate fields, and memory readings are available only on supported products. A card can therefore show a reasonable core temperature while its memory reading follows a different thermal pattern. Always record the field name, not just the number.
Why hot spot is higher than GPU temperature
The hot spot sensor is designed to find the warmest junction on the die. The core value is a different reading, so a gap is expected in many workloads. The size of that gap depends on the card’s sensor arrangement, workload, cooling behavior, firmware and the monitoring utility’s support for each field.
Official documentation does not establish a universal hotspot-minus-core range that applies across GPU models. Do not use a rule such as “a 15-degree difference is always safe” or “a 20-degree difference means the cooler has failed.” Compare readings only when the same card is running a comparable workload and the utility is reporting the same fields and units.
There is no universal safe GPU or hot spot temperature
NVIDIA states plainly: “This maximum temperature varies by GPU.” Maximum operating, slowdown and shutdown values are model-specific. A limit from one card cannot be borrowed for another card, even when both use the same manufacturer or a similar architecture.
For a useful assessment, collect these five facts:
- The exact GPU model and, when relevant, its board or laptop variant.
- The utility and field name that produced each reading.
- The model’s published maximum operating or slowdown temperature.
- Whether a throttle, thermal-violation or slowdown indicator is active.
- The workload, duration, ambient temperature and fan/airflow conditions during the reading.
Without those details, a raw number has limited diagnostic value. A temperature that is acceptable for one model may be close to the limit for another.
What happens at the limit: throttling and shutdown
NVIDIA documents a sequence rather than a single universal alarm point. When a GPU reaches its maximum specified operating temperature, it may reduce clocks or performance to control heat. If temperature continues to rise despite throttling, the system may shut down. This behavior is protective; a lower clock under a sustained load is evidence to investigate, not proof that the hot spot number itself is wrong.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Check the exact limits exposed for your product. In NVIDIA’s command-line tool, nvidia-smi -q -d TEMPERATURE displays current temperature and temperature-related limits on supported products. NVIDIA documentation also lists slowdown, maximum operating, shutdown and target-temperature fields. Some interfaces expose T.Limit as a margin from the maximum operating temperature rather than as an absolute temperature, so read the field definition and units before interpreting it.
Rank #2

- HIGH STATIC PRESSURE: Efficient even with resistance – the generated airflow easily penetrates dense radiators, narrow perforated panels and mesh structures and ensures reliable cooling
- PWM CONTROL WITH WIDE SPEED RANGE: The speed can be progressively adjusted up to 3000 rpm via the 4-pin PWM connection – the fan stops completely at less than 5% PWM
- PRECISE MANUFACTURING FOR MAXIMUM SMOOTH RUNNING: Minimal gaps, automatic balancing and high-precision measurement noticeably reduce vibrations – for quiet, efficient and long-lasting performance
- SMOOTH-RUNNING FLUID DYNAMIC BEARING (FDB): The self-lubricating bearing minimizes noise during operation – ideal for quiet, efficient cooling and a long, reliable service life
- NEW FAN BLADE DESIGN FOR MORE PERFORMANCE: The redesigned rotor blades offer an optimal balance of performance and low noise – especially efficient at low speeds
AMD uses generation-dependent telemetry. AMD SMI documentation describes checking hot spot temperature together with thermal-violation percentages on Instinct MI300-series and newer hardware. For Radeon Navi and Instinct MI100/MI200 products, the documented path is throttle status and reason flags instead; the violation API may be unavailable or report N/A on those generations.
How to monitor the readings correctly
NVIDIA cards
- Identify the exact model in the operating system or the card’s specification page.
- Use a supported utility such as NVIDIA’s
nvidia-smi. Runnvidia-smi -q -d TEMPERATUREto view current temperature and available temperature limits. - For a graphical view, NVIDIA names GPU-Z and EVGA Precision as examples of monitoring utilities. Confirm which sensor each displayed value represents.
- Record the reading during a repeatable workload, along with clock behavior and any slowdown or thermal status.
- Compare the result with that model’s specification, not with a number copied from another GPU.
Not every NVIDIA product exposes every temperature reading type. If a field is missing, that is a support limitation, not evidence that the component has no sensor or that it is overheating.
AMD cards
- Confirm the GPU generation because AMD SMI commands and telemetry differ by product family.
- On Instinct MI300 series and newer, examine hot spot temperature together with the documented thermal-violation indicators.
- On Radeon Navi and Instinct MI100/MI200 products, use the documented throttle-status and reason flags when violation telemetry is unavailable.
- Check whether the API reports a real value or an unavailable/N/A status before drawing a conclusion.
- Repeat the measurement under a known workload and compare it with the limits published for that generation and model.
AMD’s monitoring APIs are not uniformly available across all GPUs, so a missing metric must be interpreted in the context of the hardware generation.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWhy two utilities can disagree
Different programs may poll sensors on different schedules, use different driver interfaces or assign similar labels to different fields. One tool can show core temperature while another shows junction temperature, a board-level value or a temperature margin. A screenshot that omits the field name and unit cannot establish that two tools are reporting contradictory temperatures.
When values disagree, close unnecessary monitors and repeat the reading with one supported utility. Note the timestamp, field names, units and workload. If both tools expose the same sensor and still disagree materially, check the product’s supported telemetry and driver documentation before treating the discrepancy as a hardware problem.
A repeatable temperature test
A short spike and a sustained load answer different questions. To assess thermal control, use a repeatable workload that produces similar power draw each time. Start recording at idle, then note temperatures after the workload has run long enough for the reading to stabilize. Record core GPU, hot spot, memory when available, fan behavior, clocks and any throttle or violation status together.
- Write down the exact model, board or laptop variant and driver or monitoring utility.
- Record room or case ambient conditions and whether the side panel, filters and fans are in their normal positions.
- Run the same application, scene or compute job for comparable durations on each test.
- Capture peak and sustained readings rather than relying on a single instant in a graph.
- Repeat an unusual result once, then verify it with another supported monitor if the fields are available.
This method prevents a menu screen, shader-compilation burst or brief workload spike from being compared with a sustained rendering or compute session. It also makes it easier to tell whether a change followed an airflow or ambient-temperature change.
How to read a large GPU-to-hot-spot difference
Start by verifying that both values were captured at the same time, under the same load and from the same card. A game menu, a shader-compilation burst and a sustained compute job can produce different sensor relationships. Utilities can also refresh fields at different intervals or expose one value from a driver interface and another from a board sensor.
Rank #3
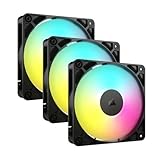
- Streamlined Fan Connections: Daisy-chain multiple fans together and control them all through just one 4-pin PWM connector and one +5V ARGB connector.
- Lighting Made Easy: Eight LEDs per fan shine bright with customisable lighting through your motherboard’s built-in ARGB control (requires compatible motherboard).
- Precise PWM Speeds: Set your fan speeds up to 2,100 RPM while providing up to 72.8 CFM airflow to your system.
- CORSAIR AirGuide Technology: Anti-vortex vanes direct airflow at your hottest components for concentrated cooling, pushing air in the direction you need when mounted to a radiator or heatsink.
- High Static Pressure: RS fans work well as radiator fans with a static pressure of 2.8mm-H2O to push through obstructions.
If the card remains below its documented limit, clocks remain stable and no thermal-violation or throttle indicator is active, the difference alone does not establish a fault. If the difference changes sharply, appears only in one utility or is accompanied by performance loss, repeat the test with another supported monitor and a controlled workload before changing hardware.
When a missing reading is normal
Sensor availability is product-dependent. NVIDIA cautions that not all products support every temperature reading type, and NVIDIA’s memory field appears only on supported products. AMD’s monitoring paths also vary by generation; a violation field can be unavailable or show N/A on Radeon Navi and Instinct MI100/MI200 products while other throttle-status fields remain available.
Do not substitute a guessed value when a field is absent. First determine whether the hardware and driver expose that sensor. A missing hot spot or memory value limits what you can conclude, but it does not prove that the component is overheating or operating perfectly.
Quick wins for a faster PC:
Repair Windows errors before they cause bigger problemsFix Now →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Clear out junk files and repair common Windows errorsFree Scan →Troubleshooting when temperatures are genuinely too high
Use the following order so that you diagnose the condition before replacing parts.
- Verify the model limit. Find the maximum operating or slowdown specification for the exact GPU. Do not substitute a limit from a different board.
- Confirm the sensor and units. Check whether the utility is showing core GPU temperature, hot spot/junction, memory temperature or a margin such as NVIDIA’s T.Limit.
- Check for protection behavior. Look for clock reduction, a thermal-violation percentage, throttle status or a reason flag. A limit breach with no protection indicator may reflect a telemetry or labeling issue that needs verification.
- Measure ambient conditions. Record room temperature and compare tests taken under similar conditions. A warmer room raises the cooling system’s starting point.
- Inspect case airflow. Confirm that intake and exhaust fans run, vents are unobstructed and cables are not blocking the GPU cooler. NVIDIA says that, when a GPU is hitting its maximum temperature, improved system cooling such as adding a case fan can help reduce temperatures. This is conditional advice; check the case’s mounting space and airflow direction first.
- Remove accumulated dust. Power down safely and clean accessible filters, vents and heatsink surfaces according to the system and card manufacturer’s instructions.
- Retest under the same workload. Record core, hot spot, memory (if available), clocks and throttle indicators together. A change that appears only after airflow or ambient conditions change points to system cooling; a persistent limit breach needs model-specific service guidance.
Do not infer that thermal paste or a GPU fan must be replaced solely because the hot spot is higher than the core reading. Those repairs require evidence of a cooler, fan or mounting problem and should follow the card manufacturer’s service instructions.
The AMD MI300 “>95°C” example is not a universal threshold
AMD ROCm’s AMD SMI documentation, version 7.13.0-preview, uses “>95°C” as an example condition when discussing high hot spot temperature together with high thermal-violation values on Instinct MI300 series and newer. That example belongs to a specific accelerator generation and monitoring workflow. It is not a general consumer-GPU safety limit and should not be applied to Radeon or other products.
Comparing two GPUs or two temperature reports
Raw temperature comparisons are meaningful only when the comparison axes match. Use this checklist:
Free tools Windows power users keep installed
One-click scans. No signup required.
- Same model context: identify the exact GPU, board design and product family.
- Same metric: compare core with core, hot spot with hot spot and memory with memory.
- Same workload: use comparable power draw, duration and software load.
- Same environment: note ambient temperature, case configuration and fan profile.
- Same limit framework: check each card’s own maximum operating and slowdown specifications.
- Same telemetry support: verify that both utilities expose equivalent fields rather than similarly named values.
A card running at a lower core temperature is not automatically cooler overall if its hot spot or memory temperature is near a model limit. Conversely, a larger hot spot gap is not automatically dangerous when all limits and performance indicators remain normal.
Rank #4

- 【High Performance Cooling Fan】 Automatic speed control of the motherboard through the 4PIN PWM fan cable interface, which can determine the speed according to the temperature of the motherboard, with a maximum speed of 1550RPM. Configured with up to 55cm of cable for PWM series control of fans, ideal for cases and CPU coolers.
- 【Quality Bearings】The carefully developed quality S-FDB bearings solve the problem of pc cooling fan blade shaking in lifting mode, keeping fan noise to a minimum while providing maximum cooling performance when needed and extending the life of the fan.
- [Excellent LED light] The high-brightness LED atomizing argb fan blade can effectively reflect the light, making the ARGB lighting effect softer, and it matches the cooler and case more perfectly. Up to 17 modes of light effects with ARGB support, color can be managed and synchronized through the port on motherboard.
- 【Silent Fan Size】 Model: TL-C12C-S X5, Size: 120*120*25mm, Speed: 1550RPM±10%, Noise ≤ 25.6dBA Connector: 4pin pwm, Current: 0.20A, Air Pressure: 1.53mm H2O, Air Flow: 66.17CFM, Higher air flow for improved cooling performance.
- 【Perfect Match】The PC fan can be used not only as a case fan, but is also suitable for use with a cpu cooler to create a cooling effect together, which can take away the dry heat from the case and the high temperature generated by the CPU in operation, allowing for maximum cooling; Ideal for cases, radiators and CPU coolers.
Common interpretation mistakes
Treating “GPU temperature” as a universal sensor
The label varies by utility. One program may show core temperature while another highlights hot spot or a board-level value. Read the field definition and unit before comparing screenshots.
Borrowing a safe number from the internet
Maximum temperature varies by GPU, and supported fields differ by product. A number quoted for another model cannot establish a limit for yours.
Diagnosing a defect from the delta alone
Official definitions establish that hot spot is the highest junction reading, but they do not define a universal normal delta. Investigate the difference in combination with throttling, violations, workload and model specifications.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Confusing temperature with a temperature margin
NVIDIA’s T.Limit can represent distance from the maximum operating temperature rather than an absolute temperature. A margin value must not be read as though it were a thermometer reading.
Ignoring memory temperature
Memory has its own reported field on supported products. If a workload is memory-intensive, core and hot spot readings alone may not describe the relevant thermal condition.
A practical decision framework
Use the following branches after a sustained, repeatable workload:
- Below the model limit, no throttle: keep monitoring; the hot spot difference alone is not a diagnosis.
- Near the limit, no clear fault: check ambient temperature, dust, fan operation and case airflow, then retest.
- At the limit with clock reduction or a violation flag: treat it as a thermal-control event and address airflow and cooling before increasing workload or power.
- Above the limit or shutting down: stop the sustained test, verify telemetry with a supported tool and follow model-specific service guidance.
- Conflicting or missing readings: check generation-specific sensor support and field definitions; do not fill the gap with a guessed threshold.
Bottom line for everyday monitoring
Hot spot/junction temperature is the hottest sensor reading on the GPU die; GPU temperature is a different core metric. A higher hot spot is expected often enough that the difference itself is not a pass/fail test. The decisive evidence is the exact model’s limit, whether the card throttles or reports a thermal violation, and whether cooling, airflow, dust or ambient conditions explain the behavior.
Frequently Asked Questions
Is GPU hot spot temperature supposed to be higher than GPU temperature?
Often, yes. Hot spot is the highest reading from multiple junction sensors, while GPU temperature is a separate core metric. The size of the difference varies, and no universal normal gap has been established.
Best Value

- 【High Performance Cooling Fan】 Automatic speed control of the motherboard through the 4PIN PWM fan cable interface, which can determine the speed according to the temperature of the motherboard, with a maximum speed of 1550RPM. Configured with up to 55cm of cable for PWM series control of fans, ideal for cases and CPU coolers.
- 【Quality Bearings】The carefully developed quality S-FDB bearings solve the problem of pc cooling fan blade shaking in lifting mode, keeping fan noise to a minimum while providing maximum cooling performance when needed and extending the life of the fan.
- [Excellent LED light] The high-brightness LED atomizing argb fan blade can effectively reflect the light, making the ARGB lighting effect softer, and it matches the cooler and case more perfectly. Up to 17 modes of light effects with ARGB support, color can be managed and synchronized through the port on motherboard.
- 【Silent Fan Size】 Model: TL-C12C-S X3, Size: 120*120*25mm, Speed: 1550RPM±10%, Noise ≤ 25.6dBA Connector: 4pin pwm, Current: 0.20A, Air Pressure: 1.53mm H2O, Air Flow: 66.17CFM, Higher air flow for improved cooling performance.
- 【Silent Fan Size】 Model: TL-C12C-S X3, Size: 120*120*25mm, Speed: 1550RPM±10%, Noise ≤ 25.6dBA Connector: 4pin pwm, Current: 0.20A, Air Pressure: 1.53mm H2O, Air Flow: 66.17CFM, Higher air flow for improved cooling performance.
What hot spot temperature is safe?
There is no universal safe value. NVIDIA says the maximum temperature varies by GPU. Check the exact model’s maximum operating or slowdown specification and look for throttling or thermal-violation indicators.
Does a large GPU-to-hot-spot difference mean my GPU is failing?
Not by itself. Verify that both readings use the same card, workload, time and units. A fault becomes more plausible only when the model limit is reached or exceeded, clocks fall, violations appear or the system becomes unstable.
How can I check NVIDIA temperature limits?
On supported products, run nvidia-smi -q -d TEMPERATURE to view current temperature and available limits. NVIDIA also documents slowdown, maximum operating, shutdown and target-temperature fields. Read whether a field is an absolute temperature or a margin such as T.Limit.
Why can’t my monitor show hot spot or memory temperature?
Sensor fields are not supported on every product. NVIDIA documents support restrictions, and AMD telemetry differs by generation. A missing or N/A field should be treated as a hardware or API limitation, not as proof of overheating.
Is AMD’s “>95°C” value a general GPU limit?
No. AMD SMI uses >95°C as an example for high hot spot temperature together with high thermal-violation values on Instinct MI300 series and newer. It is generation-specific and not a consumer-GPU safety threshold.
Should I replace thermal paste because hot spot is higher?
No. A higher hot spot is an expected consequence of measuring the hottest junction. Replace paste or a fan only when model-specific evidence indicates a cooler, fan or mounting problem, and follow the manufacturer’s service guidance.
What should I do if my GPU reaches its maximum temperature?
Verify the reading with a supported utility, check for clock reduction or thermal violations, and inspect ambient temperature, dust, fans and case airflow. NVIDIA notes that improved system cooling, such as an added case fan, can help in this condition when the case supports it.
Recommended Free Tools
The Bottom Line
Hot spot is the hottest junction reading; GPU temperature is a separate core metric. Ignore universal temperature rules and judge your exact model’s limits, telemetry support and throttling behavior. If readings approach the limit, verify the sensors, check airflow and ambient conditions, then retest before replacing hardware.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

