Free tools Windows power users keep installed
One-click scans. No signup required.
In a Crimean Tatar speech-recognition project, fine-tuning lowered the reported word error rate (WER) from 34.6% to 20.1%. Careful decoding choices brought it to 17.0%—without changing the model weights. But the most consequential work came before and after training: finding hidden duplicate recordings, building a credible test split, and tracing errors to a handful of clips that looped.
Servin Osmanov’s account is a useful case study in a broader engineering principle: a score only means what the evaluation design allows it to mean. The figures below are Osmanov’s reported results for this project, not independently replicated benchmarks or predictions for other languages.
As an Amazon Associate I earn from qualifying purchases.
Why evaluation integrity came before training
Speech datasets are often assembled from clips cut out of longer recordings. Clips from the same book, reader, session, microphone, and room can be highly similar; sentence boundaries may even cross clip boundaries. If neighboring clips are randomly assigned to training and test sets, the model can encounter familiar voices, recording conditions, or text on both sides of the split. The test score may then reflect familiarity as much as generalization.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Fix the driver behind crashes, sound loss and screen glitchesFind Drivers →Repair Windows errors before they cause bigger problemsFix Now →Osmanov instead held out two complete books and two readers absent from training. The resulting test set contained 893 clips and 1 hour 52 minutes of audio. This split asked the recognizer to handle different source material and readers, rather than nearby fragments of recordings it had already seen.
#1 Best Overall

- 360 Degree Position Adjustable Gooseneck Design --Plug and play USB microphone Pick up the sound from 360-degree with high sensitivity, in the best possible location for sound to your PC gaming, dragon voice dictation, and talk to Cortana
- Mute Button & LED Indicator --One-click to mute/unmute your microphone for pc, Build-in LED indicator tells you the working status at any time
- Intelligent Noise-Canceling Tech --Premium omnidirectional condenser microphone with noise-canceling technology can pick up your clear voice and reduce background noise and echo
- USB Plug&Play(1.8/6ft USB Cable) -- No driver required. Just need to plug & play for the microphone to start recording, well compatible with Windows(7, 8, 10 and 11) and macOS. (NOT compatible with Xbox/Raspberry Pi/Android)
- Solid Construction--Adopting premium metal pipe and heavy-duty ABS stand to make sure that you will be satisfied with our computer mic quality
Different filenames did not mean different content
A filename comparison found no overlap between training and held-out files. But matching runs of six consecutive words exposed four audiobooks duplicated in the corpus: they had been segmented in different passes and stored under unrelated names. One book initially selected for evaluation had a training twin for 651 of its 672 clips—96.9%—despite the absence of filename matches.
After removing the duplicate material, Osmanov reports that 15.5 hours of speech remained for training, with no held-out clips in training and no six-word matches. The practical lesson is simple: filenames identify files, not necessarily the recordings or text inside them. Content checks are essential when corpora have been resegmented, renamed, or assembled from multiple sources.
Choose splits that match the data’s structure
For this project, books and readers were meaningful grouping units. In another corpus, the leakage risks might follow recording sessions, speakers, devices, locations, or source documents. A random clip split can still be useful for some purposes, but it should not be treated as a test of independence when neighboring clips share those sources.
The Tool Desk
Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →What the model results do—and do not—show
Osmanov reports three stages of performance. WER counts word substitutions, deletions, and insertions relative to a reference; character error rate (CER) measures analogous edits at the character level. Lower values indicate fewer errors under the chosen scoring and text-normalization rules.
Rank #2

- 【HIGH DEFINITION AUDIO 】 This microphone embeds a patented audio filter in order to record only your voice. Good for home studio, Chatting, Skype,Discord, Yahoo Recording, YouTube Recording, Google Voice Search and Steam.
- 【PLUG & PLAY 】 You just need to plug the microphone and it will work ! No software to install. A single button to turn it on or off. Compatible with every operating system - Mac OS X Windows Linux - and every PC brand.
- 【SMOOTH AND CLEAR】 Noise cancellation and isolates the main sound source, This USB Microphone is perfect for videoconferencing, Skype, dictation or voice recognition. The audio filter will give you a clear and confident voice. Anti-pop filter included !
- 【MUTE BUTTON & LED INDICATOR 】One click to mute/unmute your microphone,Build-in LED indicator tells you the working status at any time.Built with a mix of metal and heavy duty plastic, it's solid as a tank. It is very stable thanks to its weight.360 Degree Position Adjustable Gooseneck Design --Adopting the design of metal gooseneck pipe pickup the sound from 360-degree with high sensitivity
- 【SATISFACTORY SERIVCE】- 30 days unconditional return. TKGOU Customer service 2 years, We are committed to ensuring that you are 100% satisfied, If you have any questions, please contact us directly.We will provide you with a more friendly and satisfactory service.
| Project stage | Reported WER | Reported CER | What changed |
|---|---|---|---|
| Starting model | 34.6% | 11.9% | Baseline recognition |
| After fine-tuning | 20.1% | 9.4% | Adapter training changed the model |
| After decode-time tuning | 17.0% | 7.0% | Decoding settings changed; model weights did not |
All values are Osmanov’s reported results for this Crimean Tatar project, published by DEV Community in 2026; they are not general ASR benchmarks. The baseline WER also slightly understates recognition errors in one case: the model rendered a year as digits while the reference spelled it out, and the scorer counted four substitutions. That discrepancy reflects text normalization as well as recognition.
A small adapter, trained on a small corpus
After duplicate cleanup, the author froze a starting model of about 1.5 billion parameters and trained an adapter with 31 million trainable parameters. The report gives three epochs and 705 training steps, completed in 90 minutes on a home GPU, with 10.4 GB peak VRAM use; the adapter was 126 MB. These are measurements from this particular setup, not hardware requirements or expected training times for another dataset or model.
Checkpoint 100 performed worse than the starting model, while most of the gains had appeared by around step 200. That is a reminder to evaluate checkpoints rather than infer progress from training time or step count. A training run can finish successfully without producing a useful model.
Why development and test scores diverged
The project used three distinct data roles: training examples to fit the adapter, a 255-clip selection set of roughly half an hour to choose checkpoints and decoding settings, and the held-out books for final testing. Osmanov reports 17% WER on the selection set but 34.6% on the test set. The selection material was easier, so its score was not a reliable estimate of performance on the more challenging held-out conditions.
Rank #3

- [Convenient Setup] Plug and play recording USB microphone for PC, with 5.9-Foot USB cable included for computer PC laptop, is connected directly to USB-A port for recording music, computer singing or podcast. The office condenser microphone for computer is easy to use and install. (NOT compatible with Xbox and Phones)
- [Durable Metal Design] Solid sturdy metal construction design, the computer microphone for Zoom meetings with stable tripod stand is convenient when you are doing voice overs or livestreams on YouTube. Durable material extends the service life of the voice-over microphone.
- [Mic Volume Knob] Gaming condenser USB mic compatible for PS4 with additional volume knob itself has a louder or quieter adjustment and is more sensitive. Your voice would be heard well enough through the zoom microphone USB when gaming, skyping or voice recording. Also, you can adjust your volume to zero and protect your privacy.
- [Widely Use] USB-powered design, the condenser microphone for recording no need the 48v Phantom power supply, works well with Cortana, Discord, voice chat and voice recognition. The podcast microphone for Mac, with USB-B to USB-A/C cable, is compatible with desktop, laptop or PS4/PS5, which meets most of your daily recording needs.
- [Clear Output Voice] Cardioid condenser microphone for PC captures your voice properly, producing clear smooth and crisp sound. Great computer recording mic for gamers/streamers/youtubers focus on the main source and reduces background noise. The streaming microphone does the job well for broadcast ,OBS and teamspeak.
A development set is useful for ranking alternatives; a test set is for estimating performance under its own conditions. Repeatedly choosing configurations based on test results turns the test set into another selection set, making its score less independent. Osmanov says the selection rule was written before inspecting test results and that the final test set was kept out of repeated configuration selection.
Decoding improved results without retraining
Fine-tuning changes model weights, but the decoder also affects which words appear in the transcript. Osmanov tested 24 decoding configurations on the selection set and applied the chosen configuration to the test set. Beam search keeps multiple candidate token sequences in consideration rather than committing greedily at each step. In this case, decode-time tuning lowered reported test WER from 20.1% after fine-tuning to 17.0%, and CER from 9.4% to 7.0%, with no further weight changes.
The trade-off was speed: beam search was 3.1 times slower than the preceding decoding configuration in Osmanov’s setup. Whether that cost is acceptable depends on the application. Batch transcription of an archive may tolerate extra latency; an interactive service may not.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
A few looping clips accounted for many errors
Aggregate scores concealed a concentrated failure mode. Three of the 893 held-out clips looped, accounting for 160 of 409 recovered word errors—although together they represented only 0.34% of the test material. Beam search eliminated looping in the held-out set and contributed to the improved score. This is not evidence that every clip improved uniformly: it shows how a small number of severe failures can dominate an overall error count.
Rank #4

- Microphone grille with optimized structure
- Integrated pop filter
- International products have separate terms, are sold from abroad and may differ from local products, including fit, age ratings, and language of product, labeling or instructions.
That distinction matters when transcripts will feed an archive or another training stage. A looping transcript can introduce far more corrupt text than an ordinary, localized recognition error. Inspecting outlier clips and listening to them can therefore reveal problems that a single corpus-wide score hides.
Repetition is not always an error
The author also tried a repeated n-gram ban, intended to prevent the decoder from repeating the same sequence of words. On the 255 selection clips, it broke 17 cases and fixed one; 12 of the broken cases had been essentially perfect before the constraint. In the Crimean Tatar examples, repeated forms of address or pleading were natural speech, not hallucinated loops.
A generic anti-repetition rule can therefore “fix” a statistical pattern while damaging legitimate language. Such constraints need to be checked against real examples in the target language, especially where names, discourse patterns, or morphology make repetition ordinary. Osmanov did not report a score for Whisper’s temperature fallback: the selection set contained no looping clips with which to test whether that intervention helped.
Recommended Free Tools
Robustness depends on the recording conditions
To probe noise sensitivity, Osmanov corrupted the same 893 clips in 17 ways. In the reported exercise, equal-loudness competing speech raised WER from 17% to 69%; steady noise was less damaging than babble, and music was less damaging still. A hallway-sized reverberant room multiplied errors by 2.5. A telephone-band filter did not worsen the score in this test, while a tempo change of plus or minus 15% cost at most 6%.
Best Value
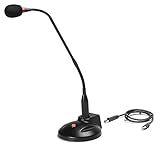
- The GN-USB-2 gooseneck is specially designed for professional voice communications. The GN-USB-2 is compatible for applications such as Hands-free dictation, PC recording software, voice recognition and internet chat.
- Features: Plug n Play, Noise cancelling, On/Off LED indicator, Detachable USB A~B cable, 16 inch adjustable neck, Weight base with non-skid rubber mounts
- Specifications: Element: fixed-charge back plate, permanently polarized condenser, Polar Pattern: Hypercardioid, Sensitivity: -40 +/- 2dB(0dB=1V/Pa at 1KHz), Frequency Response: 40Hz~16KHz, Output Impedance: 75-Ohm +/- 30% Max Input S.P.L.: 138dB, Signal/Noise Ratio: 65dB, Output Connector: USB A~B. Power Supply: Phantom Power 3V DC
- Operating Systems: Microsoft Windows 2000, Windows XP, Windows 7 and Windows 8 , Apple Mac Os9 and all OX X variations
These are results from the author’s corruption exercise, not universal rankings of acoustic conditions. They do suggest that overlapping speech and reverberation deserve particular attention in this setup. Osmanov’s interpretation is that source separation and microphone placement may matter more than simply filtering steady noise; the reported experiments support that as a project-specific conclusion, not a guarantee for other systems or environments.
A practical evaluation sequence for low-resource ASR
- Define what the test should represent. Identify the likely sources of dependence in the corpus—such as speaker, book, session, or device—and hold out complete groups that match the intended generalization question.
- Audit content, not only filenames. Look for repeated text spans or other content-level matches across splits. In this project, six-word matching exposed duplicates that file-name checks missed.
- Keep data roles separate. Use training data to fit the model, a selection set to rank checkpoints and decoding choices, and a held-out test set for final evaluation.
- Check errors at more than one scale. Report corpus-level WER and CER, then inspect severe outliers. A handful of looping clips accounted for a substantial share of recovered word errors here.
- Test decoding constraints against the language. Measure both fixes and regressions. A rule that prevents repetition can also erase valid repeated speech.
- Measure operational costs and conditions. Accuracy gains may come with slower decoding, and noisy or reverberant inputs may behave very differently from clean recordings.
What this case study can establish
Osmanov’s report demonstrates why training results are inseparable from dataset construction, split design, text normalization, decoding, and error analysis. In this case, deduplication changed what the held-out score meant; fine-tuning helped; decoding changes improved it further; and a small number of looping clips explained a disproportionate share of errors.
The precise scores should be read as author-reported results for one Crimean Tatar corpus and one setup. The DEV Community publication line says “Sep 23” without a year; search indexing associates the post with 2026. The post does not identify the exact starting-model checkpoint or provide every decoding configuration, so its numbers do not constitute a fully specified recipe for replication.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

