The best web-scraping API is the one that reliably returns your required fields from your actual target pages at an acceptable billable cost. A page-fetching endpoint may return HTML only; other services provide target-specific datasets, CSS/XPath selectors, or AI-generated JSON. Rendering JavaScript, using premium access, and adding an extraction layer can multiply usage. No controlled, same-target benchmark establishes a universal winner for accuracy, success rate, latency, or total cost, so treat vendor feature pages as capability descriptions and validate candidates with your own URLs and schema.
What a structured-data scraping API actually does
A scraping API accepts a URL or target request, retrieves the page through the provider’s infrastructure, and returns content or fields your application can consume. “Structured data” is not one standardized product feature. It can mean any of the following:


As an Amazon Associate I earn from qualifying purchases.
- Target-specific parsing: a provider recognizes a supported site or page type and returns a documented dataset.
- Selector or rule extraction: you supply CSS selectors, XPath expressions, or JSON extraction rules.
- AI or natural-language extraction: you describe the fields and receive values mapped to a JSON-like response.
- Raw content: the API returns HTML or rendered content, leaving parsing to your code.
Before comparing providers, define the exact schema: field names, data types, required versus optional values, pagination behavior, and how missing or ambiguous values should appear. An API that successfully downloads a page but omits a required field is not a successful extraction for your application.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
How to choose: workload first, vendor second
Start with target coverage
List every domain and page type you need. Product pages, search results, listings, news articles, and account-gated pages often use different layouts and access requirements. Confirm that a provider documents support for your target or offers a generic mode that you can configure. Do not infer coverage from a provider’s general statement that it supports “millions of websites.”
#1 Best Overall
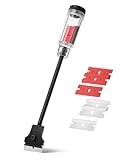
- Bates long reach extension scraper comes with a 11-inch handle for extended reach and includes 3 double-edged plastic blades and 3 metal blades for versatile use.
- The scraper is made from durable materials, ensuring reliable performance and long-lasting use for a variety of tasks.
- The 11-inch handle provides enhanced leverage and control, making it ideal for hard-to-reach areas or demanding scraping jobs.
- The interchangeable blades offer flexibility, with plastic blades designed for delicate surfaces and metal blades for tougher scraping tasks.
- This tool is perfect for removing paint, adhesives, stickers, and other residues, making it a must-have for home improvement and professional projects.
Decide whether you need rendering
If the required values are present in the initial HTML, a non-rendered request may be sufficient. If JavaScript builds the page, triggers an API call, or reveals content only after interaction, you may need a browser-rendered request or a target-specific collector. Rendering normally consumes more credits or a higher-priced request unit. Test the same URL with and without rendering and compare field completeness, not just HTTP status.
Choose an extraction method
- Stable, known layout: selectors or a maintained parser can be predictable and inexpensive, but your team owns breakage when markup changes.
- Many unrelated layouts: AI or natural-language extraction reduces selector work, but adds processing charges and can produce uncertain values that require validation.
- Known supported target: a target-specific dataset may provide normalized fields without building your own parser; verify its field definitions and update policy.
- Maximum control: raw HTML or rendered output lets you implement custom parsing, normalization, and quality checks at the cost of engineering time.
Comparison of documented options
The table reflects capabilities and pricing details documented by providers, checked in 2026. It is not a head-to-head performance ranking. “Not stated” means the reviewed material did not establish a comparable value.
| Provider/product | Output and extraction model | Target coverage and access handling | Cost model documented | Workflow notes |
|---|---|---|---|---|
| Oxylabs Web API | Search and scrape functions, target-specific data collection, and separately priced AI parsing. Depending on the request, output can be parsed results or page content. | Official material lists target-specific modes and separate Google, Amazon, and “other targets” pricing rows. Rendering and other request characteristics must be matched to the selected product and target; do not assume every mode is included in one rate. | Target- and tier-specific per-result charges. Displayed lower-tier examples include Google non-JavaScript at $1.00 per 1,000 results and Amazon non-JavaScript at $0.50 per 1,000 results. AI parsing is listed at $3.00 per 1,000 parsed pages in the displayed tiers. These are vendor-listed rates that can change. | API-based collection with product documentation at the Web API page and rates at the pricing page. |
| ScrapingBee | Classic page retrieval plus AI extraction using natural-language instructions or JSON extraction rules. You can request fields without writing CSS/XPath parsing on your side. | Documentation describes requests with and without JavaScript rendering and proxy classes. Confirm that the target’s layout and access behavior fit the selected request type. | Published credit rules: classic proxy without rendering costs 1 credit; classic proxy with rendering, 5 credits; premium proxy without rendering, 10 credits; premium proxy with rendering, 25 credits. ai_query and ai_extract_rules add 5 credits to the regular API cost. Credits must be mapped to the current plan before calculating money. |
Extraction syntax and request examples are in the data-extraction documentation; request-cost rules are in the API documentation. |
| Bright Data Web Scraper API | Cloud scraping service with a library of scraper APIs and no-code scrapers. Its FAQ describes structured parsing as part of the service. | The provider describes IP rotation, CAPTCHA handling, and parsing as service functions. These are vendor descriptions, not independent measurements or a guarantee for your target. | Current comparable prices were not established from the reviewed page; do not use a headline or quote a rate without checking the live listing. | Product and pricing information is presented at the official Web Scraper API page. |
| Apify | Adjacent option worth shortlisting when an appropriate actor or workflow is documented. | Target coverage, extraction behavior, and rendering details vary by actor. The reviewed pricing material did not provide enough information for a comparable feature or price claim. | Not stated for this comparison. | Check current terms and product details at Apify pricing before including it in a purchase decision. |
| Zyte API | Adjacent API option; the reviewed usage documentation did not expose enough detail for a side-by-side extraction claim. | Not stated for this comparison. | Not stated for this comparison. | Review the current Zyte API usage documentation for your target and billing unit. |
Provider profiles and when each model fits
Oxylabs Web API: target-aware collection with explicit result pricing
Oxylabs documents both search and scrape functionality and target-specific data collection. Its pricing page separates rates by target and usage tier rather than presenting one universal per-page number. The displayed lower-tier examples are $1.00 per 1,000 Google non-JavaScript results and $0.50 per 1,000 Amazon non-JavaScript results. A separate AI-parsing line shows $3.00 per 1,000 parsed pages in the displayed tiers.
Do these 3 things before closing this tab:
1Fix the driver behind crashes, sound loss and screen glitches2Clear out junk files and repair common Windows errors3Scan for outdated or missing drivers - takes under a minuteThose figures are not interchangeable. A Google request, an Amazon request, an “other target,” a rendered page, and a page sent through AI parsing may be billed under different rows or units. To estimate a month, classify each request by target, rendering requirement, extraction mode, and volume tier, then multiply the number of billable results by the applicable row. Recheck the live pricing page because vendor rates and tier thresholds can change.
ScrapingBee: configurable requests plus AI extraction rules
ScrapingBee’s data-extraction documentation is aimed at teams that do not want to parse HTML themselves. Its wording is direct: “If you want to extract data from pages and don’t want to parse the HTML on your side and play with CSS or XPATH selectors, you can add AI extraction rules to your API call.” You can describe the desired fields with a natural-language query or provide JSON extraction rules.
The credit schedule makes request design important. A non-rendered classic request costs 1 credit, while rendering raises that to 5. Premium proxy requests cost 10 credits without rendering or 25 with rendering. Adding ai_query or ai_extract_rules adds 5 credits on top of the ordinary request. Thus, 1,000 simple non-rendered requests with no AI would consume 1,000 credits under the documented rules; 1,000 rendered premium requests with AI extraction would consume 30,000 credits (25 + 5 per request). That is a credit calculation, not a cash price: convert it using the plan you would actually buy.
Bright Data Web Scraper API: managed scraper catalog
Bright Data presents a cloud Web Scraper API for high-volume extraction, with a library of scraper APIs and no-code scrapers. Its FAQ describes scraper APIs as services that automate IP rotation, CAPTCHA handling, and parsing into structured formats. Those statements describe the vendor’s offering; they do not establish a success rate, accuracy percentage, or legal permission to collect any particular site.
Quick wins for a faster PC:
Clear out junk files and repair common Windows errorsFree Scan →Scan for outdated or missing drivers - takes under a minuteDriver Scan →Repair Windows errors before they cause bigger problemsFix Now →Because a comparable current price was not available in the reviewed page text, request a quote or inspect the live pricing page for the exact scraper, volume, rendering, and output mode you need. Ask which unit is charged and whether parsing, storage, or browser execution is metered separately.
Rank #3

- Save Your Nails with Scrigit Scraper - The ultimate multi-use plastic scraper tool works for many tasks at home or on the go; an ideal dried-on food scraper, label scraper, sticker removal tool, and even a handy chrome delete tool for automotive detailing.
- No-Scratch Super Scraper: One side of your Scrigit Scraper tool has a flat edge that's best for flat surfaces and larger areas. The other side has a round edge, best for curved surfaces and smaller areas. Dishwasher safe and easy to hold, just like a pen.
- Made in the USA – Let this crevice cleaning tool do the work for you in hard-to-reach areas. Made from durable plastic, it's safe for most surfaces, works great as a label remover tool, and even doubles as a lottery scratch-off tool. Proudly MADE IN THE USA!
- Keep Handy Everywhere You Need It: Keep your slim scraper pen Scrigit tool at home, in your vehicle or office. It's the ultimate crevice tool to keep in your cleaning box to remove grime from those hard-to-reach areas of your kitchen and bathroom.
- Convenient Size: Our slim detailing tools are 6 inches long x 3/8 inches in diameter with a convenient pocket clip. Why not buy some for your friends, because everyone can find a use for a Scrigit Scraper.
Apify and Zyte: shortlist only after current documentation checks
Apify and Zyte may be relevant adjacent options, but the reviewed pages did not provide enough detail to make a current, fair price or feature comparison. If you shortlist either, document the specific actor or API operation, target coverage, output schema, rendering behavior, retry policy, and billing unit before comparing it with the options above.
What “returns JSON” really means
Many APIs can serialize a response as JSON while still returning one large HTML string. Ask four questions:
- Are the requested fields returned as named properties, or is the HTML merely wrapped in JSON?
- Can you define the schema and data types, or does the provider choose field names?
- How are absent, null, duplicated, and ambiguous values represented?
- Does pagination produce one record per item, nested arrays, or a provider-specific envelope?
For AI extraction, add validation after the API call. Check that dates parse, prices use the expected currency, URLs are valid, and enumerated fields contain allowed values. Store the original URL, retrieval time, extraction mode, and response identifier so a bad value can be traced without silently overwriting good data.
Handling JavaScript-heavy websites
Determine whether the needed data exists in the server response, appears after a script runs, or is loaded from a separate endpoint. A rendered request can solve the second case, but it may cost several times more than a basic request and can add latency. A target-specific API may already model the site’s data, while a generic browser request may still require selectors or AI extraction.
Rank #4

- Practical cleaning tools: you will get 9 piece of plastic scraper tools, enough quantity to satisfy your daily use, or you can share them with family and friends, so that you will be able to remove small amounts of various common substances easily
- 3 Kinds of two-way scraper tools: the 3 kinds of two-way scratch free plastic scrapers are proper for various occasions; The wide scraper head can be applied to scrape wide areas, such as smudges on the ground, chewing gum, stickers, labels, etc.; The narrow scraper head can clean narrow spaces, as well as difficult to reach places of the car outside body and interior place; And the pointed scraper is very suitable for cleaning more narrow crevices, such as tight corners, edges, grooves
- Durable material: the stiff multipurpose label scraper is made of quality carbon fiber plastic, sturdy and durable, not easy to break under pressure, with high hardness, reusable, lightweight and easy to carry; You can let the scrape cleaning tool do the job and protect your nails
- Portable and easy to use: our cleaning pen-shaped scraper tool is 5.8 inch/ 14.6 cm long, small and convenient size for easily carrying out with you; Anytime you need it, just put it in your handbag, tool box, or anywhere proper for you
- Wide applications: this plastic scraper tool is ideal for cleaning crevices, while protecting your nails; They are also suitable for removing label stickers, grease, paint, candle wax, dirt, soap, dried foods, ticket and more on kitchen, car, bathroom, office, motorcycle, boat, workshop, garage; It can also be applied as a pry open electronic repair tool for LCD, tablet
- Fetch a representative URL without rendering and inspect whether all required fields are present.
- Repeat with rendering enabled and record the additional billable units and elapsed time.
- Compare values, not just status codes: verify prices, availability, images, pagination, and nested attributes.
- If content is loaded through interaction, identify the documented interaction or endpoint supported by the provider rather than assuming a static render will reproduce it.
Do not treat an API’s ability to retrieve a page as authorization to bypass access controls. Use only methods allowed by the provider, target site, and applicable rules.
How much does scraping cost per 1,000 pages?
There is no meaningful universal “per 1,000 pages” price until the billable unit is known. One provider may charge per result, another per credit, and another by scraper, browser execution, data volume, or subscription tier. The same 1,000 URLs can require different units if half need JavaScript rendering or AI parsing.
| Scenario | Documented unit calculation | What remains to price |
|---|---|---|
| Oxylabs, 1,000 Google non-JavaScript results at the displayed lower tier | 1,000 results × $1.00 per 1,000 results = $1.00 at that listed tier | Confirm the current tier, target classification, subscription terms, and whether any rendering or parsing add-on applies. |
| Oxylabs, 1,000 Amazon non-JavaScript results at the displayed lower tier | 1,000 results × $0.50 per 1,000 results = $0.50 at that listed tier | Confirm the live rate and applicable tier; this does not represent other targets or JavaScript requests. |
| Oxylabs, 1,000 pages with the displayed AI-parsing line | 1,000 parsed pages × $3.00 per 1,000 pages = $3.00 at that listed tier | Confirm whether the base scrape, target charge, and AI parsing are all billed for your request. |
| ScrapingBee, 1,000 classic non-rendered requests with AI extraction | 1,000 × (1 + 5) = 6,000 credits | Map 6,000 credits to the current plan; credit value is not a universal cash rate. |
| ScrapingBee, 1,000 premium rendered requests with AI extraction | 1,000 × (25 + 5) = 30,000 credits | Map credits to the plan and account for retries or additional requests. |
Include retries, pagination, failed responses that are still billable, and validation calls in your estimate. Run a small sample first; extrapolating from a headline plan price can understate the real bill.
AI extraction API or your own parser?
Choose AI extraction when
- Layouts vary across many sites and maintaining selectors would consume more engineering time than the per-request surcharge.
- You can tolerate occasional uncertainty and have validation, review, or reprocessing in place.
- Your schema changes often and natural-language instructions are easier to update than parser code.
Choose selectors or a custom parser when
- The target layout is stable and high volume makes recurring AI charges significant.
- You need deterministic transformations, strict typing, or reproducible output for regulated workflows.
- Your team can monitor markup changes and maintain tests for each page type.
Use a hybrid
A practical design is to use target-specific or selector extraction for stable fields, AI only for irregular text, and a raw-content fallback for debugging. Record which method produced each field so downstream users can distinguish deterministic values from inferred ones.
A representative trial that predicts production behavior
Before committing to a plan, test 10–30 representative pages spanning every site, layout, language, and rendering behavior you will operate. Define the schema before sending requests so the comparison measures your real acceptance criteria.
- Select URLs: include ordinary pages, edge cases, pagination, missing fields, changed layouts, and JavaScript-only content.
- Run equivalent requests: use the same URLs and extraction instructions wherever the candidate interfaces permit it. Record rendering, proxy, AI, and retry settings.
- Check completeness: count required fields present on every record and inspect nested arrays, types, units, and normalization.
- Check correctness: compare each value with the page, noting truncation, stale content, hallucinated values, and wrong associations.
- Check missing-value behavior: verify whether absent data is null, omitted, empty, or replaced with a guessed value.
- Measure operations: record successful requests without manual retries, end-to-end latency at your intended concurrency, and error categories.
- Reconcile billing: count results, credits, rendering charges, AI charges, retries, and any storage or transfer units shown in the account.
- Test ingestion: load the output into your actual database or queue and confirm that no second parser is required.
- Repeat for freshness: run the sample at the interval your product needs; a one-time success does not prove ongoing stability.
Keep the sample and expected outputs as a regression suite. Re-run it after changing providers, extraction prompts, selectors, rendering settings, or plan tiers.
Reliability, latency, and accuracy: what is not established
Provider documentation can show that an endpoint or mode exists, but it does not prove that one service extracts your fields more accurately or consistently than another. No independently published, controlled head-to-head figure for accuracy, reliability, or latency is established here. Do not convert marketing terms such as “high volume,” “automated,” or “AI-powered” into a success-rate statistic.
Recommended Free Tools
Measure the dimensions that matter to your workload: field-level completeness, value correctness, successful-request rate, p95 latency at production concurrency, freshness, and cost per accepted record. Report the target set, date, request settings, and treatment of retries whenever you publish internal results.
Responsible collection and robots.txt
Robots.txt is a crawler protocol, not a grant of access. The IETF’s September 2022 RFC 9309 states: “These rules are not a form of access authorization.” Read RFC 9309 for the standard’s scope and terminology.
Honor the target site’s published crawler instructions where applicable, review its terms, and assess privacy, copyright, database-rights, contract, and other rules relevant to your location and use case. An API’s technical ability to retrieve a URL does not establish permission to collect, republish, or resell its contents. Avoid attempts to defeat authentication, paywalls, rate limits, or other controls unless you have explicit authorization.
Decision checklist
- Have you named every target domain and page type?
- Is the required schema written down, including types and missing-value rules?
- Did you determine which pages need JavaScript rendering?
- Do you know whether the provider returns parsed fields, selector output, AI values, or raw content?
- Have you converted the workload into the provider’s actual billable unit?
- Did you include rendering, AI, premium access, retries, pagination, and validation in the estimate?
- Have you tested 10–30 representative URLs at realistic concurrency and freshness?
- Are you storing provenance and validating extracted values before they reach production?
- Have you reviewed robots.txt, terms, and applicable law for each target?
The shortlist is therefore workload-dependent: Oxylabs is worth examining when target-specific result modes and explicit target-tier pricing fit your pages; ScrapingBee is a candidate when configurable requests and documented AI extraction rules reduce parser maintenance; Bright Data is relevant when its managed scraper catalog matches your targets and its live commercial terms fit your volume. Apify and Zyte require a fresh, operation-specific review before a fair comparison. Choose only after your representative test shows that the returned records, operational behavior, and billable units meet your requirements.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

