Freedom251 › AI Video Lip Sync Tools
X-Dub
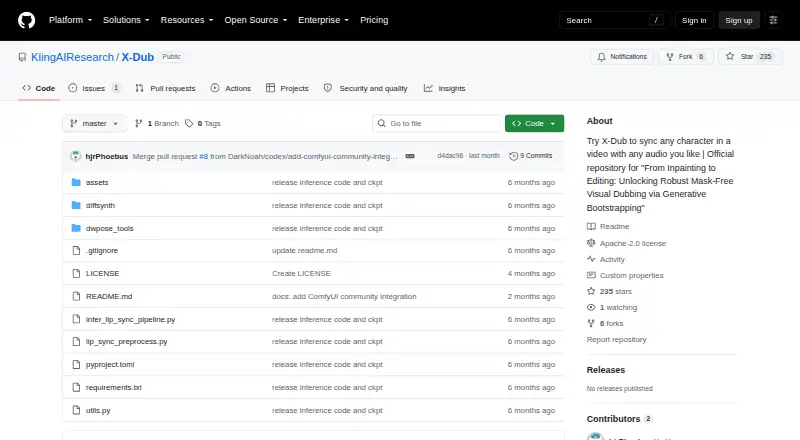
What X-Dub is
X-Dub is a free, Apache-2.0 open-source PyTorch project that synchronizes a character’s mouth movements with an audio track through visual dubbing. Its mask-free method uses full-frame temporal context without explicit masks or reference frames, and is described as supporting speech-aligned lip movement while limiting leakage and off-target edits. It is intended for human, stylized, non-human, and AI-generated characters. The public Wan-5B release is based on Wan2.2-TI2V-5B; the internal paper model is not open sourced. Videos of any size are accepted, while the pipeline crops and resizes the face to 512×512 before restoring the result to the full frame. The current release supports one-person videos only and has no target tracking for multi-person scenes. Inference generally needs about 21 GB of VRAM. Results may flicker, drift in identity or color, or contain severe noisy frames in roughly 2% of cases. DWPose cropping can jitter during rapid head movement.
Who it suits
X-Dub suits developers who can set up a local Python environment and provide substantial GPU memory. It is also relevant to creators working with stylized or synthetic characters, provided they handle the stated video limitations and responsible-use concerns.
What it does well
- Free and open-source
- Supports arbitrary-size input videos
- Works with stylized and AI characters
- Downloadable pretrained weights
- Community ComfyUI nodes available
What to know first
- Requires about 21 GB VRAM
- Single-person videos only
- Possible flicker and identity drift
- Cropping may jitter during fast movement
Verdict
X-Dub offers local, open-source visual dubbing with broad character support and downloadable weights. Its hardware demand, single-person restriction, slower public release, and possible visual artifacts should shape expectations before setup.
Facts from X-Dub's own pages
- Character support
- The project says it generalizes to stylized, non-human, and AI-generated characters. · hjrphoebus.github.io, 11 Oct 2026
- Community integration
- The repository links to community-maintained ComfyUI custom nodes with native video and audio inputs, standard VAE integration, and an isolated runtime. · github.com, 4 Oct 2026
- Cropping caveat
- The online DWPose-based cropping strategy may cause visible jitter or fail to follow faces during rapid head movement. · github.com, 4 Oct 2026
- Editing approach
- The project describes mask-free dubbing that uses full-frame temporal context without explicit masks or reference frames. · hjrphoebus.github.io, 11 Oct 2026
- Ethical use
- The repository warns of possible identity impersonation or deceptive synthetic media misuse and supports clear labeling of AI-generated content. · github.com, 11 Oct 2026
- Hardware requirement
- The repository says inference typically requires about 21 GB of VRAM. · github.com, 11 Oct 2026
- Input handling
- The inference pipeline accepts arbitrary-size input videos and automatically crops and resizes the face region to 512×512 before mapping the generated result back to the full video. · github.com, 4 Oct 2026
- Integration
- The repository links a community-maintained ComfyUI project with custom nodes for X-Dub. · github.com, 11 Oct 2026
- Intended users
- The project provides code, model weights, and command-line inference instructions for users setting up a local Python environment. · github.com, 4 Oct 2026
- Known limitations
- The public Wan-5B release may show flickering, identity or color drift, occasional noisy frames, and roughly twice the inference time of the internal version without acceleration. · github.com, 11 Oct 2026
- License
- The repository lists the Apache-2.0 license, which grants no-charge, royalty-free copyright permissions subject to its terms. · github.com, 11 Oct 2026
- Lip-sync
- The project says it produces speech-aligned lip movements while avoiding leakage and off-target edits. · hjrphoebus.github.io, 11 Oct 2026
- Output caveats
- The public release may show occasional flickering, identity or color drift, and severe noisy frames in roughly 2% of cases; the repository also reports roughly 2× slower inference than the internal version without acceleration strategies. · github.com, 4 Oct 2026
- Project affiliation
- The repository lists contributors affiliated with Tsinghua University, Kling Team at Kuaishou Technology, Beihang University, HKUST, and CUHK. · github.com, 4 Oct 2026
- Public release
- The repository provides a public X-Dub release based on Wan2.2-TI2V-5B and pretrained weights. · github.com, 11 Oct 2026
- Purpose
- X-Dub synchronizes a character’s lip movements in a video to match input audio. · huggingface.co, 11 Oct 2026
- Responsible use
- The project notes potential misuse for identity impersonation or deceptive synthetic media and encourages labeling AI-generated content. · github.com, 4 Oct 2026
- Single-person limit
- The current release supports single-person videos and does not support target tracking in multi-person scenes. · github.com, 4 Oct 2026
- Support
- The repository invites users to open an issue for suggestions and provides a contact email for questions. · github.com, 11 Oct 2026
- Video input limit
- The current auto-cropping pipeline supports single-person videos and does not support target tracking in multi-person scenes. · github.com, 11 Oct 2026
- Weights
- Pretrained weights are downloadable from the KlingTeam/X-Dub Hugging Face model repository. · github.com, 4 Oct 2026
Where X-Dub stands on Freedom251
- AI Video Lip Sync Tools#22 of 28