Freedom251 › Website Accessibility Tools
WCAG Crawler
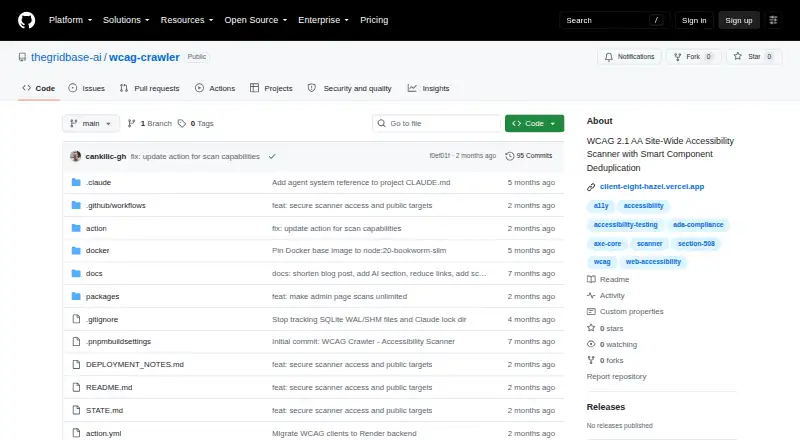
What WCAG Crawler is
WCAG Crawler is free, MIT-licensed software for scanning websites against WCAG 2.0 and WCAG 2.1 A/AA criteria. It automatically discovers pages within a domain using Playwright, with configurable crawl depth and URL patterns. Findings can be grouped across shared components, and the crawler identifies duplicate pages and repeated failing selectors. Reports provide severity filters, WCAG references, Deque University links, and before-and-after code suggestions. A GitHub Action can scan a URL in CI/CD and fail workflows when a score threshold or critical issue is reached. The API starts, lists, retrieves, deletes, and cancels scans, and can retrieve or export HTML reports. Deployments are available through web, Linux, API, or self-hosting, with Docker documentation and Vercel, Railway, or Render components. Self-hosted data stays in that instance, with scan history in localStorage. Credentials are used only during scans. Anonymous scans allow 10 pages at depth 2; verified users allow 50 pages at depth 3; allowlisted admins allow 100 pages at depth 5. Automated checks do not replace expert manual evaluation.
Who it suits
It suits developers, web agencies, enterprises, and government teams integrating accessibility checks into websites or CI/CD. Self-hosting is available for organizations needing local data storage.
What it does well
- Checks WCAG 2.0 and 2.1 A/AA
- Groups shared component issues
- Provides remediation code suggestions
- GitHub Action supports CI/CD
- MIT license permits self-hosting
What to know first
- Automated scans do not certify compliance
- Anonymous scans capped at 10 pages
- Higher limits require verified or allowlisted access
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| WCAG Crawler | Hosted use: no account needed · anonymous scans: 10 pages, depth 2, concurrency 1 · self-hostable under MIT license | Free |
As github.com lists them, read 12 Oct 2026. The maker's own page has the final word.
Verdict
WCAG Crawler offers crawl-based accessibility checks, reporting, API controls, and CI/CD integration without a software charge. Its scan caps and automated-only coverage mean larger or compliance-critical reviews need additional planning and manual evaluation.
Facts from WCAG Crawler's own pages
- API
- The API supports starting, listing, retrieving, deleting, and cancelling scans, plus retrieving and exporting reports as HTML. · github.com, 12 Oct 2026
- Authentication and access
- Signed-in users authenticate with verified Google ID tokens and access only scans they own; anonymous scan creation is rate-limited by IP. · github.com, 12 Oct 2026
- CI/CD integration
- A GitHub Action can scan a URL in a workflow and fail based on a score threshold or critical issues. · github.com, 12 Oct 2026
- Credential handling
- Target-site credentials are used only during a scan and are not persisted; credential-like URL values are rejected or sanitized. · github.com, 12 Oct 2026
- Deployment
- The repository documents Docker self-hosting and deployment with a Vercel frontend and Railway or Render backend. · github.com, 12 Oct 2026
- Headquarters
- Sarasota, Florida, US · github.com, 28 Sept 2026
- Intended users
- The project describes use by government agencies, web agencies, enterprises, and developers integrating accessibility checks into CI/CD. · github.com, 12 Oct 2026
- Issue grouping
- It groups shared component issues across pages and detects duplicate pages and repeated failing selectors. · github.com, 12 Oct 2026
- License
- The repository states that WCAG Crawler is MIT licensed. · github.com, 12 Oct 2026
- Privacy
- The project says no data leaves a self-hosted instance and scan history is stored in localStorage. · github.com, 12 Oct 2026
- Purpose
- WCAG Crawler scans websites for accessibility issues against WCAG 2.0 A/AA and WCAG 2.1 A/AA criteria. · github.com, 12 Oct 2026
- Reports
- Reports include severity filters, before-and-after code suggestions, WCAG references, and links to Deque University. · github.com, 12 Oct 2026
- Scan limits
- Anonymous scans are capped at 10 pages and depth 2; verified Google users at 50 pages and depth 3; allowlisted admins at 100 pages and depth 5. · github.com, 12 Oct 2026
- Site crawling
- It automatically discovers and scans pages within a domain using Playwright, with configurable depth and URL patterns. · github.com, 12 Oct 2026
- Testing limits
- Automated scans cover only programmatically identifiable issues and do not certify compliance or replace expert manual evaluation. · github.com, 12 Oct 2026
Where WCAG Crawler stands on Freedom251
- Website Accessibility Tools#58 of 133
- Accessibility Testing Software#75 of 169