Freedom251 › AI Podcast Generators
UNESCO PDF-to-Podcast
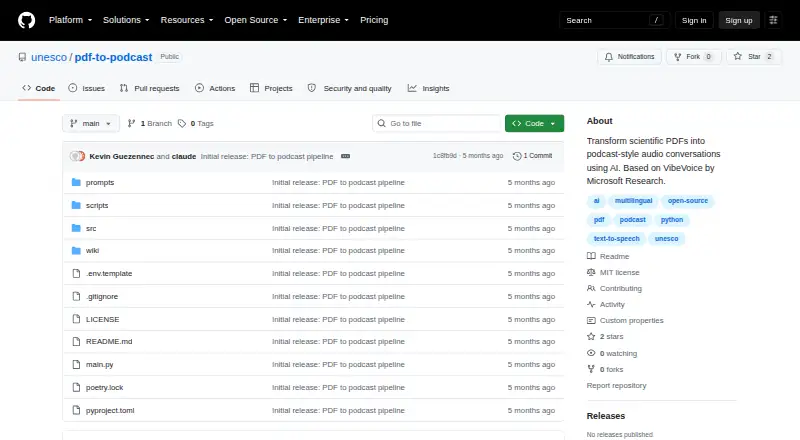
What UNESCO PDF-to-Podcast is
UNESCO PDF-to-Podcast is an open-source project that turns scientific PDFs into podcast-style conversations. It extracts structured content from a PDF, creates a conversational script, and synthesizes the audio. Scripts can be tailored for experts, the general public, young people, or novices, and generated in English, French, Chinese, Spanish, Arabic, or Russian. English and Chinese have included native voices; the other four languages use English voices unless users supply their own samples. Users can choose a target duration and select two to four speakers; the defaults are 10 minutes and two speakers. The documented pipeline uses Docling for PDF extraction, Ollama with Granite4 for script generation, and VibeVoice for audio synthesis. It runs from the command line and supports Linux, macOS, Windows, and self-hosted use. Setup requires Python 3.9 or later, Poetry, and Ollama. A GPU is recommended, while CPU use is also possible. It handles one PDF at a time, and long documents may need to be split into chunks. Audio generation can require substantial GPU memory, especially with the optional 7B model. Audio export is WAV, and the project supports voice cloning.
Who it suits
This project suits readers who want to turn scientific PDFs into conversational audio, with scripts tailored to different audiences and support for six languages. It is also suited to people comfortable setting up Python, Poetry, and Ollama and running a command-line pipeline.
What it does well
- Tailors scripts for experts, the general public, young people, or novices.
- Generates scripts in UNESCO’s six official languages.
- Lets users set duration and choose two to four speakers.
- Exports audio as WAV and supports voice cloning.
- Open source under the MIT license.
What to know first
- Processes one PDF at a time.
- Long PDFs may need to be split into chunks.
- Audio generation can require substantial GPU memory.
- Four languages use English voices unless users add samples.
Limits
The project processes one PDF at a time, and long documents may need chunking. Audio generation requires substantial GPU memory, especially with the optional 7B model; CPU use is also possible. The project is free and open source.
Getting started
- Open the project website on GitHub.
- Install Python 3.9 or later, Poetry, and Ollama.
- Follow the project’s installation instructions for macOS or Linux, using Poetry or pip in a Python environment.
- Run the pipeline from the command line with a PDF document.
- Set the target duration and choose two to four speakers.
Verdict
Choose UNESCO PDF-to-Podcast if you want a local, open-source pipeline for turning scientific PDFs into audience-tailored audio conversations. It offers language and speaker controls, but the one-PDF workflow and GPU memory demands may be limiting for larger workloads.
Questions
How much does UNESCO PDF-to-Podcast cost?
It is free and open source under the MIT license.
Which systems does it support?
Listed platforms are Linux, macOS, Windows, and self-hosted use.
Which languages can it generate?
It supports English, French, Chinese, Spanish, Arabic, and Russian. English and Chinese have included native voices; the other languages use English voices unless users add samples.
What does it use to create a podcast?
The pipeline uses Docling for PDF extraction, Ollama with Granite4 for script generation, and VibeVoice for audio synthesis.
What does setup require?
It requires Python 3.9 or later, Poetry, and Ollama. A GPU is recommended, with a CPU fallback.
What audio controls are available?
Users can set a target duration and select two to four speakers. The defaults are 10 minutes and two speakers.
Facts from UNESCO PDF-to-Podcast's own pages
- Audience options
- Scripts can be tailored for experts, the general public, young people, or novices. · github.com, 4 Oct 2026
- Audiences
- Scripts can be tailored for experts, the general public, young people, or novice audiences. · github.com, 4 Oct 2026
- Audio controls
- Users can set podcast duration and choose 2–4 speakers; the default duration is 10 minutes and default speaker count is 2. · github.com, 4 Oct 2026
- Hardware
- The README warns that audio generation requires significant GPU memory, especially with the optional 7B model. · github.com, 4 Oct 2026
- Install and run
- The maker documents installation with Poetry or pip in a Python environment and running the pipeline from the command line. · github.com, 4 Oct 2026
- Installation
- The project requires Python 3.9 or later, Poetry, and Ollama, and recommends a GPU while allowing a CPU fallback. · github.com, 4 Oct 2026
- Integrations
- The documented pipeline uses Docling for PDF extraction, Ollama with Granite4 for script generation, and VibeVoice for audio synthesis. · github.com, 4 Oct 2026
- Languages
- The project supports script generation in UNESCO’s six official languages: English, French, Chinese, Spanish, Arabic, and Russian. · github.com, 4 Oct 2026
- License
- The repository’s LICENSE file identifies the project license as MIT. · github.com, 4 Oct 2026
- License and maturity
- The repository labels the project MIT License (TBD) and identifies version 0.2.0 as MVP Complete. · github.com, 4 Oct 2026
- Limits
- The project currently accepts a single PDF at a time, with batch processing described as planned; long PDFs may need chunking. · github.com, 4 Oct 2026
- Local setup
- The README provides installation instructions for macOS and Linux. · github.com, 4 Oct 2026
- Maker
- The project’s pyproject.toml lists UNESCO Data & AI as its author contact. · github.com, 4 Oct 2026
- Maker profile
- The UNESCO GitHub profile describes its code repository as an open-source hub for education, science, culture, and sustainable development. · github.com, 4 Oct 2026
- Models and tools
- The pipeline uses Docling for PDF extraction, Ollama with Granite4 for script generation, and VibeVoice for audio synthesis. · github.com, 4 Oct 2026
- Notable limits
- The README says the project currently handles one PDF at a time, long PDFs may need chunking, and audio generation needs significant GPU memory, especially with the 7B model. · github.com, 4 Oct 2026
- PDF processing
- Its pipeline extracts structured PDF content, generates a conversational script, and synthesizes podcast audio. · github.com, 4 Oct 2026
- Pipeline
- Its pipeline extracts PDF content, generates a conversational script, and synthesizes podcast audio. · github.com, 4 Oct 2026
- Podcast controls
- Users can set a target duration and select between two and four speakers. · github.com, 4 Oct 2026
- Purpose
- The project converts scientific PDFs into podcast-style audio conversations using AI. · github.com, 4 Oct 2026
- Requirements
- The README lists Python 3.9 or newer, Poetry, and Ollama as prerequisites, and recommends a GPU while allowing CPU fallback. · github.com, 4 Oct 2026
- Security
- The README describes a local Ollama-based script-generation setup and makes no specific security certification or compliance claim. · github.com, 4 Oct 2026
- Support
- The project points users to GitHub Issues, Discussions, and wiki documentation for support. · github.com, 4 Oct 2026
- Voice availability
- English and Chinese have included native voices; French, Spanish, Arabic, and Russian fall back to English voices unless users add their own samples. · github.com, 4 Oct 2026
Where UNESCO PDF-to-Podcast stands on Freedom251
- AI Podcast Generators#12 of 23