Freedom251 › Active Metadata Management Software
Marquez
What Marquez is
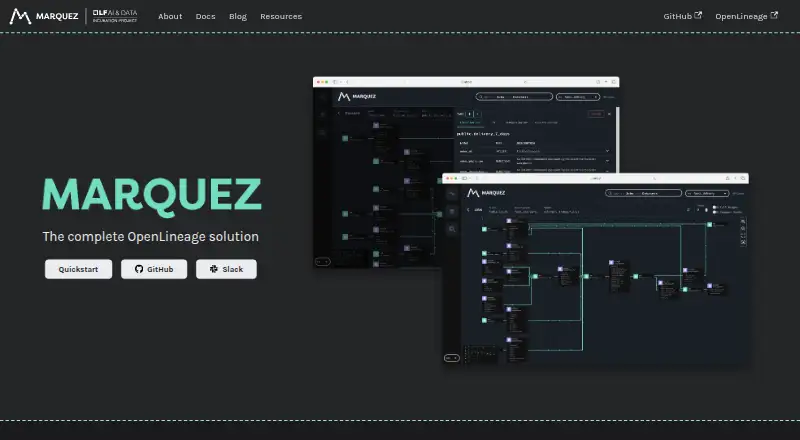
Marquez is an open-source system for collecting, storing and visualizing OpenLineage metadata from data jobs and applications. Its metadata server offers an OpenLineage-compatible endpoint for real-time collection. The web UI displays dependencies across a data ecosystem and lets teams examine job inputs and outputs, dataset lineage, performance metrics and execution details. A Lineage API supports dependency traversal and metadata queries for work such as backfills and root cause analysis.
Marquez keeps metadata versions, dataset changes and job run history, which can support auditing and investigation of downstream jobs affected by schema changes. Integrations named through the OpenLineage community include Apache Airflow, Apache Spark, Apache Flink, dbt and Dagster. The documented architecture comprises a metadata repository, REST API and metadata UI. Deployment guidance covers Docker and Kubernetes; the HTTP API server uses PostgreSQL to store dataset, job and run metadata. Marquez is free and open source. Its API does not require authentication or authorization by default, and column lineage support is limited to the Spark integration.
Who it suits
Marquez is designed for data teams managing metadata and lineage across processing applications and pipelines. It suits teams that need to inspect dependencies, job execution details or historical metadata, and can manage deployment with Docker or Kubernetes.
What it does well
- Collect OpenLineage metadata from running jobs in real time.
- Inspect job inputs, outputs, lineage and execution details in a web UI.
- Query lineage and traverse dependencies through its API.
- Track dataset changes and job run history.
- Integrates with Airflow, Spark, Flink, dbt and Dagster through OpenLineage.
What to know first
- API authentication and authorization are off by default.
- Column lineage support is limited to the Spark integration.
- Deployment guidance uses PostgreSQL for metadata storage.
Limits
Column lineage support is limited to the Spark integration. The HTTP API does not require authentication or authorization by default.
Getting started
- Review the quickstart prerequisites for MacOS/Linux or Windows.
- Deploy Marquez with Docker or Kubernetes.
- Run the Marquez HTTP server using Docker as described in the quickstart.
- Connect jobs or applications through the OpenLineage-compatible metadata endpoint.
Verdict
Choose Marquez if your data team needs an open-source system for collecting OpenLineage metadata and tracing dependencies across jobs and datasets. Look elsewhere if you need column lineage beyond Spark or require API authentication enabled by default.
Questions
Is Marquez free and open source?
Yes. Marquez is free, and its site says it was released and open sourced by WeWork.
Which integrations are named?
The OpenLineage community integrations include Apache Airflow, Apache Spark, Apache Flink, dbt and Dagster.
How is Marquez deployed?
Deployment guidance covers Docker and Kubernetes. The HTTP API server uses PostgreSQL to store dataset, job and run metadata.
Does Marquez support column lineage?
Yes, but column lineage support is limited to the Spark integration.
Does the API require authentication?
Not by default. Clients can send an API key with Bearer Auth when configured.
Where can users get help?
The project directs users to its Slack channel for help and feedback and encourages newcomers to join monthly community meetings.
Facts from Marquez's own pages
- Architecture
- The documented system includes a metadata repository, RESTful metadata API, and metadata UI. · marquezproject.ai, 11 Oct 2026
- Audience
- Marquez is designed for data teams managing metadata and lineage across data processing applications and pipelines. · marquezproject.ai, 11 Oct 2026
- Authentication
- Clients can send an API key using Bearer Auth when configured, while the Marquez HTTP API does not require authentication or authorization by default. · marquezproject.ai, 11 Oct 2026
- Column lineage limit
- The site says column lineage support is limited to the Spark integration. · marquezproject.ai, 11 Oct 2026
- Deployment
- The deployment guide describes Docker and Kubernetes deployments and says the HTTP API server uses PostgreSQL to store dataset, job, and run metadata. · marquezproject.ai, 11 Oct 2026
- Getting started
- The quickstart documents MacOS/Linux and Windows prerequisites and runs the Marquez HTTP server using Docker. · marquezproject.ai, 11 Oct 2026
- Integrations
- The site names Apache Airflow, Apache Spark, Apache Flink, dbt, and Dagster as integrations supported through the OpenLineage community. · marquezproject.ai, 11 Oct 2026
- Lineage API
- The Lineage API supports dependency traversal and metadata queries for tasks such as backfills and root cause analysis. · marquezproject.ai, 11 Oct 2026
- Lineage visualization
- The web UI maps dependencies across a data ecosystem and lets users inspect job inputs and outputs, dataset lineage, performance metrics, and execution details. · marquezproject.ai, 11 Oct 2026
- Metadata collection
- Its metadata server provides an OpenLineage-compatible endpoint for real-time collection from running jobs and applications. · marquezproject.ai, 11 Oct 2026
- Metadata history
- Marquez records job run history, job statistics, and immutable versioned dataset metadata. · marquezproject.ai, 11 Oct 2026
- Open source
- The site says Marquez was released and open sourced by WeWork. · marquezproject.ai, 11 Oct 2026
- Purpose
- Marquez consumes, stores, and visualizes OpenLineage metadata for use cases including data governance, data quality monitoring, and performance analytics. · marquezproject.ai, 11 Oct 2026
- Real-time collection
- Its metadata server provides an OpenLineage-compatible endpoint to collect information from running jobs and applications. · marquezproject.ai, 11 Oct 2026
- Security limitation
- The deployment documentation states that authentication and authorization are not enabled on the API by default. · marquezproject.ai, 11 Oct 2026
- Support
- The site directs users to its Slack channel for help and feedback and encourages newcomers to join monthly community meetings. · marquezproject.ai, 11 Oct 2026
- Visual lineage
- The web UI maps dependencies in a data ecosystem and lets users inspect job inputs and outputs, dataset lineage, performance metrics, and execution details. · marquezproject.ai, 11 Oct 2026
Where Marquez stands on Freedom251
- Active Metadata Management Software#5 of 25
- Data Lineage Tools#10 of 43