Freedom251 › LLM Evaluation Tools
HELM
What HELM is
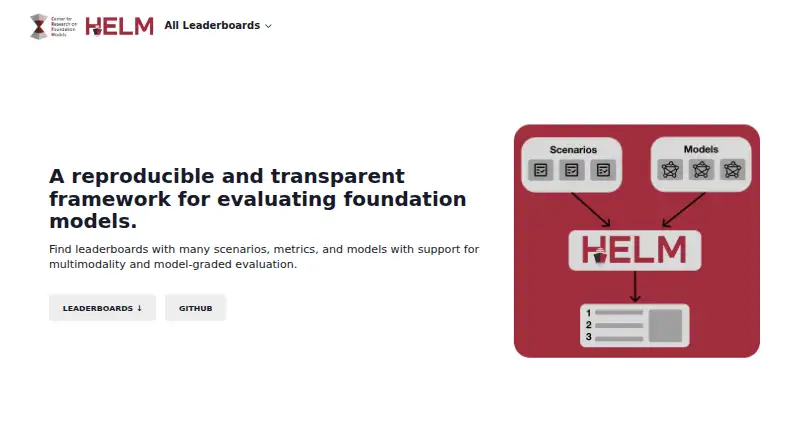
HELM is an open-source Python framework for evaluating foundation models, including large language and multimodal models. It offers standardized datasets and benchmarks such as MMLU-Pro, GPQA, IFEval, and WildBench, and a unified interface to models from providers including OpenAI, Anthropic, and Google. Users can configure private models, including local checkpoints and model servers on private networks; deployments can run inference locally or send requests to an API. Evaluation measures can cover accuracy, efficiency, bias, and toxicity. HELM includes a web interface for inspecting individual prompts and responses, plus leaderboards for comparing models and benchmarks. Official leaderboards include Capabilities, Safety, and VHELM, and the framework can reproduce published evaluation results. Users can install it from PyPI and run benchmarks, summarize results, or start a local web server. HELM is free and distributed under an Apache-2.0 license. The project entered maintenance mode on June 1, 2026; no new features or leaderboard evaluations will be added. The maintainers describe HELM as intentionally incomplete and invite community contributions.
Who it suits
HELM suits researchers and teams evaluating language or multimodal models who want standardized benchmarks, custom models, and local or API inference. It also suits users who need prompt inspection, comparison leaderboards, or reproducible evaluations.
What it does well
- Benchmarks include MMLU-Pro, GPQA, IFEval, and WildBench
- Measures efficiency, bias, and toxicity alongside accuracy
- Supports local checkpoints and private model servers
- Includes prompt inspection and comparison leaderboards
- Free and distributed under Apache-2.0
What to know first
- Entered maintenance mode on June 1, 2026
- No new features or leaderboard evaluations will be added
- External API changes may break scenarios or models
- Maintainers address GitHub questions when bandwidth allows
Limits
The free HELM plan is an open-source Python framework with no paid plans listed. Since entering maintenance mode on June 1, 2026, the project plans no new features or leaderboard evaluations; external API changes can also break scenarios and models.
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| HELM | Open-source Python framework; no paid plans listed | Free |
As crfm.stanford.edu lists them, read 8 Oct 2026. The maker's own page has the final word.
Getting started
- Visit https://crfm.stanford.edu/helm/.
- Install the package from PyPI with `pip install crfm-helm`.
- Configure the models you want to evaluate, including private models if needed.
- Run benchmarks and summarize results using the documented commands.
- Start the local web server to inspect prompts and responses.
Verdict
HELM brings standardized benchmarks, model connections, evaluation metrics, and inspection tools into a free, self-hosted Python framework. Its maintenance status and potential breakage from external API changes are relevant considerations for teams planning to use it.
Questions
How much does HELM cost?
The listed HELM plan is free. The project is open source, and no paid plans are listed.
Which models can HELM evaluate?
HELM offers a unified interface to models from providers including OpenAI, Anthropic, and Google. Users can also configure private models, including local checkpoints and private-network model servers.
Can HELM evaluate safety?
Yes. HELM has safety evaluations, measures toxicity and bias, and provides an official Safety leaderboard.
Can I inspect individual evaluation results?
Yes. Its web interface lets users inspect individual prompts and responses, and its web leaderboard compares results across models and benchmarks.
How do I install HELM?
The project instructs users to install it from PyPI with `pip install crfm-helm`.
Is HELM still receiving new features?
HELM entered maintenance mode on June 1, 2026. The project says it will add no new features or leaderboard evaluations.
Facts from HELM's own pages
- Benchmarks
- It provides datasets and benchmarks in a standardized format, including MMLU-Pro, GPQA, IFEval and WildBench. · github.com, 8 Oct 2026
- Compatibility limit
- Scenarios and models may break as external APIs change or providers deprecate models, and the maintainers recommend testing them for intended use. · crfm-helm.readthedocs.io, 8 Oct 2026
- Custom models
- Users can configure private models, including a checkpoint on local disk or a model server on a private network. · github.com, 8 Oct 2026
- Evaluation coverage
- The project says it maintains leaderboards across domains such as medicine and finance, and aspects such as multilinguality and world knowledge. · github.com, 8 Oct 2026
- Evaluation metrics
- Its metrics measure aspects beyond accuracy, including efficiency, bias and toxicity. · github.com, 8 Oct 2026
- Founded
- 2022 · crfm.stanford.edu, 28 Sept 2026
- Inference options
- Model deployments can run local inference or send requests to an API. · github.com, 8 Oct 2026
- Inspection tools
- HELM includes a web UI for inspecting individual prompts and responses and a web leaderboard for comparing results. · github.com, 8 Oct 2026
- Inspection UI
- A web UI lets users inspect individual prompts and responses. · crfm-helm.readthedocs.io, 8 Oct 2026
- Install and run
- The project documents installation from PyPI with `pip install crfm-helm` and commands to run benchmarks, summarize results, and start a local web server. · crfm-helm.readthedocs.io, 8 Oct 2026
- Installation
- The project instructs users to install HELM from PyPI with `pip install crfm-helm`. · github.com, 8 Oct 2026
- Known limitation
- The project describes HELM as intentionally incomplete and invites the community to identify gaps and contribute scenarios, metrics and models. · crfm.stanford.edu, 8 Oct 2026
- Leaderboards
- A web leaderboard compares results across models and benchmarks, with official leaderboards including Capabilities, Safety, and VHELM. · crfm-helm.readthedocs.io, 8 Oct 2026
- License
- The repository identifies HELM as open source and links to an Apache-2.0 license. · github.com, 8 Oct 2026
- Maintenance
- HELM entered maintenance mode on June 1, 2026; no new features or leaderboard evaluations will be added. · crfm-helm.readthedocs.io, 8 Oct 2026
- Maintenance status
- The repository says HELM entered maintenance mode on June 1, 2026. · github.com, 8 Oct 2026
- Metrics
- Its metrics cover aspects beyond accuracy, including efficiency, bias, and toxicity. · crfm-helm.readthedocs.io, 8 Oct 2026
- Model providers
- It offers a unified interface to models from providers including OpenAI, Anthropic and Google. · github.com, 8 Oct 2026
- Purpose
- HELM is an open-source Python framework for holistic, reproducible, and transparent evaluation of foundation models, including language and multimodal models. · crfm-helm.readthedocs.io, 8 Oct 2026
- Reproducibility
- The framework can be used to reproduce published model evaluation results. · crfm-helm.readthedocs.io, 8 Oct 2026
- Support
- Users are directed to open GitHub issues for questions, which maintainers address when bandwidth is available. · crfm-helm.readthedocs.io, 8 Oct 2026
Where HELM stands on Freedom251
- LLM Evaluation Tools#12 of 29
- AI LLM Evaluation Tools#16 of 30