Freedom251 › LLM Evaluation Tools
EvalPlus
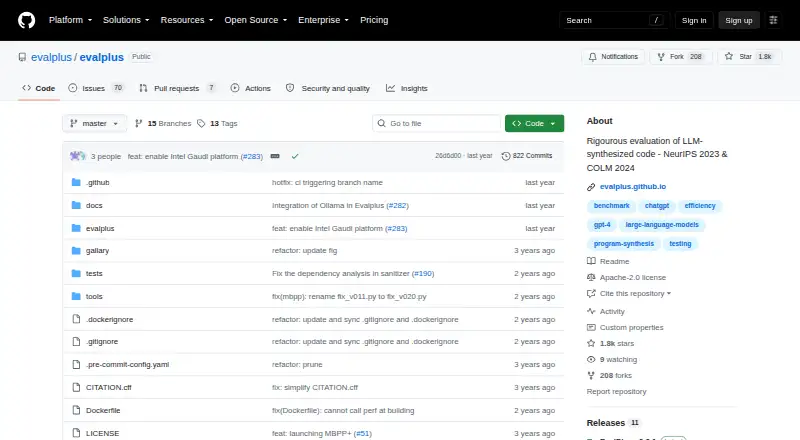
What EvalPlus is
EvalPlus is a free, open-source framework for evaluating large language models on code-related tasks. It supports HumanEval and MBPP, plus expanded benchmarks: HumanEval+ adds 80 times more tests and MBPP+ adds 35 times more tests. EvalPerf measures code efficiency with performance-exercising tasks and test inputs, while its evaluation is marked as *nix only. The project publishes leaderboards for HumanEval+, MBPP+, and EvalPerf results, and describes RepoQA as work on evaluators for long-context code understanding. Installation is documented through pip, with optional vLLM and performance extras, and Docker examples are provided for containerized evaluation described as safe code execution. Backends include Hugging Face Transformers, vLLM, OpenAI-compatible servers, OpenAI, Anthropic, Google, Amazon Bedrock, Ollama, and Intel Gaudi. It supports API, Linux, and self-hosted deployment under Apache 2.0, with evalplus/eval files also complying with MIT.
Who it suits
EvalPlus is for model teams, researchers, and developers evaluating LLM performance on programming tasks. It suits users who need benchmark suites, efficiency evaluation, Docker execution, and multiple model backends.
What it does well
- Expanded HumanEval+ and MBPP+ test suites
- EvalPerf measures code efficiency
- Leaderboards publish benchmark results
- Many documented model backends
- Docker-based evaluation examples
What to know first
- EvalPerf is marked *nix only
- Requires setup through pip or Docker
- Self-hosted deployment is required for local use
- License terms differ for evalplus/eval files
Verdict
EvalPlus provides benchmark expansion, efficiency testing, leaderboards, and broad backend support for code-focused model evaluation. Its open-source, self-hosted approach gives technical teams control over execution and setup.
Facts from EvalPlus's own pages
- Benchmarks
- The framework supports HumanEval, MBPP, and EvalPerf evaluation. · github.com, 11 Oct 2026
- Docker
- The README documents running code evaluation in Docker. · github.com, 5 Oct 2026
- Efficiency evaluation
- EvalPerf evaluates the efficiency of LLM-generated code using performance-exercising tasks and test inputs. · github.com, 11 Oct 2026
- EvalPerf leaderboard
- The EvalPlus site provides a leaderboard for EvalPerf code efficiency results. · evalplus.github.io, 5 Oct 2026
- Execution
- The README provides Docker-based examples for running code evaluation in a container. · github.com, 11 Oct 2026
- HumanEval+
- HumanEval+ expands the original HumanEval tests by 80 times. · evalplus.github.io, 11 Oct 2026
- Installation
- EvalPlus can be installed from its GitHub repository or as a stable release using pip. · github.com, 11 Oct 2026
- Intended audience
- The project is intended for evaluating LLM performance on code-related tasks. · evalplus.github.io, 5 Oct 2026
- Leaderboard
- The project links leaderboards for EvalPlus and EvalPerf benchmarks. · evalplus.github.io, 11 Oct 2026
- License
- The repository provides the software under the Apache License 2.0, with files under evalplus/eval additionally complying with the MIT License. · github.com, 11 Oct 2026
- MBPP+
- MBPP+ expands the original MBPP tests by 35 times. · evalplus.github.io, 11 Oct 2026
- Model backends
- Documented backends include Hugging Face, vLLM, OpenAI-compatible servers, OpenAI, Anthropic, Google Gemini, Amazon Bedrock, Ollama, and Intel Gaudi. · github.com, 11 Oct 2026
- Operating system limit
- The README labels EvalPerf as *nix only. · github.com, 11 Oct 2026
- Platform limit
- The README labels EvalPerf code efficiency evaluation as *nix only. · github.com, 5 Oct 2026
- Purpose
- EvalPlus is a framework for rigorously evaluating large language models on code related tasks. · github.com, 11 Oct 2026
- RepoQA
- The EvalPlus site describes RepoQA as work on evaluators for long-context code understanding. · evalplus.github.io, 11 Oct 2026
- Security
- The README describes Docker-based code execution as safe code execution. · github.com, 5 Oct 2026
- Use by model teams
- The README says EvalPlus datasets have been used by teams including Meta Llama, Allen AI TÜLU, Qwen, DeepSeek, Snowflake, StarCoder2, Magicoder, and WizardCoder. · github.com, 11 Oct 2026
Where EvalPlus stands on Freedom251
- LLM Evaluation Tools#13 of 29