Freedom251 › Text-to-speech tools
Gemini Text-to-Speech
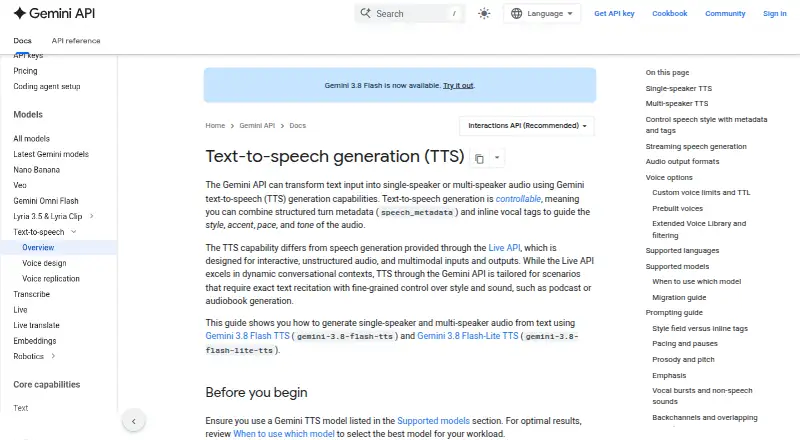
What Gemini Text-to-Speech is
Gemini Text-to-Speech converts text into single-speaker or multi-speaker audio through an API or web interface. It supports 78 languages and exports WAV or PCM audio. Structured speech metadata and inline vocal tags can guide accent, pace, tone, pauses, and vocal events. The API is intended for exact recitation and uses such as podcasts or audiobooks. Developers can choose prebuilt voices, browse an Extended Voice Library, or use designed and replicated voice IDs. Requests can stream audio; unary output defaults to WAV, while streaming defaults to raw 24 kHz mono 16-bit PCM. Python, JavaScript/TypeScript, Go, and REST usage are documented. A multi-speaker request supports up to two speakers, and input is text only with audio-only output. Commercial use is supported. Free-tier content may be used to improve Google products, while paid-tier content is marked otherwise.
Who it suits
It suits developers building speech features, including controlled narration, podcasts, and audiobooks. Commercial use, SDK documentation, and API access support product integrations.
What it does well
- Supports 78 languages
- Controls accent, pace, tone, and vocal events
- Offers streaming and WAV or PCM output
- Provides prebuilt and extended voice choices
- Supports commercial use
What to know first
- Input is text only and output is audio only
- Multi-speaker requests support up to two speakers
- Free-tier content is used to improve products
- Free-tier availability varies by plan
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| Gemini 3.1 Flash TTS Preview Standard | Output priced at $20 per 1 million audio tokens · Free tier available | $1 a month |
| Gemini 3.1 Flash TTS Preview Batch | Output priced at $10 per 1 million audio tokens · Free tier unavailable | $0.50 a month |
| Gemini 2.5 Flash Preview TTS Standard | Output priced at $10 per 1 million audio tokens · Free tier available | $0.50 a month |
| Gemini 2.5 Flash Preview TTS Batch | Output priced at $5 per 1 million audio tokens · Free tier unavailable | $0.25 a month |
| Gemini 2.5 Pro Preview TTS Standard | Output priced at $20 per 1 million audio tokens · Free tier unavailable | $1 a month |
| Gemini 2.5 Pro Preview TTS Batch | Output priced at $10 per 1 million audio tokens · Free tier unavailable | $0.50 a month |
| Gemini 3.8 Flash TTS — Batch | Paid tier per 1M tokens: $0.25 input text and $4.50 output audio through Dec 31, 2026; $0.50 input text and $9.00 output audio starting Jan 1, 2027. · Batch free tier unavailable · paid output equivalent to $0.001125 per 10s audio through Dec 31, 2026 · audio tokens correspond to 25 tokens per second | Free |
| Gemini 3.8 Flash-Lite TTS — Standard | Free tier; paid tier billed per 1M tokens: $0.50 input text and $6.00 output audio through Dec 31, 2026; $1.00 input text and $12.00 output audio starting Jan 1, 2027. · Free of charge on free tier · paid output equivalent to $0.0015 per 10s audio through Dec 31, 2026 · audio tokens correspond to 25 tokens per second | Free |
The first 8 of 14 plans, as ai.google.dev lists them, read 20 Sept 2026. The maker's own page has the final word. Every plan
Verdict
Gemini Text-to-Speech offers programmable speech generation with detailed delivery controls and several voice options. Model and processing choices affect token pricing, free-tier access, and output behavior.
Facts from Gemini Text-to-Speech's own pages
- API access
- Yes · ai.google.dev, 20 Sept 2026
- Commercial use
- Yes · ai.google.dev, 20 Sept 2026
- Custom voice limits
- Stored custom voices have a maximum of 200 per project and a one-year TTL; stateless voice keys have a seven-day TTL. · ai.google.dev, 11 Oct 2026
- Data use
- For paid services, Google says prompts and responses are not used to improve its products, while they may be logged for a limited period to detect and prevent policy violations and meet legal disclosures. · ai.google.dev, 11 Oct 2026
- Export formats
- WAV,PCM · ai.google.dev, 20 Sept 2026
- Free plan
- Yes · ai.google.dev, 20 Sept 2026
- Free-tier data use
- The pricing page marks free-tier TTS content as used to improve Google products and paid-tier content as not used for that purpose. · ai.google.dev, 11 Oct 2026
- Integrations
- The guide documents Python and JavaScript/TypeScript SDKs, Go, and REST API usage. · ai.google.dev, 11 Oct 2026
- Languages
- 78 · ai.google.dev, 20 Sept 2026
- Languages
- The models automatically detect input language; Flash TTS supports over 130 languages and Flash-Lite supports over 100. · ai.google.dev, 11 Oct 2026
- Limits
- TTS accepts text-only input and produces audio-only output; one multi-speaker request supports up to two speakers using prebuilt voices. · ai.google.dev, 11 Oct 2026
- Model choices
- Gemini 3.8 Flash TTS targets studio-grade fidelity, expressive acting, and long-form stability, while Flash-Lite targets high-throughput, low-latency, cost-efficient conversational speech. · ai.google.dev, 11 Oct 2026
- Platforms
- web,api · ai.google.dev, 20 Sept 2026
- Streaming and formats
- Requests can stream audio; unary output defaults to WAV and streaming output defaults to raw 24 kHz mono 16-bit PCM, with other listed encodings including mu-law and A-law. · ai.google.dev, 11 Oct 2026
- Style control
- Structured speech metadata and inline vocal tags can guide style, accent, pace, tone, pauses, and vocal events. · ai.google.dev, 11 Oct 2026
- Testing
- Google AI Studio is provided as a place to try Gemini TTS models before building. · ai.google.dev, 11 Oct 2026
- Use cases
- The TTS API is intended for exact text recitation with fine-grained control, including podcast or audiobook generation. · ai.google.dev, 11 Oct 2026
- Voice library
- Developers can select prebuilt voices, browse an Extended Voice Library, or use designed and replicated voice IDs. · ai.google.dev, 11 Oct 2026
- What it does
- The Gemini API converts text into single-speaker or multi-speaker audio. · ai.google.dev, 11 Oct 2026
Where Gemini Text-to-Speech stands on Freedom251
- Text-to-speech tools#33 of 232
- AI Music APIs#4 of 21
- Text-to-Speech Software#57 of 223