Freedom251 › AI LLM Evaluation Tools
DeepEval
What DeepEval is
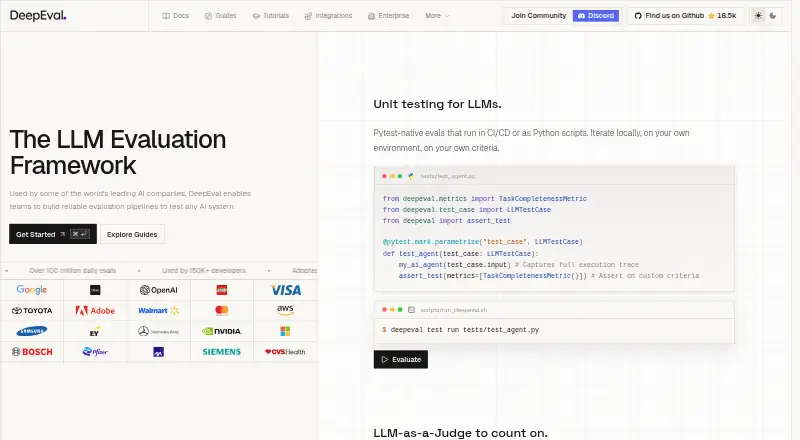
DeepEval is an open-source framework for building pipelines that evaluate AI systems. Its Pytest-native checks can run in CI/CD or as Python scripts, and it lists more than 50 metrics, including hallucination, faithfulness, relevance, summarization, toxicity, and bias. The framework evaluates text, images, and audio, including conversational and voice applications, using methods such as G-Eval, DAG, QAG, and JevEval. It can create synthetic test examples from a knowledge base and simulate conversations with user personas. For agent systems, DeepEval traces steps that can be graded and inspected in a terminal or test runner. Integrations include LangChain, Pydantic AI, OpenAI Agents, LangGraph, LlamaIndex, and CrewAI, alongside many model providers. By default, basic telemetry goes to PostHog; the maker says it excludes personally identifiable information and stored results, and users can opt out with an environment variable. The maker describes DeepEval OS as focused on pre-production testing, with results in local files and an engineer-owned test runner. Enterprise capabilities are offered through Confident AI Evals, including self-hosted or maker-cloud deployment.
Who it suits
DeepEval suits developers and teams building AI applications who need repeatable evaluations in test scripts or CI/CD. Its enterprise offering also addresses organisations seeking shared workspaces and managed evaluation workflows.
What it does well
- Pytest-native evaluations run in CI/CD
- Lists more than 50 evaluation metrics
- Evaluates text, images, and audio
- Supports synthetic test data and persona simulations
- Integrates with agent frameworks and model providers
What to know first
- DeepEval OS is limited to pre-production testing
- Default telemetry is sent to PostHog
- OS results are kept in local files
Limits
DeepEval OS is described as limited to pre-production testing, with results in local files and an engineer-owned test runner. Basic telemetry is sent to PostHog by default, though it can be disabled with DEEPEVAL_TELEMETRY_OPT_OUT=1.
Plans
| Plan | Billed and limits | Price |
|---|---|---|
| DeepEval | Open-source LLM evaluation framework · Apache 2.0 licensed · local and CI/CD test runner | Free |
| Free | Forever $0 · 2 user seats · 1 project · 5 test runs per week · 1 GB-month trace spans | Free |
| Starter | $200 / month per organization · Unlimited seats · 5 projects · 5 GB-month trace spans · $1 per additional GB-month | $200 a month |
| Team | $2,000 / month per organization · Unlimited seats · unlimited projects · 75 GB-month trace spans · $1 per additional GB-month | $2,000 a month |
| Enterprise | Custom pricing · Unlimited seats · unlimited projects · unlimited GB-month trace spans · unlimited online-evaluation metric runs | On request |
As deepeval.com lists them, read 28 Sept 2026. The maker's own page has the final word.
Getting started
- Open https://deepeval.com.
- Use the DeepEval plan, listed as free and Apache 2.0 licensed.
- Run evaluations locally as Python scripts or through Pytest in CI/CD.
- Select metrics and evaluation methods for the systems and modalities you are evaluating.
- Connect a listed agent framework or model provider if needed.
- For enterprise capabilities, book a demo for Confident AI Evals.
DeepEval is an open-source framework for testing AI systems, with particular depth for teams building LLM and agent evaluation into Python development workflows. It is strongest when engineers want broad, customizable checks in local runs and CI/CD; teams that need production monitoring and collaborative evaluation workflows should look to its separate enterprise offering or another platform.
Overview
DeepEval brings evaluation into a developer-owned test runner: checks can run as Pytest-native tests in CI/CD or as Python scripts, with results kept in local files. That approach suits pre-production quality gates and regression testing, but the maker describes DeepEval OS as limited to pre-production use. Teams that need shared workspaces, no-code evaluation, or annotation workflows will need a different layer.
Key features
The breadth of its evaluation toolkit is a clear strength. DeepEval offers more than 50 research-backed metrics, spanning hallucination, faithfulness, answer relevance, summarization, toxicity, and bias, and supports text, image, and audio evaluation, including conversational and voice use cases. G-Eval, DAG, QAG, and JevEval provide several evaluation approaches rather than locking teams into one method.
For teams without a large labeled dataset, synthetic goldens can be generated from a knowledge base, and conversations can be simulated across user personas. Agent steps can be traced and graded in the terminal and test runner, making failures easier to inspect as part of a development workflow. Integrations cover frameworks including LangChain, Pydantic AI, OpenAI Agents, LangGraph, LlamaIndex, and CrewAI, while model-provider connections include OpenAI, Anthropic, Gemini, Azure OpenAI, Ollama, Amazon Bedrock, and others.
DeepEval also supports tool-call checks, safety evaluations, regression runs, custom metrics, LLM-as-a-judge, human review workflows, prompt versioning, and CI/CD integration. Local use has a telemetry tradeoff: basic telemetry goes to PostHog by default, though it excludes personally identifiable information and stored results. Users can opt out with DEEPEVAL_TELEMETRY_OPT_OUT=1.
Pricing
DeepEval — free. The free plan is the open-source LLM evaluation framework, licensed under Apache 2.0, with a local and CI/CD test runner. It is a compelling starting point for engineers who can own their test runner and keep evaluation in pre-production. Its key limit is not a stated quota but the product boundary: DeepEval OS is described for pre-production testing, with results in local files.
For enterprise collaboration and deployment, Confident AI Evals is offered separately, with custom pricing. The enterprise offering includes shared workspaces, no-code evaluation workflows, annotation queues, and options to self-host on customer infrastructure or use the maker's cloud. Prospective customers can book a demo. Enterprise security features include SSO, role-based access control, granular permissions, audit logs, SOC 2 Type II, GDPR compliance, and custom data retention. Data sent to Confident AI is stored in databases in its private AWS cloud, except for organizations on the VIP plan.
Platforms
DeepEval supports Linux, macOS, and Windows, as well as self-hosted deployment. Its Python-script and Pytest-native workflow makes it most relevant to teams already comfortable building evaluation into code and CI/CD.
Who it's for
Choose DeepEval if you want a free, open-source way to build broad LLM and agent checks into development, especially when you need multimodal metrics, synthetic data, or trace inspection. It is less suitable as a standalone choice for teams seeking production monitoring, shared evaluation operations, or hosted collaboration in the open-source edition.
Pros and cons
- Pros: Broad coverage across 50+ metrics, three modalities, and multiple evaluation methods gives engineering teams room to test varied AI behaviors in one framework.
- Pros: Pytest-native checks, CI/CD support, and local trace inspection fit regression testing into established development workflows.
- Pros: Apache 2.0 licensing and a free plan make the framework accessible for local and self-hosted evaluation.
- Cons: The open-source edition is positioned for pre-production; local result files and an engineer-owned runner are limiting for teams that need centralized operations.
- Cons: Telemetry is on by default, so teams that require no telemetry must explicitly opt out.
Alternatives
For a broader comparison, see LLM Evaluation Tools, AI Agent Evaluation Tools, and AI LLM Evaluation Tools.
- Promptfoo is a free-plan alternative with 10k red-team probes per month, all LLM evaluation features, and local or self-hosted use; pick it if that published probe allowance and red-team focus suit your evaluation needs.
- Giskard offers a free open-source library with local deployment, a basic LLM vulnerability scan using adversarial techniques, and a basic RAG evaluation report; it fits readers prioritizing those scan and report workflows.
- Braintrust has a free Starter plan with 1 GB processed data, 10,000 scores, 14-day retention, unlimited users, projects, and datasets; choose it if those hosted usage limits and collaboration terms fit better than a local test runner.
- Confident AI has a free plan with 2 seats, 1 project, 5 test runs per week, and 1 GB-month of trace spans; it is a natural option for readers seeking a separate workspace-based offering from the same maker.
- Galileo offers a Pro plan at $100 a month, billed yearly, with 50,000 traces per month, standard RBAC, advanced analytics, and dedicated Slack support; consider it if those managed capabilities and annual billing suit your needs.
- Maxim AI has a free Developer plan with up to 3 seats, 1 workspace, 10k logs per month, 3-day retention, and email support; it suits readers whose needs fit those published caps.
- Parea AI offers a free plan for up to 2 team members, 3k logs per month with one-month retention, 10 deployed prompts, and Discord community support; choose it if that usage profile is a fit.
- Whisper is a free option for Windows, macOS, and Linux users.
Verdict
DeepEval is a strong choice for engineers who want an open-source, code-first evaluation framework with unusually broad metric, modality, and agent coverage. Its main reason to choose it is the ability to build repeatable checks into local and CI/CD workflows without a paid entry point; its main reason to look elsewhere is the pre-production boundary, which leaves teams needing centralized, collaborative or production-facing evaluation to another offering.
Verdict
DeepEval offers a broad toolkit for evaluating AI systems across modalities, metrics, and agent workflows. Its open-source edition is positioned for pre-production testing; enterprise collaboration and deployment options are described separately through Confident AI Evals.
Questions
Is DeepEval free and open source?
Yes. The DeepEval plan is listed as free and is Apache 2.0 licensed.
Which operating systems does it support?
The listed platforms are Linux, macOS, Windows, and self-hosted deployment.
What can DeepEval evaluate?
It supports text, images, and audio, including conversational and voice evaluations. Listed metrics include hallucination, faithfulness, answer relevancy, summarization, toxicity, and bias.
Does it integrate with AI frameworks and model providers?
Yes. Listed framework integrations include LangChain, OpenAI Agents, LangGraph, and CrewAI. Model integrations include OpenAI, Anthropic, Amazon Bedrock, Gemini, and other providers.
Does DeepEval send telemetry?
By default, it sends basic telemetry to PostHog. The maker says this excludes personally identifiable information and stored results; users can opt out with DEEPEVAL_TELEMETRY_OPT_OUT=1.
What enterprise options are available?
Confident AI Evals offers shared workspaces, no-code evaluation workflows, annotation queues, and listed security capabilities including SSO, role-based access control, audit logs, SOC 2 Type II, and GDPR compliance. It can be self-hosted on a customer's infrastructure or run in the maker's cloud.
Facts from DeepEval's own pages
- API and SDKs
- Confident AI exposes APIs, a TypeScript SDK and OpenTelemetry support alongside DeepEval's Python framework. · deepeval.com, 15 Oct 2026
- CLI
- The `deepeval test run` command is built on Pytest, while `evaluate()` provides a Python-programmatic interface. · deepeval.com, 15 Oct 2026
- Cloud data
- The maker says data sent to Confident AI is stored in databases in its private AWS cloud, except for organizations on the VIP plan. · deepeval.com, 28 Sept 2026
- Company relationship
- Confident AI created and maintains DeepEval and describes it as one of its open-source testing packages. · linkedin.com, 15 Oct 2026
- Company size
- LinkedIn lists Confident AI as a privately held software company with 11–50 employees and San Francisco headquarters. · linkedin.com, 15 Oct 2026
- Component evaluation
- Teams can evaluate individual spans such as tools, planners, retrievers and generators. · deepeval.com, 15 Oct 2026
- Customization
- Metrics, prompts, judge models and evaluation templates can be customized. · deepeval.com, 15 Oct 2026
- Documentation
- The documentation contains installation, quickstarts, metric references, integrations, tracing, datasets, CLI, environment-variable and troubleshooting sections. · deepeval.com, 15 Oct 2026
- Enterprise deployment
- The enterprise offering is available on Confident AI Evals and can be self-hosted on a customer's infrastructure or run in the maker's cloud. · deepeval.com, 28 Sept 2026
- Enterprise security
- The hosted enterprise offering states SOC 2 Type II, GDPR compliance, SSO, RBAC, audit logs and custom retention. · deepeval.com, 15 Oct 2026
- Evaluation methods
- Its evaluation techniques include G-Eval, DAG, QAG, and JevEval. · deepeval.com, 28 Sept 2026
- Founders
- Y Combinator identifies Jeffrey Ip and Kritin Vongthongsri as Confident AI's founders. · ycombinator.com, 15 Oct 2026
- Framework integrations
- Official integrations include LangChain, LlamaIndex, CrewAI, OpenAI Agents, LangGraph, PydanticAI, Google ADK, AgentCore, Strands and OpenTelemetry. · deepeval.com, 15 Oct 2026
- Headquarters
- San Francisco, California, United States · deepeval.com, 23 Sept 2026
- Install package
- PyPI provides a platform-independent Python wheel and source distribution for DeepEval. · pypi.org, 15 Oct 2026
- Integrations
- Listed integrations include LangChain, Pydantic AI, OpenAI Agents, LangGraph, AWS AgentCore, Strands, Google ADK, LlamaIndex, and CrewAI. · deepeval.com, 28 Sept 2026
- License
- The repository and package identify DeepEval as Apache Software License 2.0. · github.com, 15 Oct 2026
- Limit: evaluator cost
- AI Tools Atlas notes that LLM-judge metrics require provider API calls, so cost rises with dataset size and metric count. · aitoolsatlas.ai, 15 Oct 2026
- Limit: reported defect
- A GitHub issue reports the introductory tutorial failing with a `ModuleNotFoundError` when running `deepeval test run`. · github.com, 15 Oct 2026
- Limit: runtime
- AI Tools Atlas reports that large or multi-turn evaluations can be computationally slow and expensive. · aitoolsatlas.ai, 15 Oct 2026
- Limit: team features
- AI Tools Atlas says collaboration, dataset management, monitoring and dashboards require the hosted Confident AI service. · aitoolsatlas.ai, 15 Oct 2026
- Local operation
- DeepEval can run entirely locally without Confident AI or an account. · deepeval.com, 15 Oct 2026
- Local telemetry
- By default, DeepEval sends basic telemetry to PostHog, excludes personally identifiable information and stored results, and supports opting out with DEEPEVAL_TELEMETRY_OPT_OUT=1. · deepeval.com, 28 Sept 2026
- Metrics
- The project advertises more than 50 metrics spanning quality, agents, RAG, conversations, safety, voice and multimodal use cases. · deepeval.com, 15 Oct 2026
Where DeepEval stands on Freedom251
- AI LLM Evaluation Tools#1 of 30
- AI Agent Evaluation Tools#1 of 28
- Llm Developer Tools#1 of 26
- LLM Evaluation Tools#2 of 29
- Prompt Engineering Tools#2 of 25