The Tool Desk
Outbyte PC Repair FREEClear out junk files and repair common Windows errorsFree Scan →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →A voice agent listens for speech, decides when a person’s turn is over, interprets the request, and returns a spoken response. In a common cascaded design, that means VAD and turn detection, speech-to-text (STT), a large language model (LLM), and text-to-speech (TTS). WebRTC carries real-time media between the user’s device and the system; it is transport, not the component that understands or generates the answer.
How a voice agent turns speech into a response
A typical voice interaction is a loop, not simply a recording sent after the user finishes. Audio can stream while the person speaks, and downstream stages can begin work before the full turn is complete. The exact sequence depends on the architecture and how it handles turn boundaries.
As an Amazon Associate I earn from qualifying purchases.
- Capture audio: The browser or app obtains microphone audio, either through its built-in microphone support or an application-supplied media stream.
- Detect speech and turns: Voice activity detection (VAD) detects speech activity. Turn detection estimates when the user has started or finished speaking, which determines when the agent should respond.
- Recognize speech (cascaded systems): STT converts speech into text that can be passed to the dialogue system.
- Interpret and respond: The LLM uses the request and conversation context to form a response. It may also request application tools; authorization for sensitive actions belongs in trusted application logic, not in a browser connection.
- Speak the answer: TTS synthesizes the response text as audio. In a speech-to-speech system, a real-time model can instead accept audio and produce audio directly.
- Carry media and events: A transport such as WebRTC or WebSocket carries audio; the application’s client/server design determines where session events and business logic are handled.
What VAD, STT, LLM, and TTS each do
VAD and turn detection
VAD answers a narrower question than “Is the user done?” It detects speech activity. Turn detection uses that signal and other cues to decide when a person’s turn has begun or ended. A pause may mean the speaker is thinking, not that they have finished, so endpointing is part of the interaction design rather than a checkbox before the “real” AI work begins.
The OpenAI Agents SDK describes server_vad as threshold-oriented, with configurable parameters, and semantic_vad as aiming for more natural boundaries. The latter may wait longer when a speaker sounds as if they have not finished. These approaches trade faster responses against the risk of cutting someone off.
#1 Best Overall

- Omnidirectional Microphone - It is not a Speaker or Speakerphone, it is a condenser microphone. The microphone has an omnidirectional pickup pattern with a pickup distance of 11.5 ft, making it easy to capture the most subtle sounds from 360° directions and transmit the sound more loud and clear. Participants can hear each other without raising their voices.
- Made for Conferences - This microphone is perfect for small or medium meetings over an internet network by using Skype/GoToMeeting/WebEx/Hangouts/Fuze/VoIP/Zoom and other softwares. You can also use it for court reports, seminars, remote training, business negotiations, video chats, etc.
- Plug & Play, No Drivers Required - The microphone is compatible with all operating systems - both Windows and macOS. You just need to plug the microphone to start recording. If there is no response after inserting the mic, please go to the microphone setting of your computer and select the mic as the INPUT device.
- Convenient Mute Button - Quickly mute/unmute your microphone. The built-in blue indicator light for checking whether the USB microphone is working.
- Well Designed Cable - The microphone is constructed of sturdy and metal material and the base is fitted with an anti-slip mat which keeps it stable on desktop during use. It is small, convenient and does not require much space when in use. Connected with a 1.8m nylon shielded wire, it effectively eliminates signal interferences to achieve the best recording results.
STT: speech-to-text
In a cascaded pipeline, STT produces text for the next stage. That intermediate transcript can make it possible to inspect or customize recognition separately from reasoning and speech synthesis. Recognition quality, streaming behavior, and how the system treats partial transcripts all affect the experience.
LLM: dialogue and tool use
The LLM interprets the request, uses conversation context, and generates a response or a request for an application action. The model does not replace the application’s security controls: privileged operations should be authorized and executed by trusted server-side logic.
TTS: text-to-speech
In a cascaded system, TTS turns the generated response into speech. Keeping synthesis separate lets a builder choose and configure it independently from STT and the LLM. Speech-to-speech systems can generate audio without a separately managed text-to-speech stage.
Recommended Free Tools
Rank #2

- ✔Crystal Clear Sound: Conduct advanced noise-canceling technology, the Conference microphone can easily capture clear sound with a 360°sensitivity pickup range(3m/10ft), 10 times better than a traditional computer microphone. (𝐍𝐎𝐓𝐄: 𝐈𝐭'𝐬 𝐣𝐮𝐬𝐭 𝐚 𝐦𝐢𝐜𝐫𝐨𝐩𝐡𝐨𝐧𝐞, 𝐧𝐨𝐭 𝐚 𝐬𝐩𝐞𝐚𝐤𝐞𝐫)
- ✔Plug and Play: Connected to a computer through a USB cable(1.8m/6ft), no drivers to install, hassle-free installation, well compatible with Windows and macOS. (NOT compatible with Raspberry Pi/Android)
- ✔Compact and Versatile: This microphone are small and portable. You can put it in your pocket or briefcase and take it wherever you want. Perfect for meetings, interviews, podcasting, home studio recording, YouTube, Twitch, Skype, Face Time, Gaming, and more.
- ✔Convenient Mute Button - Quickly mute/unmute your microphone: the built-in Indicator LED lights tell you the working status (Green Light: Microphone has been connected; Flashing Green Light: Working Mode; RED Light: Mute Mode)
- ✔Advanced Cancellation Technology - Built-in high-performance CMTECK CCS2.0 SMART CHIP can effectively block the noise and eliminate echo, better than a traditional computer microphone
Cascaded pipeline or speech-to-speech?
These are different ways to compose a voice interaction, not a universal ranking. Microsoft’s hosted-agent guidance describes both a cascaded STT → LLM → TTS pattern and a real-time speech-to-speech pattern.
| Decision | Cascaded STT → LLM → TTS | Speech-to-speech |
|---|---|---|
| How it works | Separate speech recognition, text reasoning, and speech synthesis components. | A real-time model processes audio input and produces audio output without a separately managed STT/TTS chain. |
| Component choice | Microsoft describes flexibility to choose text models and TTS voices. | The audio interaction follows a more unified model path. |
| Conversational dynamics | The builder coordinates streaming, endpointing, playback, and interruption behavior across stages. | Microsoft positions this pattern for natural dynamics such as interruptions and backchanneling when latency is critical. |
| Visibility and control | Separate stages make intermediate text and providers available for inspection and customization; this follows from the component-separated design. | There are fewer separately managed stages, but the model handles the interaction as a more unified path. |
| Latency | Strictly serial processing can add stage waits; streaming can overlap work. Actual timing depends on the implementation. | Direct audio-to-audio interaction can avoid separate STT and TTS steps. OpenAI documents lower latency as a benefit, not a guarantee for every deployment. |
Choose the cascaded approach when separate model, language, recognition, or voice choices and access to intermediate text matter. Consider speech-to-speech when direct, low-latency conversational dynamics are a priority. In either case, the turn-taking, playback, and transport choices still shape what the user experiences.
Why WebRTC matters—and what it does not do
OpenAI describes WebRTC as “an open standard for sending low-latency audio, video, and data between browsers, mobile apps, and servers.” It gives a real-time voice agent standardized media transport rather than supplying speech recognition, dialogue reasoning, or speech synthesis itself.
Rank #3
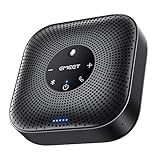
- Enhanced 360° Voice Pickup with 4 AI Mics - The EMEET OfficeCore M0 Plus Bluetooth speakerphone features a four-mic array, which enhances voice pickup from any direction. Powered by EMEET’s VoiceIA algorithm upgraded in 2023, the mic can filters out background noise and eliminates echos of the speaker.
- Crystal-Clear Audio Quality - The 3W high-quality bluetooth conference speaker can spread sound evenly throughout the room, ensuring no details are missed. With full duplex audio support, our conference speaker produces natural and rich sounds, so to feel like you are talking to others in person.
- Expandable for Larger Meetings - Room is too large? Link 2 EMEET’s Bluetooth speakerphones with the Daisy Chain, you will have 2x professional mics and speakers working seamlessly extending the conferencing space, effectively supporting up to 16 attendees. This feature supports multiple models of EMEET products, such as Meeting Capsule, M3, or M0 Plus, making it a flexible solution for setting up your conference room.
- Easy to Set Up and Use - The EMEET Conference Speaker and Microphone M0 Plus offers 2 ways to connect: USB-C & USB-C-to-A Adapter, and Bluetooth 5.0 with single-device or dual-device connection. No drivers or additional software is required, simply plug and play. The speakphone is compatible with most conferencing platforms, such as Zoom, Microsoft Teams, Slack, Webex, and etc. Connect Bluetooth-enabled phones using standard Bluetooth protocols, regardless of brand or model.
- Long Battery Life for Optimal Performance - Equipped with a large capacity battery, the M0 Plus Bluetooth conference speaker with microphone supports long-term calls over 10 hours of talk time on a single charge, making it perfect for all-day meetings. The M0 Plus Bluetooth Conference Speakerphone is optimal for use in the meeting room, home office, or on business trips, ensuring that you always have a professional meeting experience.
WebRTC addresses several difficult media-networking tasks: ICE connectivity establishment and NAT traversal, DTLS/SRTP encrypted transport, codec negotiation, RTCP quality control, and client-side features such as echo cancellation and jitter buffering. Those capabilities let teams build on interoperable media behavior instead of creating separate connectivity, encryption, codec, and adaptation mechanisms for each client.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
WebRTC can support a responsive conversation, but it cannot guarantee one. Network round-trip time, jitter, packet loss, connection setup, endpointing, model response time, and audio playback all affect perceived speed. OpenAI’s May 4, 2026 engineering article emphasizes low and stable media round-trip time, low jitter and packet loss, and fast connection setup as parts of natural interaction.
WebRTC, WebSocket, or SIP: choose by media path
The choice is mainly about who manages media and events, and how the agent connects to the user. The OpenAI Agents SDK recommends WebRTC as the browser SDK’s lowest-friction option when an app does not need to manage raw audio; its SDK can handle microphone capture, playback, and the WebRTC connection.
Rank #4
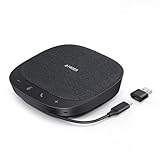
- Smart Voice Enhancement: Eliminate background noise while simultaneously enhancing voices for a professional meeting experience in any environment.
- Plug and Play: Connect via USB-C (includes standard USB adapter) and join meetings in an instant. A wired connection offers a stable and reliable USB speakerphone experience.
- 360° Voice Coverage: A USB speakerphone with 4 high-sensitivity microphones to pick up all voices within 3m in super-high clarity.
- Superior Sound: A 1.75” driver paired with 2 passive bass-radiators adds body and depth to both meeting audio and music.
- What’s In The Box: PowerConf S330 USB Speakerphone, USB-C to USB-A adapter.
- Browser speech-to-speech: Use the documented WebRTC SDK path when the application can let the SDK manage capture, playback, and the connection.
- Browser audio with server-side controls: WebRTC can carry audio while the server owns session events, tools, and business logic. Protect privileged actions with server-side authorization; browser-side peer-connection customization is not an access-control boundary.
- Server-owned audio or a custom pipeline: WebSocket suits applications that already control audio capture and playback and need direct access to events.
- Telephony: SIP and provider-specific bridges are relevant when connecting voice sessions to phone systems. Microsoft documents provider bridging, and the OpenAI SDK guidance identifies SIP and Twilio paths.
- Native mobile: A native WebRTC implementation may require the app to own transport, permissions, audio routing, and lifecycle management.
Microsoft’s hosted-agent pattern also distinguishes WebSocket signaling from the negotiated WebRTC media connection. Signaling and media are related parts of a session, but they need not use the same transport.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Barge-in: stopping the agent when the user speaks
Barge-in is the ability to interrupt an agent that is already speaking. When VAD is enabled, an incoming user utterance can interrupt ongoing output. A correct implementation must stop audio the user has not heard and keep conversation history consistent with what was actually played.
How that is handled depends on transport:
- WebRTC and SIP: The Realtime server manages an output-audio buffer and can truncate unplayed output automatically. In the Agents SDK guidance, WebRTC clears buffered output audio for the client.
- WebSocket: The client owns playback, so it must stop playback and send truncation information. The SDK guidance describes listening for a speech-start event, truncating to the portion the user heard, and emitting an interruption event.
The exact event flow varies by SDK and transport. Treat interruption handling as part of the media and conversation design, not as a universal callback.
Best Value

- Built-in AI Noise Reduction: Compared to the base model, G11 pro upgraded AI noise cancellation, effectively eliminates distractions like fan noise, keyboard clicks. It delivers clear, crisp teleconferencing experiences, making it perfect for conference calls, online learning and chatting
- Omnidirectional Conference Mic: Features omnidirectional pickup pattern with a pickup distance of 11.5 ft, making it easy to capture sounds from 360° directions. Highly sensitive pickup ensures participants hear everything clearly. Tips: This is not a speaker
- Effortless Control: Physical volume and monitoring control buttons are built into the microphone body, allowing you to effortlessly adjust both microphone and monitoring volume. Click to adjust volume between 4 levels
- Mute & Monitor: Quickly mute/unmute your microphone by one tap. Built-in 3.5mm jack allows connection of headphones for monitoring. Long press for 3 seconds to enable/disable: Blue-Mic mode, Red-Mute, Purple-Monitoring. Note: Do not connect the 3.5mm jack to external speakers, as this may cause feedback interference
- Plug & Play: Compatible with all operating systems,both Windows and macOS. No additional drivers needed . If there is no response after inserting the mic, please go to the microphone setting of your computer and select the mic as the INPUT device
How to think about voice-agent latency
There is no universal acceptable-latency threshold established by the sources cited here. The useful measure is the full interaction path: connection setup, speech detection and endpointing, recognition or audio understanding, model response, synthesis, network delivery, and playback. Streaming can overlap work in a cascaded design, but it does not make every stage instantaneous.
A 2026 arXiv tutorial, Building Enterprise Realtime Voice Agents from Scratch: A Technical Tutorial, reports 947 ms P50 time-to-first-audio and a 729 ms best case for its particular implementation using streaming STT, a vLLM-served language model, and streaming TTS. Those are study-specific measurements, not a general benchmark or a promise for other systems.
When comparing implementations, record what “first audio” means, which configuration was used, and whether the figure describes a typical result or a best case. Also evaluate turn-taking and barge-in: a fast first response that cuts off the user or continues speaking after an interruption may still feel poor.
PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minuteWhat to test before shipping
A built-in microphone is sufficient when it suits the device and test environment; an external microphone is optional, not a requirement. Test the interaction under realistic conditions rather than judging the agent from a clean, uninterrupted demo.
Quick Recap
- Try short pauses and unfinished-sounding phrases to see whether turn detection responds too early or waits too long.
- Interrupt the agent during playback and verify that it stops promptly and does not treat unplayed speech as something the user heard.
- Check response timing across the full path, including connection setup and playback—not just model generation.
- Test the intended network and device conditions, including mobile audio routing if native mobile is in scope.
- Verify that tools and sensitive actions are authorized by trusted application logic.
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

