Compare complete processors on the same real workload, software, memory configuration, power limit, and system budget. Measure useful work completed, time, energy, and cost, then account for cooling and package constraints. A 3D stack and a smaller process node are not opposing categories: stacking can put cache or other functions close to compute, while a newer process can improve the density and performance-power-area of logic that scales well. A processor may use both.
What are you actually comparing?
“3D-stacked chip” describes how dies are integrated; “smaller-node processor” describes a process technology used to manufacture some or all of the logic. Neither label alone tells you how fast a finished processor will be, how much energy it will use, or what it will cost.
A package can combine dies made on different process nodes and can pair a newer process for scalable compute with older or specialized processes for functions such as analog, SRAM, or I/O. TSMC describes its SoIC technology as integrating known-good dies with different sizes, functions, and wafer-node technologies. Intel likewise describes combining dies made with different process technologies, potentially from different foundries. In other words, a fair comparison is between processor designs and systems, not between two labels treated as mutually exclusive options.
Which design choice could matter for your workload?
Stacked cache: useful when the workload can use it
Stacked cache can benefit work that repeatedly accesses data and is limited by memory access rather than by raw compute alone. AMD positions 3D V-Cache for data-heavy engineering workloads including electronic design automation (EDA), computational fluid dynamics (CFD), and finite element analysis (FEA). That makes these applications candidates for testing; it does not establish that every engineering program, or every workload, will benefit.
#1 Best Overall

- 【Precision-Engineered for Bambu Lab 001 Model】Professionally designed to seamlessly integrate with 3D-printed Bambu Lab X1/P1 series models. Led lamp kit 001 plug-and-play kit guarantees a fit and effortless installation, delivering a clean, factory-original look. *Note: 3D-printed structural parts not included; download models for free on MakerWorld by searching "LED Light" or "MH001"
- 【Full-Range RGB & Dimming Control】Command your for bambu led lamp kit lighting with the included remote. Instantly switch between static colors or dynamic cycling modes with adjustable speed. Fine-tune the ambiance with seamless brightness control—from a soft glow to full brilliance—for the mood in scenario
- 【Premium COB LED & Aluminum Construction】Experience superior illumination powered by a high-quality 4W COB led lamp kit, ensuring vibrant, even light output. Housed in a robust aluminum alloy body for effective heat dissipation and long-term durability. Powered via a versatile 1.5-meter USB cable (5V/1A)
- 【Lamp Kit Limitless Application & Easy Power Options】Designed for ultimate versatility. Ideal for home, office, dorm, or party decor—use it as cabinet lighting, a desk lamp, or festive decoration. Easily powered by standard USB port, including phone chargers, power banks, or computers
- 【Quick-Start Guide & Safety】For optimal performance, use a 5V/1A (or higher) power adapter.led lamp kit 001 included CR2025 battery gets you started immediately. For best results, ensure the remote is within 1 meter and clear of obstructions If unresponsive, immediately reinstall or replace the battery..Store it out of children’s reach to prevent swallowing hazards
A smaller process: useful where logic scales well
A newer process may allow more logic in a given area or improve performance and power for logic that benefits from scaling. But node names are not a direct, cross-foundry measurement of transistor density or whole-processor performance. Compare the functions and processes actually used in the dies, and the resulting processor behavior, rather than ranking products by node label.
Interconnect and integration: the connection is part of the design
Stacked dies need connections whose density, bandwidth, latency, and energy use affect the system. TSMC describes short, dense die-to-die connections as enabling bandwidth and power-integrity benefits. Intel describes Foveros Direct 3D as copper-bonded stacking of chiplets onto an active base die, while EMIB is another package-interconnect approach. These are technology descriptions, not substitutes for measurements of a finished processor in your workload.
Rank #2

- Precision 3D-Printed Resin Core – Multi‑layer colored detailing accurately reproduces chip architecture
- High-Clarity Acrylic Shell – Fully transparent for unobstructed internal structure viewing
- Compact Study Size – 80×80×30 mm, ideal for desktop display and hands‑on handling
- Educational Focus – Designed for classroom instruction, university labs, science fairs, and tech exhibitions
- Steady & Lightweight – Sturdy yet portable for repeated use in teaching environments
How should you compare processors fairly?
Use the same application and representative data, and record conditions that can change results. A result is useful only if you know what was run, on which systems, and under what limits.
- Define the job. Choose the application, software version, workload settings, and dataset that reflect the work you need to complete. Identify whether it is cache-sensitive, compute-bound, bandwidth-bound, latency-sensitive, or mixed.
- Match the system conditions. Keep memory capacity and configuration, operating conditions, software, compiler and settings consistent where possible. Set a stated power limit and use cooling appropriate to each processor; record any differences that cannot be matched.
- Measure useful output and elapsed time. Record completed tasks, throughput, or time to finish—not just peak specifications or a vendor-selected score. Run repeatable workloads and note the benchmark configuration.
- Measure energy as well as performance. Record wall power and energy per completed task at a stated performance level. A processor that finishes sooner may use either more or less total energy, so speed alone does not answer the efficiency question.
- Compare the whole purchase and deployment. Include processor and system price, availability, package and platform compatibility, cooling needs, and any limits on power or thermals. A chip-level performance gain may not make the system a better fit for a fixed budget or operating environment.
| Comparison axis | What to record | Why it matters |
|---|---|---|
| Workload behavior | Application, version, representative dataset, and whether the task is cache-sensitive, compute-bound, bandwidth-bound, latency-sensitive, or mixed | Extra cache helps only when the workload can use it; other bottlenecks may dominate. |
| Performance | Throughput or completion time under matched software and settings | Peak specifications and selected vendor workloads do not predict every user’s result. |
| Energy | Wall power and energy per completed task at the measured performance level | Faster completion does not, by itself, establish lower energy use. |
| Process allocation | Which functions or dies use which process, where that information is available | A heterogeneous package can combine newer logic with older or specialized dies. |
| Interconnect | Die-to-die bandwidth, latency, energy per bit, density, and topology, when published | Stacked, side-by-side, and package-level links have different physical and system behavior. |
| Package, thermals, and cost | Cooling, power and package limits, system price, availability, and manufacturing or test considerations | A processor advantage may not translate into a system or budget advantage. |
What do published examples show—and what do they not show?
AMD’s 2024 3D V-Cache materials give concrete examples of cache capacity and application results. They are vendor-reported product and workload figures, not independent tests that isolate the effect of stacking from process node, processor generation, core count, or other design differences.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Rank #3

- [Canton Tower DIY Kit] This is a DIY electronic kit for making a light house. The kit contains 155 LEDs. After installed, the lighthouse is about 0.38m high and can display gorgeous dynamic effects. It is a DIY electronic kit very suitable for training hands-on ability. It is also a very novel gift completely made by hand.
- [To Be soldered By Users] It requires users to solder 155 LEDs. Users need to be skilled in soldering. Of course, we also provide standby LED lamps. Its mainboard is soldered and tested and users only need to solder the leds together. For LED soldering, we have provided auxiliary molds, printed installation tutorials and video guide.
- [Hardware Structure] It uses 3mm colorful flashing LEDs. There are 12 LEDs in each loop and more than 12 loops of LEDs from top to bottom. It uses an STC high-speed SCM (single chip microcomputer).
- [Features] The mainboard is 6x6cm in size. There are 3 keys provided on the mainboard to adjust the dynamic effects. There is a microphone on the mainboard to collect sound. Users can switch the audio dynamic mode by pressing the keys. The current dynamic effect will jump up and down with the music.
- [Professional services] iCubeSmart have various electronic DIY products. If you receive the product and do not know how to make it, or the component is broken during production or if you need help to modify the animation, you can leave us a message. We offer life-long technical support services for our DIY products. If you need other products, please search for the brand name: icubesmart.
| AMD-reported example | What the figure describes | How to interpret it |
|---|---|---|
| 96 MB L3 cache per CCD versus 32 MB on general-purpose EPYC | AMD’s 2024 product architecture figures for EPYC with 3D V-Cache versus general-purpose EPYC | These are cache-capacity figures, not a measured application-speed ratio. |
| Up to 1,152 MB total L3 | AMD’s 2024 statement about 4th Gen EPYC processors with 3D V-Cache | This is a product-family maximum, not a capacity claim for every EPYC processor. |
| Approximately 1.28× | AMD-reported Synopsys VCS performance for 32-core EPYC 9384X versus 32-core EPYC 7573X | The processors are from different generations. This comparison does not isolate cache stacking; the benchmark and configuration are part of AMD’s source material. |
| Approximately 1.55× | AMD-reported Synopsys VCS performance for 96-core EPYC 9684X versus 64-core EPYC 7773X | Core counts and generations differ, so the figure is not an isolated stacking comparison. |
| About 2.1× faster time-to-market | AMD’s ANSYS Fluent comparison of EPYC 9684X with Intel Xeon 8480+ | This is a vendor-reported, application-specific comparison, not a general result for CFD or a controlled measure of stacking alone. |
For its stated comparisons, AMD’s source is its 2024 material on How does AMD 3D V-Cache™ technology work? The named models and workloads make the examples more informative than an unqualified speed claim, but they do not supply a neutral, fully matched test of stacking versus process scaling.
Packaging figures illustrate integration, not processor performance. TSMC’s undated SoIC technology page, accessed October 4, 2026, says its sub-10 µm bond-pitch rule and 3 nm SoIC stacking were entering volume production in 2025. Intel Foundry’s undated article on cutting-edge process technologies for data centers, accessed October 4, 2026, gives a 9 µm copper-bonding pitch for first-generation Foveros Direct 3D and a stated 3 µm target for a second generation. Intel’s packaging page also describes its Data Center GPU Max Series as containing more than 100 billion transistors, 47 active tiles, and five process nodes. Those figures show the range and complexity of integration; they do not rank CPU performance or establish which processor is faster for a particular user.
Rank #4
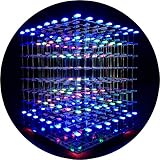
- [LED CUBE KIT] This is a DIY welding package for 3D cube light, a 3D matrix made up of 512 red, green and blue square LED lamps, which can display a lot of colorful dynamic lighting shapes. It is suitable for students' manual electronic manufacturing courses and welding exercises. Meanwhile, it is also a pretty innovative and meaningful small gift. The size of the finished product after welding of this package is about 7.08*7.28*7.88inch, and the distance between the lamps is 0.9inch.
- [SOLDERING KIT] The PCB main board in this package has been well soldered and tested, and users need to solder the LED lamp themselves, users are required to have a simple electronic technology foundation and soldering ability, so it is not suitable for children under 12+ years old. There are 64 square holes on the main board to fix the LED and make welding easier. We provide paper welding instructions. Users can also download installation instructions on Google network disk.
- [EFFECTS CAN MODIFIED] More than 20 kinds of brilliant animation effects have been built into the main board of this cube. Users can display the animation after welding and plugging in the USB power supply. Users can also modify the animation displayed through the 3D software provided by us. Our 3D software can directly generate a HEX burning file, and then download the HEX file to the light cube to run.
- [MAIN BOARD FUNCTION] The size of the main board PCB is 18*18.5cm; the main board is powered by TYPE-C 5V USB; there are 8 keys on the main board to switch animation modes.
- [AUDIO SPECTRUM MODE]There is a microphone on the motherboard to sense sound, and the audio spectrum mode can be switched by a switch on the motherboard.
How do packaging, yield, and cost affect the decision?
More dies and denser connections can change package design, assembly, and testing. Intel describes wafer sort, die sort, burn-in, and final or system-level testing as parts of its manufacturing flow. It also explains that smaller chiplets can be easier to yield than a very large die. That is not proof that a stacked processor will have lower cost: die partitioning, known-good-die screening, package assembly, and the complete manufacturing flow determine the outcome.
Likewise, vendor descriptions of bandwidth, power integrity, or integration benefits do not establish a lower total system cost or a better result under your cooling and power limits. The available vendor examples do not provide a neutral total-cost comparison across 3D-stacked and smaller-node processors.
Best Value

- Model: 23HS8430
- High torque: 270oz-in 180N.cm holding torque
- Size: 57x57x56mm (2.24"x2.24"x2.20")
- Advantage: Made of high-quality motor steel, tough and durable. The side wall has a frosted texture to increase friction.
- Application: 1:Semiconductor Equipment;Application 2:Milling Machine, Engraver Machine ; Application 3:CNC Routers4.3D printers
What evidence would make a comparison convincing?
A strong comparison would test processors on the same workload, software version, memory setup, power limit, and system budget, while reporting performance, energy, and price. To attribute a result specifically to 3D stacking rather than to a newer generation, different core count, process node, or other design change, the comparison would also need to control for those factors. The vendor workload figures above do not do that, and no independent test holding all those conditions constant while isolating stacking from process scaling is established here.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




