Do these 3 things before closing this tab:
1Scan for outdated or missing drivers - takes under a minute2Clear out junk files and repair common Windows errors3Fix the driver behind crashes, sound loss and screen glitchesWARC (Web ARChive) is the ISO 28500 container used to preserve web captures. It combines the bytes retrieved from protocols such as HTTP, DNS, and FTP with request data, timestamps, identifiers, crawl notes, duplicate events, and other preservation metadata. A WARC file is not a browser or replay program: it is an ordered sequence of typed records that another index and replay system can interpret.
What the WARC format is
ISO 28500:2017 is the current confirmed second edition of the WARC standard. ISO published that edition in August 2017 and confirmed it in 2023. The specification defines a container for payload content and the control information needed to preserve and exchange web-capture events.


The payload can be an HTML document, image, stylesheet, JavaScript file, PDF, audio or video object, redirect response, DNS result, or other bytes. WARC does not require one media type. It records what was captured and the context in which it was captured.
The format also provides places for linked metadata, protocol request headers, compression and record-integrity information, duplicate-detection events, later transformations, extensions, and optional segmentation when a logical record is too large to store as one piece.
Recommended Free Tools
#1 Best Overall

- Used Book in Good Condition
How a WARC file is laid out
A WARC file is a concatenation of records. Each record has a version line, line-oriented named headers, a blank line, an arbitrary content block, and record-ending newlines. A simplified record looks like this:
WARC/1.0
WARC-Type: response
WARC-Date: 2026-09-29T12:00:00Z
WARC-Record-ID: <urn:uuid:...>
WARC-Target-URI: https://example.com/
Content-Type: application/http; msgtype=response
Content-Length: 1234

HTTP/1.1 200 OK
Content-Type: text/html

<html>...captured bytes...</html>
The exact mandatory, recommended, and version-specific fields are defined by the applicable WARC 1.0 or 1.1 rules. Do not assume that every producer emits the same optional headers. In practice, record identifiers and relationship fields are essential when a replay system must connect a request, response, metadata item, revisit, or continuation.
Important fields
- WARC-Type identifies the record role.
- WARC-Record-ID gives the record a globally unique identifier.
- WARC-Target-URI identifies the requested resource when the record has a target.
- WARC-Date is a UTC ISO 8601/W3C-style timestamp.
- Content-Length states the byte length of the content block.
- Relationship headers connect records, such as a revisit to the earlier capture it reuses or a continuation to the segment before it.
Records from one capture event normally share the same WARC-Date even if the crawler writes them to disk at slightly different moments. That timestamp describes the capture event, not necessarily the instant the file writer flushed each record.
The eight common WARC record types
| Type | Purpose |
|---|---|
warcinfo |
File- or crawl-level context, such as software, operator, and collection information. |
response |
A protocol response and its captured payload, commonly an HTTP response. |
request |
The request message associated with a retrieval. |
resource |
A captured resource that is not represented as a response record. |
metadata |
Descriptive or technical metadata linked to another record. |
revisit |
A compact event stating that content duplicates, or is unchanged from, an earlier capture. |
conversion |
The result of a later transformation of archived content. |
continuation |
A segment used when one logical record is split across multiple records. |
A file commonly starts with a warcinfo record and then contains retrieval records and related metadata, but the standard does not make that visual order a substitute for following identifiers and indexes.
WARC-Date, payloads, and preservation metadata
WARC separates the captured bytes from the facts needed to interpret them. An HTTP response record can preserve status and headers together with the response body; a separate request record can preserve the request that produced it; a metadata record can describe the crawl or add technical information without changing the original payload.
This separation matters for preservation. A crawler can retain redirects, request headers, DNS evidence, non-HTTP resources, and later conversion results while keeping relationships explicit. Duplicate captures can be represented with a small revisit record instead of storing another full response, provided the relationship to the earlier record is preserved.
Rank #2
WARC versus ARC
ARC_IA is the Internet Archive’s earlier aggregate format, used since 1996. WARC is a revision and generalization of that model, designed for broader memory-institution use and standardized as ISO 28500.
| Comparison point | ARC_IA | WARC |
|---|---|---|
| Standards position | Legacy Internet Archive crawl format. | ISO 28500:2017, second edition confirmed in 2023. |
| Basic model | Sequences of captured web-content blocks. | Concatenated typed records with named headers and arbitrary content blocks. |
| Requests and control data | More limited legacy model. | Explicit request capture and richer protocol-control information. |
| Metadata and relationships | Less expressive. | Linked metadata, identifiers, duplicate/revisit events, transformations, and extensions. |
| Large records | Legacy handling. | Optional continuation and segmentation records. |
| Migration | Still encountered in historical collections. | Intentionally distinguishable so software can read legacy ARC while collections migrate. |
ARC and WARC are containers, not viewers. Choosing WARC is primarily a preservation and interchange decision; it does not by itself make a captured site replayable.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Compression, indexing, and random access
Libraries and archives commonly store WARC preservation files with record-at-a-time GZIP compression. A filename ending in .warc.gz normally means “a gzip-compressed WARC,” not a separate archival format. Compressing members at record boundaries allows an index to locate and decompress individual records without expanding the entire crawl.
The WARC container does not define your archive’s complete search index. Archives often maintain a CDX-style or successor index that maps a URL and capture time to a compressed record offset. The index layer, replay service, and any URL-rewriting rules belong to the archive system.
How to inspect or open a .warc file
Opening a WARC means either inspecting its bytes or replaying its captures. Use inspection when you need headers, timestamps, record types, or payloads; use a replay application when you need a browser-like view with embedded resources and redirects resolved.
Inspect an uncompressed file
- Confirm the first line:
head -n 1 capture.warcshould show a WARC version line. - Find record boundaries and types:
grep -n '^WARC-Type:' capture.warc. - Read the beginning of a file safely:
sed -n '1,80p' capture.warc. - Check a target URL or date:
grep -n -E '^(WARC-Target-URI|WARC-Date):' capture.warc.
Inspect a .warc.gz file
- Stream decompression without creating a second copy:
gzip -dc capture.warc.gz | head -n 80. - List record types:
gzip -dc capture.warc.gz | grep '^WARC-Type:'. - Search for a host or path:
gzip -dc capture.warc.gz | grep -n 'WARC-Target-URI: https://example.com'.
These text commands are useful for a quick check, but they do not understand compressed-member indexes, continuation relationships, HTTP message framing, or replay rewriting. For a collection you intend to serve, use a WARC-aware indexer and replay system and preserve the original files unchanged.
Rank #3
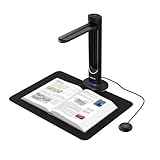
- [48MP Ultra-High Resolution] The K48 is a professional-grade book scanner equipped with a true 48MP Sony CMOS sensor, capable of capturing exceptional detail at 600 DPI — even on A3-sized materials. Used for digitizing books, magazines, documents, and archival materials with stunning clarity.
- [AI-Assisted Page Smoothing] Curved book pages are automatically flattened using intelligent software technology. This causes the removal of finger shadows, background interference, and page curvature — delivering flat, clean scans without any manual post-processing. Double pages are split automatically.
- [Laser Positioning & Auto-Scan] The built-in laser positioning system ensures precise alignment every time. Page turning detection causes the scanner to start capturing automatically as soon as a page is turned — ideal for high-volume digitization where speed matters.
- [Multi-Format OCR & Text-to-Speech] Used for creating searchable PDFs, editable Word/Excel files, or MP3 audio for voice playback. The K48 is capable of recognizing text in multiple languages and converting documents into accessible formats — perfect for education, accessibility compliance, and digital archives.
- [4K Live View & USB 3.0] Stream 4K@30fps video for live presentations, online classes, or real-time document review. USB 3.0 Type-C ensures fast data transfer and stable connection. Used for immediate setup in classrooms, offices, and libraries — plug and play, no drivers needed.
What “open” does not guarantee
- A WARC may contain only the top-level HTML response and omit images, scripts, fonts, or API calls.
- Modern JavaScript may depend on services that were not captured or cannot be reproduced offline.
- External content can disappear or change independently of the archived bytes.
- A redirect chain may be present as several records; a basic text viewer will not follow it.
- A truncated, segmented, or transformed capture requires relationship-aware software to reconstruct the intended result.
Creating a useful WARC capture
A preservation workflow should record more than a screenshot. Capture the target response, associated requests when policy permits, redirects, relevant non-HTTP data, crawl software and operator context in warcinfo, and stable identifiers linking related records. Record the UTC capture date and retain the original compressed members. If your crawler deduplicates content, keep the revisit relationship rather than silently discarding the event.
Before accepting a file, validate that content lengths match, record terminators are present, identifiers are unique, and continuation chains are complete. Keep a separate index so a URL and capture time can be located without scanning every byte of every WARC.
Independent reader supportYour contribution helps us test, update, and keep practical guides available for everyone.Reliability and troubleshooting
“The file is unreadable”
First determine whether it is compressed. Run file capture.warc*; use gzip -t capture.warc.gz to test gzip integrity. A failed test indicates transfer or storage corruption, not an ARC-versus-WARC difference. Restore the file from a verified copy and compare checksums.
“My editor shows binary garbage”
That is expected for .warc.gz. Decompress a stream with gzip -dc or use a WARC-aware tool. Do not save an editor’s altered output over the preservation master.
Crashes, No Sound, or Screen Glitches?
Random freezes, missing sound and display glitches usually trace back to one bad driver. Find and replace yours safely.Free scan · under a minutePC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11“The page is blank in replay”
Check the index entry, response status, redirect records, and whether embedded resources were captured. A valid WARC can still replay poorly when the crawl omitted dependencies or when the original site required live scripts and third-party services.
“The content length does not match”
Remember that WARC Content-Length measures the record’s content block, not the whole file and not necessarily the HTTP body alone. Parse the headers and blank-line boundary before judging the value. For segmented records, validate each continuation and the complete logical chain.
“I need one file per web page”
That is a packaging preference, not a WARC requirement. One WARC can contain many records from many URLs. Use the archive index to address individual captures while retaining the efficient aggregate file.
WARC is not a screenshot format
A screenshot is a visual output; WARC preserves protocol exchanges and their context. If you need a clean visual reference alongside an archival capture, ScreenshotNeo can return a PNG, JPEG, WebP, or PDF from one API request. It removes cookie-consent banners, newsletter popups, and chat widgets before capture, while WARC remains the format for preserving crawl records.
Or skip the browser setup
Use ScreenshotNeo’s API documentation at https://screenshotneo.com/docs/ for the available options. The following call captures a clean image without configuring a local browser:
curl -G "https://api.screenshotneo.com/v1/shot" -d access_key=YOUR_API_KEY --data-urlencode url=https://stripe.com -o shot.webp
import requests
r = requests.get("https://api.screenshotneo.com/v1/shot", params={"access_key": "YOUR_API_KEY", "url": "https://stripe.com"}, timeout=90)
open("shot.webp", "wb").write(r.content)
const q = new URLSearchParams({ access_key: 'YOUR_API_KEY', url: 'https://stripe.com' });
const res = await fetch(`https://api.screenshotneo.com/v1/shot?${q}`);
Bot checks or CAPTCHAs, blank pages, timeouts, failed loads, and cache hits are not billed, and response headers identify the page verdict and billing result. Its MCP server provides take_screenshot, get_page_info, and capture_pdf tools for Claude, Cursor, and other MCP clients. The Free plan includes 1,000 shots each month with no card; paid plans start at $5 for 3,000 shots, with every feature available on every plan.
Sign up for ScreenshotNeo’s free 1,000-shot plan to create visual references without a card.
When WARC is the right choice
- Choose WARC when you need a standards-based preservation or interchange container.
- Use its request, response, metadata, revisit, conversion, and continuation records when provenance and relationships matter.
- Plan an index and replay layer separately; WARC alone is not a viewer.
- Retain compressed masters and validate integrity before moving files between systems.
- Use ARC readers for legacy collections, but prefer WARC for new archives that need ISO 28500 features.
Frequently Asked Questions
Is WARC an ISO standard?
Yes. ISO 28500:2017 is the second edition of the WARC specification; it was published in 2017 and confirmed in 2023.
Does a .warc.gz file use a different format from WARC?
Usually no. The suffix normally indicates a WARC stored with gzip compression, commonly compressed at record boundaries.
Can I view a WARC directly in a web browser?
Not reliably. A browser needs replay software and an index that understand WARC records, HTTP semantics, redirects, embedded resources, and capture-specific rewriting.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.




