PC Slower Than It Used to Be?
A free scan shows the junk files, broken settings and background clutter dragging Windows down - then fixes them in one click.Free scan · Windows 10 & 11Outdated Drivers Are Slowing You Down
One free scan finds every outdated or missing driver and matches the right update for your exact hardware.Free scan · exact hardware matchDesigning an IoT platform for 99.999% availability starts by defining which customer-visible operation must succeed—not by choosing a multi-region deployment. Set a measurable service-level objective (SLO) for the full device-to-service path, translate it into a small failure budget, then engineer and test the dependencies that can consume that budget.
What five nines means for an IoT service
Availability is not a single universal measurement. It can describe the share of time a service is usable or the share of eligible requests it serves successfully. Google Cloud defines availability as “the percentage of time that an application is usable” in its infrastructure reliability guide; request-based measurement can reveal failures that a broad uptime signal misses.

As an Amazon Associate I earn from qualifying purchases.
For an IoT product, decide what “usable” means to the device operator or customer. A reachable endpoint is not enough if devices cannot authenticate, telemetry is rejected, processing stalls, or stored data is stale or incorrect. Choose a transaction that represents the service’s promise and specify how partial failures count.
Write the SLO around an observable transaction
An example design objective is: an authenticated device can publish an eligible telemetry message and receive the required acknowledgment within a stated latency limit. For a monitoring product, a separate objective might cover whether an operator can retrieve sufficiently fresh device state. These are examples to adapt, not vendor commitments.
#1 Best Overall

- Dual-Core Performance Up to 240 MHz: Run sensor processing, wireless communication, automation logic and connected-device tasks on a 32-bit dual-core ESP32 platform designed for responsive embedded and IoT projects
- Built-in Wi-Fi and Bluetooth 4.2: Connect to 2.4 GHz Wi-Fi networks or use Bluetooth Classic and BLE for wireless sensors, smart devices, remote controls, home automation and other connected projects
- Flexible Power-Saving Modes: ESP32 power-management features support dynamic clock scaling and low-power operating modes, helping developers reduce energy use in compatible sensing, monitoring and connected-device applications, suitable for battery-powered Internet of Things (IoT) devices.
- USB-C Programming with CP2102: Connect through USB-C for power, sketch uploads and serial monitoring, while GPIO, UART, SPI and I2C interfaces support sensors, displays, motor drivers and other modules (USB-C cable not included)
- Over-the-Air Update Support: Configure OTA functionality through a compatible ESP-32 software framework to update deployed firmware over Wi-Fi without reconnecting the board by USB for every revision
Document the eligible operations, success criteria, latency boundary, measurement window, and treatment of partial service. State whether a successful publish acknowledgment alone counts, or whether the message must also be validated, processed, and made available to the intended consumer. Specify exclusions narrowly; an undefined exclusion can make a headline target impossible to interpret.
Keep the SLO distinct from a service-level agreement (SLA). An SLO is an internal, measurable reliability objective; an SLA is a formal commitment to customers and may carry financial or legal remedies. Microsoft’s guidance on reliability targets treats success rate, latency, capacity, availability, and throughput as common SLO measures. A provider SLA only covers the named service and conditions in its current terms; it does not establish the availability of your complete application.
Translate the percentage into time
For time-based availability, 99.999% means that the unavailable share is 0.001%. Google Cloud’s current infrastructure guide gives 99.999% as a multi-region infrastructure target, corresponding to about 26 seconds of downtime in a 30-day month. The same guide presents lower location-level targets and warns that targets are not universal guarantees: an individual service’s SLA can vary with the product and configuration. Use these figures to understand the scale of the budget, not as a forecast or promise for an IoT workload.
For an annual window, the arithmetic equivalent of a 0.001% unavailable share is about 5.26 minutes in a 365-day year. That is a calculated budget, not a source-published IoT result. Request-based objectives have a different budget: their failed-request allowance depends on the number and distribution of eligible requests. Write down the actual window and denominator rather than converting between time and request ratios as if they were interchangeable.
Rank #2

- Certified & Future-Ready: Espressif-certified ESP32-WROOM-32E ensures full hardware compatibility and lifetime firmware support. Upgraded 8MB Flash handles IoT data and OTA updates.
- Dual-Core Speed: 240MHz dual-core processor runs Wi-Fi/BLE and sensors 2x faster. 38 GPIO pins (10 RTC) support SPI/I2C/UART for LCDs, motors, and industrial sensors.
- Plug & Play Dev: USB-C driver pre-installed: upload code instantly on Windows/Mac/Linux. Works with Arduino IDE, MicroPython, and Espressif IDF.
- All-Environment Ready: Run Wi-Fi smart switches (Home Assistant) and BLE tracking on one board. Industrial-grade stability (-40°C~85°C) for outdoor/automated systems.
- Advantages: The ESP32 development board offers high performance, low power consumption, and rich wireless connectivity, making it suitable for developers of all levels, especially beginners.
Choose the availability measure and deployment scope
Use the customer journey to decide what to measure. Time-based uptime is useful when the service must remain continuously usable; request success rate is useful when discrete operations can be counted. A request metric may expose failures hidden by an “up” status page, while a time metric may better express a sustained outage affecting every device. For either method, also track latency, capacity or throttling, throughput, data correctness, and pipeline freshness where they matter to the promise.
| Deployment or example | Published availability figure | How to interpret it |
|---|---|---|
| Single zone | 99.9%; about 43.2 minutes in a 30-day month | Google Cloud infrastructure guide target; not an end-to-end IoT result. |
| Multiple zones in one region | 99.99%; about 4.3 minutes in a 30-day month | Google Cloud infrastructure guide target; requires the workload and dependencies to tolerate a zone failure. |
| Multiple regions | 99.999%; about 26 seconds in a 30-day month | Google Cloud infrastructure guide target, not a guarantee for all services or application designs. |
| Bigtable example: three or more regions with multi-cluster routing | 99.999% minimum uptime SLA | Product- and configuration-specific statement in the guide; verify current service terms before relying on it. |
| Bigtable example: single-cluster routing | 99.9% minimum uptime SLA, regardless of cluster count or distribution | Shows why a regional footprint alone does not determine the covered SLA; verify current terms. |
All figures in the table are from Google Cloud’s building blocks of reliability guidance. The infrastructure figures are location-level targets; the Bigtable figures are stated for the specified product configurations. Neither establishes what an independently designed, end-to-end IoT service will achieve.
Redundancy improves resilience only when the relevant failure domains are independent and the system can actually route, authenticate, process, and serve data after a failure. Replication, DNS or routing, identity services, dependencies, and operator procedures can share a common failure cause. Do not estimate end-to-end availability by multiplying component percentages unless the independence and measurement assumptions behind that calculation are justified.
What’s actually slowing this PC down?
Pick the symptom - the matching free tool is one click away.
Map the complete device-to-customer path
Build a dependency map for each important transaction, from the device to the result the customer expects. A practical checklist includes:
Rank #3
- Device power, firmware, local network, carrier or other connectivity, and any edge gateway.
- DNS, routing, load balancing, TLS termination, authentication, authorization, and credential services.
- The ingestion endpoint or broker, message queues, stream processing, rules, and downstream integrations.
- Telemetry and device-state storage, APIs, dashboards, and the control plane used to manage devices.
- External services and human-operated processes needed for provisioning, incident response, and recovery.
For every dependency, record its failure modes, owner, health signals, capacity limits, recovery procedure, and whether it is shared across otherwise redundant paths. Identify the portion of the customer transaction each dependency can break. This turns a high-level diagram into a reliability model that can guide investment and testing.
Select an ingestion design that matches device behavior
Do not select a protocol or broker from its label alone. Compare what the devices need against what the endpoint actually implements, then account for the operator’s responsibility for maintaining it.
| Choice | Best fit to investigate | Trade-off to resolve |
|---|---|---|
| MQTT-to-messaging connector or full MQTT broker | Required MQTT version and features, QoS, persistent sessions, shared subscriptions, and device-to-platform messaging patterns. | A connector can reduce operational effort but may omit parts of MQTT; a full broker can support broader protocol behavior and brings added management and cost. |
| MQTT, HTTPS, or CoAP endpoint | Device constraints, network overhead, footprint, client support, and existing operational tooling. | HTTPS is broadly supported but has higher overhead than MQTT; CoAP is designed for constrained devices and small-footprint sensors. |
| Managed IoT platform or standalone broker | Whether the service needs integrated identity, device state, configuration or OTA management, rules, processing, and visualization. | A platform may package lifecycle capabilities; with a standalone broker, the operator must supply and own the missing functions. |
Google Cloud’s IoT platform architecture guidance distinguishes connector-based approaches from full brokers and emphasizes understanding a product’s chosen approach. Confirm behavior against the implementation and device use case rather than assuming that “MQTT compatible” means every MQTT feature is available. The MQTT standard overview describes QoS levels and persistent sessions; selecting a protocol QoS does not by itself guarantee exactly-once business processing across the entire application.
For each candidate, assess message ordering needs, duplicate handling, offline duration, reconnect behavior, and the system’s response to backpressure. If devices buffer locally, specify the buffer limit, retention period, replay order, and what happens when storage fills. Use retry limits and jitter so that recovery does not turn a connectivity outage into a synchronized reconnect surge.
Rank #4

- 2.4GHz Dual Mode WiFi + Bluetooth Development Board
- Support LWIP protocol, Freertos
- SupportThree Modes: AP, STA, and AP+STA
- Ultra-Low power consumption, Compatible with Arduino IDE
- ESP32 is a safe, reliable, and scalable to a variety of applications
Make redundancy real across zones and regions
Choose the failure scope your product must survive: an instance, zone, region, or a broader dependency failure. Multi-zone or multi-region designs add routing, replication, consistency, and operational complexity. They help only if the surviving path has adequate capacity and can access the credentials, state, software, and data needed to continue the measured transaction.
For each failure scope, decide where writes are accepted, how device traffic is steered, how state is replicated, and how conflicting or delayed updates are resolved. Define recovery time and recovery point objectives in customer terms: how quickly the service must resume and how much telemetry or state loss is acceptable. Where a device may reconnect to a different region, test whether identity, authorization, and device configuration remain usable there.
Provider availability statements must be read at their exact scope. Google Cloud notes that component SLAs and configuration affect aggregate reliability, and its examples show that routing mode can matter as much as cluster geography. Review the current SLA for each named service and its prerequisites before including it in a reliability model; do not substitute the provider’s target for your own end-to-end measurement.
The Tool Desk
Outbyte PC Repair FREERepair Windows errors before they cause bigger problemsFix Now →Outbyte Driver Updater FREEScan for outdated or missing drivers - takes under a minuteDriver Scan →Include fleet security and lifecycle operations
Availability depends on the fleet being able to establish trusted connections and recover safely. Assign clear ownership for:
Best Value
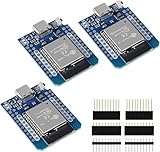
- D1 Mini NodeMCU Type-C ESP32 WLAN WiFi Bluetooth IoT Development Board 5V Compatible for Arduino
- Designed with ultra-low power technology, it offers the full range of performance and features of the ESP32 chip. The pin arrangement provides compatibility with the modules developed for the D1 Mini ESP8266 while also offering fast WLAN, enhanced GPIO, Bluetooth functionality, and with its higher performance, a wider range of applications.
- 100% compatible with Arudino IDE, Lua and Micropython, it shows robustness, versatility, and reliability in a wide variety of applications and power scenarios.
- All I/O pins have interrupt, PWM, I2C and one-wire capability, except the pin DO.
- Designed with ultra-low power technology, it offers the full range of performance and features of the ESP32 chip. The pin arrangement provides compatibility with the modules developed for the D1 Mini ESP8266 while also offering fast WLAN, enhanced GPIO, Bluetooth functionality, and with its higher performance, a wider range of applications.
- Device identity creation, credential provisioning, authentication, authorization, and revocation.
- TLS configuration, certificate issuance and rotation, secure key handling, and audit records.
- Firmware and configuration rollout, staged deployment, health checks, rollback, and recovery of devices that miss an update.
- Device state, telemetry retention, processing rules, and the recovery path when a device is offline or its credentials are compromised.
Plan credential and firmware changes so that an interruption or failed rollout does not strand a device cohort without a supported recovery route. Google Cloud’s backend security guidance, last reviewed 2024-12-06 UTC, covers security practices for IoT backends: Best practices for running an IoT backend securely. Treat it as guidance to validate against current product documentation and your threat model.
Instrument customer outcomes and manage the budget
Instrument the defined SLO at the transaction boundary, not only at infrastructure components. Publish separate signals for successful operations, latency distributions, capacity and throttling, throughput, data freshness, and correctness. Segment them by region, protocol, operation, and device cohort so a healthy aggregate does not hide a localized outage or a failing firmware rollout.
Set alert thresholds and deployment rollback criteria from the SLO and the remaining budget. Track both symptoms customers experience and leading signals such as queue growth, saturation, elevated authentication failures, stale processing, or rising retry volume. A dashboard that shows component health without confirming delivery and data quality cannot establish that the IoT service is meeting its objective.
Recommended Free Tools
Reliability has a cost in engineering time, infrastructure, and operational complexity. Google SRE frames the task as risk management: “In SRE, we manage service reliability largely by managing risk.” Its guidance on risk and reliability engineering argues for balancing reliability with innovation and cost rather than maximizing uptime without regard to trade-offs. Use the SLO to prioritize work where failures have material user impact.
Validate recovery before claiming five nines
Exercise representative failures and document the observed customer impact, recovery time, data loss, and remaining gaps. Include tests for the fault domains your design claims to tolerate, such as a zone or regional routing event, a credential-service disruption, a storage failover, processing backlog and replay, or the recovery of devices after a network outage.
Use controlled tests and rehearsed operational procedures to verify that alerts reach the right people, failover behaves as expected, and recovery does not corrupt, lose, or indefinitely delay telemetry. Repeat exercises after meaningful architectural changes. A successful component failover is not proof of the end-to-end SLO; evaluate the same customer-visible transaction and window defined at the outset.
Turn the target into an operating design
- Define the promise: choose the customer-visible device or operator transaction and make success, latency, data quality, eligibility, and window explicit.
- Set the budget: translate the objective into allowed time or failed requests for that exact window, and decide how degradation and planned work count.
- Map dependencies: trace the transaction through device connectivity, identity, ingestion, processing, storage, APIs, and external services.
- Choose the fault scope: select the zone or region failures the service must withstand, then design routing, state, capacity, and recovery for those cases.
- Match protocols and operations to the fleet: validate protocol features, offline behavior, security lifecycle, rollout, and rollback against real device needs.
- Measure and exercise: monitor user outcomes, alert against the SLO, rehearse failures, and use observed results to revise the design and budget.
A 99.999% target is meaningful only when the complete service path is measured against an explicit customer promise and the organization can demonstrate that it recovers within the defined budget. A multi-region diagram is a design option; operational evidence is what supports the reliability claim.
Quick Recap
Product prices and availability are accurate as of the date/time indicated and are subject to change. Any price and availability information displayed on Amazon at the time of purchase will apply.

