Freedom251 › Text-to-speech tools
VALL-E X
Facts from VALL-E X's own pages
- Accent control
- The README describes controlling accents, including speaking Chinese with an English accent or vice versa. · github.com, 12 Oct 2026
- Audio environment
- The model attempts to preserve the prompt’s acoustic environment, including ambient noise and music. · github.com, 12 Oct 2026
- Commercial use
- Yes · github.com, 20 Sept 2026
- Cross-language speech
- It can synthesize speech in another language using a monolingual speaker prompt; the reproduced model does not include the speech-to-speech translation module, but the demo page says this can be achieved with Google Translate API. · plachtaa.github.io, 13 Oct 2026
- Cross-lingual synthesis
- It can generate personalized speech in another supported language from a monolingual speaker prompt. · github.com, 12 Oct 2026
- Emotion and environment
- The model can preserve emotion and acoustic characteristics from a supplied audio prompt. · github.com, 13 Oct 2026
- Emotion control
- Speech synthesis can retain the emotion of the acoustic prompt. · github.com, 12 Oct 2026
- Export formats
- WAV · github.com, 20 Sept 2026
- Generation limit
- The README recommends keeping the combined audio prompt and generated audio under 22 seconds for acceptable performance. · github.com, 13 Oct 2026
- Hardware
- The README says 6 GB of GPU VRAM is enough to run VALL-E X without offloading. · github.com, 13 Oct 2026
- Intended use
- The README says the trained model is released publicly for research or application usage. · github.com, 13 Oct 2026
- Interfaces and demos
- The project provides a Python graphical interface and links to online demos on Hugging Face and Google Colab. · github.com, 12 Oct 2026
- Languages
- 3 · github.com, 20 Sept 2026
- Languages
- The implementation supports English, Chinese, and Japanese speech synthesis. · github.com, 13 Oct 2026
- Length limitation
- For acceptable performance, the combined prompt and generated audio should be less than 22 seconds. · github.com, 12 Oct 2026
- License
- The repository uses the MIT License, which permits use, copying, modification, distribution, sublicensing, and sale subject to its terms. · github.com, 13 Oct 2026
- License and maintenance
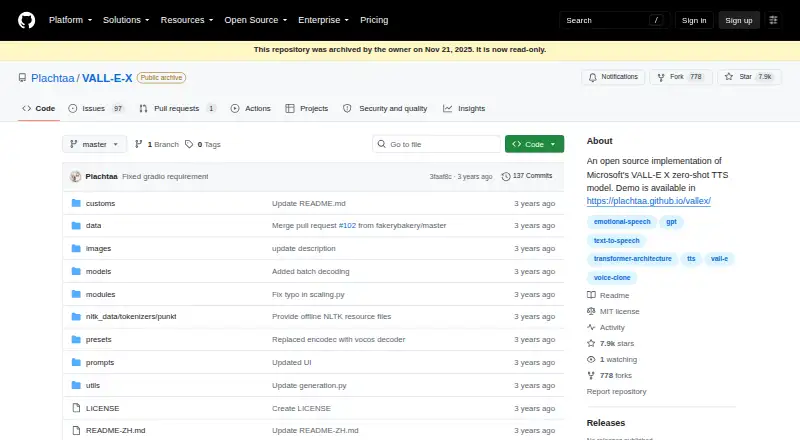
- The project is MIT-licensed, and GitHub marks the repository as archived and read-only since November 21, 2025. · github.com, 12 Oct 2026
- Model limitation
- The reproduced model does not include the speech-to-speech translation module; its demo page says that functionality can be achieved using Google Translate API. · plachtaa.github.io, 12 Oct 2026
- Platforms
- web,self_hosted · github.com, 20 Sept 2026
- Product
- VALL-E X is an open-source implementation of Microsoft’s zero-shot text-to-speech model, released for research or application use. · github.com, 12 Oct 2026
- Project status
- GitHub marks the repository as archived and read-only since November 21, 2025. · github.com, 13 Oct 2026
- Purpose
- VALL-E X is an open source implementation of a multilingual, zero-shot text-to-speech model. · github.com, 13 Oct 2026
- Requirements
- The installation instructions specify Python 3.10, PyTorch 2.0 or later, and CUDA 11.7–12.0; the project says it also runs on CPU. · github.com, 13 Oct 2026
- Runtime requirements
- Installation instructions specify Python 3.10, PyTorch 2.0+, and CUDA 11.7–12.0; the README says it also works on CPU. · github.com, 12 Oct 2026
Where VALL-E X stands on Freedom251
- Text-to-speech tools#146 of 232
- Text-to-Speech Software#169 of 223