Freedom251 › Text Analytics Software
TextDescriptives
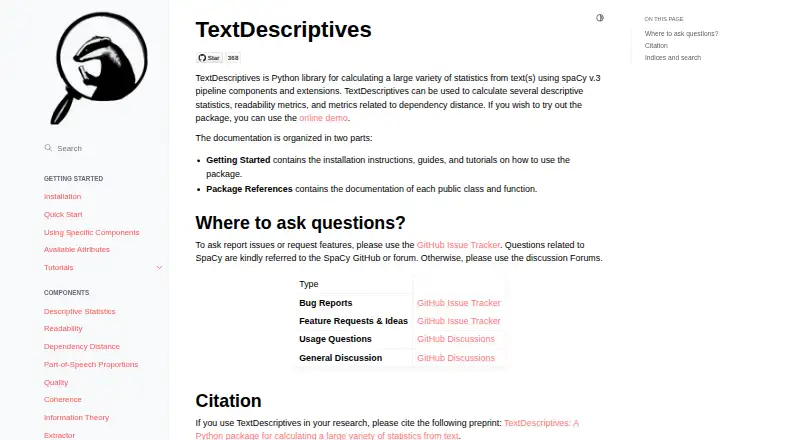
What TextDescriptives is
TextDescriptives is a free Python library for measuring text through spaCy v.3 pipeline components and extensions. It calculates descriptive statistics, readability scores, dependency distance, part-of-speech proportions, coherence, text quality, and information-theory metrics. Its statistics include token and character totals, unique-token proportions, sentence and token lengths, and syllable counts. Readability options include Flesch, SMOG, Gunning-Fog, Automated Readability Index, Coleman-Liau, LIX, and RIX. Quality checks cover stop-word and out-of-vocabulary ratios, repeated text, bullet points, and ellipses, with configurable thresholds. You can analyze raw text or spaCy documents, then receive results as a Pandas DataFrame or a list of dictionaries. The documentation describes use in spaCy pipelines and a scikit-learn pipeline featurizer, and links to an online demo. Installation is through `pip install textdescriptives`. The project is licensed under Apache-2.0 and is listed for API and Linux use, with on-premise deployment. Some readability calculations that rely on hyphenation can return NaN for languages Pyphen does not support.
Who it suits
TextDescriptives suits Python users who need to calculate text statistics, readability, quality, or linguistic metrics. It is also relevant to people building spaCy workflows or scikit-learn pipeline features.
What it does well
- Covers descriptive, readability, coherence, quality, and information-theory metrics.
- Accepts raw text or spaCy documents.
- Returns results as a DataFrame or list of dictionaries.
- Integrates with spaCy and scikit-learn pipelines.
- Free to use under an Apache-2.0 license.
What to know first
- Some hyphenation-dependent scores may return NaN for unsupported Pyphen languages.
- Usage is centered on Python and spaCy v.3.
Limits
Hyphenation-dependent readability metrics may return NaN for languages unsupported by Pyphen.
Getting started
- Open the TextDescriptives documentation website.
- Install the package with `pip install textdescriptives`.
- Use it with raw text or spaCy documents.
- Try the online demo linked from the documentation.
Verdict
Choose TextDescriptives if you need a free Python library that brings a broad range of text measurements into spaCy or scikit-learn workflows. Look elsewhere if your required readability measures depend on hyphenation for a language Pyphen does not support.
Questions
Is TextDescriptives free?
Yes. It is free and licensed under Apache-2.0.
What metrics can it calculate?
It covers descriptive statistics, readability, dependency distance, part-of-speech proportions, coherence, text quality, and information theory.
What input and output formats does it support?
It can process raw text or spaCy documents and return metrics in a Pandas DataFrame or a list of dictionaries.
What integrations are described?
The documentation shows integration with spaCy pipelines and a scikit-learn pipeline featurizer.
What platforms and deployment are listed?
It is listed for API and Linux use, with on-premise deployment.
Can all readability metrics work for every language?
Metrics requiring hyphenation may return NaN for languages unsupported by Pyphen.
Facts from TextDescriptives's own pages
- Demo
- The documentation links to an online demo for trying the package. · hlasse.github.io, 4 Oct 2026
- Install
- The documentation says to install the package with `pip install textdescriptives`. · hlasse.github.io, 4 Oct 2026
- Integrations
- The documentation shows integration with spaCy pipelines and a scikit-learn pipeline featurizer. · hlasse.github.io, 4 Oct 2026
- License
- The project’s GitHub page identifies its license as Apache-2.0. · github.com, 4 Oct 2026
- Metrics
- Its components cover descriptive statistics, readability, dependency distance, part-of-speech proportions, coherence, text quality, and information theory. · hlasse.github.io, 4 Oct 2026
- Notable limitation
- Readability metrics that require hyphenation may return NaN for languages unsupported by Pyphen. · hlasse.github.io, 4 Oct 2026
- Output
- The extractors can return metrics in a Pandas DataFrame or a list of dictionaries, and can process raw text or spaCy documents. · hlasse.github.io, 4 Oct 2026
- Purpose
- TextDescriptives is a Python library for calculating statistics and other metrics from text using spaCy v.3 pipeline components and extensions. · hlasse.github.io, 4 Oct 2026
- Quality filtering
- Quality metrics include stop-word and out-of-vocabulary ratios, text repetition, bullet points, ellipses, and configurable thresholds for checks. · hlasse.github.io, 4 Oct 2026
- Readability
- Readability measures include Flesch, SMOG, Gunning-Fog, Automated Readability Index, Coleman-Liau, LIX, and RIX. · hlasse.github.io, 4 Oct 2026
- Support
- The documentation directs bug reports and feature requests to GitHub Issues and usage questions to GitHub Discussions. · hlasse.github.io, 4 Oct 2026
- Text statistics
- Descriptive statistics include token and character counts, unique-token proportions, sentence lengths, syllable counts, and token lengths. · hlasse.github.io, 4 Oct 2026
Where TextDescriptives stands on Freedom251
- Text Analytics Software#11 of 37