Freedom251 › Text-to-speech tools
TensorFlowTTS
What TensorFlowTTS is
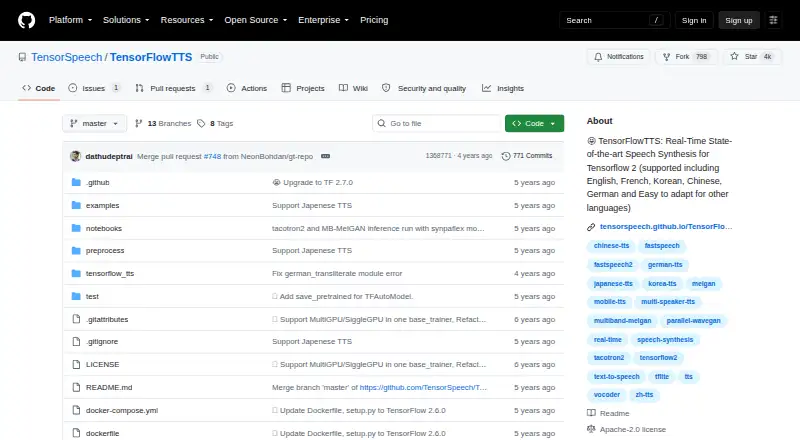
TensorFlowTTS is a free, open-source TensorFlow 2 project for real-time text-to-speech research, model training, and deployment. It provides Tacotron-2, MelGAN, Multiband-MelGAN, FastSpeech, FastSpeech 2, Parallel WaveGAN, and HiFi-GAN architectures. Listed language support covers Chinese, Korean, English, French, and German, with adaptation to other languages described. Training features include mixed precision, single- and multi-GPU operation, and gradient accumulation. For deployment, the project supports TensorFlow Lite conversion and C++ inference for mobile or embedded systems. Documentation lists an Android example and says FastSpeech 2 and Multiband MelGAN support iOS. Pretrained models can be loaded from Hugging Face Hub, and a Gradio demo is described on Hugging Face Spaces. Installation is documented through pip or the GitHub source repository. Preprocessing supports LJSpeech, KSS, Baker, LibriTTS, Thorsten, and Synpaflex. WAV is the listed export format.
Who it suits
TensorFlowTTS suits developers and researchers training, fine-tuning, or deploying speech-synthesis models. It supports self-hosted and mobile-oriented workflows across the listed platforms.
What it does well
- Open-source Apache-2.0 license
- Multiple TTS architectures
- Mixed-precision and multi-GPU training
- TensorFlow Lite and C++ inference
- Commercial use allowed
What to know first
- WAV is the listed export format
- Installation may require source setup
- Language list is limited to five named languages
Verdict
TensorFlowTTS provides a broad set of speech models and training tools under an open license. Its deployment paths cover mobile and embedded targets, while installation and model work require technical skills.
Facts from TensorFlowTTS's own pages
- Architectures
- Supported architectures include Tacotron-2, MelGAN, Multiband-MelGAN, FastSpeech, FastSpeech 2, Parallel WaveGAN, and HiFi-GAN. · github.com, 13 Oct 2026
- Commercial use
- Yes · github.com, 20 Sept 2026
- Data compatibility
- Its preprocessing is based on ESPnet, and the README says the resulting data can be combined with models from the ESPnet repository. · github.com, 13 Oct 2026
- Datasets
- The documented preprocessing currently supports LJSpeech, KSS, Baker, LibriTTS, Thorsten, and Synpaflex datasets. · github.com, 12 Oct 2026
- Deployment
- The project supports TFLite conversion, C++ inference, and deployment to mobile devices or embedded systems. · github.com, 13 Oct 2026
- Export formats
- WAV · github.com, 20 Sept 2026
- Installation
- The project documents installation with pip or from its GitHub source repository. · github.com, 12 Oct 2026
- Integrations
- The project documents integration with Hugging Face Spaces and Gradio, and hosting pretrained models on the Hugging Face Hub. · github.com, 13 Oct 2026
- Languages
- The README lists Chinese, Korean, English, French, and German support, and says the framework can be adapted for other languages. · github.com, 13 Oct 2026
- License
- The repository states that its models are licensed under Apache 2.0. · github.com, 13 Oct 2026
- Mobile examples
- The README includes an Android example and reports iOS support for FastSpeech 2 and MB MelGAN. · github.com, 13 Oct 2026
- Model reuse
- Pretrained models can be loaded from Hugging Face Hub using the project’s inference API. · github.com, 12 Oct 2026
- Models
- It provides Tacotron-2, MelGAN, Multiband-MelGAN, FastSpeech, FastSpeech 2, Parallel WaveGAN, and HiFi-GAN architectures. · github.com, 12 Oct 2026
- Platforms
- Linux,iOS,Android · github.com, 20 Sept 2026
- Purpose
- TensorFlowTTS provides real-time speech synthesis architectures built on TensorFlow 2. · github.com, 13 Oct 2026
- Requirements
- The repository says it was tested on Ubuntu 18.04 with Python 3.7 or later and TensorFlow versions 2.2 through 2.6. · github.com, 13 Oct 2026
- Support
- The README provides project contact email addresses and links to tutorials, notebooks, and Colab examples. · github.com, 13 Oct 2026
- Supported datasets
- The README lists ljspeech, kss, baker, libritts, thorsten, and synpaflex for preprocessing, with reformatting instructions for some datasets. · github.com, 13 Oct 2026
- Training
- Features include mixed-precision training and single- or multi-GPU training and gradient accumulation. · github.com, 13 Oct 2026
- Use case
- The project describes itself as suitable for speech synthesis research, training or fine-tuning TTS models, and deployment. · github.com, 12 Oct 2026
Where TensorFlowTTS stands on Freedom251
- Text-to-speech tools#117 of 232
- Text-to-Speech Software#130 of 223