Freedom251 › AI Sound Effect Generators
Sony Woosh
What Sony Woosh is
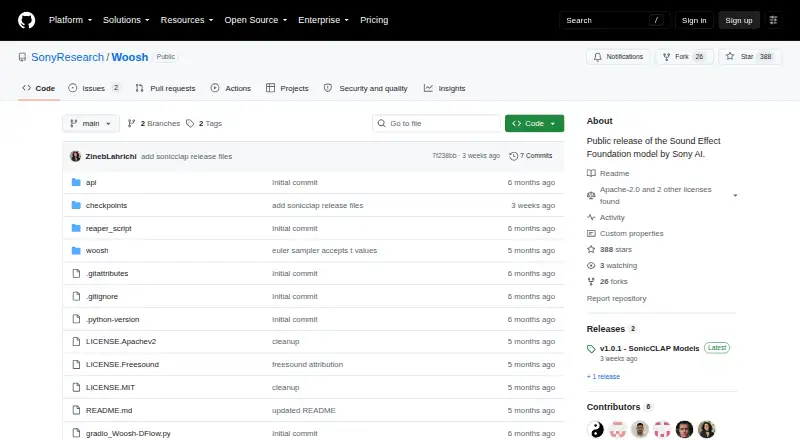
Sony Woosh is Sony AI’s publicly released sound-effects foundation model, providing inference code and open model weights trained on public datasets. Woosh-Flow and Woosh-DFlow generate audio without a prompt or from text. Woosh-VFlow generates audio from a video sequence and can accept optional text prompts. The release includes Woosh-AE for audio encoding and decoding, Woosh-CLAP for text-audio alignment, text-to-audio and video-to-audio generators, and distilled generator versions. Installation supports CPU or CUDA, with inference test scripts for each model. Local Gradio demos for Woosh-Flow and Woosh-DFlow run in a browser on the same machine. A self-run inference API server is provided, currently for Woosh-DFlow only. GitHub releases provide pretrained weights and sample media; version 1.0.1 also includes SonicCLAP-AR for audio-text retrieval and SonicCLAP-MOS for alignment with human perceptual judgments. Most code is MIT-licensed, selected video-model code is Apache 2.0, and model weights are CC-BY-NC.
Who it suits
Woosh suits developers and researchers working on sound-effect generation, audio research, or model baselines. Its CPU/CUDA setup, local demos, and inference API support different workflows.
What it does well
- Generates sound effects from text or video
- Includes open weights and inference code
- Supports CPU and CUDA installation
- Offers local browser-based Gradio demos
- Provides a self-run inference API
What to know first
- API server currently supports Woosh-DFlow only
- Model weights use a CC-BY-NC license
- Commercial use is unclear
Verdict
Sony Woosh offers several sound-effect generation models with local demos, scripts, and open weights. The limited API model support and model-weight license should be reviewed before adoption.
Facts from Sony Woosh's own pages
- Additional models
- Release v1.0.1 provides SonicCLAP-AR for audio-text retrieval and SonicCLAP-MOS for alignment with human perceptual judgments. · github.com, 5 Oct 2026
- API
- A self-run API server is provided for inference, but currently supports Woosh-DFlow only. · github.com, 5 Oct 2026
- Audience
- The repository describes inference scripts, local demos, and an API server for running sound effect generation models. · github.com, 5 Oct 2026
- Audio models
- Woosh-AE provides audio encoding and decoding, while Woosh-CLAP provides text-audio alignment for diffusion conditioning. · github.com, 5 Oct 2026
- Compute options
- Installation instructions offer either CPU or CUDA support. · github.com, 5 Oct 2026
- Downloads
- Pretrained model weights and sample media are available through GitHub releases. · github.com, 5 Oct 2026
- Inference options
- The repository provides installation options with CPU or CUDA support and inference test scripts for each model. · github.com, 5 Oct 2026
- Licensing
- Most repository code is MIT-licensed, code for Woosh-VFlow and Woosh-DVFlow is Apache 2.0 licensed, and released model weights are CC-BY-NC licensed. · github.com, 5 Oct 2026
- Local demos
- The repository includes local Gradio demos for Woosh-Flow and Woosh-DFlow, accessed in a browser on the same machine. · github.com, 5 Oct 2026
- Model components
- The release includes an audio encoder/decoder, a text-audio alignment model, text-to-audio and video-to-audio generators, and distilled versions of the generators. · arxiv.org, 5 Oct 2026
- Model weights
- Open weights for models trained on public datasets are available from the repository’s releases. · github.com, 5 Oct 2026
- Open weights
- The repository provides inference code and open weights for models trained on public datasets. · github.com, 5 Oct 2026
- Organization
- The repository identifies Woosh as a public release of a sound effect foundation model by Sony AI. · github.com, 5 Oct 2026
- Purpose
- Woosh is Sony AI’s publicly released sound effects foundation model, with inference code and open model weights. · github.com, 5 Oct 2026
- Support
- The repository welcomes pull requests and asks contributors to open an issue before making major changes. · github.com, 5 Oct 2026
- Text-to-audio
- Woosh-Flow and Woosh-DFlow generate audio unconditionally or from a text prompt. · github.com, 5 Oct 2026
- Use case
- The models are optimized for sound effects and are presented as tools for audio research and building approaches or baselines. · arxiv.org, 5 Oct 2026
- Video-to-audio
- Woosh-VFlow generates audio from a video sequence and can take optional text prompts. · github.com, 5 Oct 2026
Where Sony Woosh stands on Freedom251
- AI Sound Effect Generators#24 of 29