Freedom251 › AI Voice Cloning Software
MetaVoice
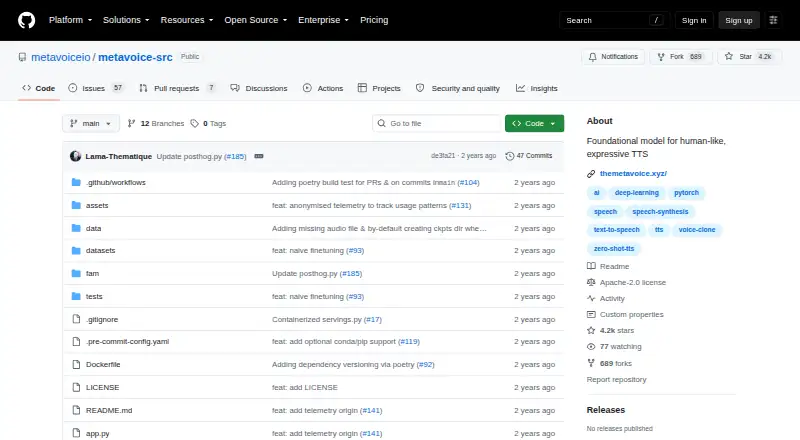
What MetaVoice is
MetaVoice is an open-source text-to-speech model built around MetaVoice-1B, which has 1.2 billion parameters and was trained on 100,000 hours of speech. It is designed to convey emotional rhythm and tone in English, synthesize long-form text, and create zero-shot copies of American or British voices from 30 seconds of reference audio. The repository provides a Gradio interface with preset voices and sample uploads, plus an inference server with API documentation. You can run the reference implementation locally or deploy it on AWS, GCP, or Azure; Hugging Face and a Google Colab demo are also linked. The model is free under the Apache 2.0 license, and commercial use is allowed. Running it requires a GPU with at least 12 GB of VRAM and Python 3.10 or later but below 3.12. The web interface limits text to 220 characters and truncates longer input. Voice samples must be clean, single-speaker recordings of 30 to 90 seconds, with a 50 MB upload ceiling. The repository also supports fine-tuning its first-stage language model.
Who it suits
MetaVoice suits developers and creators seeking an open-source speech model for English synthesis, voice cloning, or local and cloud deployment. Fine-tuning is available, while running the reference implementation requires the specified GPU and Python versions.
What it does well
- Apache 2.0 license permits commercial use.
- Clones American and British voices from 30 seconds.
- Includes a web interface and inference API server.
- Supports local use and AWS, GCP, or Azure deployment.
- Fine-tuning supports the first-stage language model.
What to know first
- Requires a GPU with at least 12 GB VRAM.
- Requires Python 3.10 or later but below 3.12.
- Web UI truncates text beyond 220 characters.
- Voice uploads are capped at 50 MB.
Limits
The included web interface accepts up to 220 characters and truncates longer input. Voice samples must be 30 to 90 seconds, clean and single-speaker, and uploads cannot exceed 50 MB.
Getting started
- Open the GitHub repository
- Install Python 3.10 or later but below 3.12
- Use a GPU with at least 12 GB of VRAM
- Run the reference implementation locally or deploy on AWS, GCP, or Azure
- Use the Gradio web UI, inference server API, Hugging Face, or Google Colab
Verdict
MetaVoice combines open-source licensing with voice cloning, fine-tuning, and several deployment options. Check the hardware requirements and web UI limits before choosing how to use it.
Questions
Is MetaVoice free?
The pricing model is free, with a free plan.
Is MetaVoice open source?
MetaVoice-1B and its code are described as open source, and the model uses the Apache 2.0 license.
Can it clone voices?
It supports zero-shot cloning of American and British voices from 30 seconds of reference audio.
What platforms are supported?
Platforms include API, Linux, self-hosted, and web. Deployment is described for AWS, GCP, and Azure, with local use through the reference implementation.
Does it provide an API?
Yes. The project includes an inference server with API documentation at its /docs route.
Can it be fine-tuned?
The repository supports fine-tuning its first-stage language model and describes success with as little as one minute of training audio for Indian speakers.
Facts from MetaVoice's own pages
- Access
- The README links to use through Hugging Face and a Google Colab demo. · github.com, 9 Oct 2026
- API and deployment
- The project provides an inference server with API documentation at its /docs route and says it can be deployed on AWS, GCP, or Azure. · github.com, 9 Oct 2026
- Deployment
- The README says it can be deployed on AWS, GCP, or Azure, or used locally with the reference implementation. · github.com, 9 Oct 2026
- Fine-tuning
- The repository supports fine-tuning its first-stage language model and says it has succeeded with as little as one minute of training audio for Indian speakers. · github.com, 9 Oct 2026
- Hardware requirement
- Installation requires a GPU with at least 12 GB of VRAM and Python version 3.10 or later but below 3.12. · github.com, 9 Oct 2026
- Interfaces
- The repository provides a web UI and an inference server with API definitions available at the server's /docs URL. · github.com, 9 Oct 2026
- License
- The model is released under the Apache 2.0 license. · github.com, 9 Oct 2026
- Local use
- The model can be downloaded and run locally through the reference implementation. · github.com, 9 Oct 2026
- Model scale
- The model has 1.2 billion parameters and was trained on 100,000 hours of speech. · github.com, 9 Oct 2026
- Open-source model
- MetaVoice-1B is a 1.2-billion-parameter text-to-speech model trained on 100,000 hours of speech and released under the Apache 2.0 license. · github.com, 9 Oct 2026
- Optional integration
- The fine-tuning workflow offers optional Weights & Biases logging. · github.com, 9 Oct 2026
- Organization
- GitHub identifies the MetaVoice organization as based in the United States; the opened maker pages do not state its headquarters city or founding year. · github.com, 9 Oct 2026
- Performance
- The README says that on Ampere, Ada-Lovelace, and Hopper GPUs, synthesis runs faster than real time after model compilation. · github.com, 9 Oct 2026
- Product
- MetaVoice-1B is an open-source foundational text-to-speech model. · github.com, 9 Oct 2026
- Product status
- The GitHub-linked metavoice.io site redirects to Familiar, which describes a duplex speech model for outbound sales calls and offers a 30-day pilot. · metavoice.io, 9 Oct 2026
- Security and privacy
- The repository describes the model and code as open source but does not state security certifications or data-handling commitments. · github.com, 9 Oct 2026
- Speech style
- The project lists emotional speech rhythm and tone in English as a design priority. · github.com, 9 Oct 2026
- Text length
- The README describes synthesis of arbitrary-length text. · github.com, 9 Oct 2026
- UI input limit
- The included web UI accepts up to 220 characters of text and truncates longer input. · github.com, 9 Oct 2026
- Voice cloning
- It supports zero-shot cloning of American and British voices from 30 seconds of reference audio. · github.com, 9 Oct 2026
- Voice generation
- The model targets emotional speech rhythm and tone in English, zero-shot cloning of American and British voices using 30 seconds of reference audio, and long-form synthesis. · github.com, 9 Oct 2026
- Voice upload limits
- The web UI asks for a clean, single-speaker sample of 30 to 90 seconds without background noise, and its code enforces a 50 MB upload-size ceiling. · github.com, 9 Oct 2026
- Web interface
- The repository includes a Gradio web UI with preset voices and an option to upload a target voice sample for cloning. · github.com, 9 Oct 2026
Where MetaVoice stands on Freedom251
- AI Voice Cloning Software#16 of 29